2. Stop writing prompts that assume the model "gets it." 4.6 prompt: "help me with my pitch deck"
(4.6 inferred you wanted structure + hooks + content tips) 4.7 prompt: "review the 10 slides below. flag weak hooks, missing stats, and confusing transitions. output as a
LLMS
-
Improving AI Prompt Precision for Better Model Performance
By
–
-
Adjusting Prompting Strategies for Opus 4.7 Behavior Changes
By
–
The shift is simple but devastating: Opus 4.6 inferred your intent and filled in the gaps.
Opus 4.7 does EXACTLY what you ask. Nothing more. Translation: the same prompt now produces narrower, terser, sometimes broken results. Here's how to fix it -
Prompt Engineering Adjustments for Claude 3.7 Opus
By
–
RIP your old Claude prompts Opus 4.7 dropped 3 weeks ago and it follows instructions LITERALLY now. It scores 87.6% on SWE-bench (vs 80.8% on 4.6) but every prompt tuned for 4.6 is silently failing. 7 fixes that stopped my outputs from getting worse:
-
Scaling Senior Engineer Productivity with Claude Code and Multi-Agent Workflows
By
–
Así escala de verdad un Senior Engineer con Claude Code.
— Nico (@nicos_ai) 9 mai 2026
La diferencia está en mover tu tiempo hacia lo que más importa:
→ mejores prompts, más planificación, más review, menos tecleo.
El workflow:
usa un plugin que divide cada tarea entre 5 agentes:
– uno hace brainstorming
-… pic.twitter.com/PkMxnKfmEJHere's how a Senior Engineer truly scales with Claude Code. The difference lies in shifting your time toward what matters most:
→ better prompts, more planning, more review, less typing. The workflow:
use a plugin that divides each task among 5 agents:
– one does brainstorming -
Gary Marcus on AGI and scaling limits
By
–
So many people misremember (or never read) what I said in in 2022 in “Deep learning is hitting a wall”, which was neither about revenue or AI’s potential upper limits. Rather, it was an argument that the pure of scaling LLMs would not get us to AGI, and that we would need to
-
Local LLM capabilities and AGI potential
By
–
Imagine seeing how capable Qwen 3.6 27B is when you give it web access and a proper harness and not yet getting that AGI will run locally Ngmi
-
Evolution of AI Models and Benchmark Shifts
By
–
models will undoubtedly get to that point, and the METR benchmarks will undoubtedly shift to a frame above their current one—of which there are many
-
Early Look at Imagine Agent Mode for Image and Video Generation on Grok App
By
–
Early look at Imagine Agent Mode on Grok app for iOS!
— 🚨 AI News | TestingCatalog (@testingcatalog) 9 mai 2026
Users will be able to use Imagine Agent via a mobile optimised native UI to generate images and videos that require more complex workflows.
SpaceXAI is getting quite ahead of everyone else on this front!
We just need… pic.twitter.com/5QxeCclHEoEarly look at Imagine Agent Mode on Grok app for iOS! Users will be able to use Imagine Agent via a mobile optimised native UI to generate images and videos that require more complex workflows. SpaceXAI is getting quite ahead of everyone else on this front! We just need
-

Continuous Latent Diffusion Language Model Advances
By
–
“Continuous Latent Diffusion Language Model” Most diffusion language models still use diffusion to recover token-like states, just in a different generation order. However, this paper uses diffusion in a different way. It learns a continuous latent prior for global semantics
-
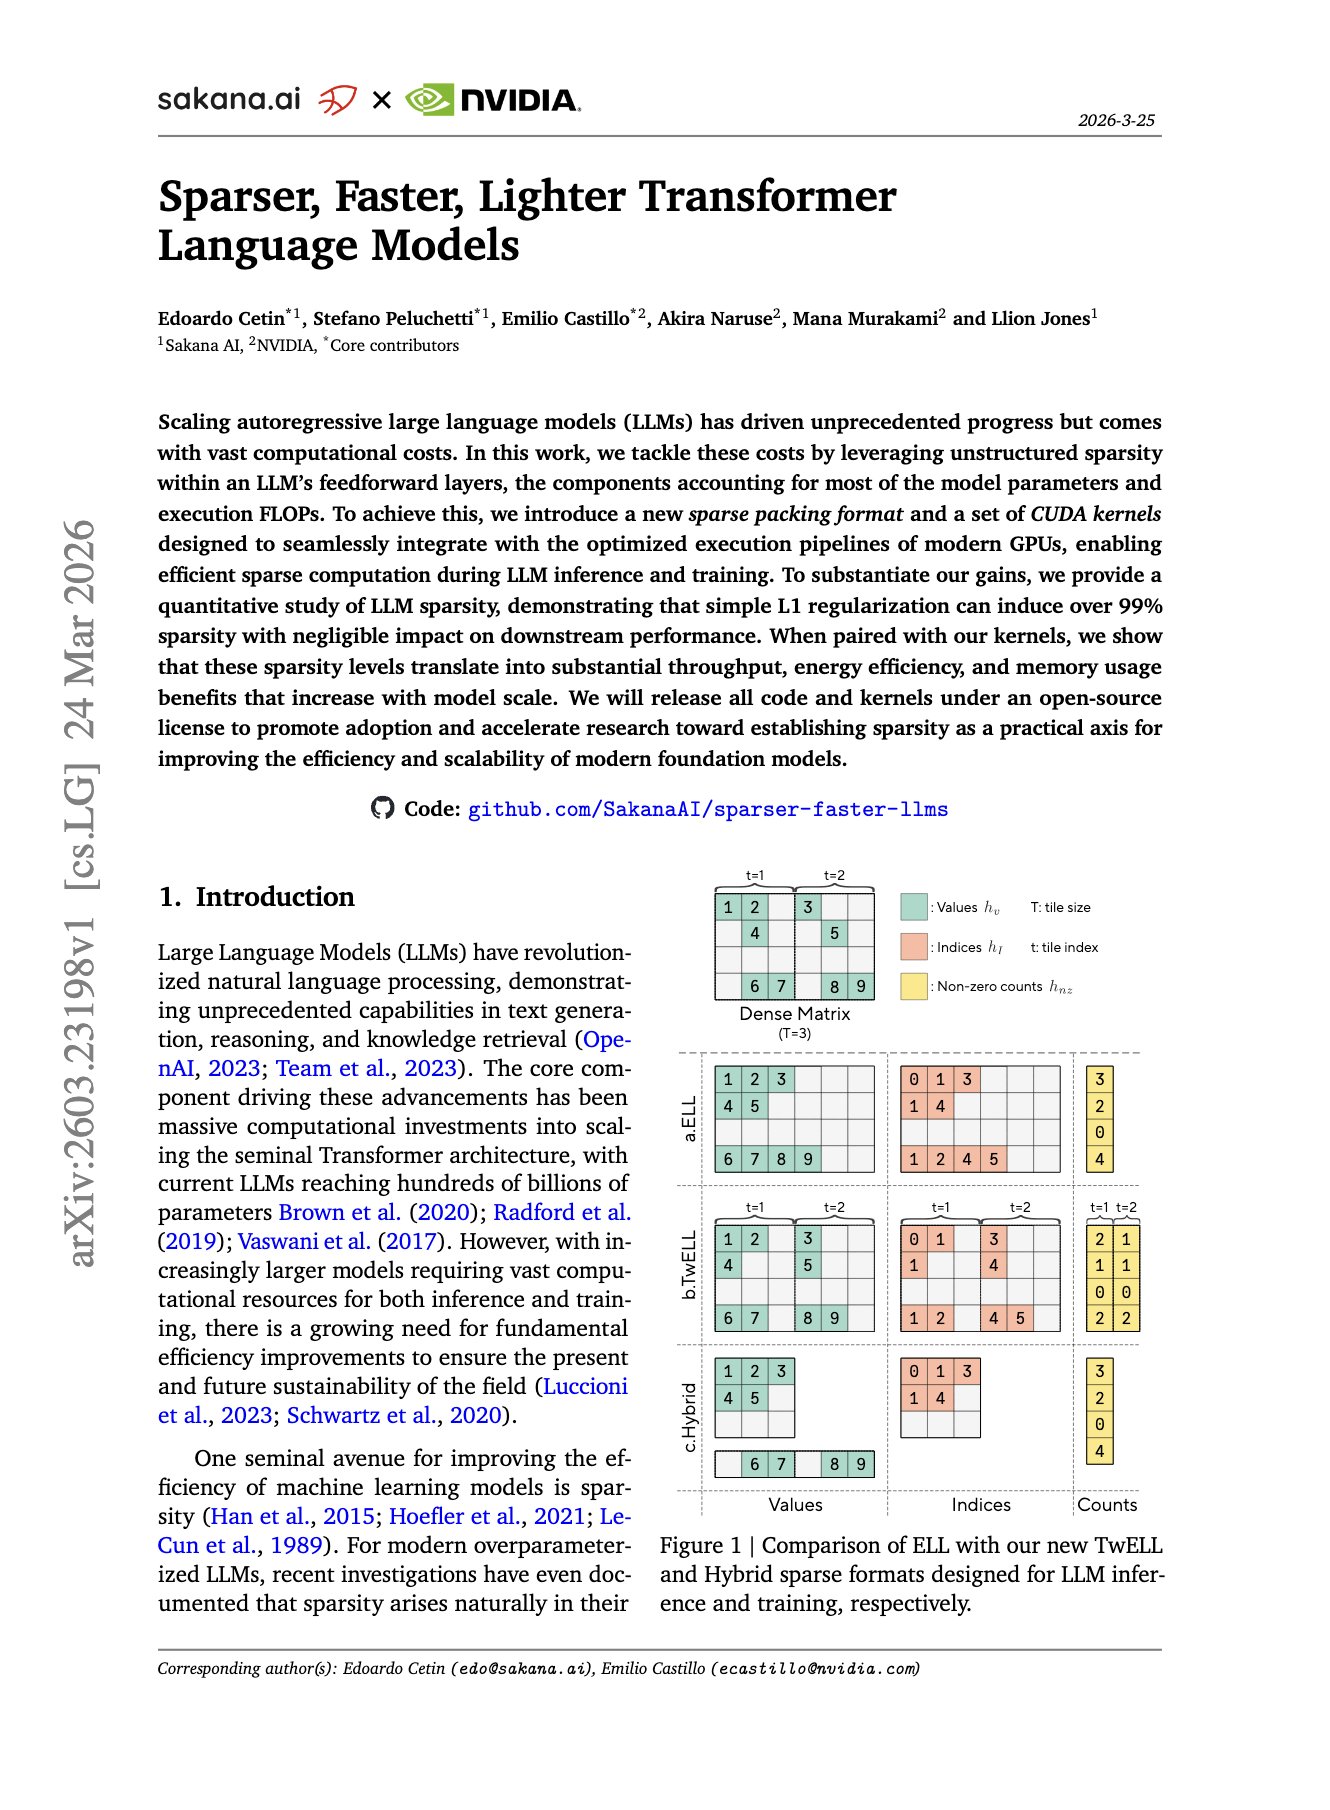
Sparser, Faster, Lighter Transformer Language Models
By
–
“Sparser, Faster, Lighter Transformer Language Models” LLMs are naturally sparse in their feedforward layers, but unstructured sparsity usually doesn’t get you real speed on GPUs, because the hardware stack is built for dense compute. The key idea of the paper is to redesign