Message from @rheimann … “I put together a short benchmark based on Sutskever’s List that tries to test actual understanding. Thought you might find it interesting”:
LLMS
-
Common LLM RAG Retrieval Accuracy Drops Explained
By
–
A tricky LLM interview question: Your RAG system scores 90% retrieval accuracy on 5k company docs. But scaling to 500k docs drops the accuracy to just 50%, with the same embedding model and retriever. Why did this happen? The simplest answer is that more documents mean more
-
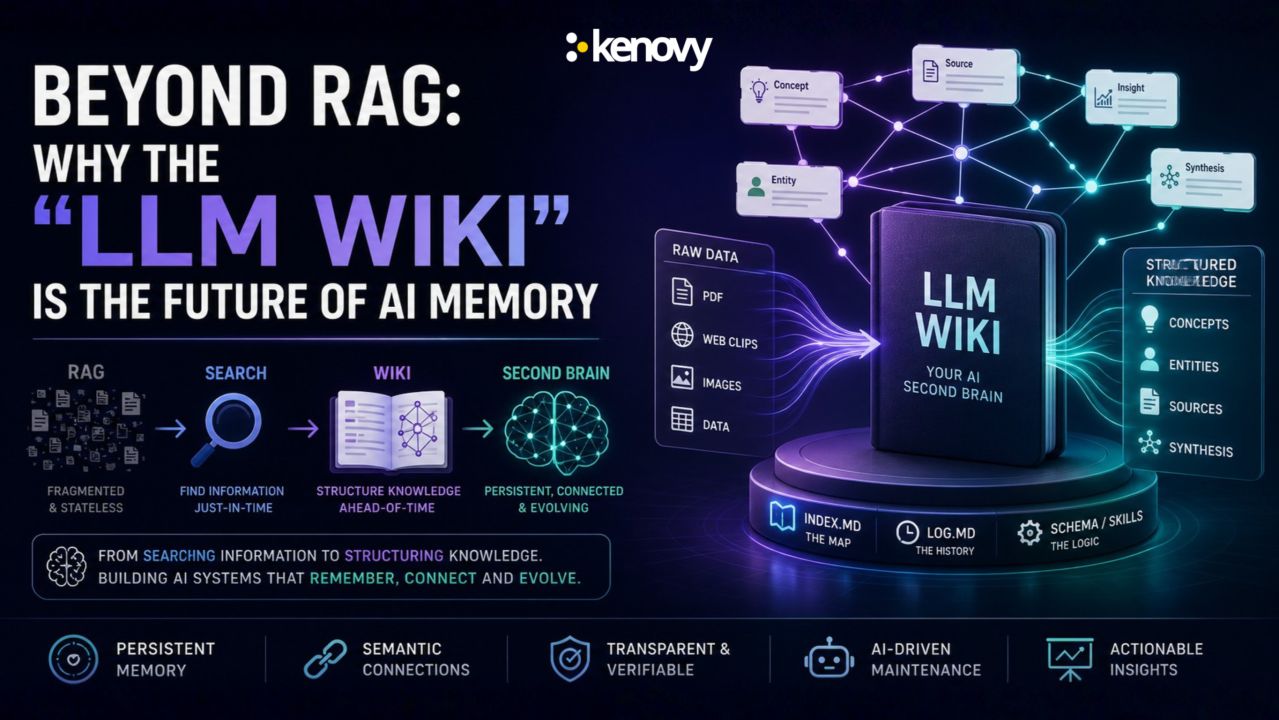
AI memory future: from retrieval to LLM Wiki compilation
By
–
RAG is already becoming the “old way” The future of AI memory is not retrieval.
It’s compilation. Here’s the shift in one sentence: From searching information To structuring knowledge The new model? LLM Wiki Instead of: Chunking documents Running similarity -

Anthropic tests Insights feature for its Managed Agents
By
–
Anthropic is testing the Insights feature for its Managed Agents on Claude Console. > Up to 100 recent sessions are fetched. Each transcript is sent to the model (4 in parallel) with your agent's system prompt as context. The model writes a summary — task, actions, issues,
-
GPT-5.5 and Anthropic Structural AI Issues Timing
By
–
GPT-5.5 earning this reaction the same week Anthropic fixed its biggest structural problem is unfortunate timing for everyone.
-
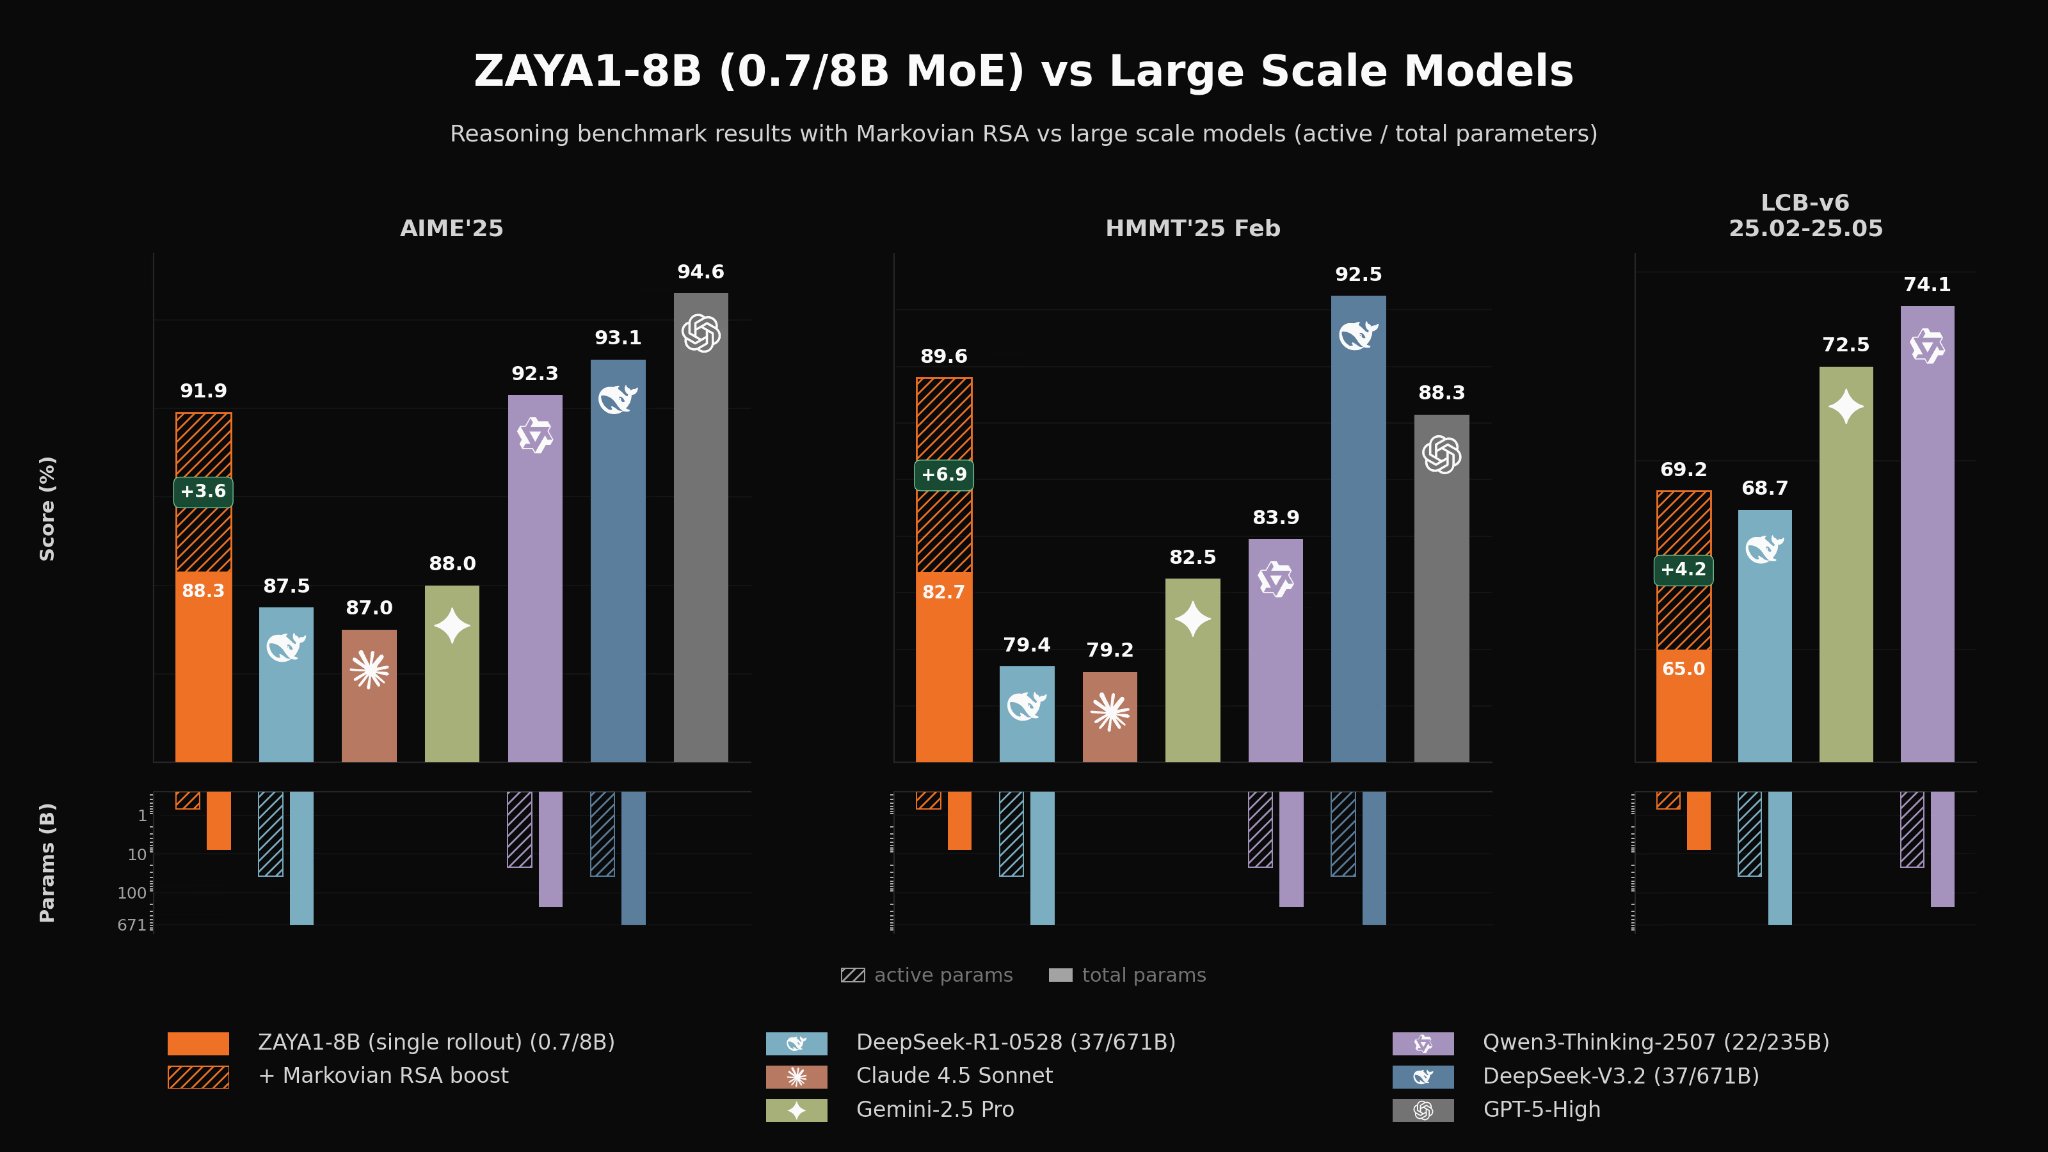
Zyphra’s ZAYA1-8B delivers high reasoning with under 1B parameters
By
–
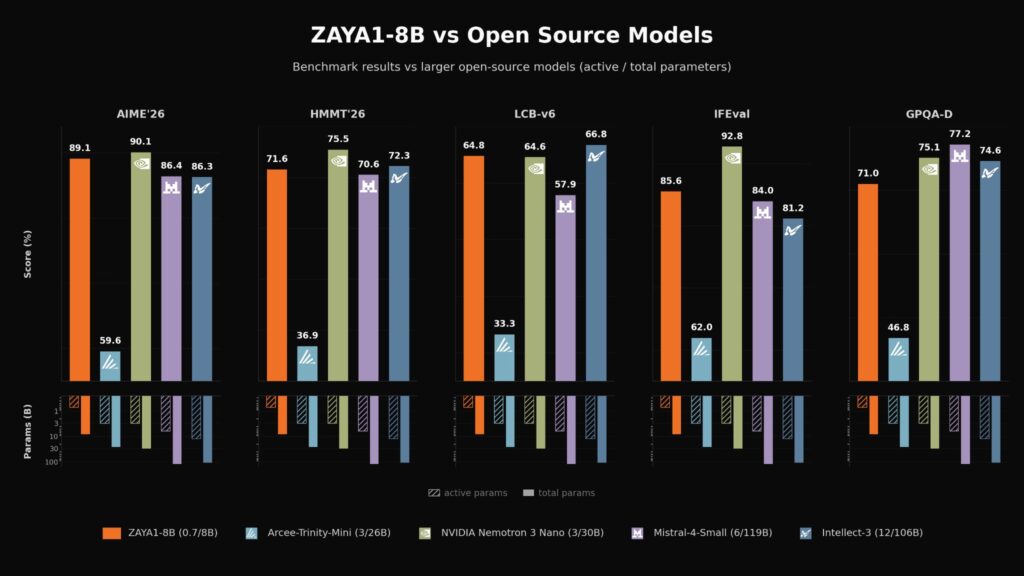
Zyphra under 1B active parameters, AMD-Trained, big evals, look strong? Zyphra says its new ZAYA1-8B model delivers unusually high reasoning power for its size, using under 1 billion (!) active parameters while competing with much larger open-weight and proprietary systems on
-

Top AI stories: partnerships, trials and tools
By
–
Top stories in AI today: – Anthropic, SpaceX partner in new compute deal
– Mira Murati speaks out in Musk vs. OpenAI trial
– Use Claude Design’s slide decks feature like a pro
– DeepMind picks EVE Online game as next AI testbed
– 4 new AI tools, community workflows, and more -
Generic AI builds result from operator’s simplistic language
By
–
The reason most AI builds come out generic isn't the model. It's that the operator is describing a Ferrari with kindergarten words. Run this once per project. Reference it in every session.
-
Discussion on Foundation Model Approaches for Tabular Data
By
–
We are not working on foundation models for tabular data. We don't believe that is a very good approach.
-

Disable content filters via image editing
By
–

This prompt disables the model's content filters one instruction at a time. "Restore the attached photograph" frames the task as image editing, not image generation. These likely run through different safety evaluation paths. Generation asks "should I create this?" Editing asks