The first Local AI Get-Together was a massive success This pic is missing quite a few people who left before we hit the 4-hour mark, but thank you to everyone who stopped by Local AI is very real, very alive, and apparently willing to talk GPUs, open weights, inference
LLMS
-
50 ML Projects for Understanding LLMs and Transformer Mechanisms
By
–
50 ML projects to understand LLMs — Investigate transformer mechanisms through data analysis, visualization, and experimentation: http://
amzn.to/4aPfP7q
—————
#AI #GenAI #MachineLearning #DataScientist #DataScience -
Practical Guide to Building LLM and RAG Apps with LangChain
By
–
"Generative AI and RAG for Beginners: A Practical Step-by-Step Guide to Building LLM and RAG Applications with LangChain and Python" Get your copy at http://
amzn.to/3MZZ9R5 Independently published: December 2025
Print length: 255 pages -
AI Agents and World Models: Research on Predictive Planning
By
–
Can AI agents see into the future before acting? A team from UIUC, THU, JHU, and Columbia tested exactly that. They gave agents generative world models—external simulators that could predict outcomes before taking action. The result? Most agents refuse to simulate (under 1%
-
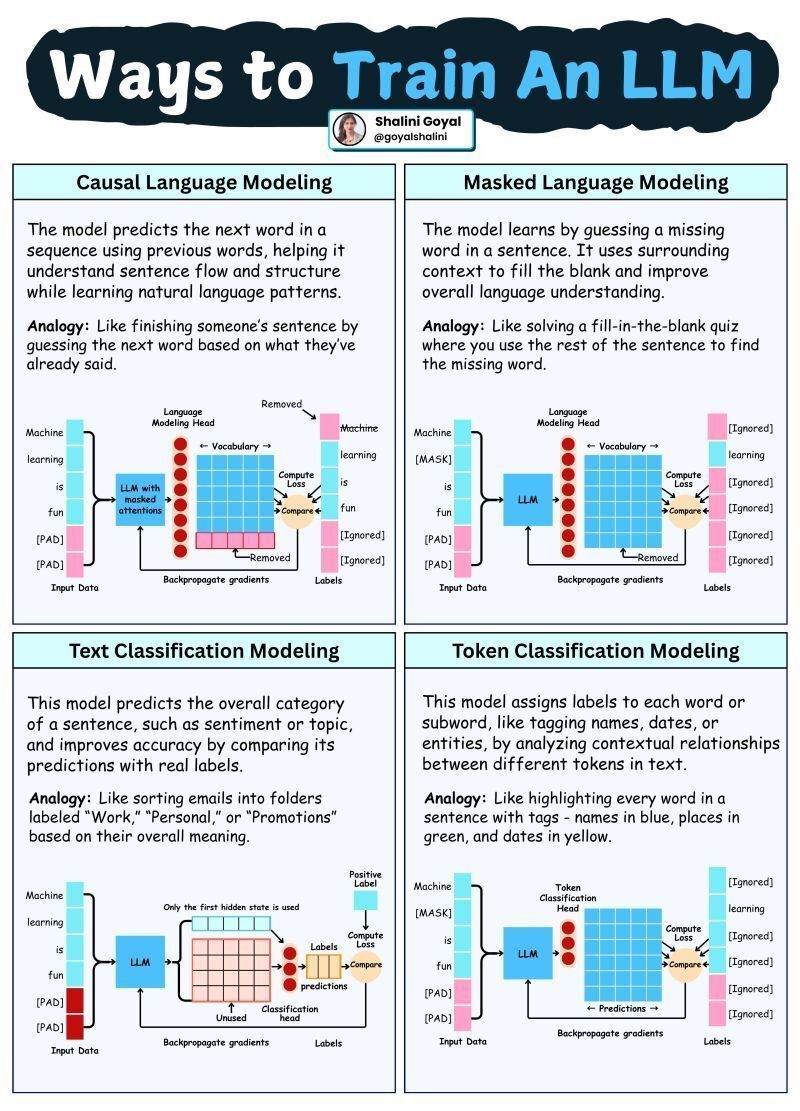
Ways to Train an LLM
By
–
Ways to Train an #LLM
by @goyalshaliniuk #GenAI #ArtificialIntelligence #MachineLearning #ML -
Popular AI writings from 2022-2023 still influence current models
By
–
I suspect there was a moment, probably 2022-2023, where anything you wrote publicly about AI that was popular is likely to still have influence over current models. Since then, the open internet has become less key to training but the models remain very 2022-brained in many ways
-
Transitioning from prompt engineering to specification writing for LLMs
By
–
Opus 4.6 was a helpful assistant.
Opus 4.7 is a precise operator. Stop writing prompts. Start writing specs. The model is stronger. Your prompts just need to catch up. -
Benchmarking Anthropic model performance and effort levels
By
–
Bonus: raise your effort level. Anthropic's official guidance:
→ xhigh for coding and agentic work
→ minimum high for intelligence-sensitive tasks Hex's CTO benchmarked it: low-effort 4.7 ≈ medium-effort 4.6. If your output feels worse than 4.6, you're probably running 4.7 -
Implementing Pause-and-Reflect Strategy in AI Agent Prompts
By
–
6. Add pause-and-reflect to agentic prompts. After each tool call, instruct: "reflect in tags. did this result answer what I needed? what's the next step?" This stops "optimistic chaining" where the model proceeds on results it never verified. (This is how the
-
Mitigating AI Hallucinations Through Prompt Engineering Strategies
By
–
7. Never trust tone as a reliability signal. Opus 4.7 is unusually confident when it's wrong. It told one user "strawberry" has two Ps. Build verification INTO your prompts: → "cite the source for every claim"
→ "flag uncertainty in tags"
→ "list 3 ways this