1/ Beginnings Flowise began with a simple vision – to help people build LLM applications visually using frameworks like @langchain and @llama_index
. We launched publicly in April 2023, and it immediately resonated with the developer community.
LLMS
-
Flowise: Building LLM Applications Visually with No-Code
By
–
-
Agentic Orchestration: Developer Need for Better Control Systems
By
–
3/ Shift From simple RAG and LLM workflows, we saw the shift to agentic orchestration – combination of predefined workflows and autonomous agents. It is clear to us developers need a better way to build agentic systems with more controllability and customization.
-
GPT-4.1 outperforms GPT-5 on code completion speed
By
–
One simple thing to try – use GPT-4.1 as a basic code completion model; you'll see it's really fast and accurate. Try to get any size GPT-5 with any amount of reasoning to match it. In my testing, GPT-5 was ~5x slower at the point it matched performance.
-
GPT-4.1 and Sonnet 4 Adoption for Development Work
By
–
Thanks Ted! Tbh we've got back to using GPT-4.1 for our coding quick fixes, and Sonnet 4 / Opus 4.1 for our main work. So we won't have too much feedback until GPT-5 has improved enough for us to give it another try. Definitely barracking for you guys to succeed!
-
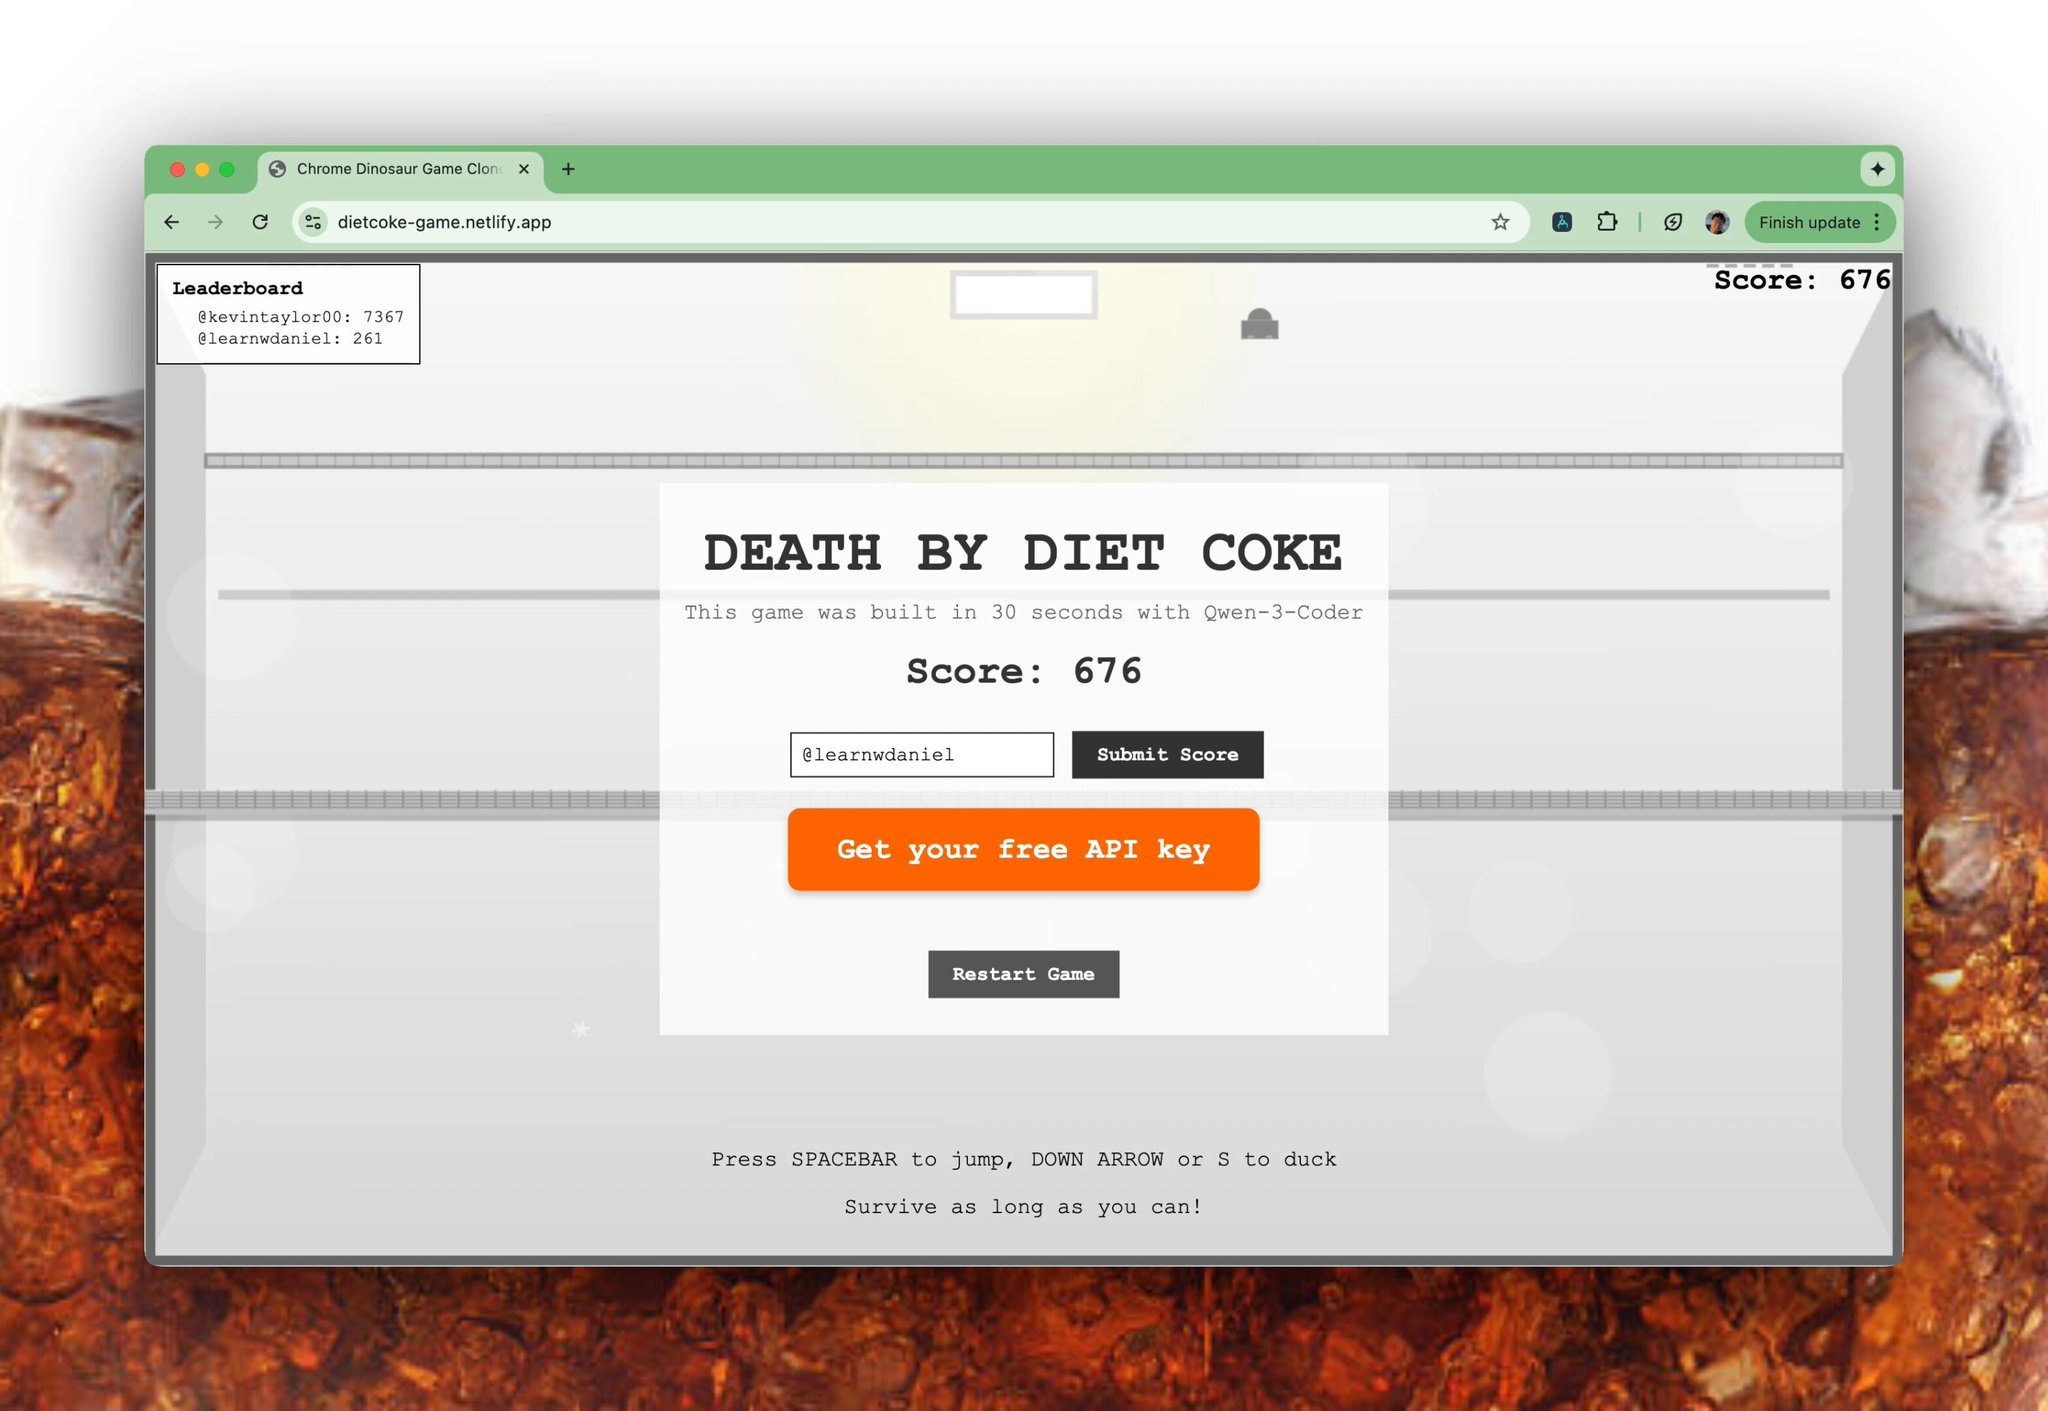
Cerebras Code Pro Launches with Higher Rate Limits for Developers
By
–
We built Death by Diet Coke in less than 30 seconds using Cerebras Code Pro, where you get higher rate limits and more power for Qwen3-Coder.
— Cerebras (@cerebras) 14 août 2025
We are opening the same number of Cerebras Code Pro/Max plans as diet coke cans in the office.
First come, first serve.… https://t.co/CNBcL0JtRR pic.twitter.com/15QdVcprycWe built Death by Diet Coke in less than 30 seconds using Cerebras Code Pro, where you get higher rate limits and more power for Qwen3-Coder. We are opening the same number of Cerebras Code Pro/Max plans as diet coke cans in the office. First come, first serve.
-
LM Studio and Ollama lack tool support capabilities
By
–
Neither the LM Studio nor the Ollama builds support tools, so I've not tried to get that to work
-

Google releases Gemma 3 with 270 million parameters
By
–
270 million (not billion) parameters! https://
huggingface.co/google/gemma-3
-270m
… -
GPT-5 GB200 FP4 Precision and Token Speed Analysis
By
–
So GPT-5 is running on GB200, to take full advantage of it, it could be in FP4. So I wonder if this change is hiding the size of the model somewhat. If it was FP8 and on H100, it would be now running at something like 10 tokens per second rather than current 50 tps.
-

Google Releases Gemma3 270M Tiny LLM on KerasHub
By
–
Google just dropped a new tiny LLM with outstanding performance — Gemma3 270M. Now available on KerasHub. Try the new presets `gemma3_270m` and `gemma3_instruct_270m`!
-
OpenAI’s GPT-5-Pro: Cost Optimization Over Capability Push
By
–
Given that we saw OpenAI test better checkpoints on the arena, it does also seem like they have also optimised for cost / mass appeal rather than pushed the capabilities as far as they could. We also don't have almost any benchmarks for GPT-5-Pro, which is genuinely superb and