
It looks like GPT-Alpha will be a significantly improved version of ChatGPT Agent. Initial tests are extremely positive. If this comes true, will 2025 really be the year of agents? Was Sama right? It seems increasingly likely that we will get really useful agents in the second
LLMS
-
AWS passive income strategy hosting open source LLMs
By
–
He can sit back while startups develop and host the best open source LLMs on AWS. Solid passive income strategy.
-
Learning Effectively with Top Tier Large Language Models
By
–
If you genuinely want to learn new things the amount you can learn from working thoughtfully with a top tier LLM is enormous
-

Microsoft Expands Copilot with Anthropic Claude Models
By
–
Big #AI move: @Microsoft expands @Copilot with @AnthropicAI ’s @claudeai models—alongside @OpenAI -starting in Researcher & Copilot Studio, with more to come.
Multi-model AI, tuned for work, tailored for every business. -

Scaling Language Models with Infinite Compute via Ensemble Distillation
By
–
As data and compute scales differently, what do we do when we have infinite compute? To answer this, this paper shows you can still scale LMs by cranking up regularization, training many small clones on the same corpus, then ensemble → distill, netting 5x data-efficiency
-
LangChain Rewrites DeepAgents Package for v1 Release
By
–
We rewrote our deepagents package on top of the upcoming LangChain v1 release! Deepagents excel at agentic tasks by leveraging their planning, filesystem, and sub-task capabilities. We built these features with LangChain middleware (new in LangChain 1.0!), and as a result,
-
A2D-VL Diffusion Model Outperforms VLMs with Efficient Training
By
–
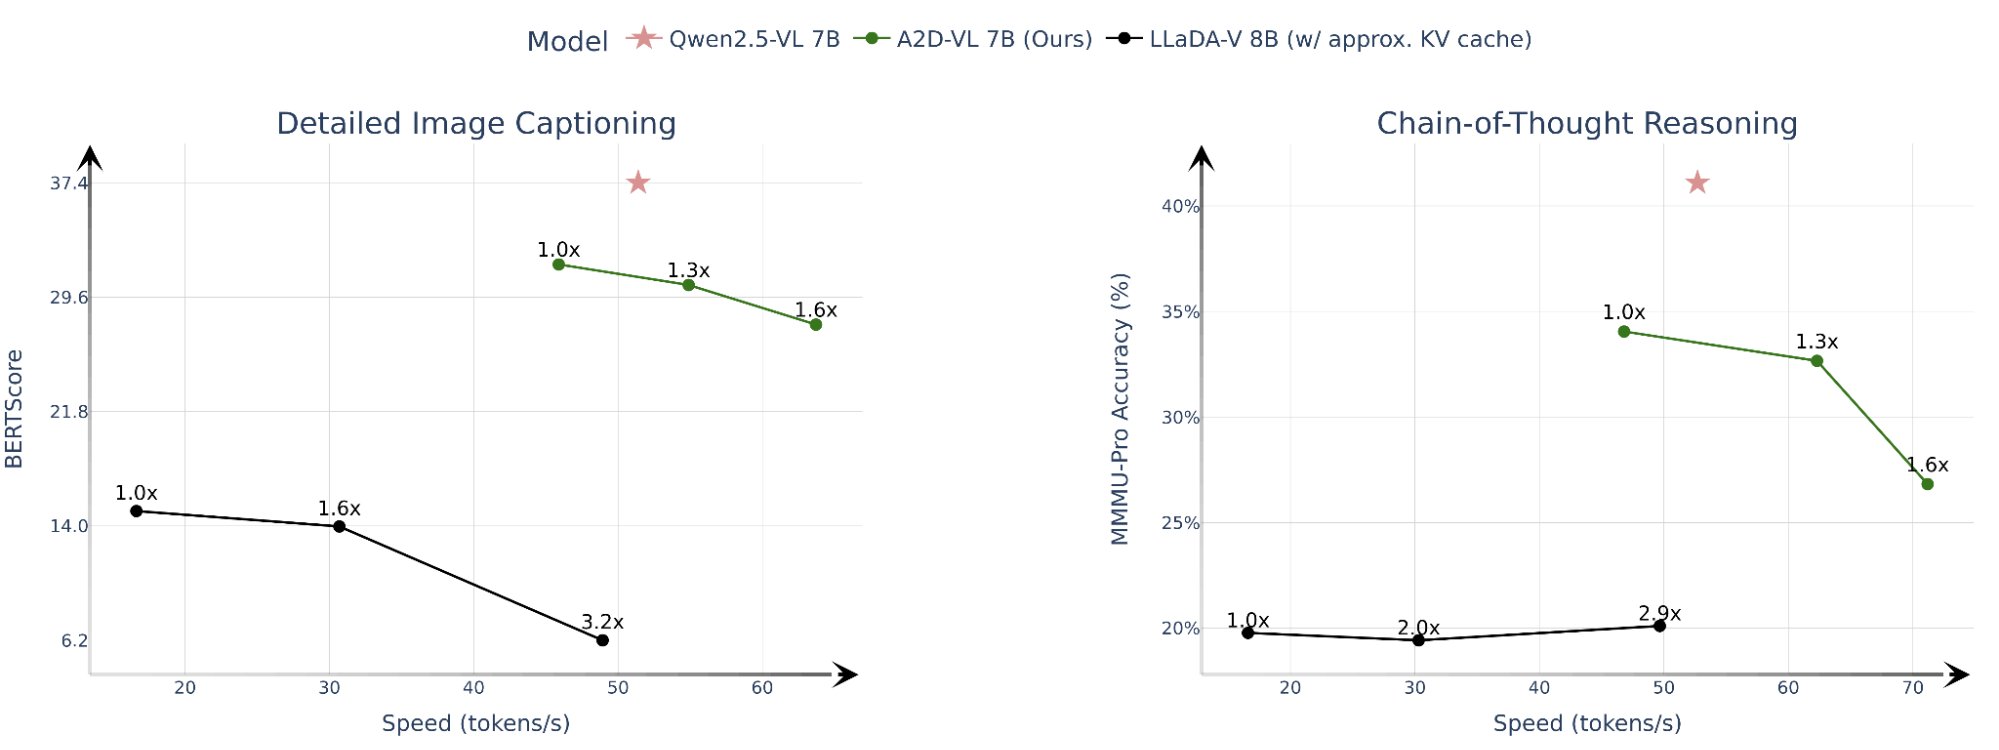
A2D-VL outperforms prior diffusion VLMs in visual question-answering while requiring significantly less training compute. Our novel adaptation techniques are critical for retaining model capabilities, finally enabling the conversion of state-of-the-art autoregressive VLMs to
-
VLMs Sequential Generation Limits Parallelization Efficiency
By
–
Standard Vision-language models (VLMs) reason about images and videos through language, powering a wide variety of applications from image captioning to visual question answering.
— Runway (@runwayml) 24 septembre 2025
Autoregressive VLMs generate tokens sequentially, which prevents parallelization and limits… pic.twitter.com/54ahfojDZuStandard Vision-language models (VLMs) reason about images and videos through language, powering a wide variety of applications from image captioning to visual question answering. Autoregressive VLMs generate tokens sequentially, which prevents parallelization and limits
-
A2D-VL 7B: Diffusion-Based Parallel Vision-Language Model
By
–
We trained a state-of-the-art diffusion VLM, A2D-VL 7B for parallel generation by finetuning an existing autoregressive VLM on the diffusion language modeling task, using the masked diffusion framework which "noises" tokens by masking them and "de-noises" tokens by predicting the… pic.twitter.com/zqU3szysQ1
— Runway (@runwayml) 24 septembre 2025We trained a state-of-the-art diffusion VLM, A2D-VL 7B for parallel generation by finetuning an existing autoregressive VLM on the diffusion language modeling task, using the masked diffusion framework which "noises" tokens by masking them and "de-noises" tokens by predicting the
-
Diffusion Models Advance Vision Language AI Research
By
–
Today we're sharing our first research work exploring diffusion for language models: Autoregressive-to-Diffusion Vision Language Models We develop a state-of-the-art diffusion vision language model, Autoregressive-to-Diffusion (A2D), by adapting an existing autoregressive vision