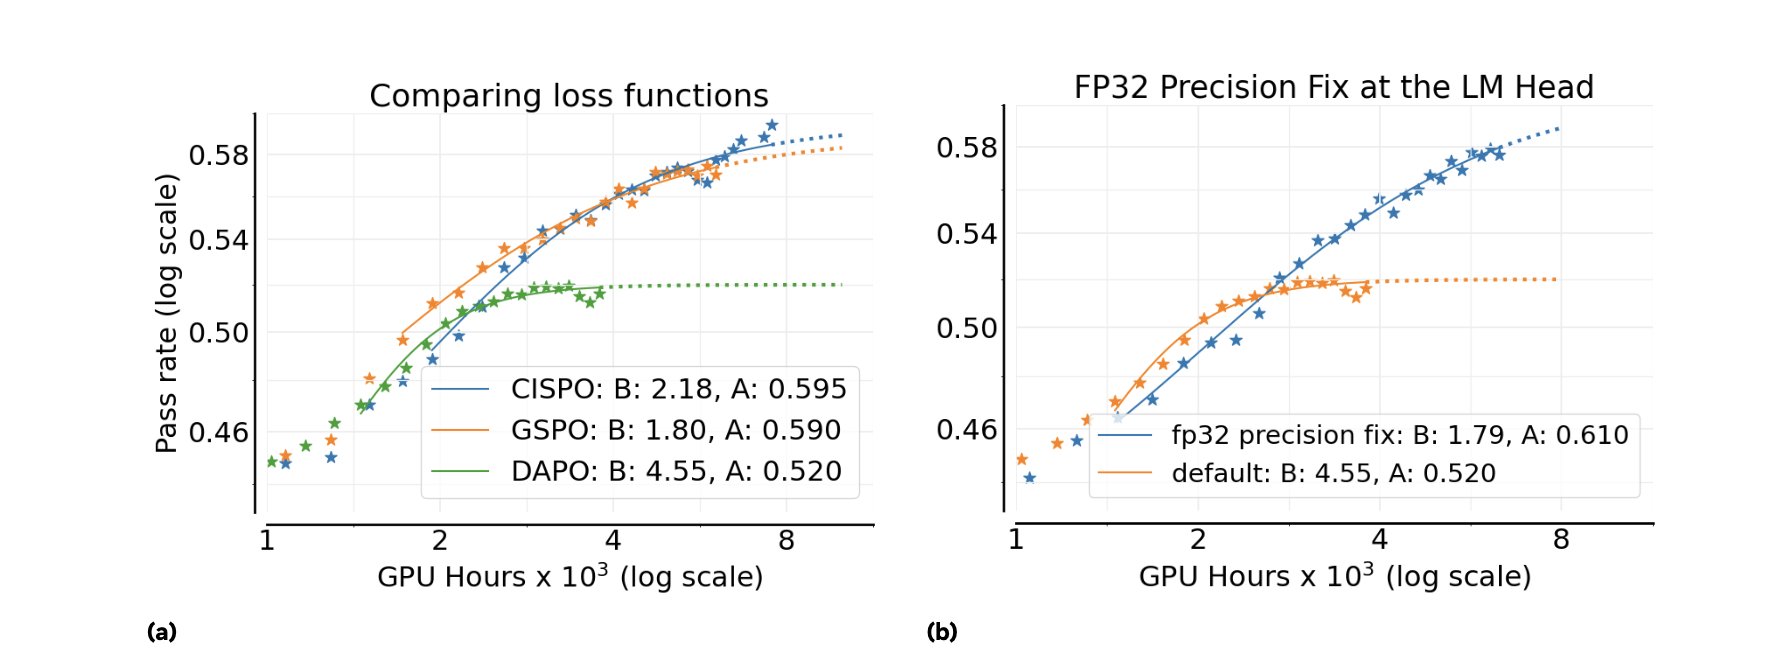
Here’s the wildest part… The same scaling law held across different model sizes, tasks, and sequence lengths. 8B dense model? 17B×16 MoE? Math + code RL tasks? Even 32k-token reasoning traces stayed on-curve. Stable scaling across everything.
LLMS
-
Predicting AI Model Performance from Small-Scale Training Runs
By
–
Why this matters: For the first time, we can predict asymptotic performance from small runs. Meta extrapolated 8k GPU-hour curves →
and nailed the actual performance at 100k GPU-hours. That’s predictive scaling in action no more trial and error. -
ScaleRL: Key Components Explained
By
–
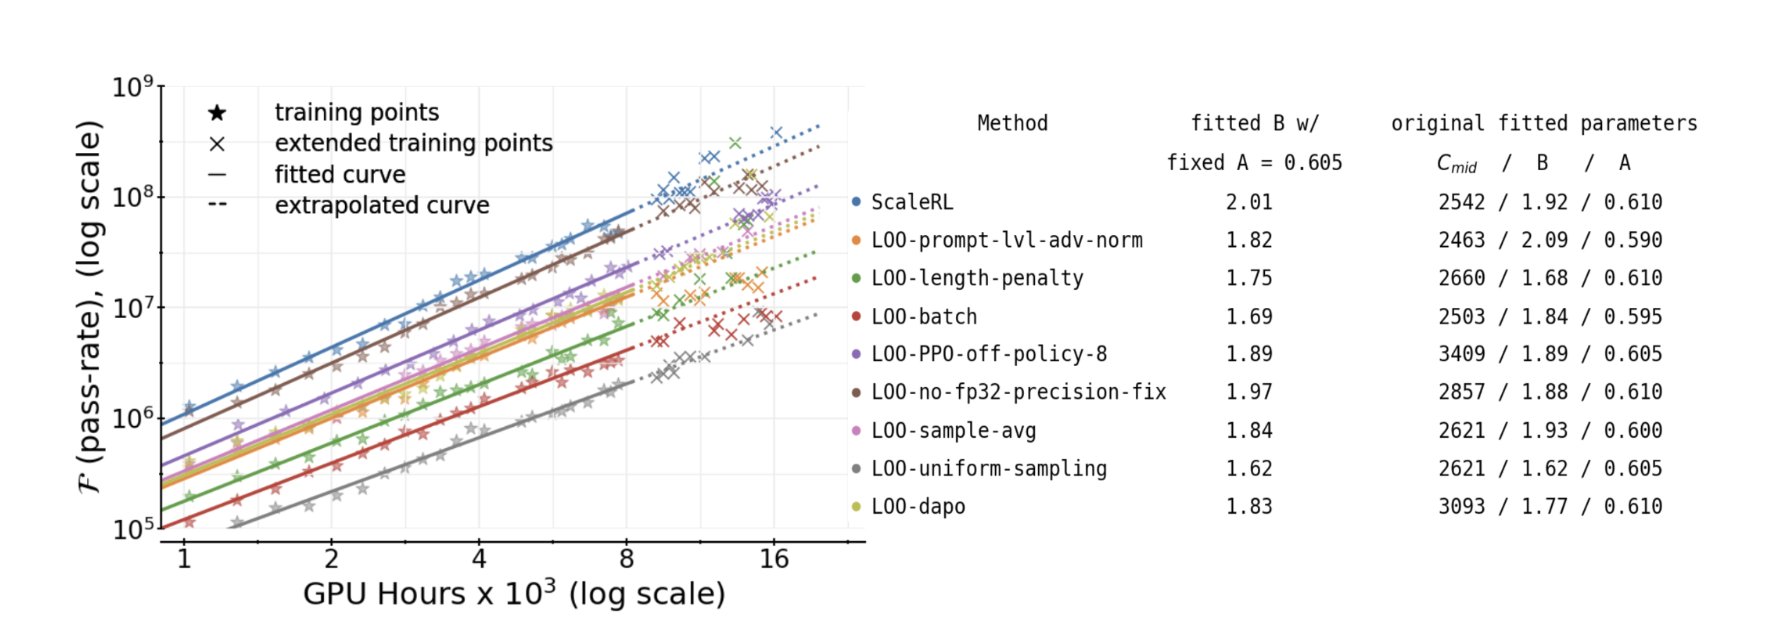
ScaleRL isn’t magic. It’s a recipe of small, proven ingredients: – Pipeline-RL async setup
– FP32 logits for stable gradients
– CISPO loss (clipped importance sampling)
– Prompt-level averaging
– Batch-level normalization
– No-Positive-Resampling (drop “too easy” prompts) -
ScaleRL outperforms in RL scaling tests
By
–
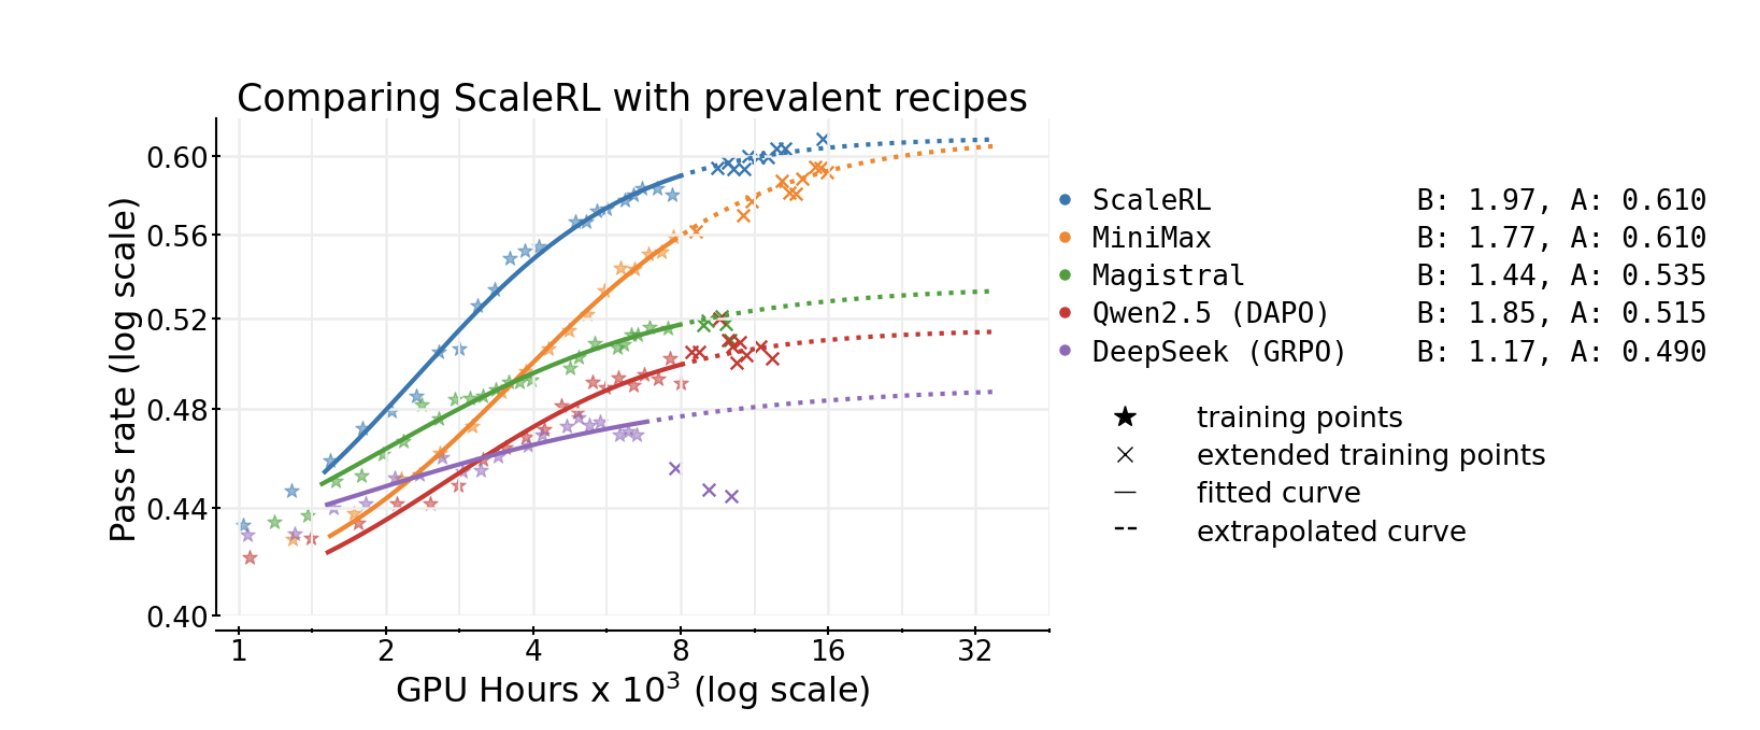
They tested this with 400,000 GPU hours across multiple RL recipes: DeepSeek (GRPO)
Qwen (DAPO)
Magistral
Minimax Result: only ScaleRL showed a stable, predictable trajectory. The others broke scaling laws entirely their curves collapsed. -
Meta’s ScaleRL reveals predictable RL scaling laws
By
–
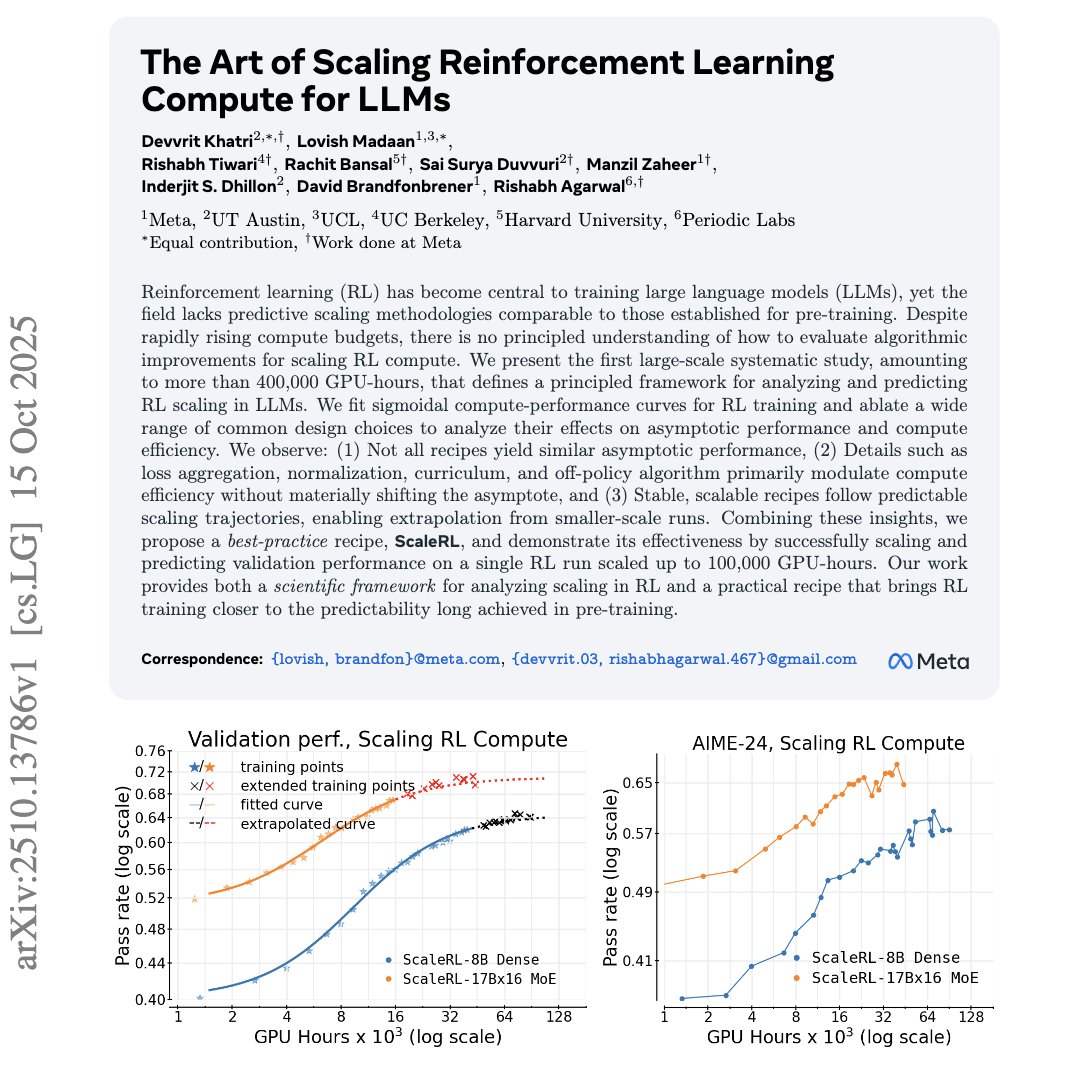
Holy shit… Meta just cracked the art of scaling RL for LLMs. For the first time ever, they showed that "reinforcement learning follows predictable scaling laws" just like pretraining. Their new framework, 'ScaleRL', fits a sigmoid compute-performance curve that can forecast
-

VIR-Bench: Evaluating Multimodal LLMs on Travel Video Understanding
By
–
How well can multimodal LLMs understand long-distance travel videos? Enter VIR-Bench, a new benchmark with 200 real-world travel videos that challenges models to reconstruct itineraries and reason over extended geospatial-temporal trajectories. Why it matters: mastering
-

RiskPO: Risk-Based Policy Optimization for LLM Post-Training
By
–
#PapersAccepted by Jiqizhixin
Our report: https://
mp.weixin.qq.com/s/9TbUIT6ed_wO
viVU0GuLqg
… RiskPO: Risk-based Policy Optimization via Verifiable Reward for LLM Post-Training Peking University
Paper: https://
arxiv.org/abs/2510.00911
v1
…
Code: https://
github.com/RTkenny/RiskPO -

Risk-based Policy Optimization Improves LLM Reasoning Through Reward Risk-Taking
By
–
RL keeps evolving! Now you can teach LLMs to reason better by rewarding risk-taking. Risk-based Policy Optimization (RiskPO) is a new reinforcement learning framework for post-training LLMs. Instead of averaging rewards like GRPO, RiskPO uses a Mixed Value-at-Risk objective
-
Windsurf launches SWE-grep for faster context retrieval
By
–
Windsurf announced SWE-grep and SWE-grep-mini models for faster context retrieval. These models are now available on Windsurf!
— 🚨 AI News | TestingCatalog (@testingcatalog) 16 octobre 2025
TPS 🤯 https://t.co/E3QgCw8ndK pic.twitter.com/VMWuFaUDRrWindsurf announced SWE-grep and SWE-grep-mini models for faster context retrieval. These models are now available on Windsurf! TPS
-
GPT-6 Likely Arriving Before Year End, CNBC Reports
By
–
BREAKING 🚨: GPT-6 is likely coming before the end of the year! This means, less than 2.5 months!
— 🚨 AI News | TestingCatalog (@testingcatalog) 16 octobre 2025
From the "Rise of agentic commerce could dramatically change the tech landscape: Evercore ISI's Mark Mahaney" video by CNBC
"Wen GPT-6?" time has come 👀 https://t.co/IxYIYTtwm8 pic.twitter.com/X16dyQIjHLBREAKING : GPT-6 is likely coming before the end of the year! This means, less than 2.5 months! From the "Rise of agentic commerce could dramatically change the tech landscape: Evercore ISI's Mark Mahaney" video by CNBC "Wen GPT-6?" time has come