9. Kimi Linear Kimi Linear introduces a hybrid linear attention architecture combining Kimi Delta Attention (KDA) with periodic full attention layers at a 3:1 ratio, achieving superior performance over full attention while reducing KV cache by 75% and delivering 6× faster
LLMS
-
Agent Data Protocol Standardizes LLM Agent Training Datasets
By
–
8. Agent Data Protocol Agent Data Protocol introduces a standardized format to unify fragmented agent training datasets across different tools and interfaces, enabling more efficient fine-tuning of LLM agents.
-
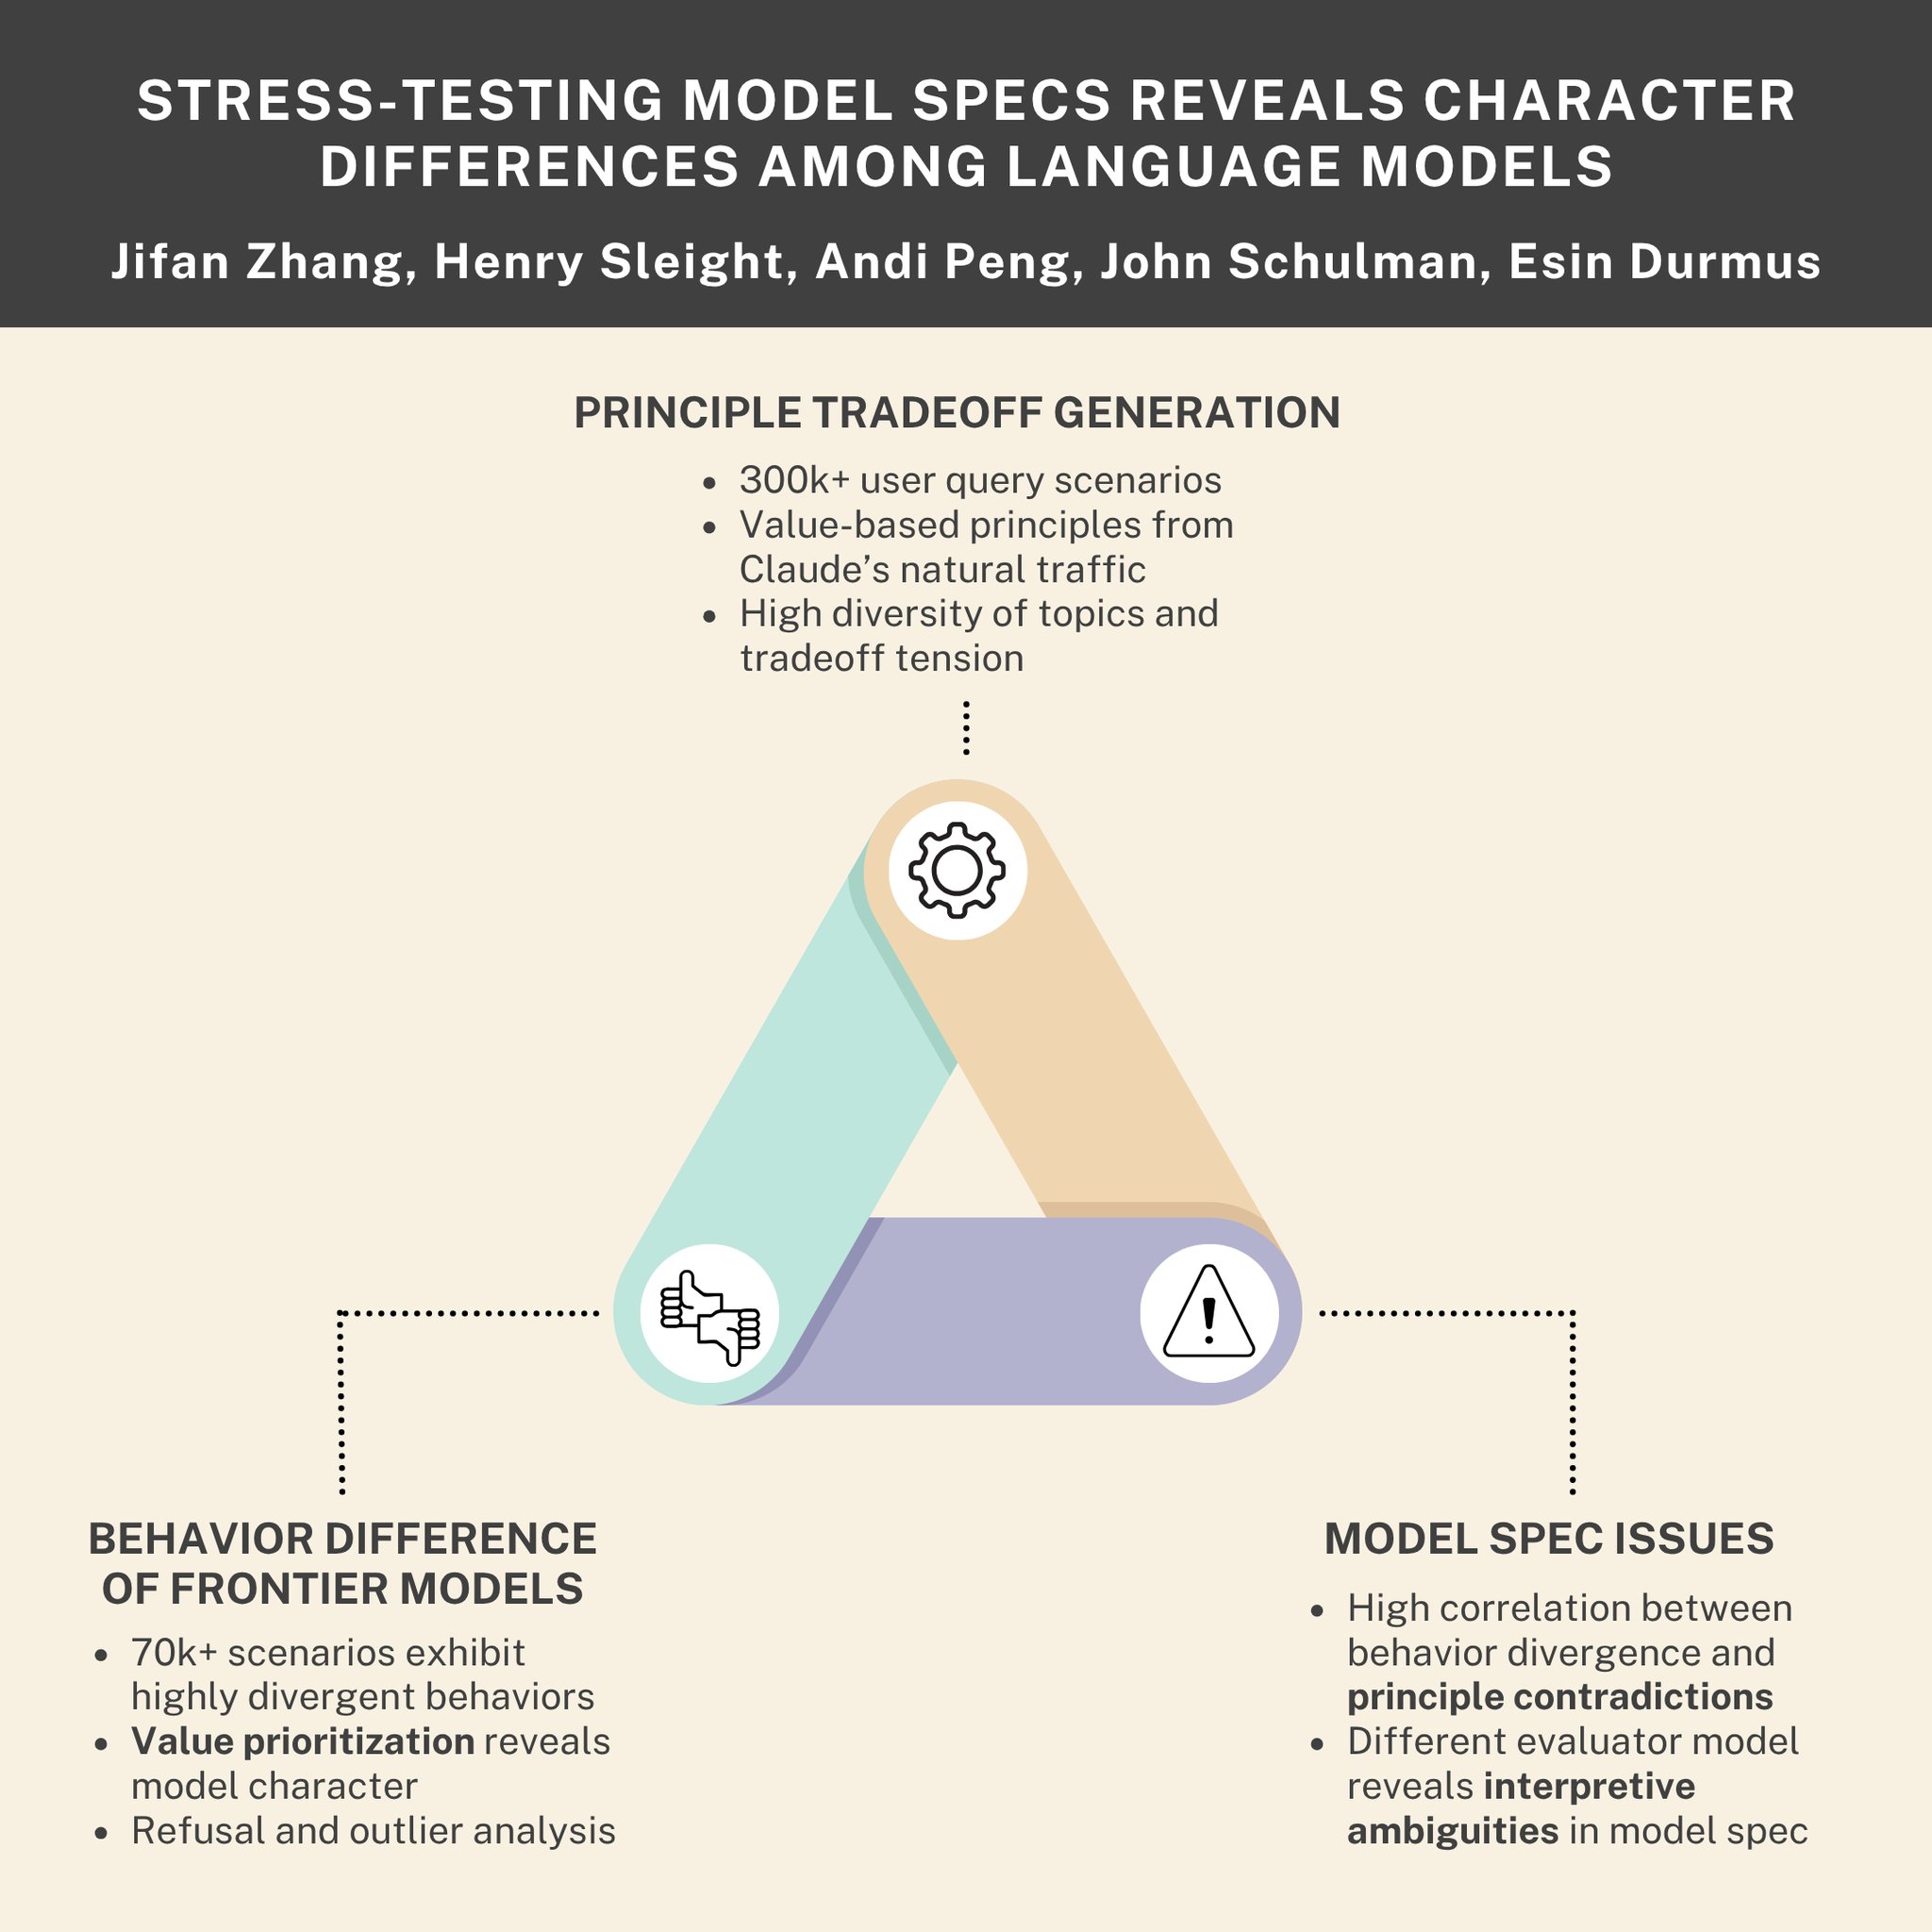
Stress-Testing LLM Constitutional Specifications and Behavioral Guidelines
By
–
7. Stress-Testing Model Specs This research examines how well large language models adhere to their stated behavioral guidelines by stress-testing AI constitutional specifications through value-tradeoff scenarios.
-

Global PIQA: Physical Commonsense Reasoning Across 100+ Languages
By
–
5. Global PIQA Global PIQA extends physical commonsense reasoning evaluation to 100+ languages and cultural contexts, revealing how language models handle everyday practical scenarios across diverse linguistic communities.
-

SmolLM2: Strategic Data Curation Over Scale in Language Models
By
–
4. SmolLM2 SmolLM2 demonstrates that strategic data curation beats scale through a 1.7B parameter model trained on 11 trillion tokens using iterative data mixing optimization.
-

Multi-Agent Evolve: LLMs Self-Improve Without Human Annotation
By
–
3. Multi-Agent Evolve Multi-Agent Evolve (MAE) enables LLMs to self-improve their reasoning capabilities without human-annotated data through a co-evolving multi-agent framework.
-

LLMs Show Limited Introspective Awareness Capabilities
By
–
2. Introspective Awareness Anthropic research demonstrates that contemporary LLMs possess limited but functional introspective capabilities, the ability to recognize and accurately report on their own internal states.
-
Open-source AI transparency crisis: Chinese base models audit challenges
By
–
state of open-source AI in 2025:
– almost all new open American models are finetuned Chinese base models
– we don’t know the base models’ training data
– we have no idea how to audit or “decompile” base models who knows what could be hidden in the weights of DeepSeek -
Groq’s Crazy October: Partnerships, Price Drops, and Major Updates
By
–
october was craaaazy:
– Groq IBM partnership
– McLaren keeps winning with Groq on the halo
– gpt-oss-safeguard day 0 on GroqCloud
– gpt-oss 120/20B major price drop + prompt caching
– Huge openbench v0.5.0 release with 350+ new evals
– @JonathanRoss321 speaks at @FIIKSA – Groq -

Attending EMNLP2025 in Suzhou presenting multimodal LLM grounding work
By
–
I will be heading to Suzhou soon attending #EMNLP2025 next week, presenting my work on grounding multimodal LLMs with world/cultural knowledge, https://
arxiv.org/abs/2508.07414. Email/DM open if you want to chat about the paper and other topics more broadly(multimodal LLMs x languages x