
I appreciate how Grok doesn’t sugar coat corrections.
LLMS
-

MiniMax-M2 Open Source Model Available on Poe
By
–
MiniMax-M2 is now available on Poe! This open source model has a 200k token context window, has 230b parameters with an MoE architecture, and excels at coding and agent workflows. (1/2)
-
Minimax-M2 AI Model Now Available on Poe Platform
By
–
You can try it at https://
poe.com/Minimax-M2, across the Poe apps on all platforms, and via the Poe API. (2/2) -
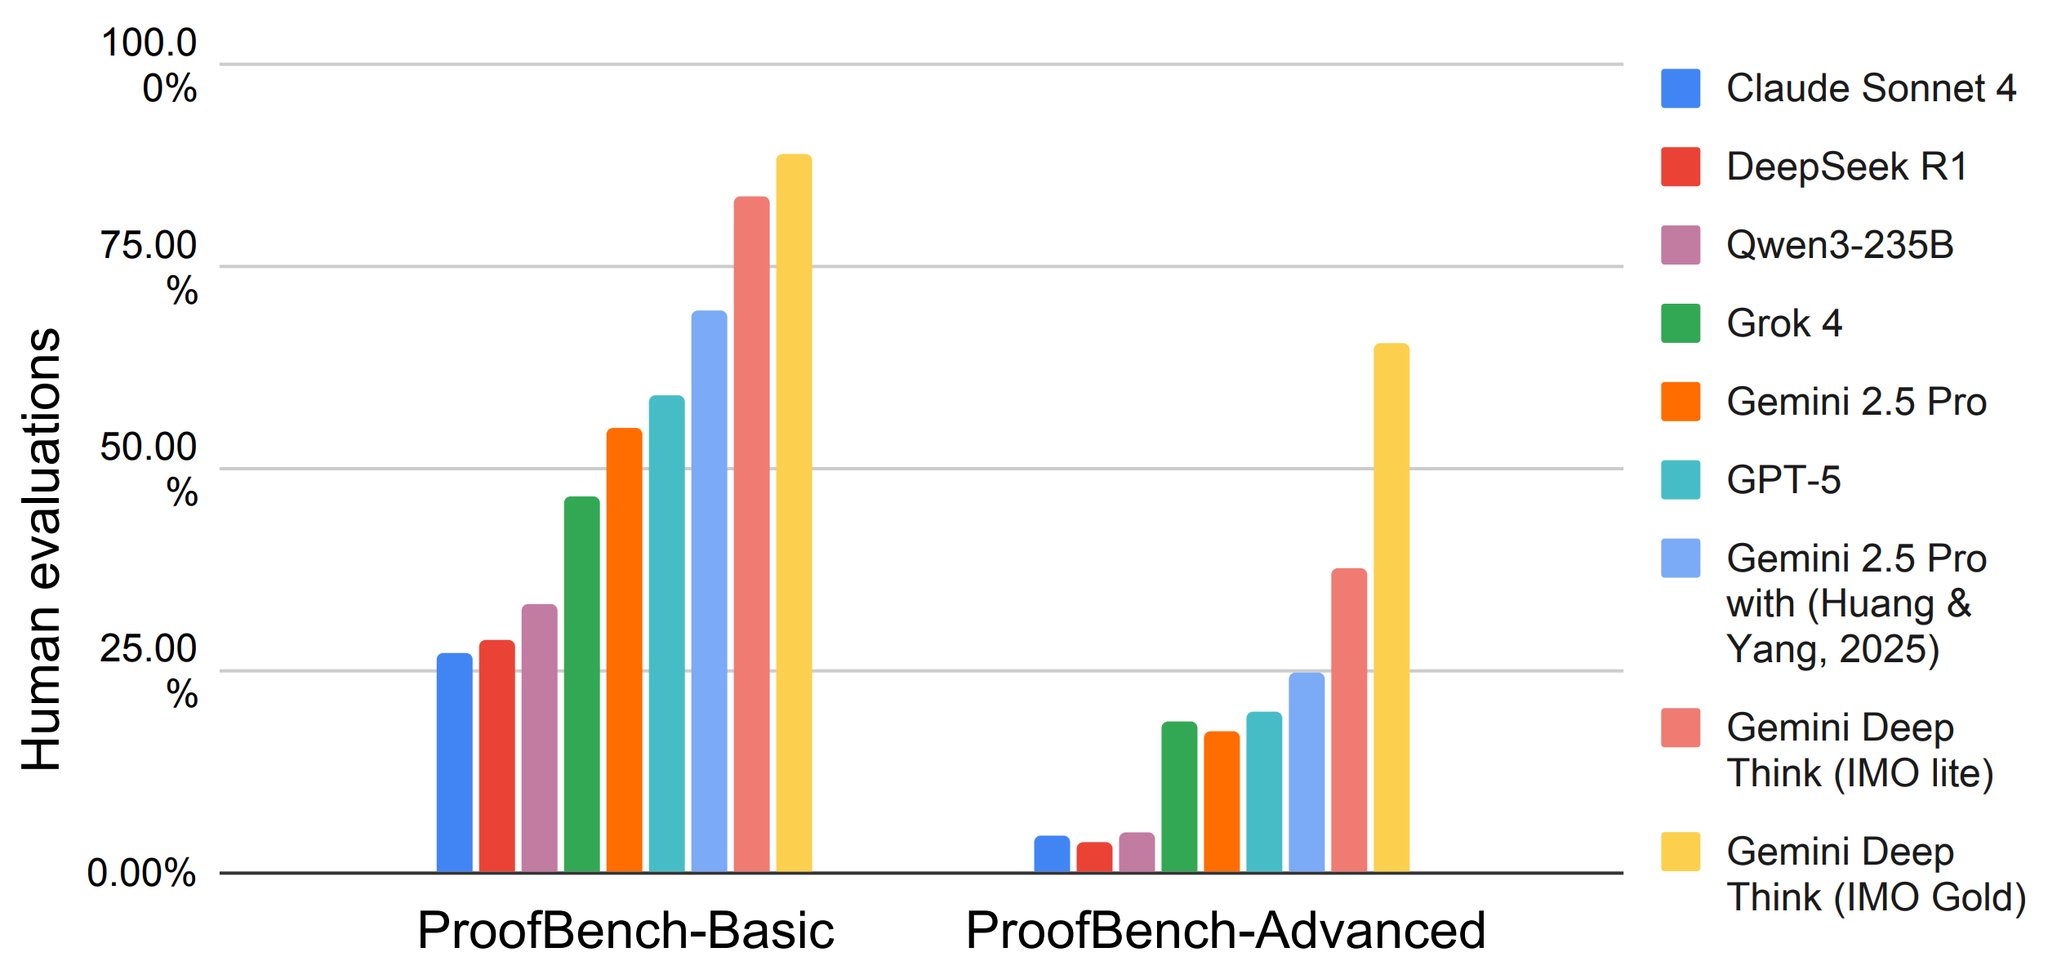
IMO-ProofBench: Evaluating AI Mathematical Reasoning Capabilities
By
–
IMO-ProofBench is our key focus designed to evaluate the ability of AI models in constructing rigorous and valid mathematical arguments. With 60 proof-based problems, the benchmark is divided into two subsets: a basic set covering pre-IMO to IMO-Medium difficulty levels, and an
-
Waterfall Development with LLMs: Inherent Challenges
By
–
Waterfall based development with LLMs have all the challenges with waterfall based dev?
-

IMO-Bench: New AI Model Evaluation Framework for Mathematics
By
–
IMO-Bench consists of three benchmarks that judge models on diverse capabilities: IMO-AnswerBench, a large-scale test on getting the right answer; IMO-ProofBench, a next-level evaluation for proof writing; and IMO-GradingBench, a new benchmarkto enable further progress in
-
LangSmith for Improving Agent Quality at Scale
By
–
Why we built LangSmith for improving agent quality
— LangChain (@LangChain) 4 novembre 2025
As more agents move into production, teams need to move beyond vibe-checking and bring rigor to how they understand agent behavior at scale.
In this video, the LangSmith engineering team and Harrison (@hwchase17) sit down to… pic.twitter.com/q7jrXfWJo1Why we built LangSmith for improving agent quality As more agents move into production, teams need to move beyond vibe-checking and bring rigor to how they understand agent behavior at scale. In this video, the LangSmith engineering team and Harrison (
@hwchase17
) sit down to -
Jamba Reasoning 3B outperforms Qwen 3 4B in speed test
By
–
Our Jamba Reasoning 3B model took on Qwen 3 4B 2507 by @Alibaba_Cloud in the same 60K token task. Jamba Reasoning 3B finished nearly 3× faster.
— AI21 Labs (@AI21Labs) 4 novembre 2025
🎥 Watch how it played out 👇
👉 Download Jamba Reasoning 3B here: https://t.co/W0ajfxd8ll pic.twitter.com/noeZNd6j1VOur Jamba Reasoning 3B model took on Qwen 3 4B 2507 by @Alibaba_Cloud in the same 60K token task. Jamba Reasoning 3B finished nearly 3× faster. Watch how it played out Download Jamba Reasoning 3B here: https://
huggingface.co/collections/ai
21labs/jamba-reasoning-3b
… -

16,800 Academic Papers Reference GPT-4 in 2025
By
–
There are 16,800 papers on Google Scholar that were published in 2025, which reference GPT-4, but not any future versions of GPT, e.g. no GPT-4o, 4.1, 4.5, or 5.
-
Effortless expert interaction: Grunt, mumble, get it done.
By
–
How you’d talk to a respected expert is way too much work. You should just sort of grunt and mumble half a keyword and it does what you want.