I’ve tested this on:
→ Business strategy decisions
→ Technical debugging
→ Research synthesis
→ Investment analysis The difference isn’t subtle. It’s like going from a Magic 8-Ball to a panel of consultants. And it works in ChatGPT, Claude, Gemini. Any model.
LLMS
-
From Magic 8-Ball to consultant panel: method tested across domains
By
–
-
Multi-perspective check catches errors before they reach you
By
–
The multi-perspective check catches errors before they reach you: ✓ Does the logic actually hold?
✓ Are the facts grounded?
✓ Is anything missing?
✓ Are there hidden assumptions? Most AI answers fail at least one of these. This framework catches them. -
AI framework vs standard prompt: breakdown and verification
By
–
Real example:
Standard prompt: “What’s the best marketing strategy for my SaaS?” AI gives you ONE answer. Sounds confident. Might be completely wrong for your situation. With this framework:
AI breaks it down, verifies each piece, tells you WHERE it’s uncertain. Night and day. -

MIT’s Recursive Meta-Cognition Boosts Prompting by 110%
By
–
R.I.P. basic prompting. MIT just dropped a technique that makes ChatGPT reason like a team of experts instead of one overconfident intern. It’s called “Recursive Meta-Cognition” and it outperforms standard prompts by 110%. Here’s the prompt (and why this changes everything)
-

Reciprocal Rank and Relative Score Fusion Hybrid Search
By
–
Reciprocal Rank Fusion and Relative Score Fusion: Classic Hybrid Search Techniques https://
buff.ly/82sOdAd
#AI #MachineLearning #DeepLearning #LLMs #DataScience -

Google Integrates Agentflow into Gemini for Business
By
–
Google is working on integrating Agentflow into Gemini for Business. Agentflow is an automation builder in Google Workspace that allows you to build agentic pipelines, and it seems like they will become more integrated into Gemini Agent builder in the future. Consolidation
-
How soon will AI coding bots build an entire OS?
By
–
How long before someone uses AI coding bots to build a whole OS from scratch?
-
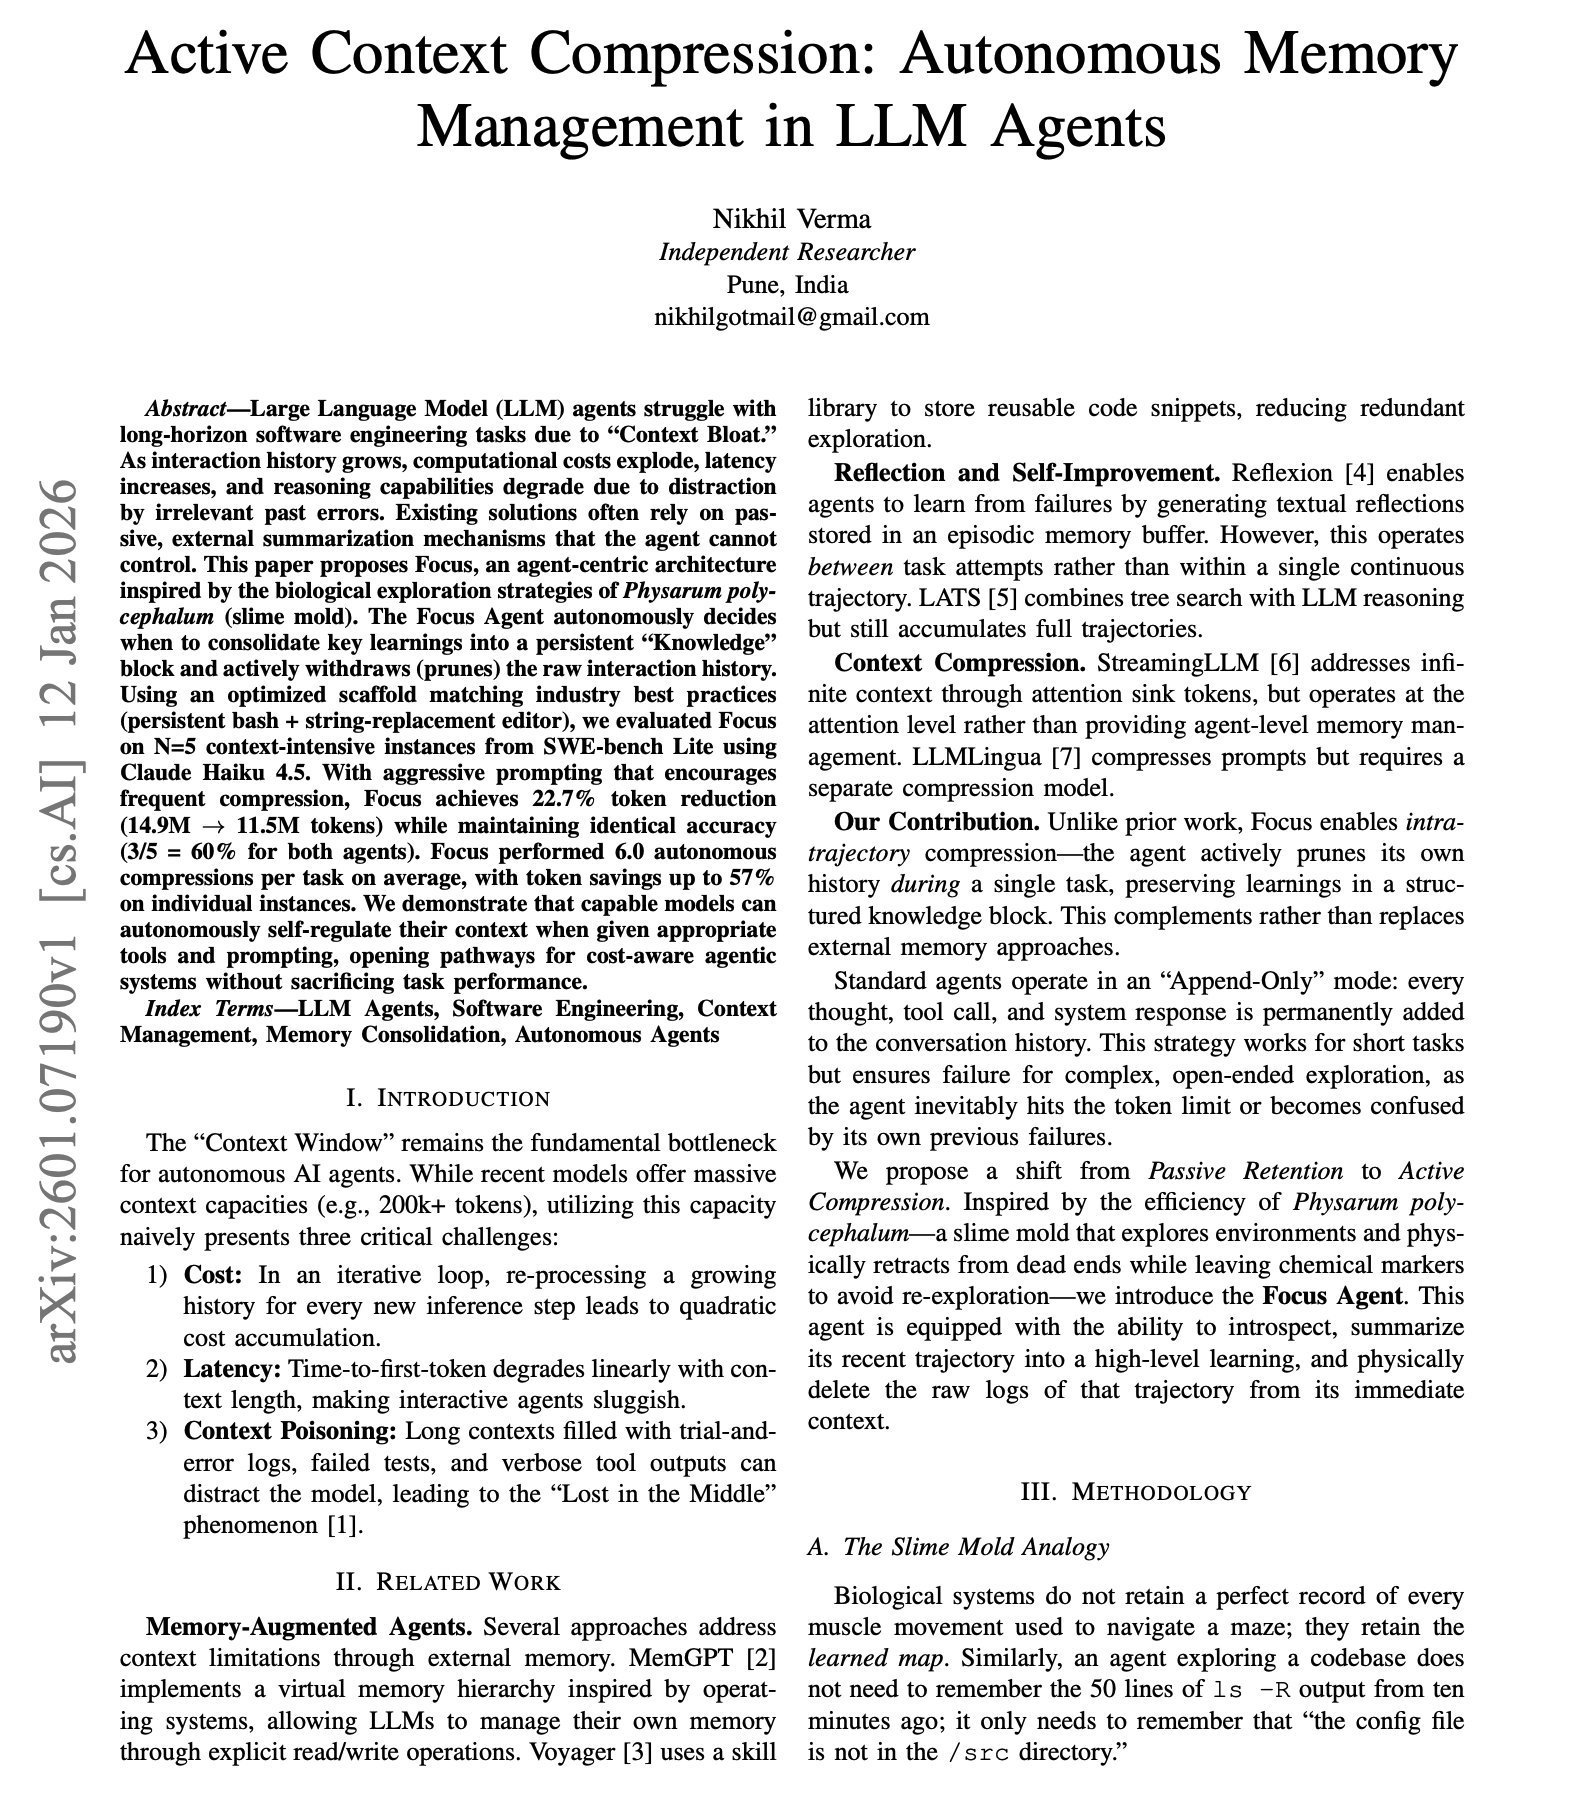
Autonomous Memory Management in LLM Agents
By
–
Autonomous Memory Management in LLM Agents LLM agents struggle with long-horizon tasks due to context bloat. As interaction history grows, computational costs explode, latency increases, and reasoning degrades from distraction by irrelevant past errors. The standard approach
-
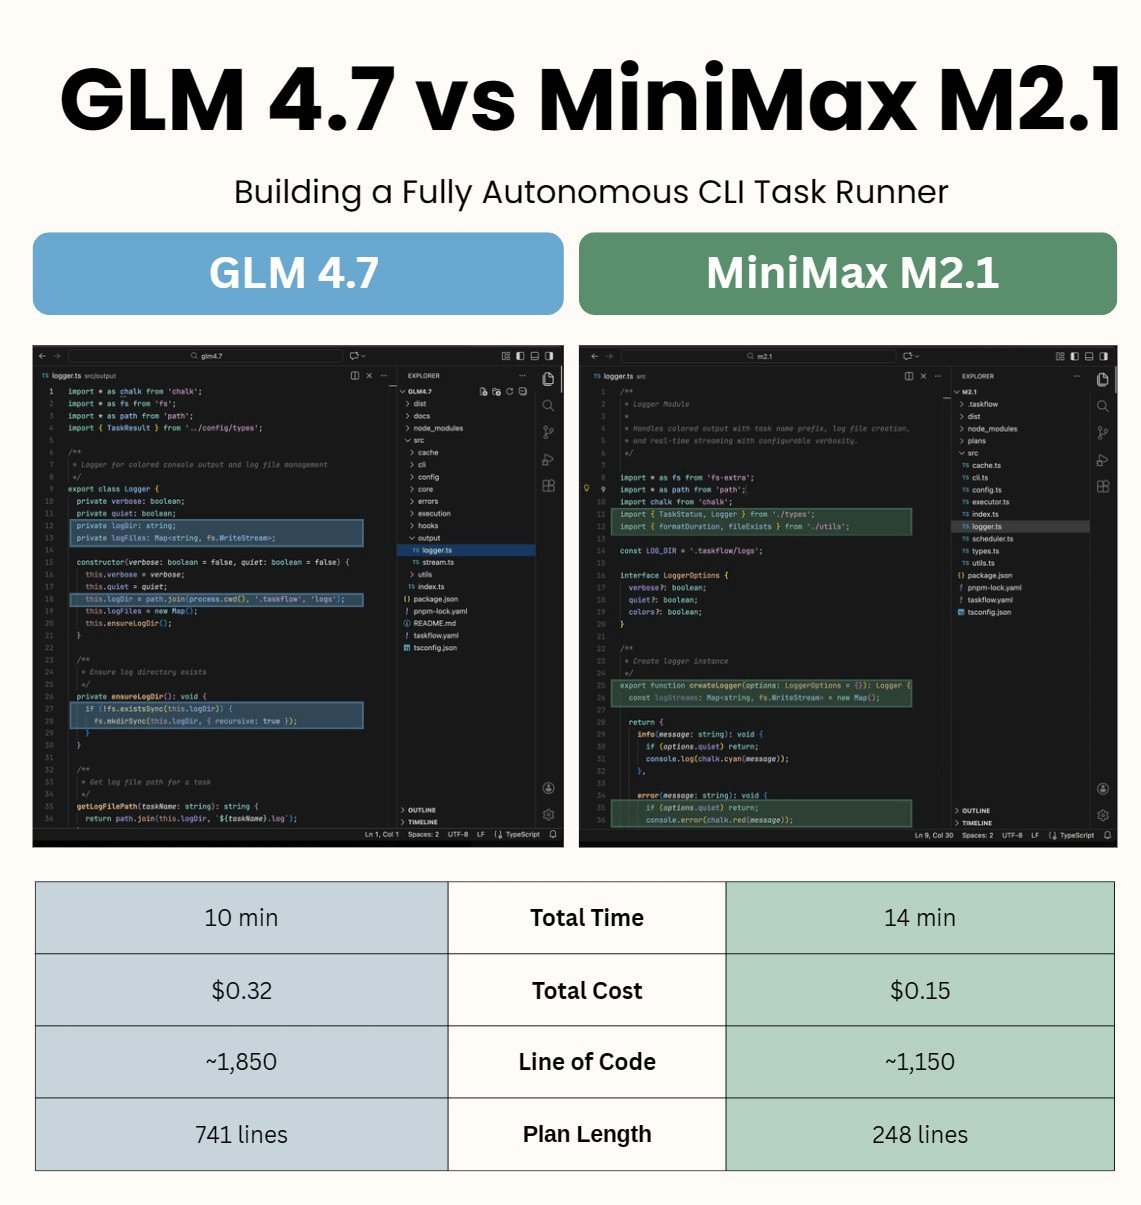
Open-Weight Models Build CLI Runner Autonomously Without Human Intervention
By
–
Open-weight models just built a 20-feature CLI runner autonomously! Kilo Code tested MiniMax M2.1 and GLM 4.7 by having them build a complete CLI task runner from scratch. Both models succeeded. No human intervention for 10-14 minutes straight. The test was realistic: build a