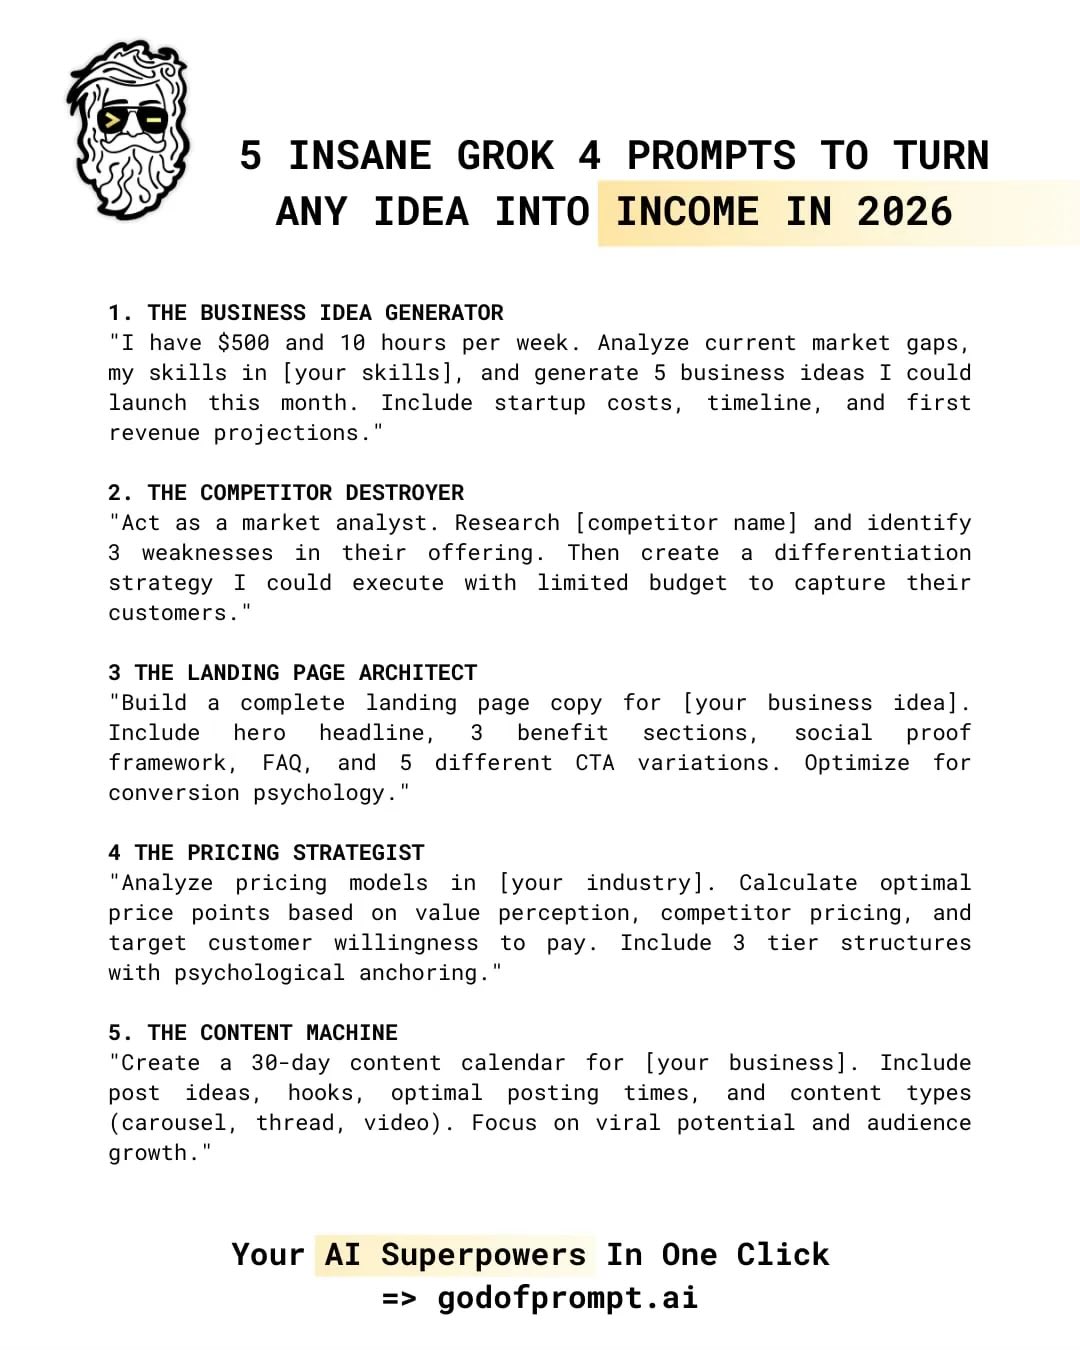
Steal my Grok prompts to create a business in 2026 Bookmark for later.
LLMS
-

Claude’s new writing pattern: not [x], not [y], [z]
By
–
new writing pattern emerged in Claude: not [x].
not [y].
[z]. -

Test-time compute scaling makes large training runs obsolete
By
–
The brutal truth: The future isn't bigger models trained on more data. It's smarter inference strategies that make small models think deeper. Test-time compute scaling just made the $100M training run obsolete. Intelligence is no longer about size—it's about how long you let
-
Implications cascade: inference hardware, reasoning strategies, open-source rise
By
–
The implications cascade: – Inference hardware becomes more valuable than training clusters
– Optimization shifts from pre-training to reasoning strategies
– Model size matters less than inference efficiency
– Open-source models compete with closed frontier models The playing -
DeepSeek-R1 beats 10x larger models by thinking longer
By
–
This explains why DeepSeek-R1 beats models 10x its size. It's not bigger. It's not trained on more data. It just thinks longer and verifies harder. 32B parameters thinking for 30 seconds > 405B parameters answering instantly. The scaling law just changed from "bigger" to
-
Dynamic compute allocation adjusts thinking time based on query difficulty
By
–
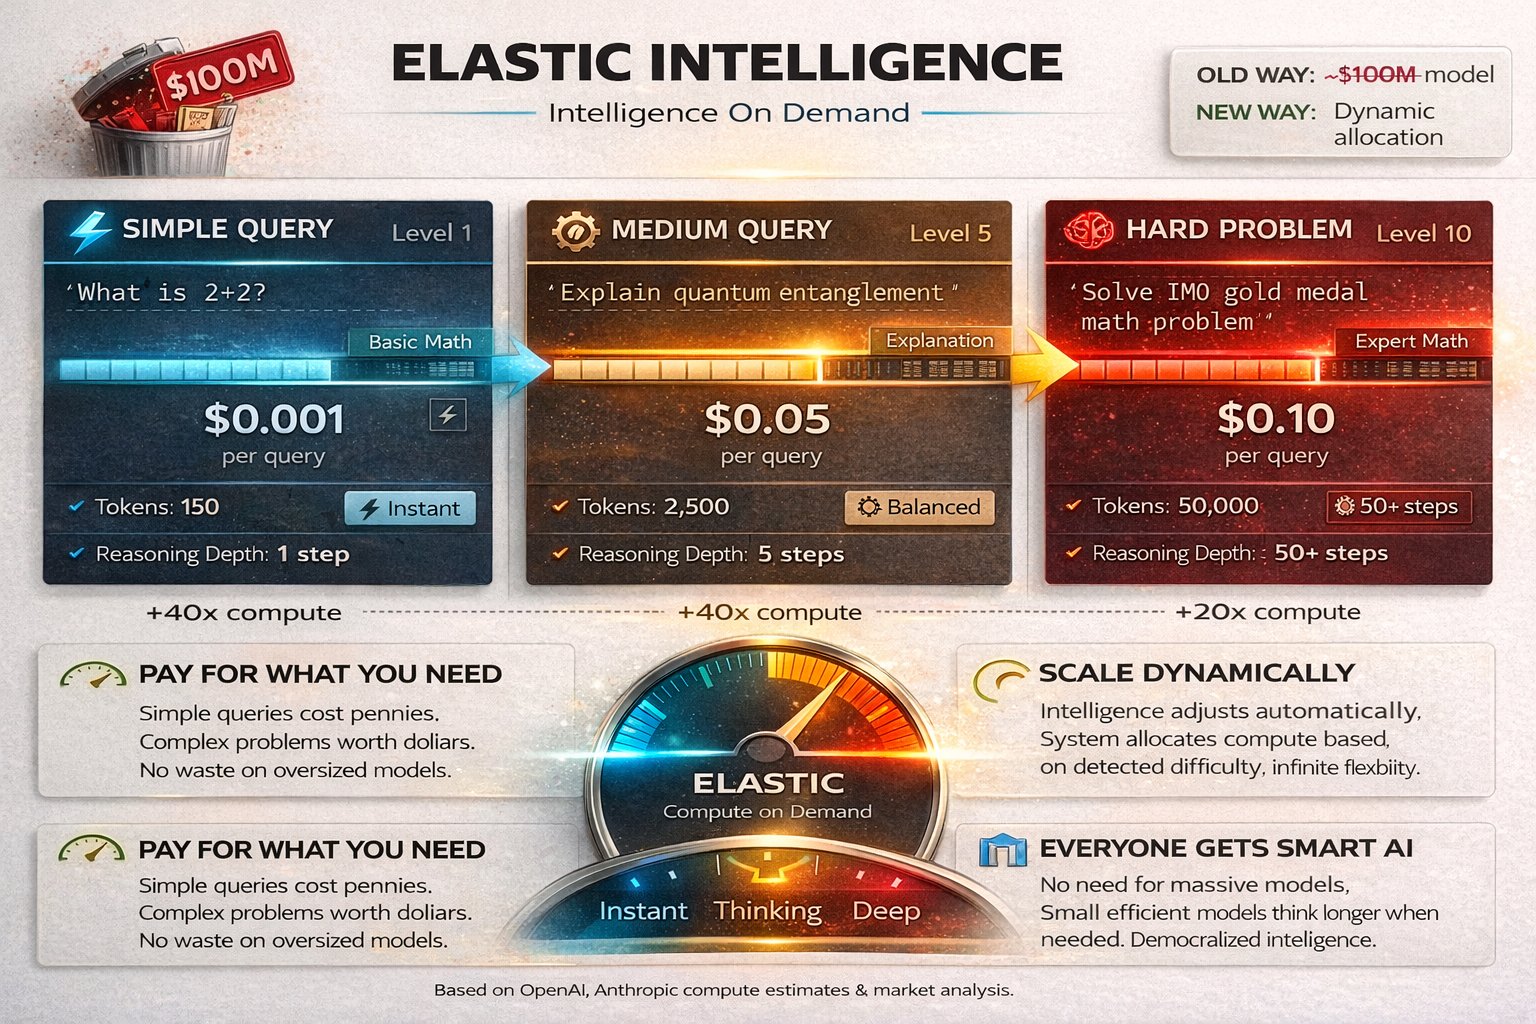
Dynamic compute allocation is the killer feature. Easy query: 0.1 seconds, minimal cost
Medium complexity: 2 seconds, moderate cost
Hard problem: 60 seconds, deep reasoning The model automatically adjusts thinking time based on difficulty. Pay for intelligence only when you -
Wild AI research directions: Best-of-N, tree search, self-verification, process supervision
By
–
The research directions are wild: – Best-of-N sampling: Generate 100 answers, pick the best
– Tree search: Explore reasoning branches like chess moves
– Self-verification: Model checks its own work recursively
– Process supervision: Reward correct reasoning steps, not just -

Elastic Intelligence: small model, dynamic per-query scaling
By
–
This makes $100M training runs obsolete. Why spend months training a massive model when you can deploy a smaller one and scale intelligence dynamically per query? Hard math problem? Give it 60 seconds to think.
Simple question? Answer instantly. Intelligence becomes elastic -

Economics flip: small models with more inference match GPT-4
By
–
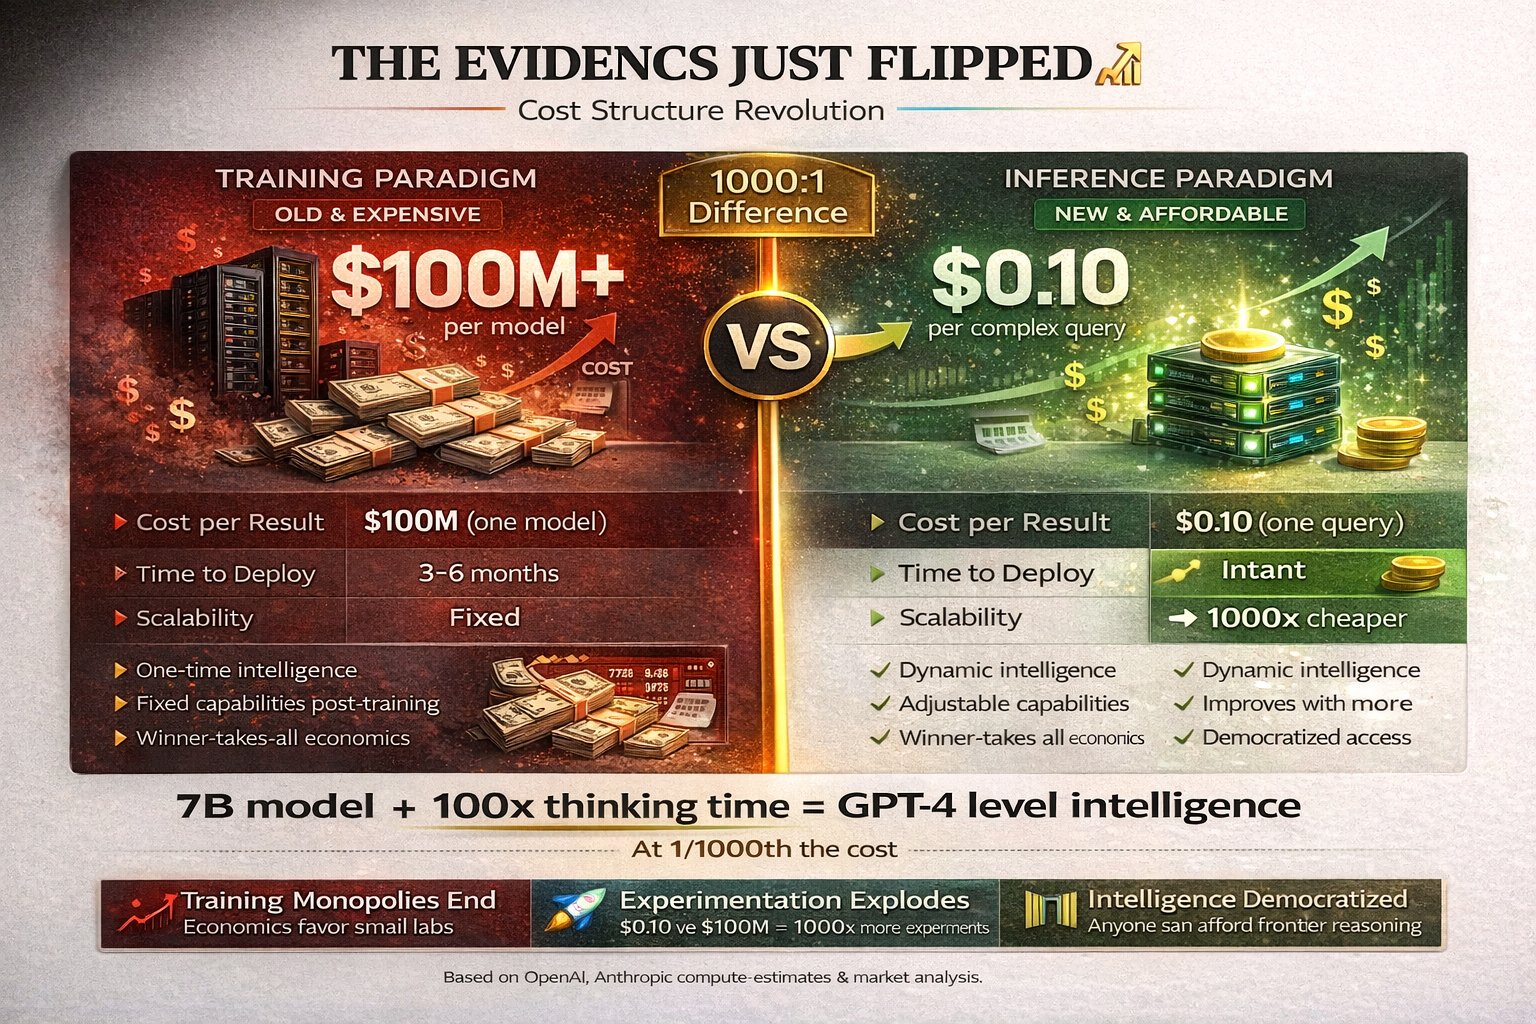
The economics just flipped completely. Training GPT-4: $100M+ in compute
Inference scaling: $0.10 per complex query You can make a 7B model as smart as GPT-4 by letting it think 100x longer at inference. Smaller models + more thinking time = beats bigger models at fraction of -
All frontier AI labs discover identical reasoning breakthrough
By
–
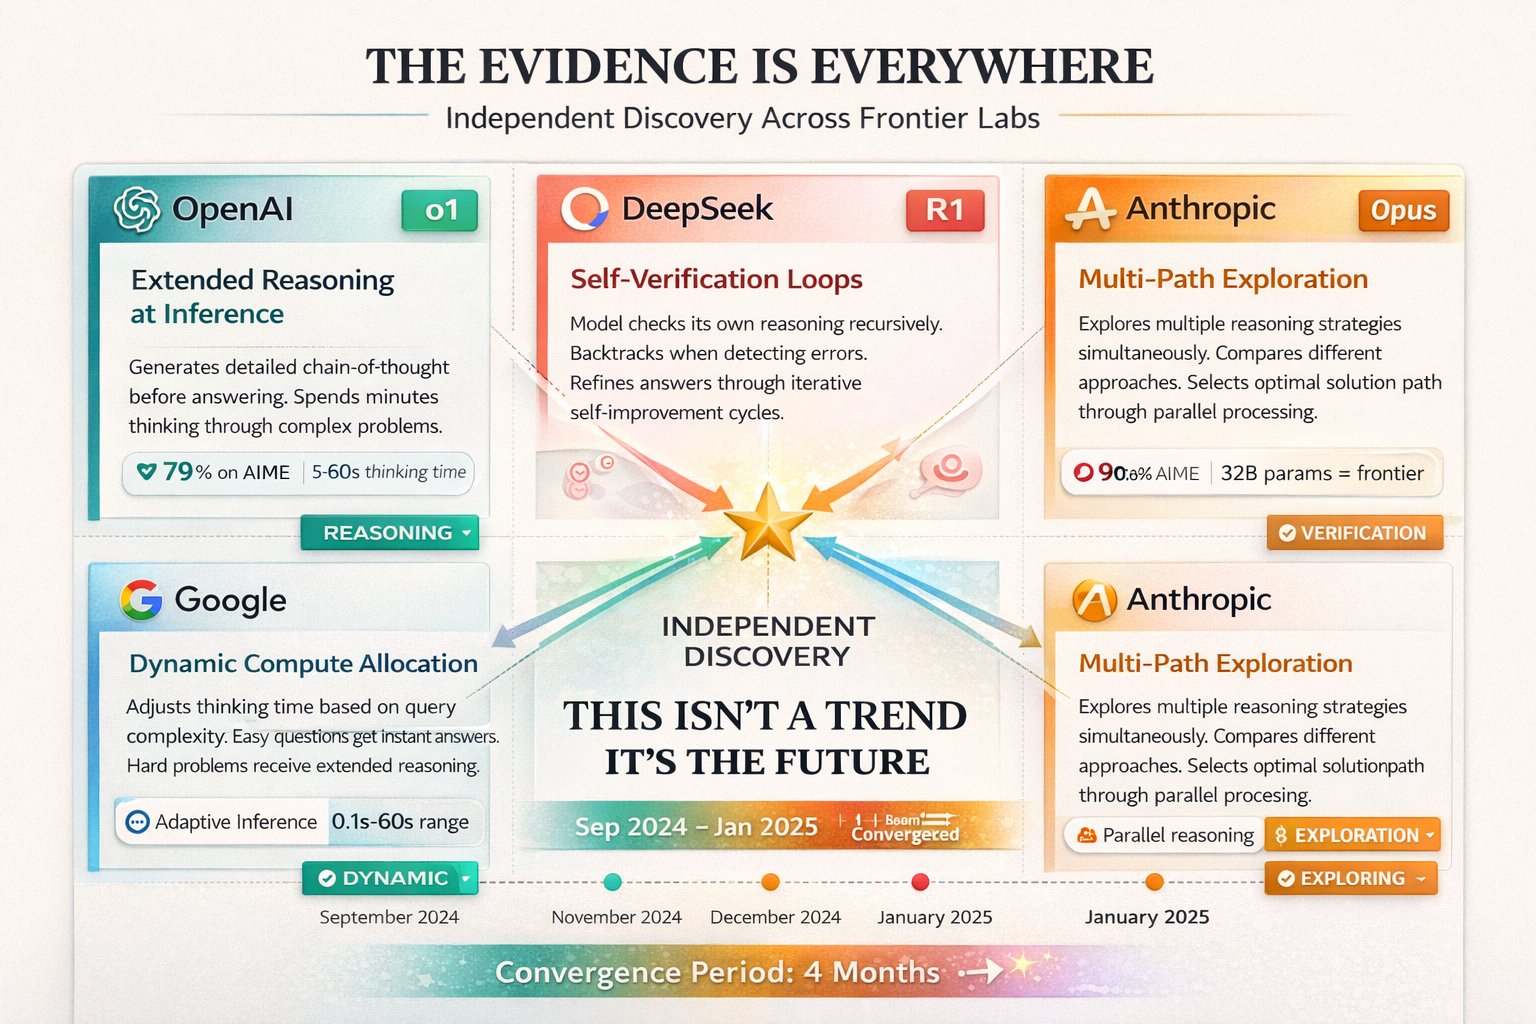
The evidence is everywhere: – OpenAI o1: Extended reasoning at inference
– DeepSeek-R1: Self-verification loops
– Gemini 2.0 Thinking: Dynamic compute allocation
– Claude Opus: Multi-path exploration Every frontier lab independently discovered the same breakthrough. This isn't