Progress in AI:
Pre-LLMs: The computer checks your math
Post-LLMs: You check the computer's math
LLMS
-
The Shift in Human-Computer Interaction Paradigms Post-LLMs
By
–
-
Foundational models are IQ; enterprise agents need judgment
By
–
Foundational models are IQ.
— AI Breakfast (@AiBreakfast) 24 février 2026
Enterprise agents need judgment.
The gap between demo and production is where most AI dies. If you can’t measure it, you don’t have AI infra, just vibes. https://t.co/96LSAPqwe3Foundational models are IQ.
Enterprise agents need judgment. The gap between demo and production is where most AI dies. If you can’t measure it, you don’t have AI infra, just vibes. -
Automating Job Searches with AI Prompts
By
–
L'IA peut maintenant automatiser TOUTE votre recherche d'emploi (gratuitement). Voici 15 prompts Claude 3.5 + DeepSeek qui décrochent 5+ entretiens en 48h. (Ajoutez en signet avant que tout le monde les utilise)
-
Introducing the LFM2-24B-A2B Model on Hugging Face
By
–
huggingface.co/LiquidAI/LFM2… [Translated from EN to English]
→ View original post on X — @maximelabonne, 2026-02-24 17:48 UTC
-
Using Claude Code for household chore automation
By
–
I just fired my kids from their chore duties. They were pretty bad at those. Claude Code does them much better now.
-
Unfortunate timing: 24B-A2B release coincides with Qwen3.5 launch
By
–
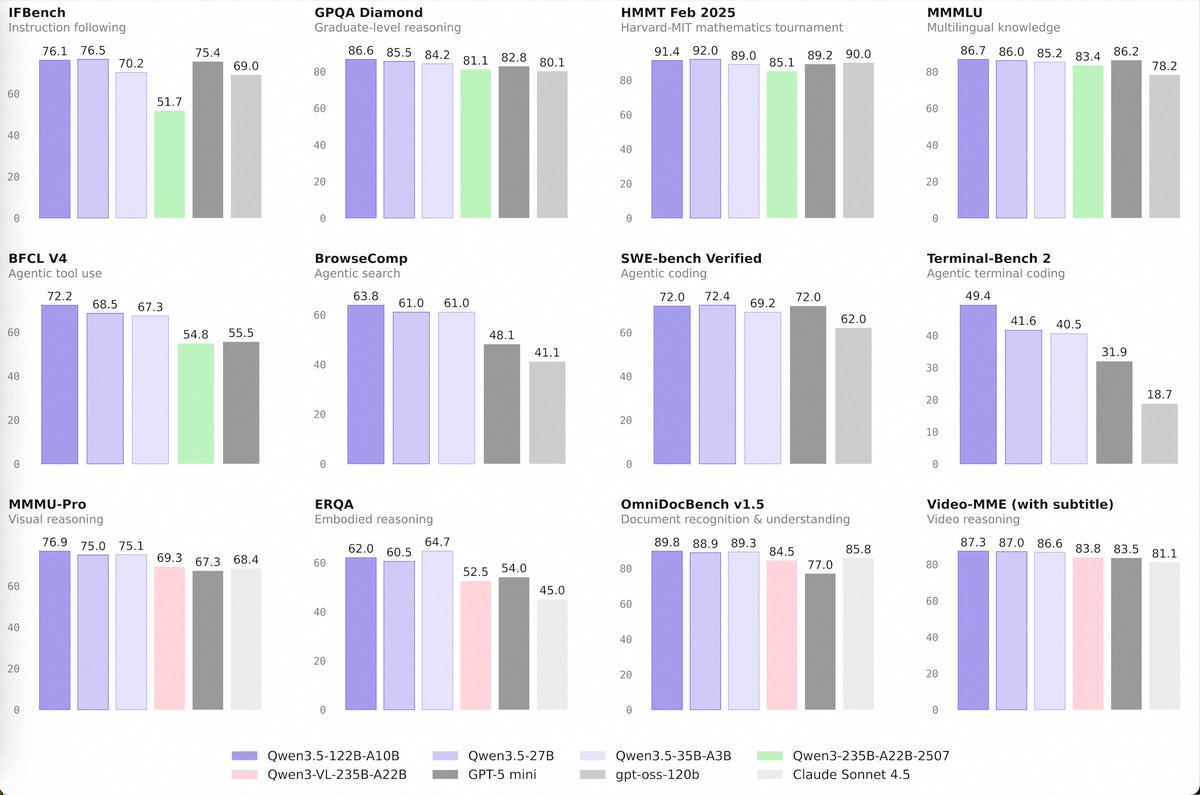
Releasing a 24B-A2B model on the same day as Qwen3.5-35B-A3B is NOT great timing 🥲 Qwen (@Alibaba_Qwen) 🚀 Introducing the Qwen 3.5 Medium Model Series Qwen3.5-Flash · Qwen3.5-35B-A3B · Qwen3.5-122B-A10B · Qwen3.5-27B ✨ More intelligence, less compute. • Qwen3.5-35B-A3B now surpasses Qwen3-235B-A22B-2507 and Qwen3-VL-235B-A22B — a reminder that better architecture, data quality, and RL can move intelligence forward, not just bigger parameter counts. • Qwen3.5-122B-A10B and 27B continue narrowing the gap between medium-sized and frontier models — especially in more complex agent scenarios. • Qwen3.5-Flash is the hosted production version aligned with 35B-A3B, featuring: – 1M context length by default – Official built-in tools 🔗 Hugging Face: huggingface.co/collections/Q… 🔗 ModelScope: modelscope.cn/collections/Qw… 🔗 Qwen3.5-Flash API: modelstudio.console.alibabac… Try in Qwen Chat 👇 Flash: chat.qwen.ai/?models=qwen3.5… 27B: chat.qwen.ai/?models=qwen3.5… 35B-A3B: chat.qwen.ai/?models=qwen3.5… 122B-A10B: chat.qwen.ai/?models=qwen3.5… Would love to hear what you build with it. — https://nitter.net/Alibaba_Qwen/status/2026339351530188939#m
→ View original post on X — @maximelabonne, 2026-02-24 17:01 UTC
-
LFM2-24B-A2B: Liquid AI’s Fastest 24B MoE Model Released
By
–
Meet LFM2-24B-A2B, @liquidai's largest model. 24B MoE, 2B active. Blazing fast even on CPU. Available now in LM Studio 👾💧 lmstudio.ai/models/lfm2-24b-…
→ View original post on X — @maximelabonne, 2026-02-24 15:44 UTC
-
Liquid AI releases LFM2-24B-A2B model for on-device inference
By
–
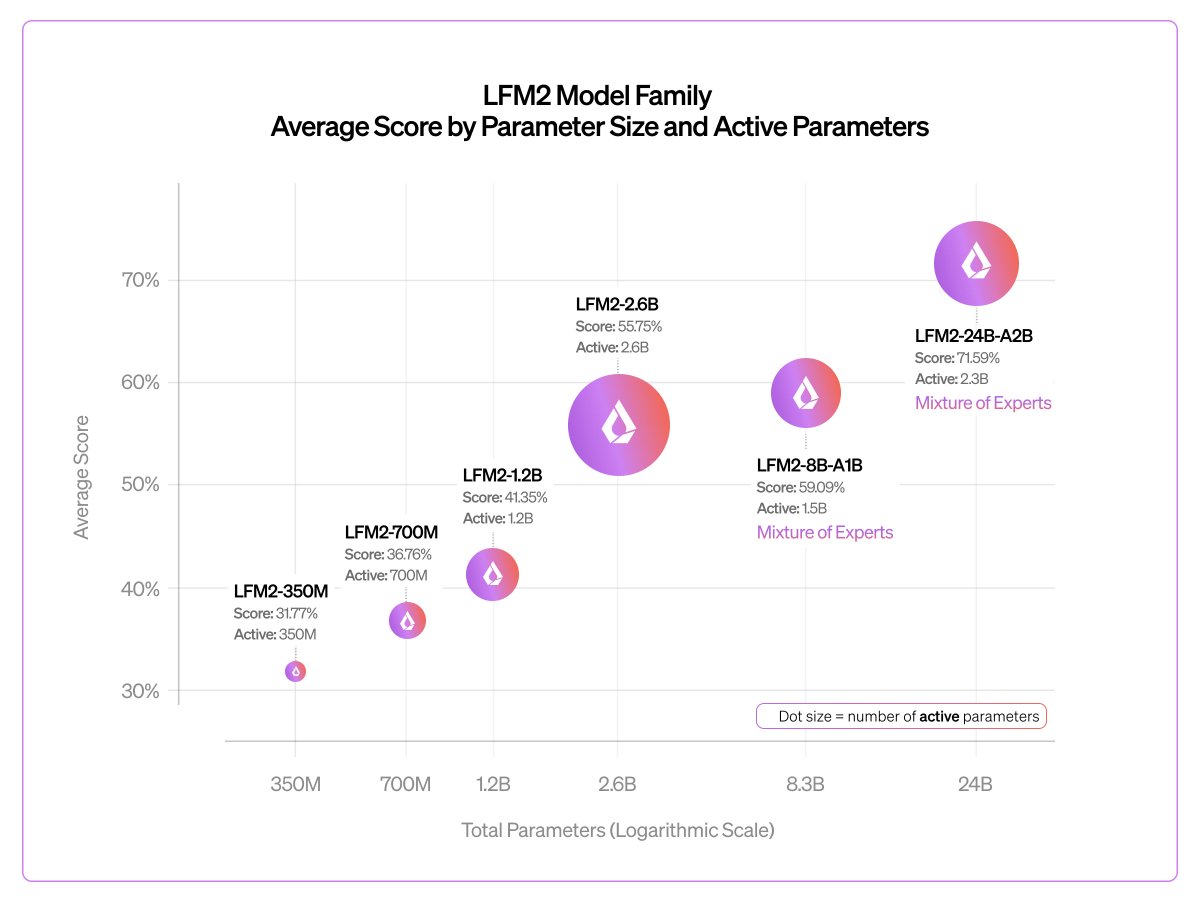
ollama run lfm2:24b-a2b .@liquidai's latest on-device model is here! It's the largest LFM2 model yet, and is designed to run fast on device, and fits on devices with 32GB of unified memory. Liquid AI (@liquidai) Today, we release our largest LFM2 model: LFM2-24B-A2B 🐘 > 24B total parameters > 2.3B active per token > Built on our hybrid, hardware-aware LFM2 architecture It combines LFM2’s fast, memory-efficient design with a Mixture of Experts setup, so only 2.3B parameters activate each run. The result: best-in-class efficiency, fast edge inference, and predictable log-linear scaling all in a 32GB, 2B-active MoE footprint. 🧵 — https://nitter.net/liquidai/status/2026301771539202269#m
→ View original post on X — @maximelabonne, 2026-02-24 14:36 UTC
-
Liquid AI Releases Largest LFM2-24B-A2B Model with Fast Inference
By
–
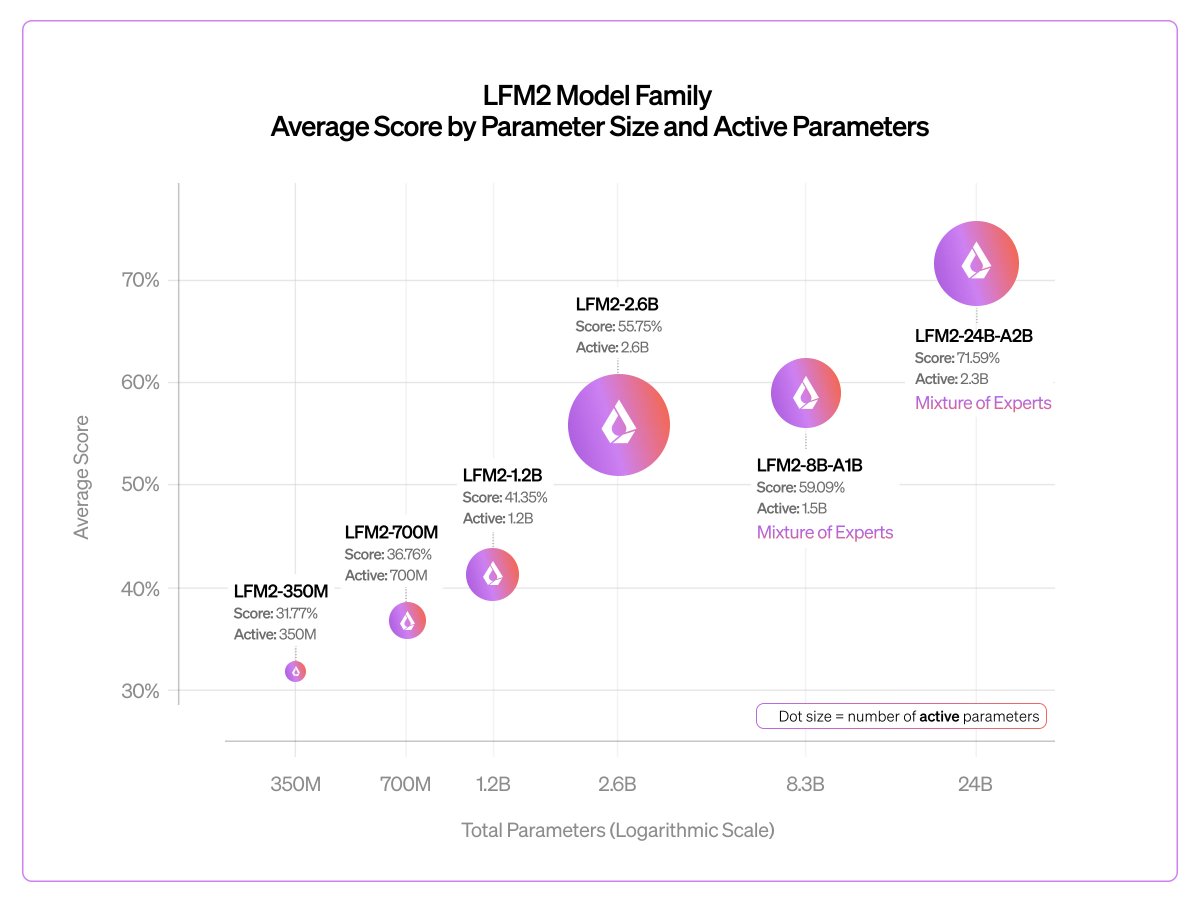
Early checkpoint of our biggest LFM2 model to date 🎉 It shows good scaling and extremely fast inference vs. gpt-oss-20b and Qwen3-30B-A3B We'll release an LFM2.5 version with more pre-training and RL in a few months Liquid AI (@liquidai) Today, we release our largest LFM2 model: LFM2-24B-A2B 🐘 > 24B total parameters > 2.3B active per token > Built on our hybrid, hardware-aware LFM2 architecture It combines LFM2’s fast, memory-efficient design with a Mixture of Experts setup, so only 2.3B parameters activate each run. The result: best-in-class efficiency, fast edge inference, and predictable log-linear scaling all in a 32GB, 2B-active MoE footprint. 🧵 — https://nitter.net/liquidai/status/2026301771539202269#m
→ View original post on X — @maximelabonne, 2026-02-24 14:31 UTC
-
Three Common Mistakes When Using Claude AI
By
–
LES 3 ERREURS QUI VOUS TRAHISSENT Erreur 1 : Utiliser Claude sans personnalisation
Prompt générique → Résultat générique Erreur 2 : Accepter la première version
Claude améliore souvent trop. Demandez-lui de se retenir. Erreur 3 : Ne pas relire après correction
Même avec les