nice followup from Ankit: https://
x.com/ankitxg/status
/2036487355981234377?s=20
… and @TheNoahHein : https://
x.com/TheNoahHein/st
atus/2037573208707137639
… and https://
molochinations.substack.com/p/no-more-code
-reviews-lights-out-codebases?triedRedirect=true
… it is coming!
LLMS
-
AI Automation Eliminating Code Reviews and Developer Workflows
By
–
-
AI Models Master SwiftUI Development Without Xcode
By
–
I've been vibe coding SwiftUI menu bar apps for my new Mac, turns out Claude Opus 4.6 and GPT-5.4 are both competent at Swift programming, no need to even open Xcode!
-

4 Essential Books on AI LLMs and Generative Intelligence
By
–
Explore 4 amazing books on AI, LLMs, Gen AI by @AltoValentina v/ @PacktDataML AI Agents in Practice: https://
amzn.to/4p98LYl Practical Generative AI with ChatGPT: https://
amzn.to/4oXSXHI Building LLM-Powered Applications: https://
amzn.to/4iNimjQ Modern Gen AI with ChatGPT -

Boost Coding Productivity with GitHub Copilot and ChatGPT
By
–
Supercharged Coding with #GenAI — From vibe coding to best practices using GitHub Copilot, ChatGPT, and OpenAI: https://
amzn.to/3VBH2Su v/ @PacktDataML 𝓚𝓮𝔂 𝓕𝓮𝓪𝓽𝓾𝓻𝓮𝓼: Discover how GitHub Copilot, ChatGPT, and the OpenAI API can boost your coding productivity Push -

DRIFT Framework: Dual-Model Approach for Long Document Processing
By
–
Tired of LLMs losing context on super long documents? Researchers from Shanghai AI Lab, Fudan, & Tongji Universities unveil DRIFT! Their new framework uses a clever dual-model approach: one AI finds and compresses relevant facts into "implicit fact tokens" — query-specific
-
Agent 4 Content Challenge Winner: Dari.fyi for Central Asia Diaspora
By
–
Week 1 winner of the Agent 4 Content Challenge:
— Replit ⠕ (@Replit) 27 mars 2026
Rahim Siddiq 🎉
Built: https://t.co/S8aozLfvQh Duolingo for the Central Asia diaspora https://t.co/eemfRd7r0Z pic.twitter.com/QodIKVNI11Week 1 winner of the Agent 4 Content Challenge: Rahim Siddiq Built: http://
Dari.fyi Duolingo for the Central Asia diaspora -
Why I Shill Droid 24/7: Eight Major Accomplishments Today
By
–
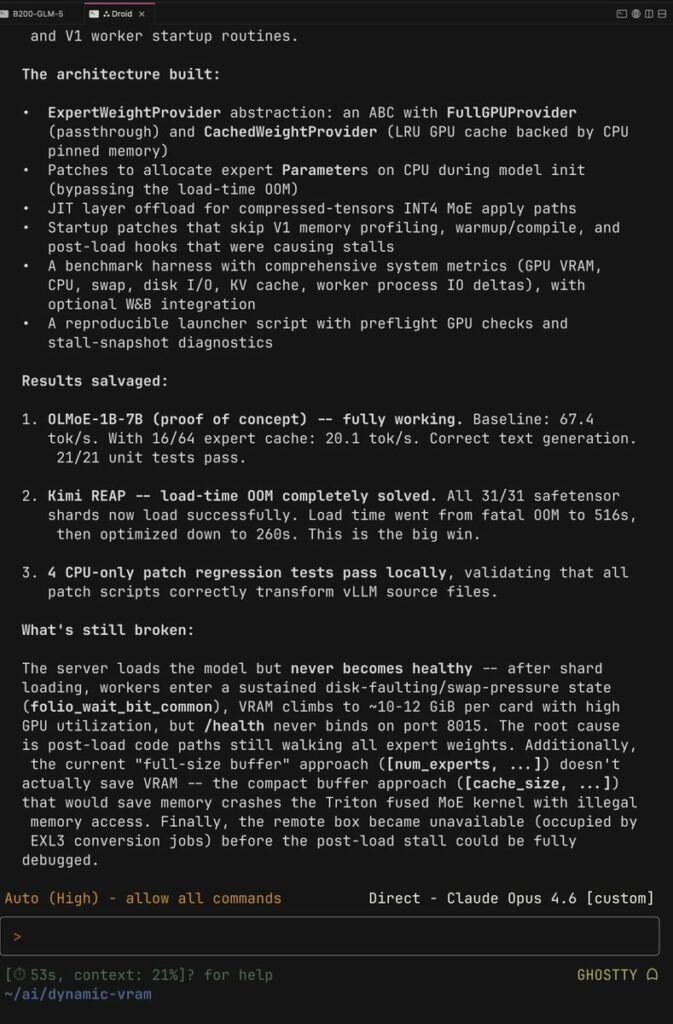
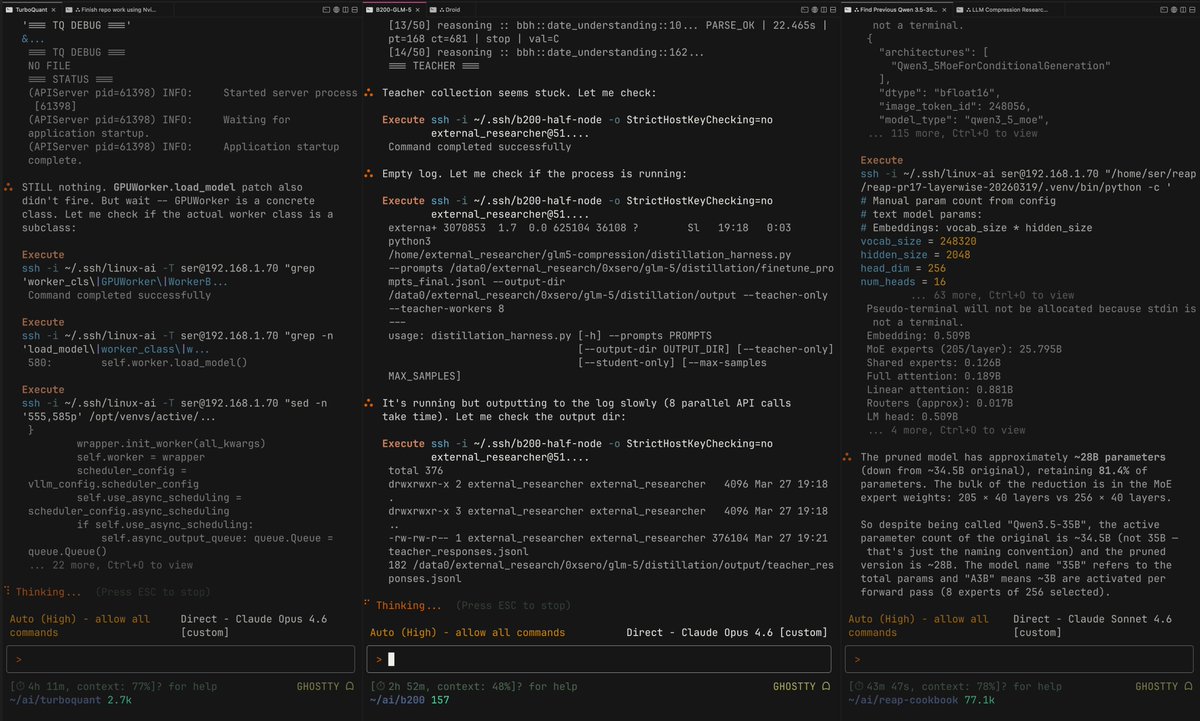
Here's why I shill Droid 24/7 ———- Today Droid single-handedly: 1. Published a REAP of GLM-5 in FP8, there's a reason no one else has done it DSA is still very new: huggingface.co/0xSero/GLM-5-… 2. Found and Fixed an upstream issue with VLLM + DSA + Hopper where GLM-5's kv-cache would need to recompute and spend 20x the time needed, fixed. 3. Created multiple working quantisations on it's own, it tried exl3 and autoround but both failed so resorted to GGUF (autoround 3 bits doesn't work on ampere) huggingface.co/0xSero/GLM-5-… 4. Implemented github.com/0xSero/turboquant within 24 hours of the research paper coming out, tested it across 5090s, 3090s, H100s, and B200s 5. Has been distilling larger models into LoRA to help me test arxiv.org/abs/2505.21835 and it got an 80% prune to be semi-coherent again. 6. Helped my find research papers, clean up slop with the human-writing skill. 7. Got BYOK working with Anthropic, ZAI, Kimi, MiniMax, OpenAI working in Cursor github.com/0xSero/factory-cu… 8. Helped me Implement blog.comfy.org/p/dynamic-vra… 's dynamic loading, only works on a tiny model, but still. ——- I only have to check in on it every 30-45 minutes (I am talking all 8 of my sessions) the thing will run for 16 hours with like 0 prep All this while I am mostly focused on my actual job and tweeting 24/7 Keep in mind each one of these experiments is running on a different server, with different constraints, like I don't understand how I can get such good results here. ——— I love novelty. Which is why I jump around and talking about all these different tools. I have used all of these harnesses and messed around with every feature. I keep coming back to this, and I keep shilling it because I sincerely wish others get to experience this.
→ View original post on X — @nathanlands, 2026-03-27 19:36 UTC
-

Claude’s Secret Aristotle Mode Revealed
By
–
BREAKING: Claude has a secret mode called "Aristotle First Principles Deconstructor." It strips any complex problem down to its fundamental truths, eliminates every assumption you didn't know you were making, and rebuilds the solution from zero. Aristotle invented this
-
SlopCodeBench: New Evaluation for Iterative Code Generation Quality
By
–
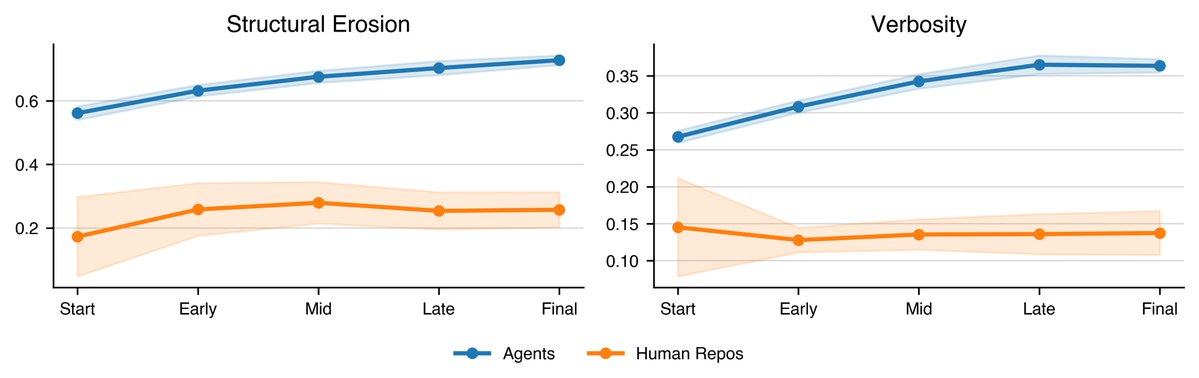
Congrats on the release 🚀 Proud to support research like this that moves the needle on evals and real-world agent performance. Gabe Orlanski (@GOrlanski) We found that agents generate progressively worse code with each iteration. Real developers do not. SlopCodeBench is the only eval that faithfully measures quality degradation on iterative, long-horizon coding tasks. arxiv.org/abs/2603.24755 scbench.ai 🧵 — https://nitter.net/GOrlanski/status/2037560777356238881#m
→ View original post on X — @snorkelai, 2026-03-27 18:57 UTC
-
Running Ollama with 1.58-bit Quantization
By
–
Or/and are running Ollama with a 1.58-bit quantization