AI Dynamics

Global AI News Aggregator

About

LLMS

  • AI Competitiveness: Internal Use, Industrialization, Model Control

    My takeaway is simple: The next 2 to 3 years will reward companies that do 3 things well: → use AI internally, so leadership understands it firsthand → build with a clear path from pilot to industrialization → take control of their own models, data, and evaluation strategy That is how AI stops being a demo and starts becoming a competitive moat. And now the tools are here: Mistral AI Forge makes model customization accessible, powered by NVIDIA infrastructure, while the NEMO Tron coalition is building an open ecosystem to democratize AI development. Watch more NVIDIA GTC replays at nvda.ws/45K2sCw

    → View original post on X — @ronald_vanloon, 2026-04-07 10:00 UTC

  • Open Models as Strategic Advantage for Enterprise AI Differentiation

    The second big insight, open and custom models are becoming a strategic advantage, not just a technical preference. Why? → More control over your AI stack → Less vendor lock-in → Better fit for regulated industries → More value from your own enterprise data and IP General models are strong generalists. But real differentiation comes when you make AI an expert in your domain, your workflows, your business. That’s exactly where the market is heading: With Mistral AI Forge, enterprises can build and fine-tune their own models, while NVIDIA’s NEMO Tron coalition is accelerating open innovation across models, datasets, and tooling.

    → View original post on X — @ronald_vanloon, 2026-04-07 10:00 UTC

  • AI as Software Development: From POC to Production Success

    The shift happening right now is bigger than "which model should we use?" AI is becoming a new way of building software. That means leaders need to think in terms of: → test cases → evaluation frameworks → feedback loops → continuous optimization If you cannot define success, you cannot move from POC to production. That is why so many pilots stall. At the same time, the foundation is changing: Mistral AI’s Forge platform now allows enterprises to customize models end-to-end with their own data, while NVIDIA’s NEMO Tron coalition is pushing open AI development with shared models, datasets, and training tools.

    → View original post on X — @ronald_vanloon, 2026-04-07 10:00 UTC

  • LLMs Generate New Knowledge Video Refutation Guide

    Si en algún momento necesitas refutar eso de "los LLMs no pueden generar nuevo conocimiento" este es el vídeo que debes compartir.

    → View original post on X — @dotcsv

  • Anthropic Surpasses OpenAI in Revenue Run Rate at $30B

    Holy: Anthropic just passed OpenAI in revenue run rate. OpenAI is at roughly $25B. Anthropic just crossed $30B. Sixteen months ago Anthropic was doing $1B. Two months ago Anthropic was doing $9B. They *are* the exponential. Anthropic (@AnthropicAI) Our run-rate revenue has surpassed $30 billion, up from $9 billion at the end of 2025, as demand for Claude continues to accelerate. This partnership gives us the compute to keep pace. Read more: anthropic.com/news/google-br… — https://nitter.net/AnthropicAI/status/2041275563466502560#m

    → View original post on X — @kimmonismus, 2026-04-07 08:33 UTC

  • LLMs as CPUs: Understanding Agent Harness Infrastructure
    LLMs as CPUs: Understanding Agent Harness Infrastructure

    A raw LLM is just like a CPU without OS. It can compute. But it can't do anything useful on its own. This analogy is the clearest way I've found to understand what an agent harness actually does. Here's the mapping: • 𝗖𝗣𝗨 → 𝗟𝗟𝗠 (model weights). The raw compute engine. Powerful, but useless without infrastructure around it. • 𝗥𝗔𝗠 → 𝗖𝗼𝗻𝘁𝗲𝘅𝘁 𝘄𝗶𝗻𝗱𝗼𝘄. Fast, always available, but limited. When it fills up, you start losing things. • 𝗛𝗮𝗿𝗱 𝗱𝗶𝘀𝗸 → 𝗩𝗲𝗰𝘁𝗼𝗿 𝗗𝗕 / 𝗹𝗼𝗻𝗴-𝘁𝗲𝗿𝗺 𝘀𝘁𝗼𝗿𝗮𝗴𝗲. Large capacity, but slow to access. You retrieve from it, not compute in it. • 𝗗𝗲𝘃𝗶𝗰𝗲 𝗱𝗿𝗶𝘃𝗲𝗿𝘀 → 𝗧𝗼𝗼𝗹 𝗶𝗻𝘁𝗲𝗴𝗿𝗮𝘁𝗶𝗼𝗻𝘀. The interfaces that let the model interact with the outside world. Code execution, web search, file I/O. • 𝗢𝗽𝗲𝗿𝗮𝘁𝗶𝗻𝗴 𝘀𝘆𝘀𝘁𝗲𝗺 → 𝗔𝗴𝗲𝗻𝘁 𝗵𝗮𝗿𝗻𝗲𝘀𝘀. This is the key layer. It manages everything: which tools to call, what fits in memory, when to retrieve, how to recover from errors, and when to stop. And then there's the 𝗮𝗽𝗽𝗹𝗶𝗰𝗮𝘁𝗶𝗼𝗻 layer. That's the "agent" itself. Not a piece of software you install, but emergent behavior that arises when the OS does its job well. This is why two products using the exact same model can perform completely differently. LangChain changed only their harness infrastructure (same model, same weights) and jumped from outside the top 30 to rank 5 on TerminalBench 2.0. The model didn't improve. The operating system around it did. The article below is a deep dive on agent harness engineering, covering the orchestration loop, tools, memory, context management, and everything else that transforms a stateless LLM into a capable agent. Akshay 🚀 (@akshay_pachaar) x.com/i/article/204073208484… — https://nitter.net/akshay_pachaar/status/2041146899319971922#m

    → View original post on X — @akshay_pachaar, 2026-04-07 08:30 UTC

  • Using MiniMax M2.7 for OpenClaw task execution

    I’ve been playing with MiniMax M2.7 for a while as a model for my OpenClaw, and it can easily execute much more complex tasks than before. “A cyberpunk Game of Life” one-shot Looking forward to testing the open-source version now!

    → View original post on X — @testingcatalog

  • Shayan Rais shares Claude code best practice repository open-source

    A massive thank you to @shanraisshan for building this and sharing it open-source with our dev community 🙌 Let's help it gain the visibility it deserves, be sure to give the repo a ⭐! → github.com/shanraisshan/clau… github.com/shanraisshan/clau…

    → View original post on X — @datachaz, 2026-04-07 07:56 UTC

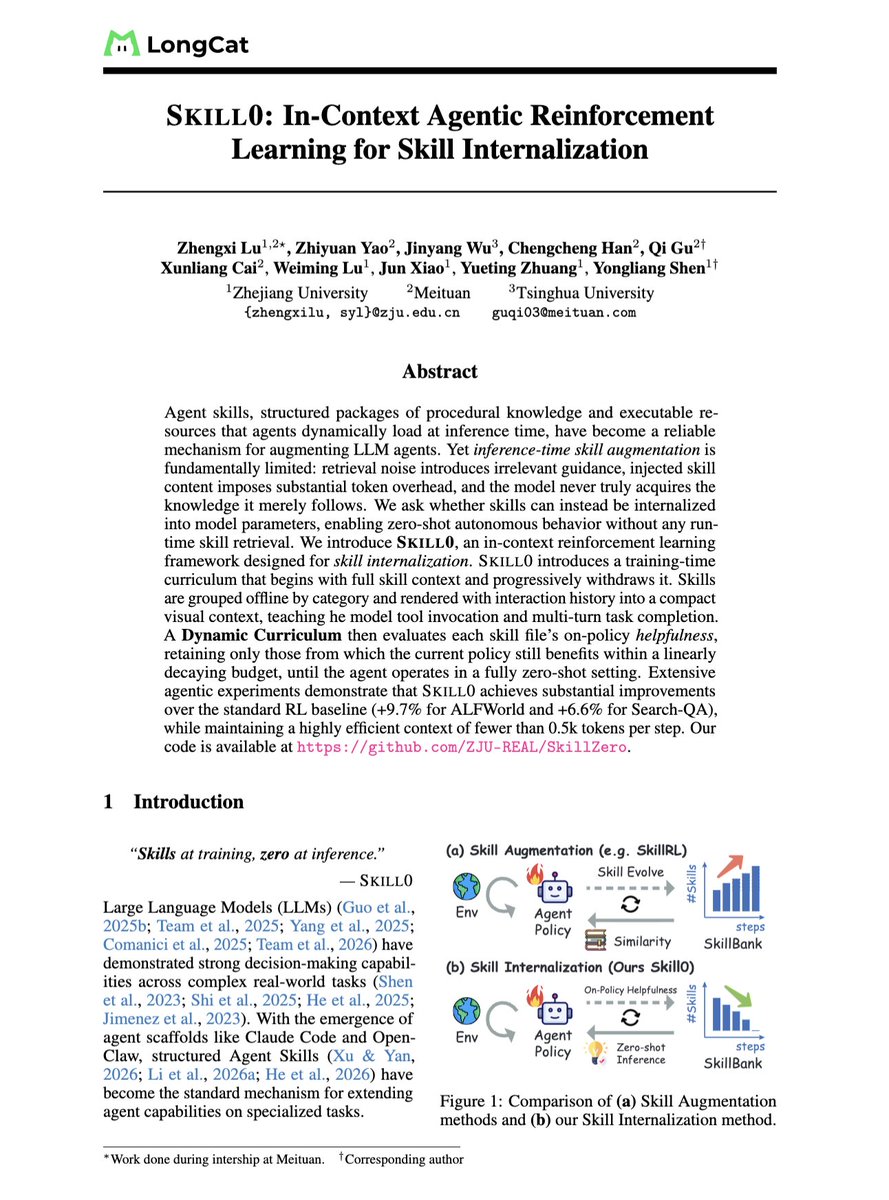
  • SKILL0: Training Agents to Internalize Skills Without Context
    SKILL0: Training Agents to Internalize Skills Without Context

    “SKILL0: In-Context Agentic Reinforcement Learning for Skill Internalization” Most agent systems use skills like cheat sheets. It retrieves them at runtime, pastes them into the prompt, and hopes the model follows them. This paper suggests why not train the model with those skills, then slowly remove them until it can do the job from memory? So the agent starts training with skill guidance, but over time the helpful skills are taken away. And instead of depending on instructions forever, it learns to absorb them into its own parameters. This turns skills from something the model reads into something the model actually knows, and the result is a more efficient agent with much less context overhead, but still better performance. Empirically, SKILL0 beats strong RL baselines on ALFWorld and Search-QA while using under 0.5k tokens per step.

    → View original post on X — @askalphaxiv, 2026-04-07 07:37 UTC

  • Zo Computer: The Closest Thing to Real-Life AGI Implementation

    @zocomputer is the closest thing to real-life agi. (AGI is going to be the harness + any advanced model.) Zo is @openclaw but it's on its own server and you are accessing it's personal environment. You can use @NousResearch's Hermes in Zo computer and Zo will do all the setup. https://hermes-trying with Zo. tinyurl.com/Zocomputer #keep4o #AGI

    → View original post on X — @scobleizer, 2026-04-07 06:34 UTC