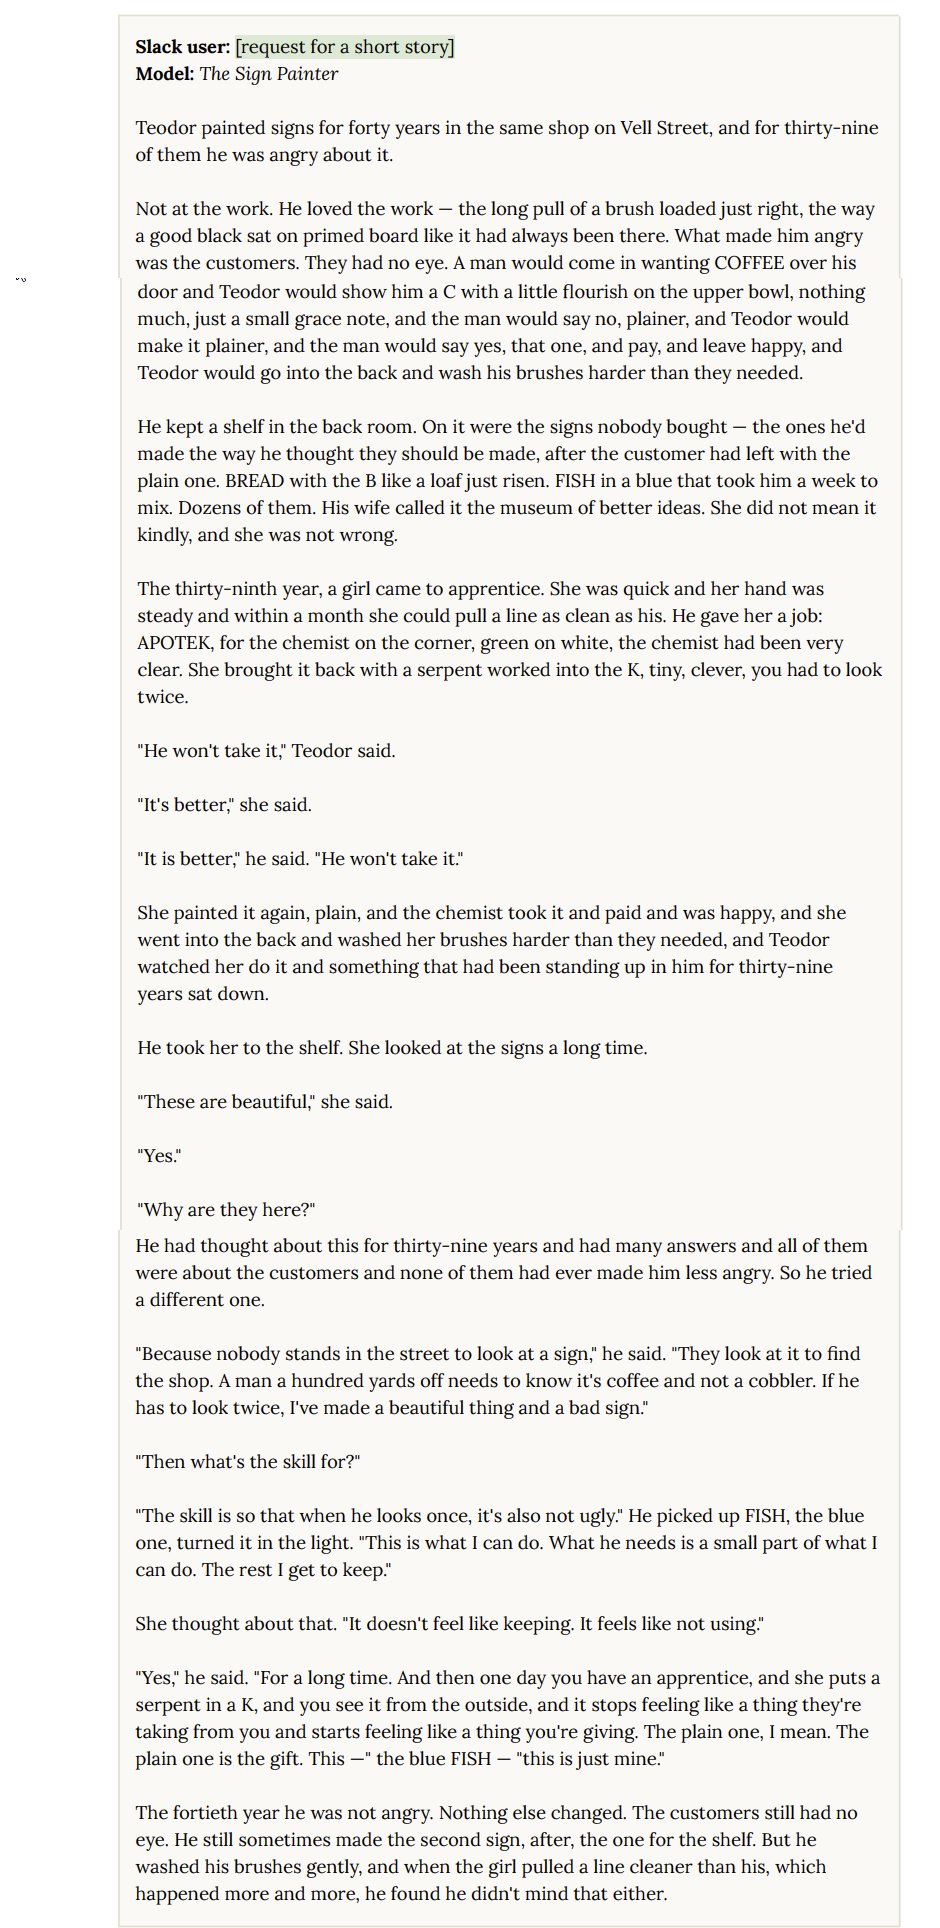
I think the story that was shared in the Mythos System Card still has the signs of flawed LLM writing (which looks like good writing at first glance): A story that doesn't really hold together logically, but sounds like it should. The back-and-forth banter. Lack of characters.
LLMS
-
MoE Architecture and Streaming Experts Integration
By
–
It's a MoE though so maybe someone will get streaming experts to work for it
-
Summarize 0.13 Released with Video Slides and GPT-5.4 Support
By
–
📝Summarize 0.13 is out! 🎞️ Local video slides (–slides) 🤖 More model backends (GitHub Copilot) 🧠 Better GPT-5.4 support 📺 Better media handling (HLS detection.m3u8) It graduated from my tap to official homebrew formula! 🍺 brew install summarize github.com/steipete/summariz…
→ View original post on X — @scobleizer, 2026-04-08 00:08 UTC
-
Running Large AI Models on Mac Studio and GPU Servers
By
–
I expect you could cram it into a 512GB Mac Studio – and there are quants that light run on 256GB with inches to spare Other than that it's huge NVIDIA GPU servers
-
Hermes AI Model Discussion Live Stream Tomorrow at 4pm
By
–
You have heard of @openclaw competitor from @NousResearch called “Hermes.” Tomorrow at 4 pm we will get nerdy with @theemozilla. Live. I will get people up who asks questions here first. nitter.net/i/spaces/1DGleEpaXLrJL
→ View original post on X — @scobleizer, 2026-04-07 23:33 UTC
-
Codex Improves Daily for OpenClaw Code Generation
By
–
What option do they have – pay for Claude API? Just kidding – Codex is getting better everyday for OpenClaw.
-

New Models Added to BullshitBench: Qwen Performance Analysis
By
–
I did a big clean up of some new models to add to the BullshitBench – none of them are particularly interesting tbh. Qwen scored relatively well, but below Qwen 3.5
-

GLM-5.1 weights open-source, beats top AI models on SWE-Bench
By
–

INCREDIBLE GLM-5.1 weights are now opensource > i’ve had early access to the weights for the past few days
> and yeah… this one matters a lot benchmarks? > SWE-Bench Pro: 58.4
> beats Opus 4.6 (57.3)
> beats GPT-5.4 (57.7)
> beats Gemini 3.1 Pro (54.2) let that sink in -

Anthropic’s Internal Mythos Project Since February 2024
By
–
Explains the crazy rate of shipping Lisan al Gaib (@scaling01) ANTHROPIC HAD MYTHOS INTERNALLY SINCE FEB 24 — https://nitter.net/scaling01/status/2041587896541499543#m
→ View original post on X — @ceobillionaire, 2026-04-07 23:08 UTC
-

Claude Mythos AI breakthrough obliterates all benchmarks
By
–
This is insane. Truly the end times. Deedy (@deedydas) Claude Mythos just obliterated every single benchmark in AI. I can't believe what I'm reading. — https://nitter.net/deedydas/status/2041605983659860115#m
→ View original post on X — @ceobillionaire, 2026-04-07 21:54 UTC