I’m old school VS coder supercharged with Claudio.
LLMS
-

LLMs Fairness and Consistency in AI Model Evaluation
By
–
Are LLMs truly fair and consistent when judging other AI models? A collaborative team from Peking University, NUS, Institute of Science Tokyo, Nanjing University, Carnegie Mellon, Westlake, and Southeast University has the answer! They introduce TrustJudge, a probabilistic
-

Context length benchmarks up to 180k tokens
By
–
Ran some benchmarks on different context lengths all the way to 180k Findings below
-
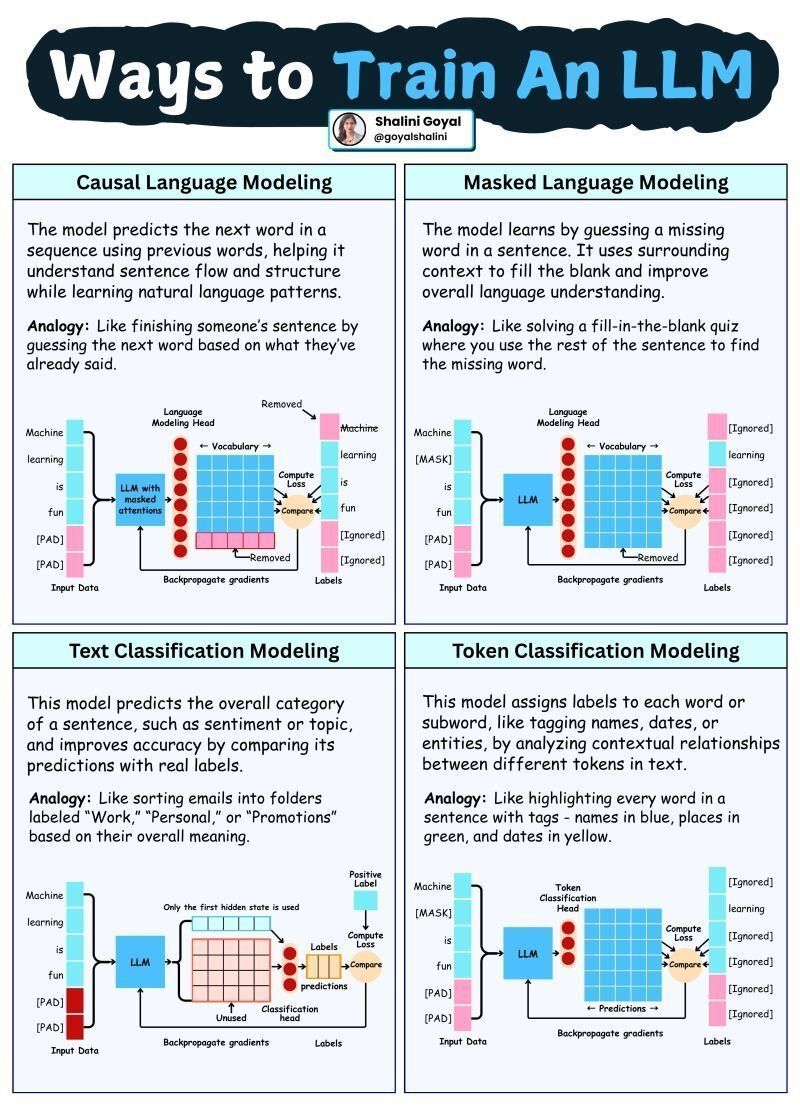
Ways to Train Large Language Models Effectively
By
–
Ways to Train an #LLM
by @goyalshaliniuk #GenAI #ArtificialIntelligence #MachineLearning #ML -

Exploring dense new format with tests in BF16, FP8, NVFP4 and TP scaling
By
–

it's very dense, a new format that I am playing with still need to test it in concurrency + try it in nvfp4 hopefully will be able to compare perplexity in bf16 / fp8 / nvfp4 as well as TP performance jumps from 2 -> 4 -> 8 nodes across all 3 formats most important thing
-

Anthropic Developing Coordinator Mode for Multi-Agent Delegation
By
–
Anthropic is working on a new Coordinator Mode, along with the ability to create custom agents directly from the desktop app. > "Delegate work across parallel agents." Will Coordinator Mode be similar to an upcoming Magic TODO list on Codex? h/t @M1Astra
-
Anthropic and OpenAI preparing desktop application updates
By
–
Both Anthropic and OpenAI are gearing up to release updates to their desktop apps already next week.
— 🚨 AI News | TestingCatalog (@testingcatalog) 13 avril 2026
Anthropic is finalizing its new Claude Code "epitaxy" experience with a power-user-friendly UI, Cowork-style layout, and the possibility to work on multiple repositories at once.… pic.twitter.com/Z9tfiP5Vy7Both Anthropic and OpenAI are gearing up to release updates to their desktop apps already next week. Anthropic is finalizing its new Claude Code "epitaxy" experience with a power-user-friendly UI, Cowork-style layout, and the possibility to work on multiple repositories at once.
-
AI Models Excel at Code Tasks Over Image Generation
By
–
Okay but this is actually way closer to what they’re good at (code) than image models would be
-
AI as Autocomplete, Not True Intelligence
By
–
AI doesn’t understand your question. It predicts which words are statistically likely to follow it. That’s not intelligence. That’s autocomplete with a PhD-sized training set.