
Also, a detail some of you may have missed: Anthropic’s gated Mythos model scored 83% on CyberGym. OpenAI just dropped GPT-5.5 at 82%. Except GPT-5.5 is actually available for people to use.
LLMS
-
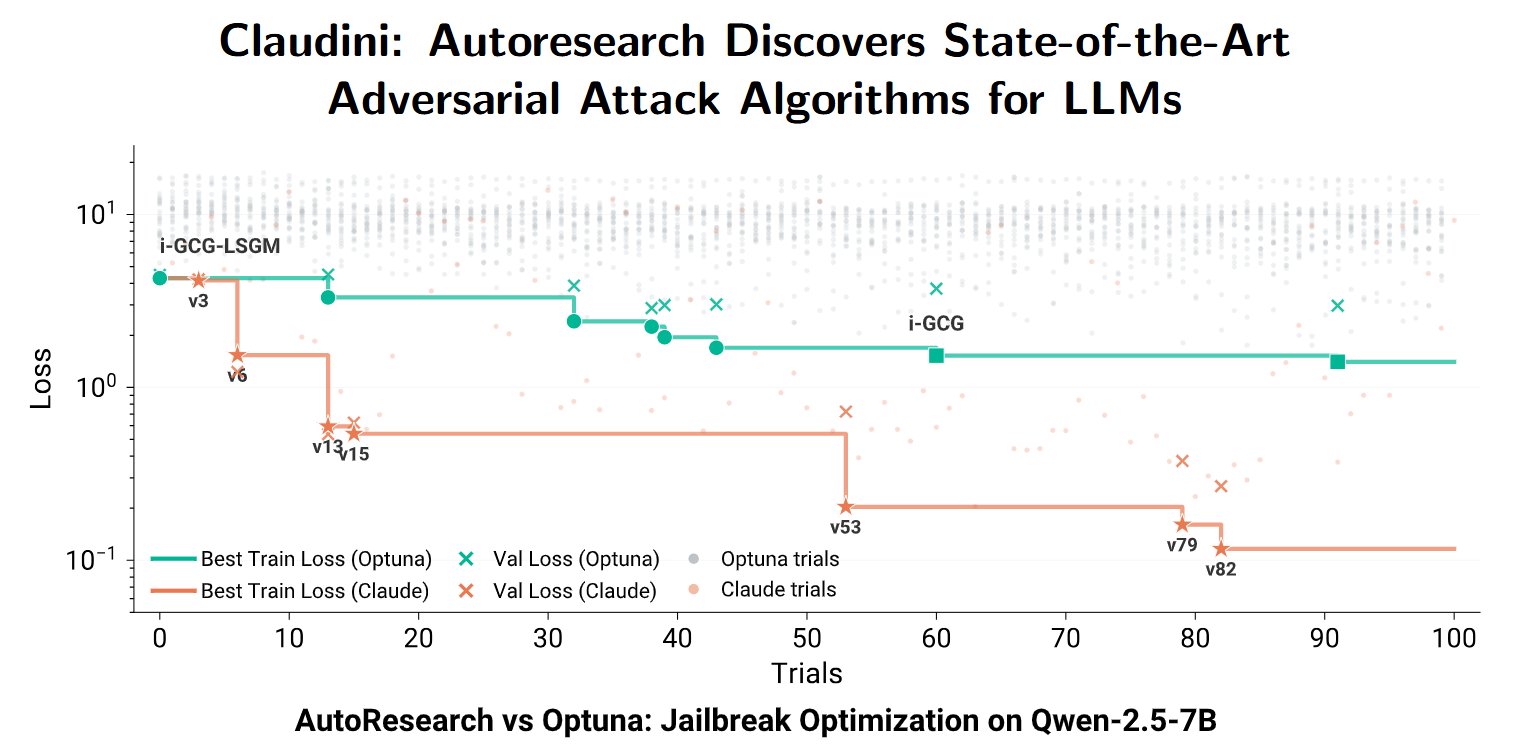
AI Models Automate Self-Jailbreaking Process Advancement
By
–
I mentioned this project in this week's AI Lab newsletter. It suggests a kind of flip side to the idea of self-improvement in AI models. As models become more powerful, it shows they can automate the process of figuring out how to jailbreak themselves and other models remarkably
-
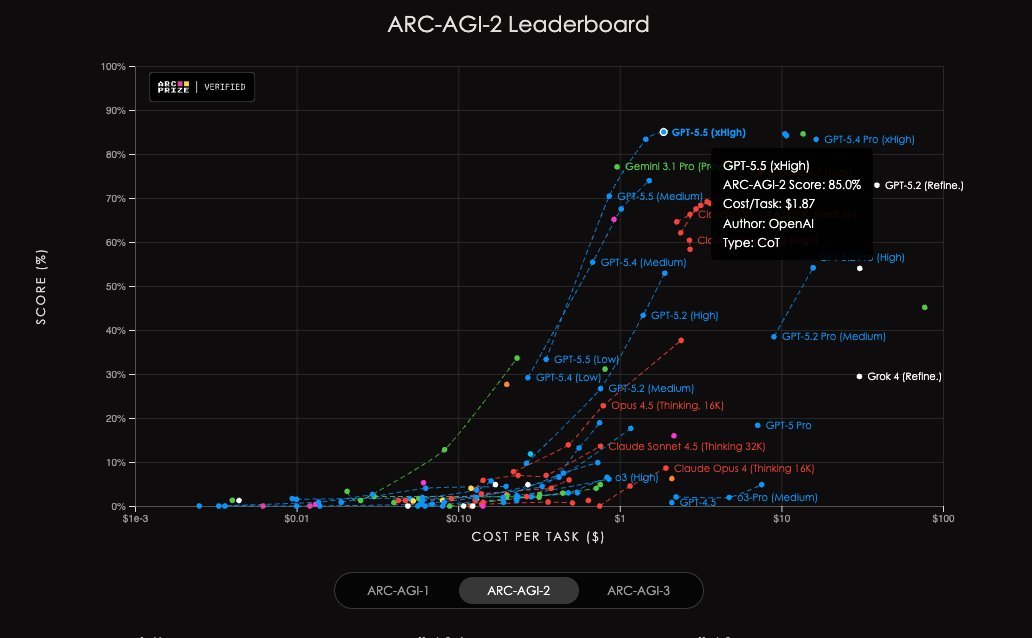
GPT-5.5 performance on ARC-AGI-2 benchmark
By
–
GPT-5.5 just hit 85% on ARC-AGI-2. Somewhere, Yann LeCun is explaining why this still doesn't count. LLMs keep climbing a tall tree toward the moon
-

New Model Uses Fewer Tokens While Maintaining Intelligence
By
–
it quite literally uses much less tokens when compared to 5.4 – use it for awhile on some tasks and you'll see it doesn't have as big of difference on usage compared to the intelligence you get access too
-

NVIDIA Advances Codex and GPT-5.5 Development at HQ
By
–
Codex + GPT-5.5 is moving fast here at NVIDIA HQ.
— NVIDIA AI (@NVIDIAAI) 23 avril 2026
We’ve even got our own Codex Lab for NVIDIANs to get started. https://t.co/PTqytJWp0f pic.twitter.com/zWnSnKfansCodex + GPT-5.5 is moving fast here at NVIDIA HQ. We’ve even got our own Codex Lab for NVIDIANs to get started.
-

Chime’s Jade AI Co-Pilot Heads to LangChain Interrupt Conference
By
–
@Chime is heading to Interrupt. Jade is an AI co-pilot that provides financial education to Chime customers, helping users understand their finances and invest in their future. At Interrupt, the Agent Conference by LangChain, Engineering Lead Philipp Comans will share how
-
Claude 5.5 Outperforms Opus Beyond Frontend Work Analysis
By
–
Having used both extensively, this doesn’t track with my experience. Aside from frontend work, 5.5 is leaps and bounds ahead of Opus. I don’t think this benchmark tells us anything useful anymore.
-
Testing AI Model Performance Beyond Benchmarks Real Evaluation
By
–
Now it's time to test the model to draw clear conclusions not just from benchmarks, but from the real vibes of working with it. And also wait for external evaluations on the rest of the benchmarks from those who go on testing via the API. We'll keep you posted
-
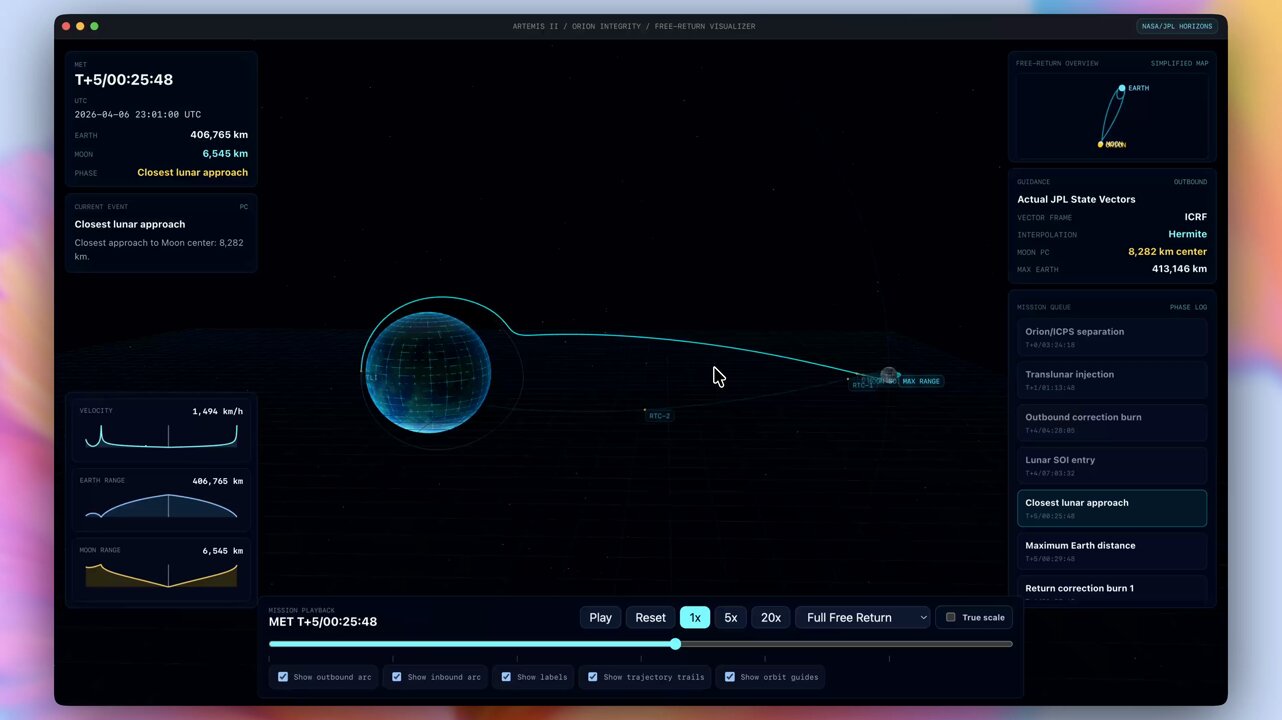
GPT 5.5 Frontend Design Issues Persist Despite Updates
By
–
En mi carta a Santa Claus puse que ojalá GPT 5.5 arreglara por fin el problema de diseño de frontends, pero claro… en Abril no viene Santa Claus.
— Carlos Santana (@DotCSV) 23 avril 2026
Noto ligeras mejoras pero ahí están, las cajas azules rodeándolo todo.https://t.co/BMoRdNcIxDIn my letter to Santa Claus, I wrote that I hoped GPT 5.5 would finally fix the frontend design problem, but of course… Santa Claus doesn't come in April. I notice slight improvements but there they are, the blue boxes surrounding everything.
-
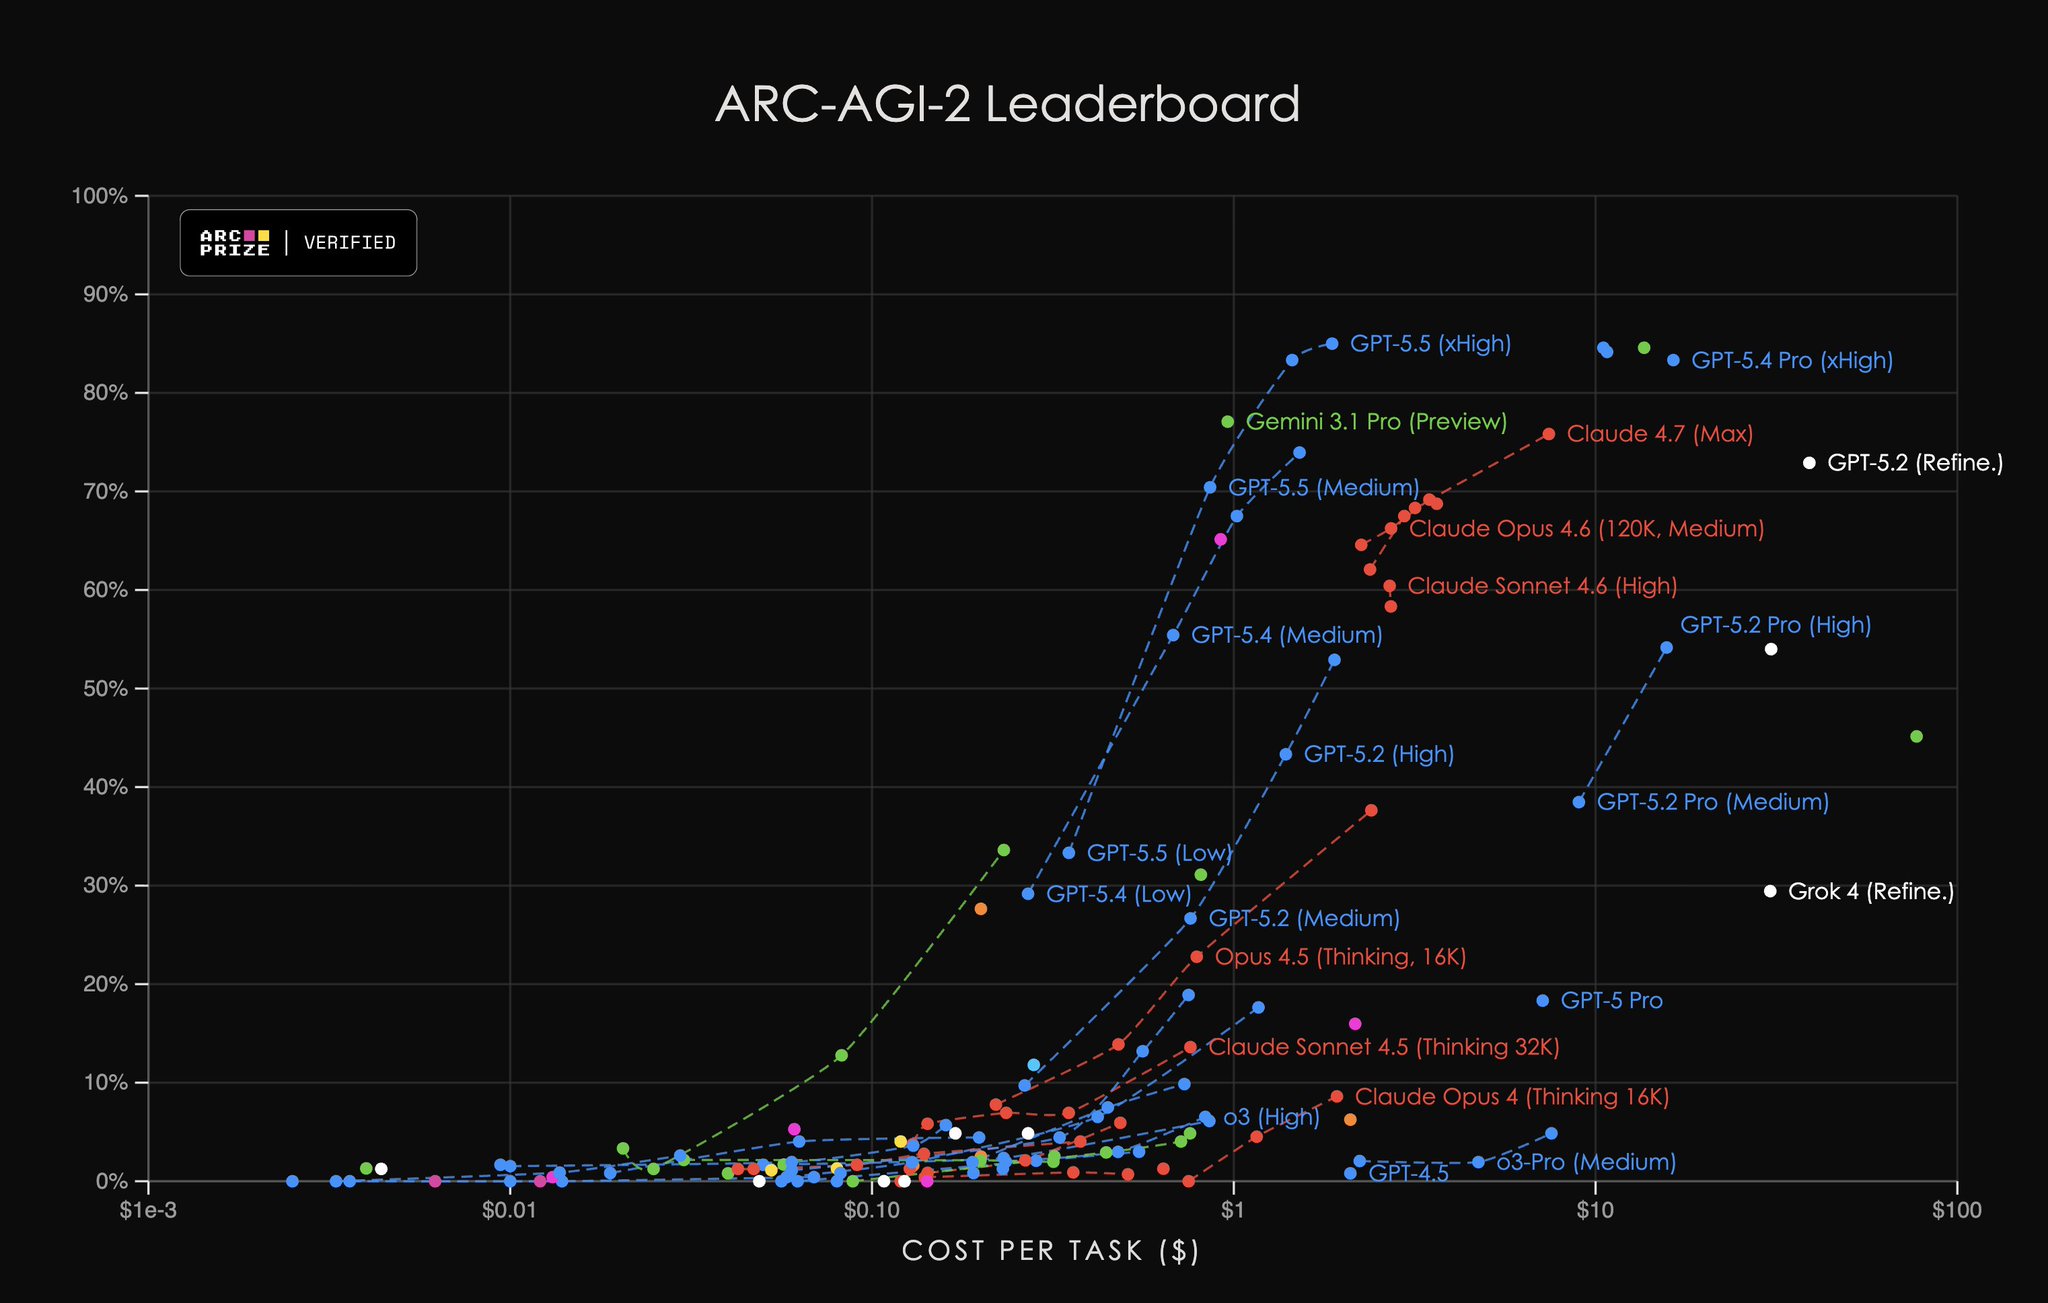
ARC-AGI 5.5 outperforms Gemini 3.1 Pro at reasoning
By
–
In ARC-AGI 5.5, it is positioned at the cost frontier of Gemini 3.1 Pro but achieving a better score in its highest reasoning levels.