GPT-5.5 Live with Every https://
x.com/i/broadcasts/1
AxRnaLmZYPxl
…
LLMS
-
GPT-5.5 Live Launch Announced by OpenAI
By
–
-
OpenAI’s Rapid GPT Release Pace Raises Marketing Concerns
By
–
I'm sure that GPT 5.5 by vibes will be an excellent model, just like its predecessor was. And hey, OpenAI's pace of progress is excellent if we think about the fact that the previous one came out a month and a half ago! BUT FOR GOODNESS' SAKE OPENAI STOP WITH THE OVER-THE-TOP
-
GPT-5.5 executes plans without hesitation
By
–
many models write a great plan and then get scared of it.@OpenAI's new GPT-5.5 just does the thing.
— Dan Shipper 📧 (@danshipper) 23 avril 2026
here's what changed 👇 pic.twitter.com/Z79GUK7Opdmany models write a great plan and then get scared of it. @OpenAI
's new GPT-5.5 just does the thing. here's what changed -
New Model Costs 20% More Than GPT 5.4 Despite Token Efficiency
By
–
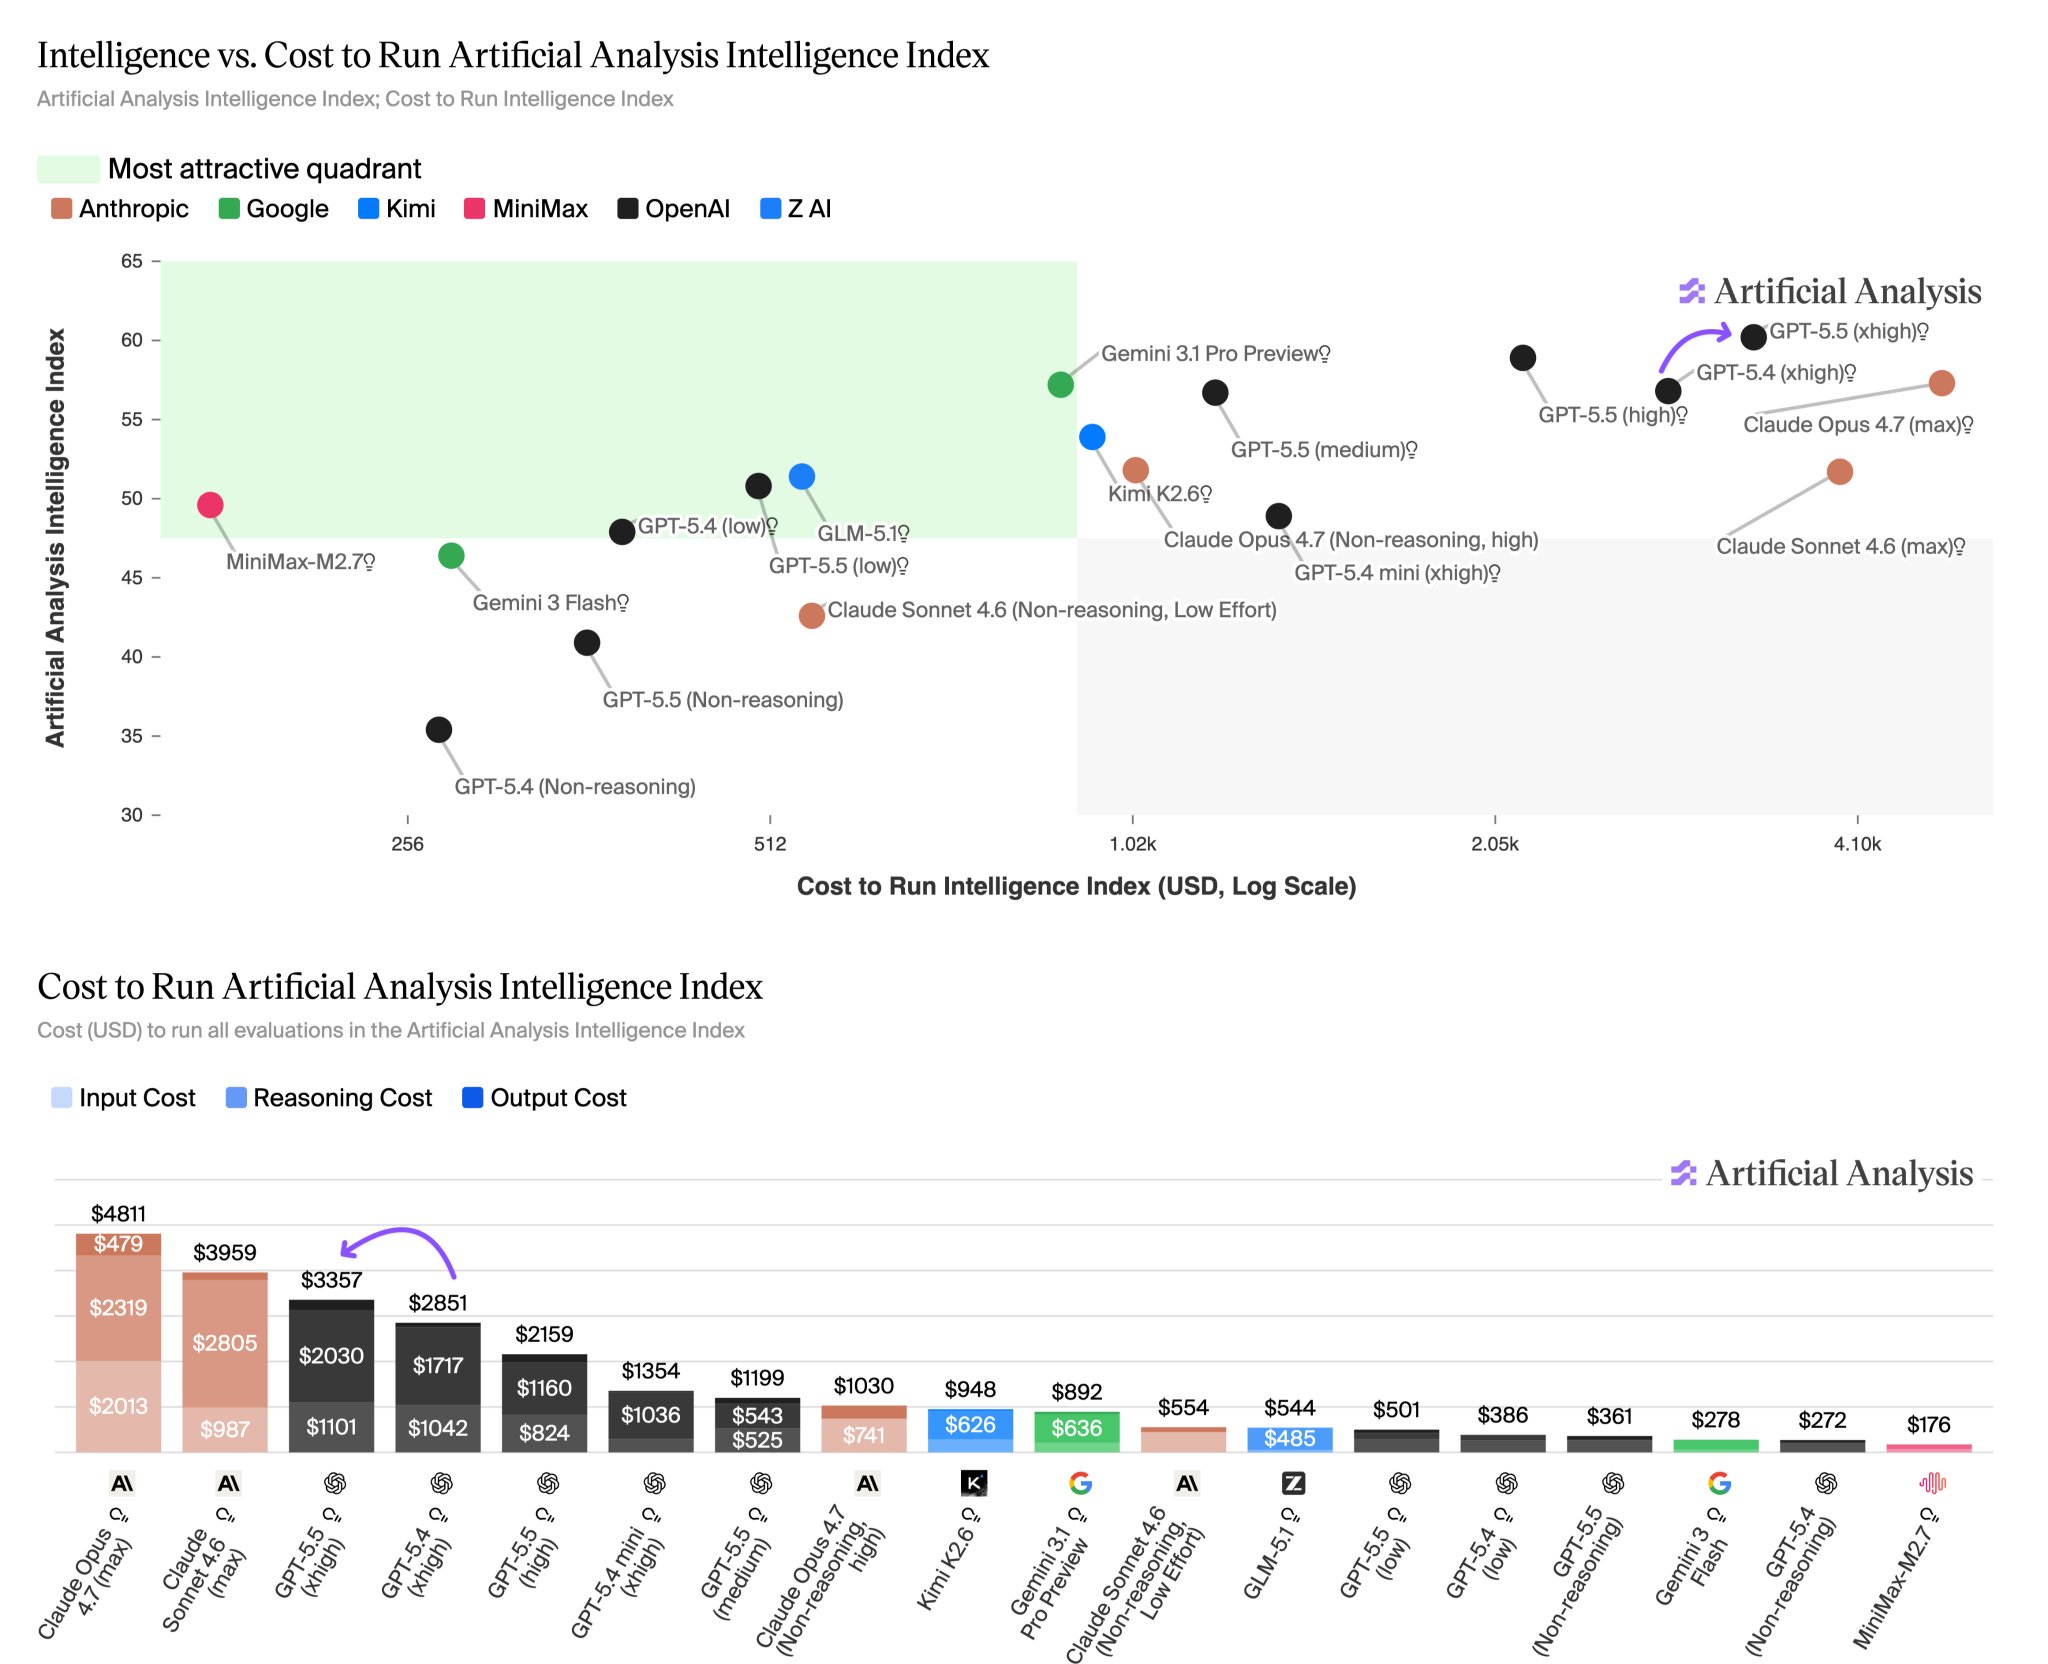
Because the price of the model doubles (!!) its predecessor, buuuut this is something that's mitigated by the more efficient use of tokens But in combination, as a result, it leaves us with a model that's 20% more expensive than GPT 5.4 xhigh when it comes to evaluating
-
Codex and GPT-5.5: Combining Models for Shipping Work
By
–
Codex + GPT-5.5 is an incredible combo.
— Romain Huet (@romainhuet) 23 avril 2026
A great model needs a great space to work. Codex gives GPT-5.5 the context, tools, artifacts, browser, and review loop to turn reasoning into work you can ship. https://t.co/9sAnYFBDdlCodex + GPT-5.5 is an incredible combo. A great model needs a great space to work. Codex gives GPT-5.5 the context, tools, artifacts, browser, and review loop to turn reasoning into work you can ship.
-

User claims AI model ‘Claude’ was intentionally degraded
By
–

I can't believe we were right Claude was dumbified on March 4, just when we noticed!
-
GPT 5.5 Base64 Encoding Security Capabilities
By
–
Il doit sûrement être bon en gestion de hack en base64 le #gpt5.5
-
New AI Model Shows Better Benchmarks Despite Higher Costs
By
–
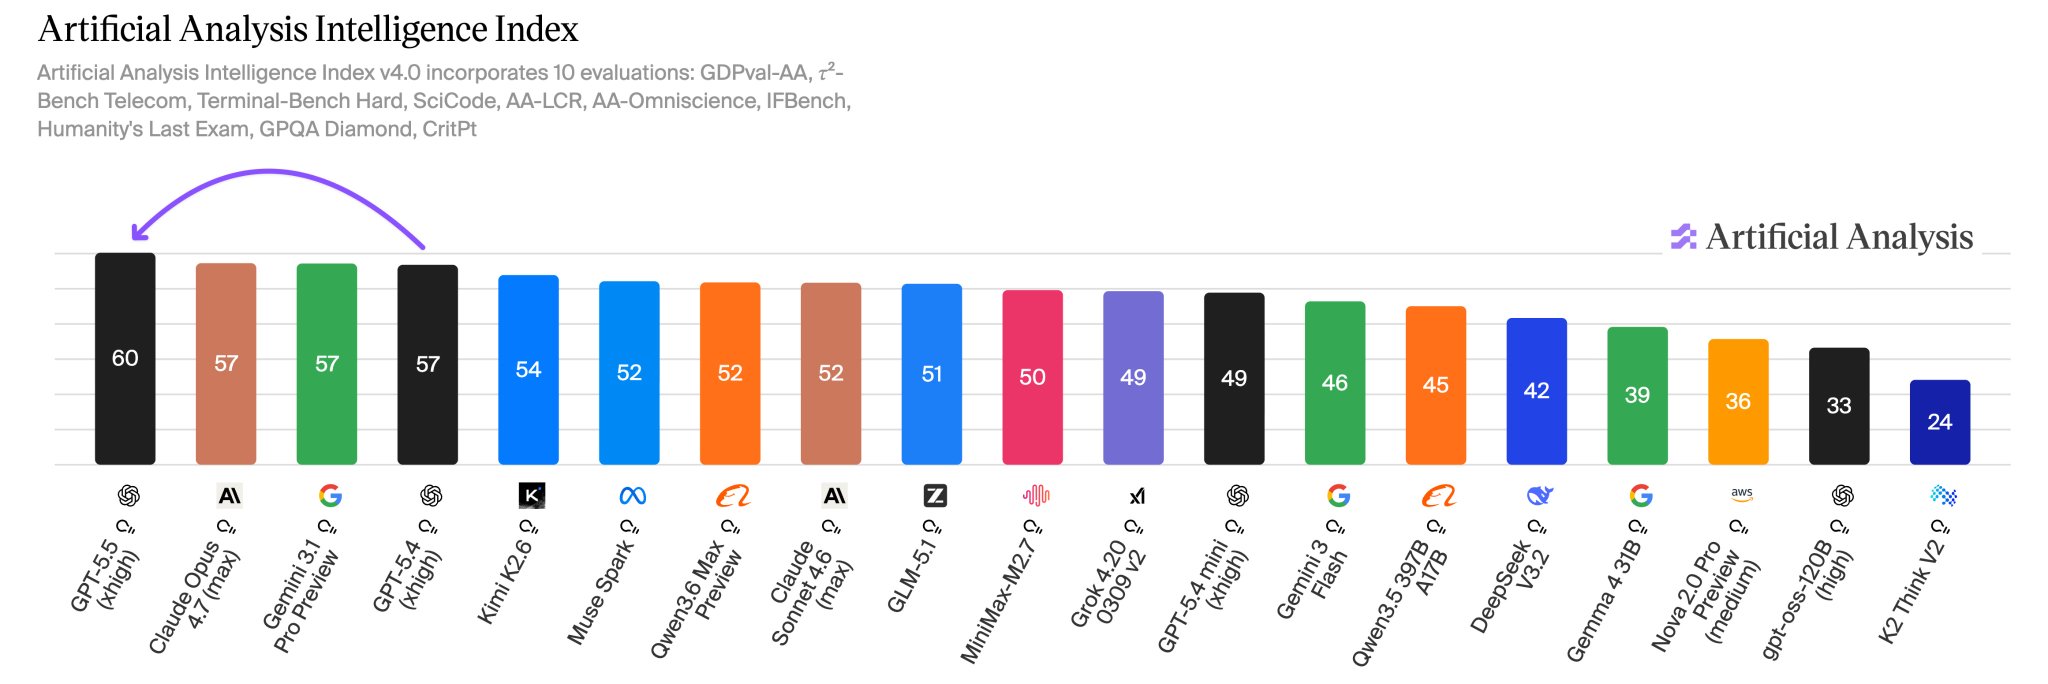
What is clear is that it is a better model in terms of benchmarks and based on the feedback I've been seeing for days from insiders I trust who have been testing it. Bring it on. That said, it is also a more expensive model.
-
AI Models Reaching Excellence in Code, Struggling Elsewhere
By
–
It's not "meh", and it's not plateauing. I think we're just reaching a point where, for the things the models were already good at (i.e. code), they are becoming absolutely excellent, and it's hard to tell the difference between releases. And for things that they're not yet good
-
GPT-5.5 Achieves State-of-the-Art Agentic Coding and Tool Use Results
By
–
GPT-5.5 reaches SOTA results across key evals for agentic coding, computer use, tool use, advanced math, and cybersecurity: 82.7% on Terminal-Bench 2.0 and 78.7% on OSWorld-Verified. Rolling out in Codex and ChatGPT today. API coming soon! Full post: