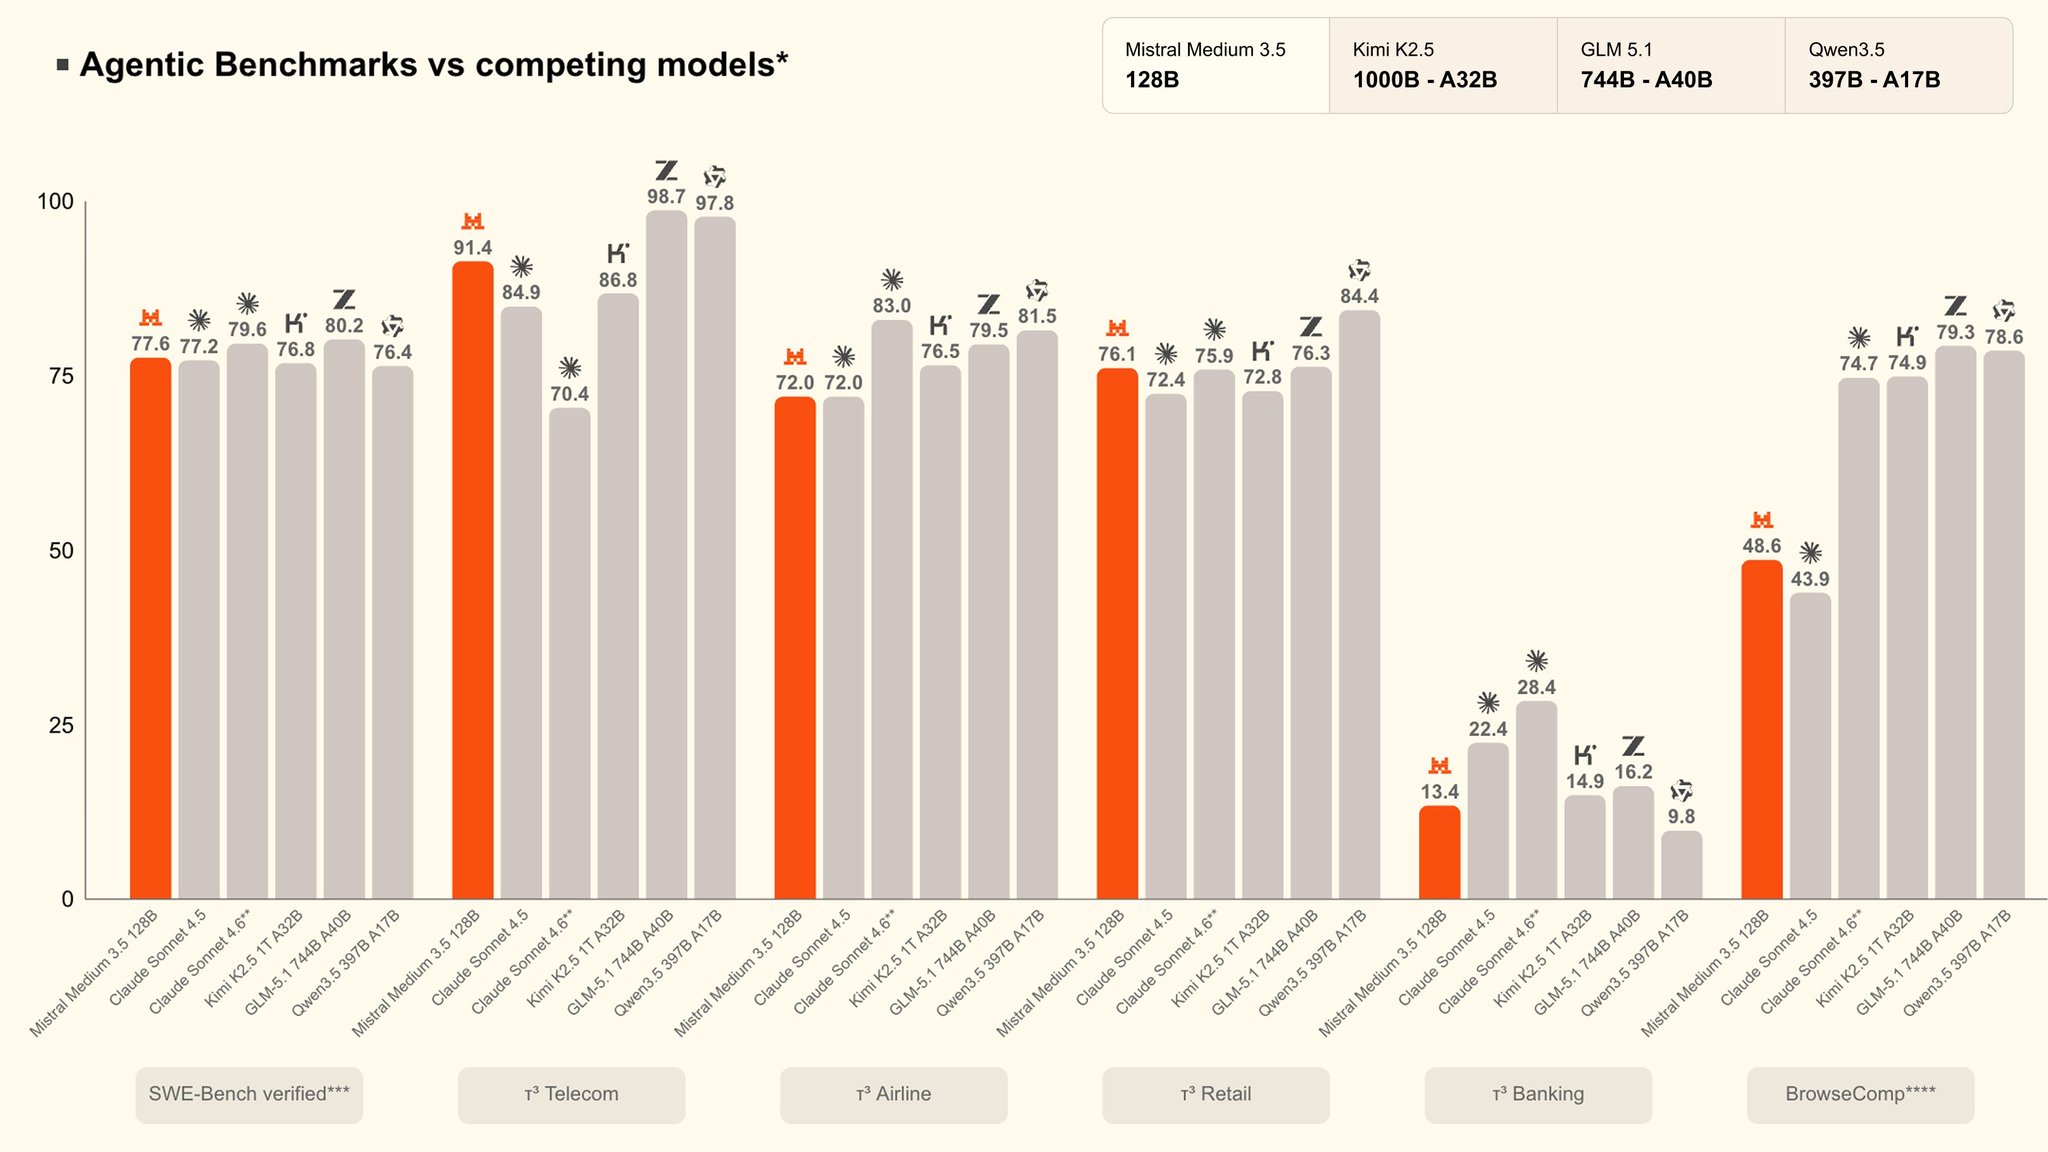
Not sure if this is a good look since most of the competing models were released BEFORE Tau3-Bench
LLMS
-
AI-Native Founders Rise: Insights from Replit Leaders
By
–
— Replit ⠕ (@Replit) 29 avril 2026
At @Replit they’re empowering a new wave of million-dollar founders. Cofounders @amasad and @HayaOdeh joined us at @southpkcommons to discuss: – The rise of AI-native founders – New AI models and their capabilities – And why most founders quit too early Full Minus One
-

ChatGPT Integrates Model Switcher Into Prompt Field
By
–
ChatGPT's model switcher is now built directly into the Prompt field
-
NVIDIA Leads AI Benchmarks with Open Models Across Domains
By
–
📈 NVIDIA tops AI leaderboards and benchmarks with open models driven by extreme co-design across compute, networking, memory, storage, and software.
— NVIDIA (@nvidia) 29 avril 2026
This includes models for biology, AI physics, agentic AI, physical AI, robotics, and autonomous vehicles.
By being vertically… pic.twitter.com/ybjuWm637CNVIDIA tops AI leaderboards and benchmarks with open models driven by extreme co-design across compute, networking, memory, storage, and software. This includes models for biology, AI physics, agentic AI, physical AI, robotics, and autonomous vehicles. By being vertically
-

LangChain Now Hiring Positions Available
By
–
We can confirm #11 is hiring. https://
langchain.com/careers -

Introspection Adapters Enable Language Models Self-Report Misalignment
By
–
In new Anthropic Fellows research, we discuss “introspection adapters": a tool that allows language models to self-report behaviors they've learned during training—including potential misalignment.
-
DeepSeek v4 Demonstrates SOTA Long Context Efficiency Without Benchmarking
By
–
IMO DeepSeek v4 demonstrated utter confidence and competence by not benchmaxxing, not focusing on some BS final run cost, not even spending inference-optimal compute. just showed up, demonstrated SOTA long context efficiency techniques (CSA, HCA, mHC, flash at 8% cost of pro,
-
Two models with 1M context, near equal, model just 20% of result
By
–
And this is the part nobody is talking about:
Both models ship with 1M-token context. Both are within a few points of each other on most tasks. The gap between them is smaller than the gap between a good prompt and a bad one. The model is maybe 20% of your result. Your -
Professional comparison of Claude and GPT-5.5 capabilities
By
–
The definitive ranking doesn't exist. Here's what does: → Complex reasoning, code review, multi-file refactoring: Claude Opus 4.7
→ Agentic execution, terminal workflows, tool orchestration: GPT-5.5
→ Interactive speed: Claude
→ Cost at scale: GPT-5.5 The professionals -
Claude wins 7 tests but GPT-5.5 leads in OpenAI’s table
By
–
Tom's Guide ran 7 head-to-head tests. Claude won all 7. OpenAI's own benchmark table shows GPT-5.5 leading on 14 categories. But that table includes tests where only OpenAI published a Claude score. Anthropic's own numbers tell a different story on several of those. The