This is the first >1:30 video I’ve seen someone make with Sora Extend. Very cool! https://
x.com/O_on_X/status/
/O_on_X/status/1975770528247128292
…
INNOVATION
-
First 1:30+ video created with Sora Extend
By
–
-

AI Gym Buddy Monitors Form and Counts Reps
By
–
Check out this AI gym buddy that monitors your form and counts reps. Server/client setup ready for gym deployment without any extra gear. Making workouts safer with edge AI Demo: https://
eu1.hubs.ly/H0nGsLD0 -

Direct Text-to-Video Generation Coming Soon
By
–
Temporary workaround. Direct video generation from text coming soon.
-
Midjourney Releases V7: First New AI Image Model in Year
By
–
Midjourney releases V7, its first new AI image model in nearly a year #AI #AIio #AIInnovation #ML #DataScience #Futureofwork @timnitgebru @oriolvinyalsml @ceobillionaire @soumithchintala @waitin4agi_ @sallyeaves @bernardmarr
-
EU Commission launches AI adoption strategies for industry and science
By
–
Commission launches two strategies to speed up AI uptake in European industry and science https://
ec.europa.eu/commission/pre
sscorner/detail/en/ip_25_2299
…
#digitaleu #AI #industry #science #Innovation #technology @DigitalEU @ArturHabant @elaniazito @BetaMoroney @Fabriziobustama @mvollmer1 @mikeflache @enilev @AkwyZ -

Jamba Reasoning 3B: Exceptional Performance on Extended Contexts
By
–
3/5 Where most other tiny models choke at context lengths above 8K, Jamba Reasoning 3B stays steady, with a consistent 30-40 tokens/second on an M3 MacBook Pro, regardless of context size. This is up to an order of magnitude faster than other on-device models.
-
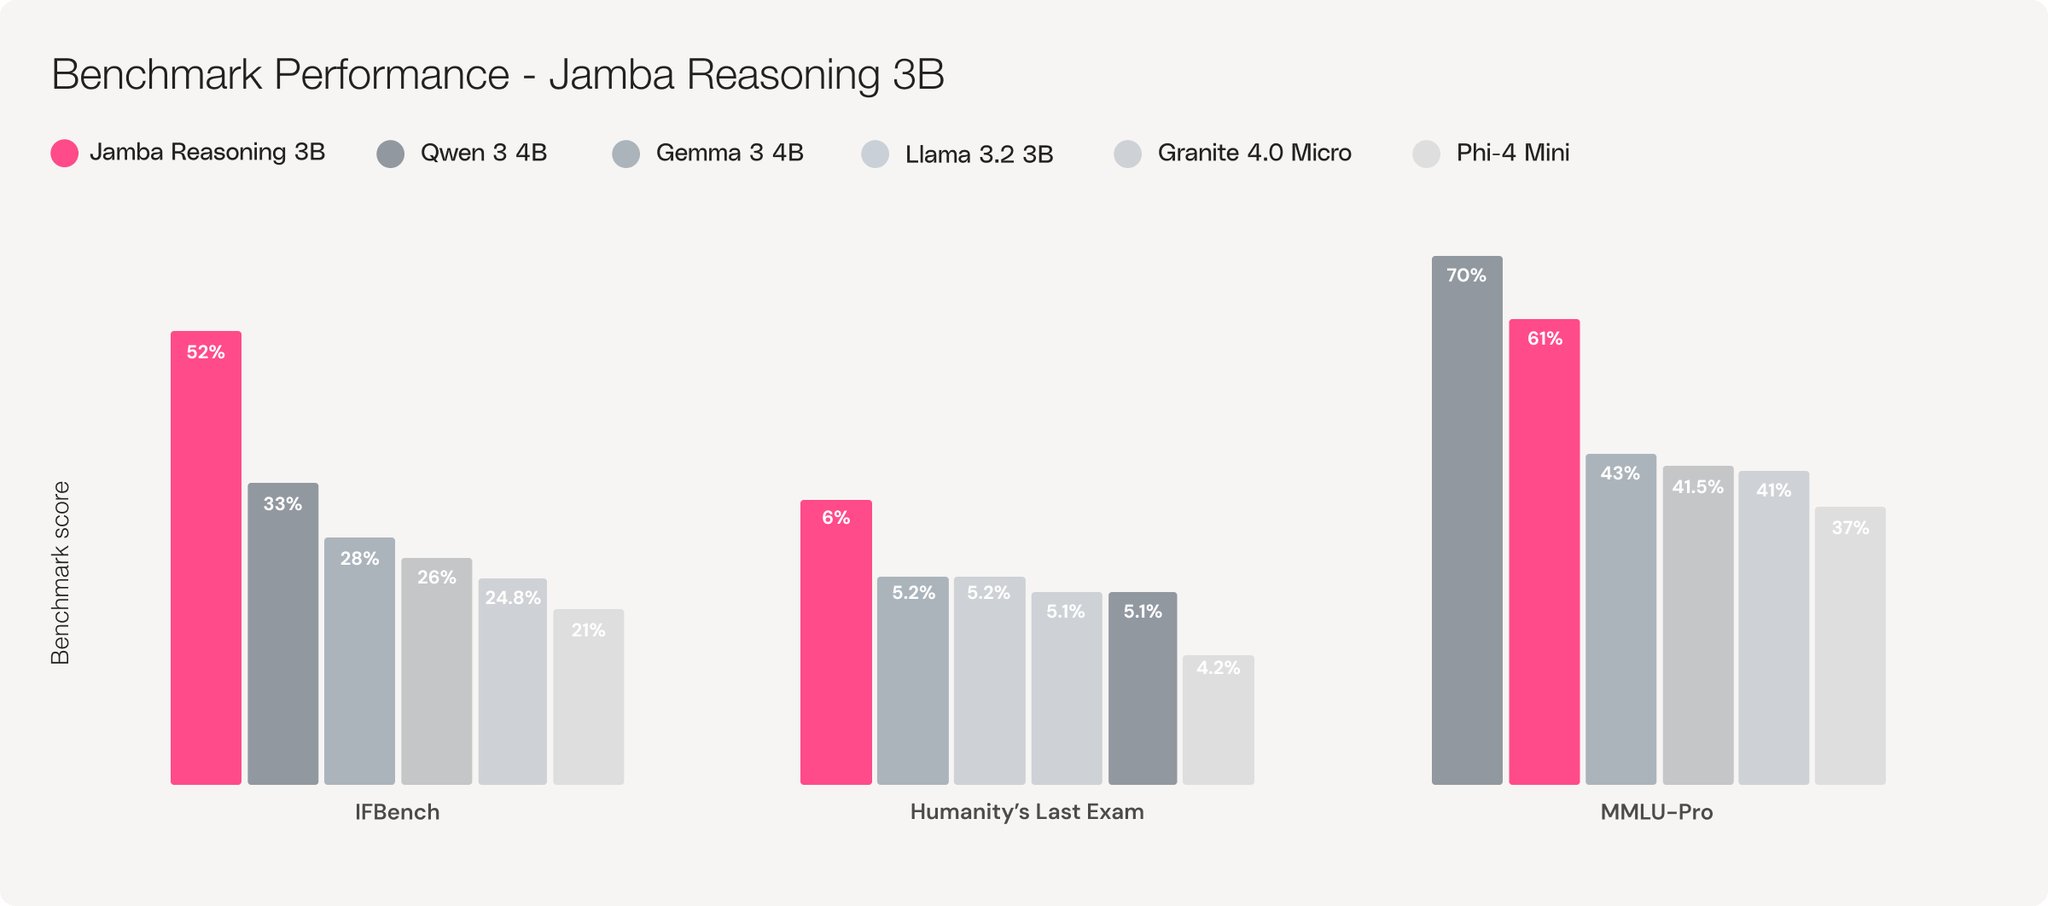
Jamba Reasoning 3B Excels in Knowledge and Instruction-Following
By
–
2/5 Jamba Reasoning 3B excels in general knowledge benchmarks (MMLU-Pro, HLE) and instruction-following (IFBench), making it reliable and performant
-

Jamba Reasoning 3B: Hybrid SSM-Transformer Apache 2.0 Release
By
–
1/5 Releasing Jamba Reasoning 3B under Apache 2.0: Hybrid SSM-Transformer architecture that tops accuracy & speed across record context lengths. e.g. 3-5X faster than Llama 3.2 3B and Qwen3 4B at 32K tokens.