
Something very special is happening on this island. We're building AGI, the first frontier lab in Asia/SG, and also gathering the best people around in one team. Welcome @zzlccc to join the AGI enjoyers club! Looking forward to cooking with you! Zichen Liu (@zzlccc) Thrilled to share that I’ve joined @GoogleDeepMind to work on Gemini post-training! I feel incredibly fortunate to be cooking on this sunny island under @YiTayML's leadership, within @quocleix's broader organization. Looking forward to enjoying RL research and pushing the frontiers of Gemini alongside such a brilliant team! — https://nitter.net/zzlccc/status/2020869034045231602#m
INNOVATION
-

Startup Growth: Leverage Compounds, Hiring Doesn’t
By
–
When workload grows, you have 3 options:
— Ronald Schmelzer (@rschmelzer) 9 février 2026
1. Add people
2. Add hours
3. Add leverage
Most founders only know the first two.
But leverage COMPOUNDS. Hiring doesn't.
🔗 https://t.co/3Dh093DfsZ#Startups #MicroTeams pic.twitter.com/X303iLO0QXWhen workload grows, you have 3 options: 1. Add people
2. Add hours
3. Add leverage Most founders only know the first two. But leverage COMPOUNDS. Hiring doesn't. https://
scalebrate.com/podcast/hiring
-without-hiring
… #Startups #MicroTeams -
AI Project Leadership: Rev 2026 Conference for Impact Drivers
By
–
Most AI projects stay small. Learn to lead yours so it stands out.
— Domino Data Lab (@DominoDataLab) 9 février 2026
Rev 2026: Where leaders come to drive impact.
3 cities. Limited seats. Registration is open.
Secure your spot now: https://t.co/36BWatcjs0#Rev26 pic.twitter.com/HXECqKOpZgMost AI projects stay small. Learn to lead yours so it stands out.
Rev 2026: Where leaders come to drive impact.
3 cities. Limited seats. Registration is open. Secure your spot now: https://
domino.buzz/4qXjwNX
#Rev26 -

AI Telecom Strategy: 5G Networks and Autonomous Systems at MWC26
By
–
Join us at #MWC26 for insights into the next era of AI for telecom. Learn about: Strategy: The AI Value Equation AI-Native Networks: 5G Revenue Sovereign AI Autonomous Networks Explore sessions: https://
nvda.ws/45OFiLl -
AI-Supported Breast Cancer Screening Spots More Cancers Earlier
By
–
'A second set of eyes': AI-supported breast cancer screening spots more cancers earlier, landmark trial finds https://
livescience.com/health/cancer/
a-second-set-of-eyes-ai-supported-breast-cancer-screening-spots-more-cancers-earlier-landmark-trial-finds
… #AI #HealthcareAI #TechNews #CancerResearch #cancer -

Axelera AI and AIKO Enable Onboard Intelligence in Space
By
–
Axelera AI partners with AIKO to push onboard intelligence in space. Their flight-proven AI software plus our efficient processors enable real-time data processing and autonomous decisions in orbit. Blog: https://
eu1.hubs.ly/H0rzLdF0 #SpaceAI #EdgeAI -

Crypto entrepreneurs launch ai.com with Super Bowl, OpenAI wrapper
By
–

>Crypto guys (no AI background) buy ai.com for $70M
>Burn $10M on a Super Bowl ad
>Slogan: "Accelerating the arrival of AGI"
>Turns out it's just a thin OpenAI wrapper
>Ask for your credit card right away just to "claim a handle"
>Website looks like a cheap vibecoded mess
>Crashed instantly with a 504 Gateway Time-out. This looks like the absolute peak of the AI bubble. [Translated from EN to English]→ View original post on X — @reza_zadeh, 2026-02-09 10:11 UTC
-
Optimizing vLLM Deployments: Workload Tuning and Metrics Scaling
By
–
5/5 The takeaway: know your workload, tune your config, scale on metrics that reflect client experience. These lessons apply beyond GRPO – any high-throughput vLLM deployment facing variable load can benefit. Full blog post:
-
Autoscaling by Queue Depth: Beyond GPU Utilization Metrics
By
–
4/5 The horizontal fix: autoscale on queue depth, not GPU utilization 100% GPU = efficiency, not overload. We use vllm:num_requests_waiting to trigger scale-up when the deployment can't keep up with incoming requests.
-
Auto-Tune vLLM Config Doubles Throughput and Halves Latency
By
–
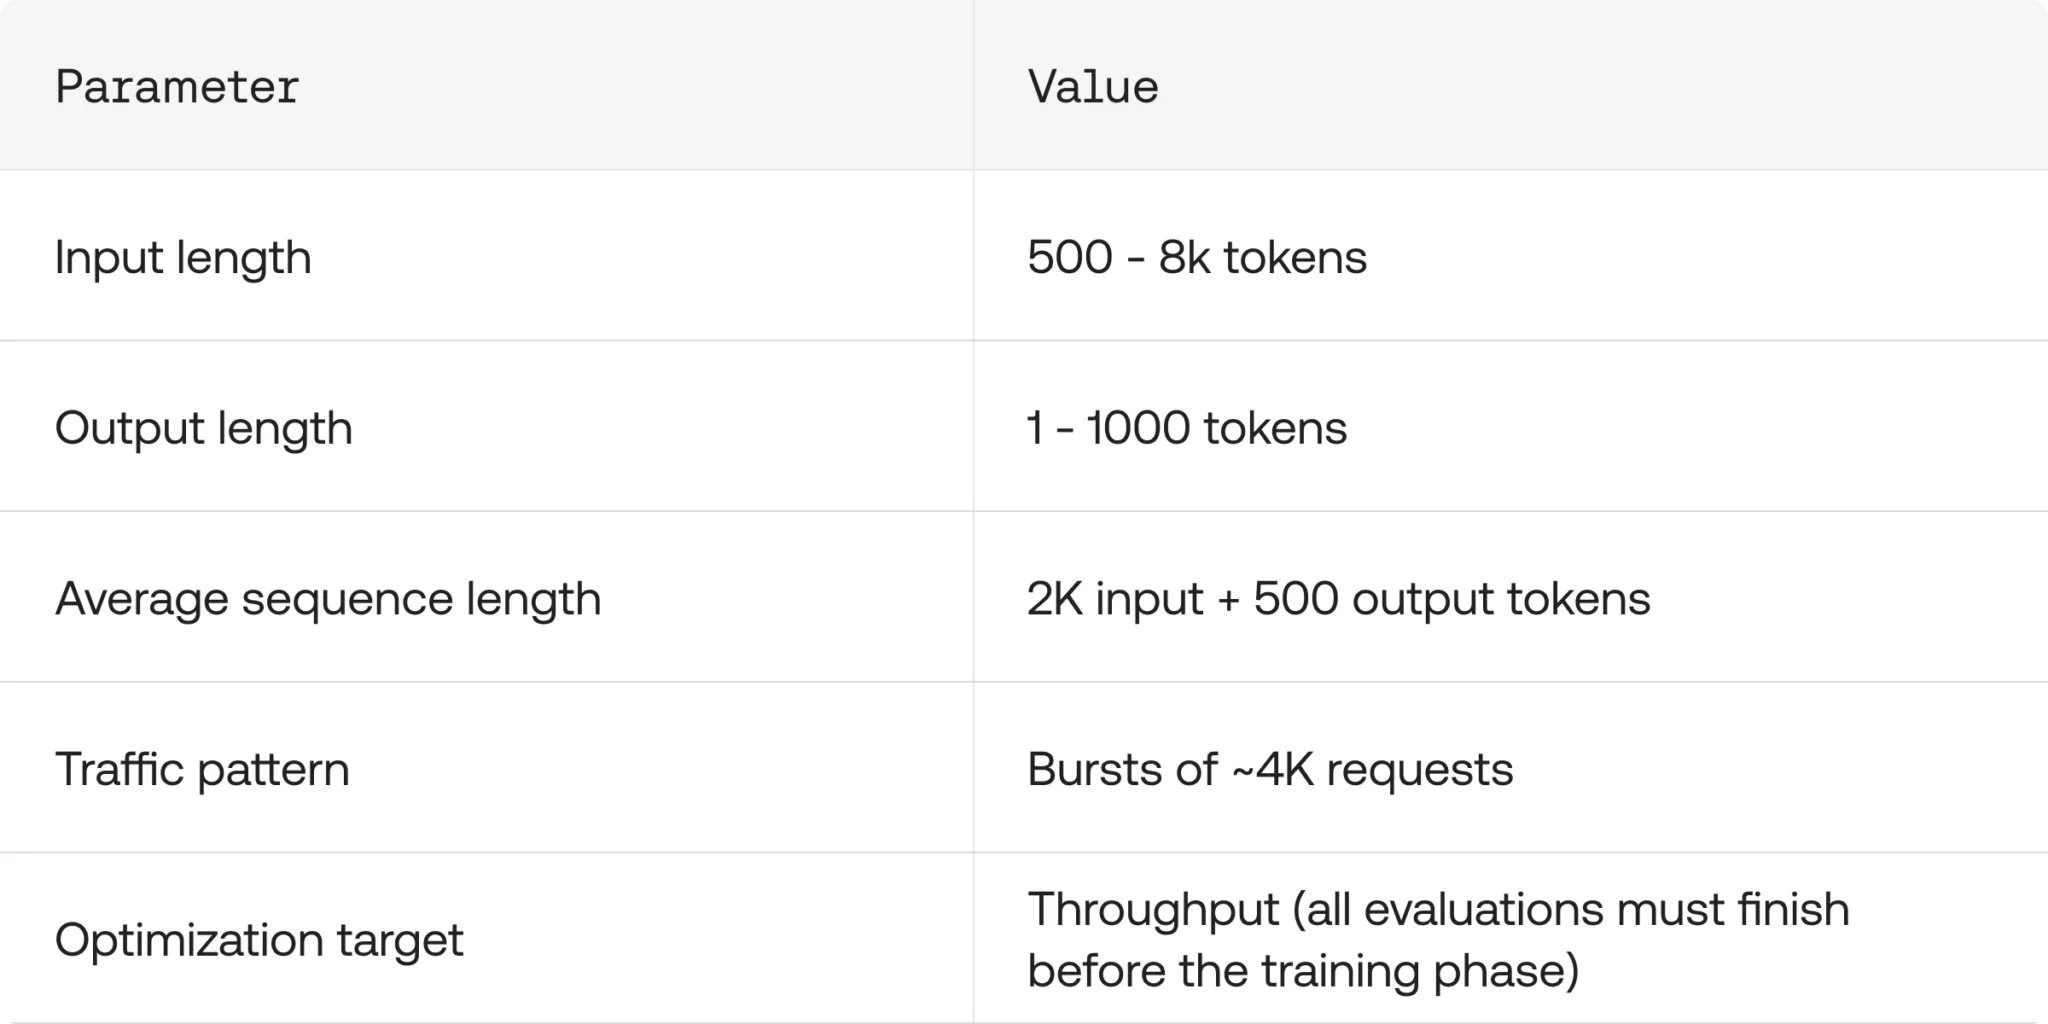
3/5 The vertical fix: auto-tune vLLM config Our old settings were way too conservative. After tuning with Auto-Tune vLLM + GuideLLM we got: ~2× throughput, 2× lower latency, same GPU budget @VLLM @Openshift