A Pseudolab developer event in Korea showcasing Llama 3.1 70B running on TT-QuietBox with the vLLM framework. Buy TT-QuietBox today –> http://
tenstorrent.com/hardware/tt-qu
ietbox
…
HARDWARE
-

Llama 3.1 70B on TT-QuietBox with vLLM Framework
By
–
-

SambaNova Suite Delivers World-Record AI Inference Performance
By
–
SambaNova Suite is THE platform for inference & fine-tuning ⭐️
— SambaNova (@SambaNovaAI) 26 novembre 2024
🚀 World-record performance
🎯 Accurate & efficient results
🔒 Secure AI platform #GenAI #AI #AIChips
Learn more ⤵️SambaNova Suite is THE platform for inference & fine-tuning World-record performance Accurate & efficient results Secure AI platform #GenAI #AI #AIChips Learn more
-

Agentic AI demands ultra-fast inference speeds for business
By
–
Last week, @KunleOlukotun shared insights on the future of #AI with @SquawkCNBC at @SlushHQ.
— SambaNova (@SambaNovaAI) 26 novembre 2024
⚡️ Agentic AI will demand ultra-fast #inference
🚀 Training advantage doesn’t mean speed
💰 SambaNova avoids costly upgrades
🏎️ Fast inference will solve business challenges pic.twitter.com/koyTQO3uGxLast week, @KunleOlukotun shared insights on the future of #AI with @SquawkCNBC at @SlushHQ
. Agentic AI will demand ultra-fast #inference Training advantage doesn’t mean speed SambaNova avoids costly upgrades Fast inference will solve business challenges -
Cerebras Demonstrates 70x Faster LLM Inference at NeurIPS 2024
By
–
It's that time of the year again! We're headed to Vancouver for NeurIPS 2024!
— Cerebras (@cerebras) 26 novembre 2024
Test drive Cerebras Inference, serving the biggest LLMs 70x faster than NVIDIA GPUs. Learn about the latest ML research that's powering the next wave of genAI.
See you there: https://t.co/9Cji9bKtx3 pic.twitter.com/JhGlaFPLWDIt's that time of the year again! We're headed to Vancouver for NeurIPS 2024! Test drive Cerebras Inference, serving the biggest LLMs 70x faster than NVIDIA GPUs. Learn about the latest ML research that's powering the next wave of genAI. See you there: https://
cerebras.ai/events/neurips
2024
… -

NVIDIA releases Hymba-1.5B open-source language model weights
By
–
yo! @NVIDIAAIDev finally released the weights for Hymba-1.5B – outperforms Llama, Qwen, and SmolLM2 with 6-12x less training trained ONLY on 1.5T tokens > massive reductions in KV cache size and improved throughput
> combines Mamba and Attention in a hybrid parallel -
Generative AI and Agentic AI Transform Key Industries in 2025
By
–
Gain insights from NVIDIA experts on how industries such as healthcare, telecom, energy, automotive, retail, entertainment, and robotics will be utilizing #generativeAI in 2025. #AgenticAI
-

AI Training Clusters Energy Consumption: Dell Intel Partnership Insights
By
–
Did you know a single AI training cluster can consume as much energy as 10% of an entire city? Vivek Mohindra, SVP of Corporate Strategy at @Dell
, shared this surprising fact during our chat at CXO Spice. Here are the key takeaways: Dell & Intel Partnership: A legacy -
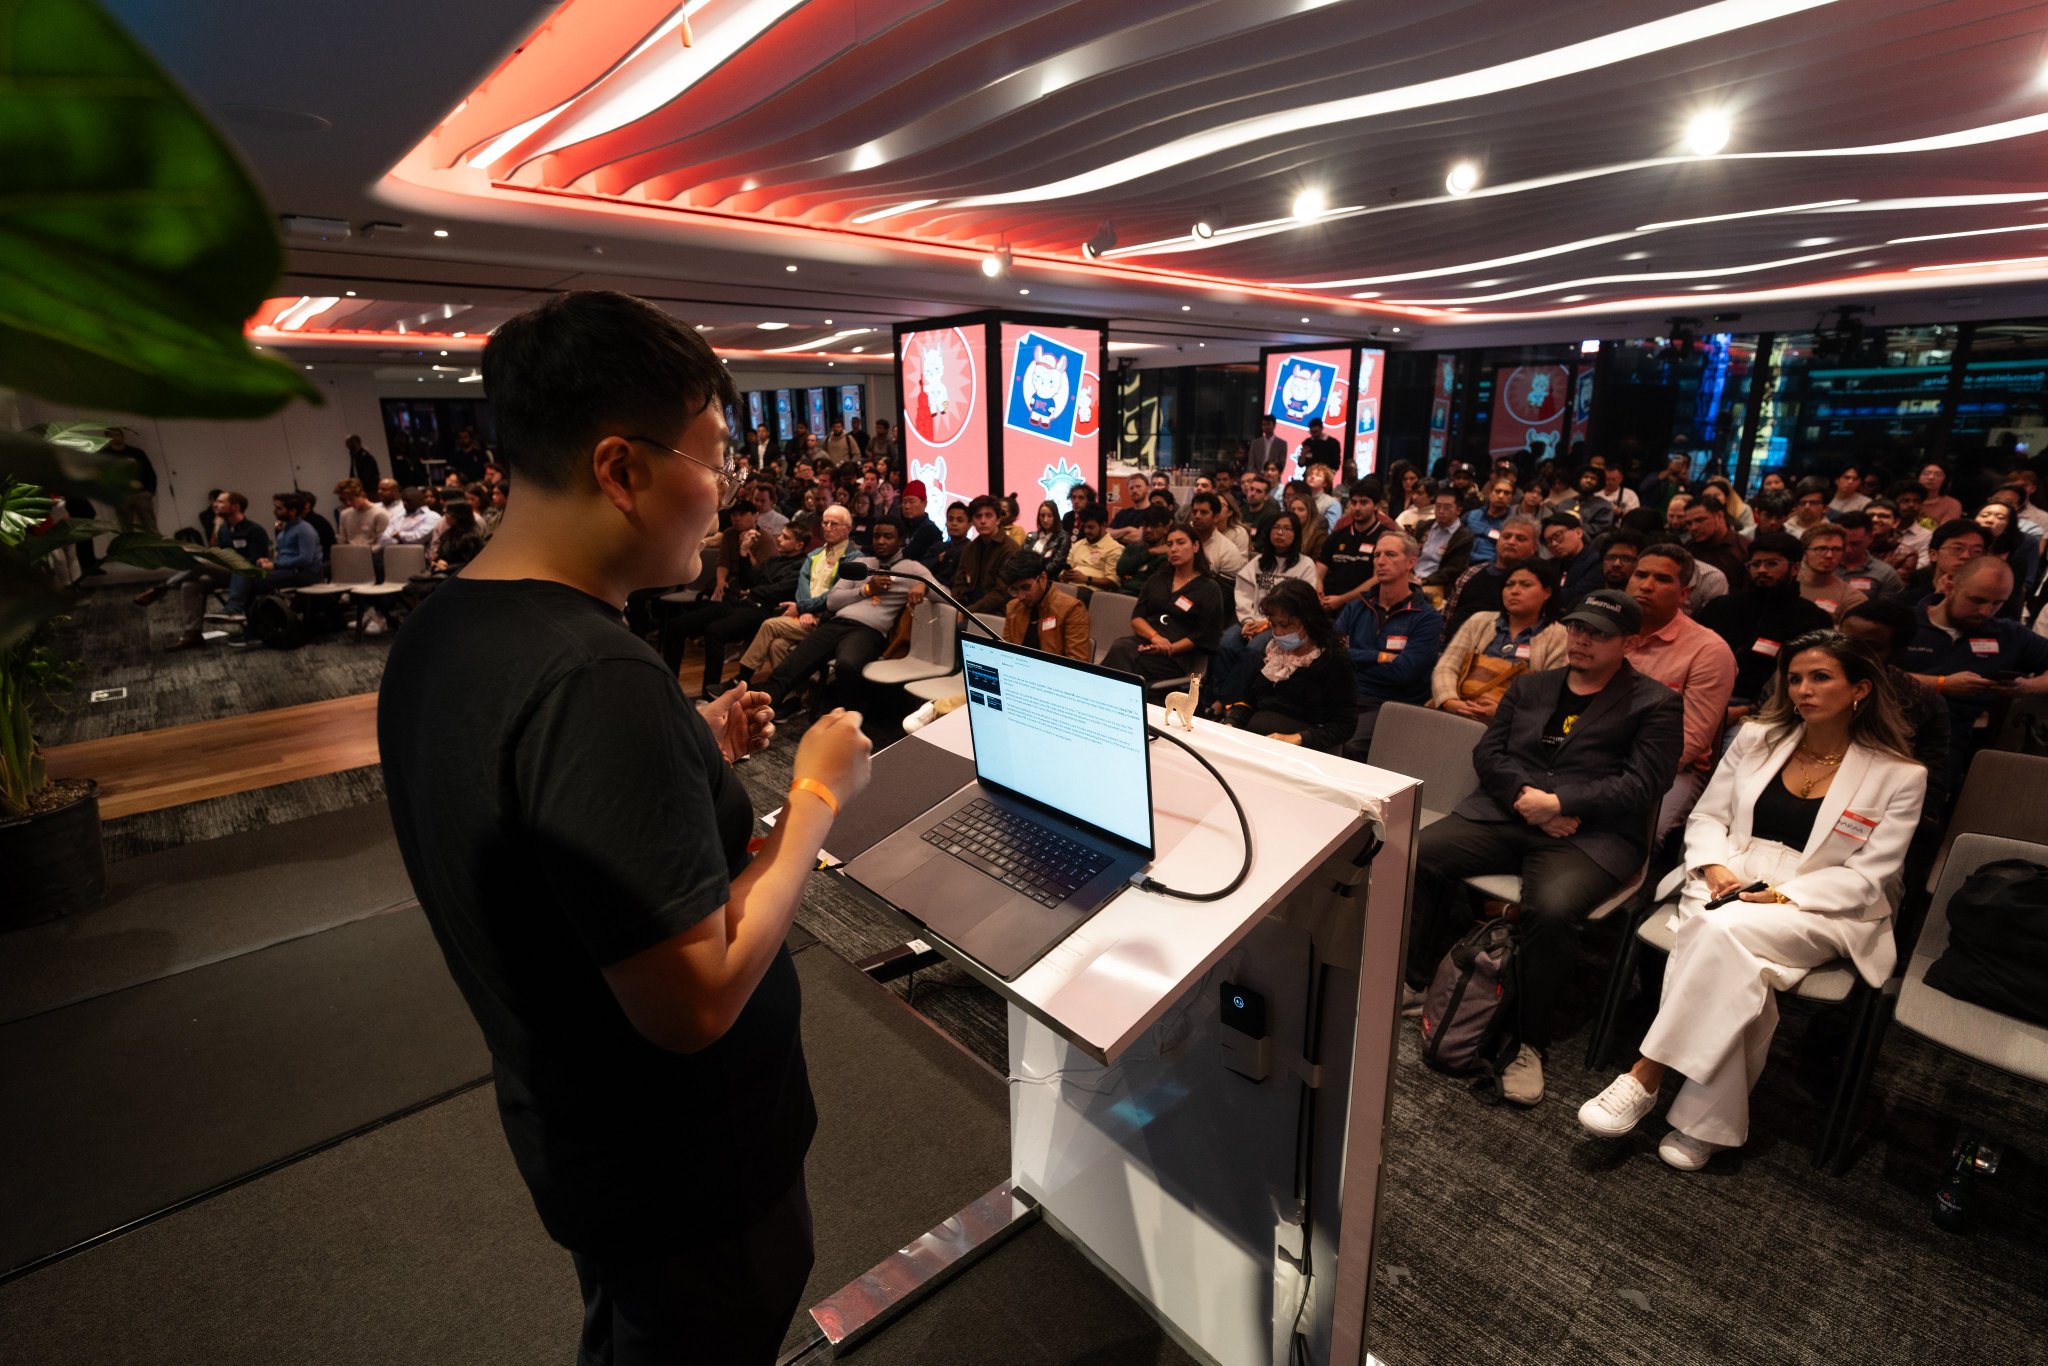
Cerebras Achieves 70x Faster Inference Than NVIDIA
By
–
Curious how we've achieved 70x faster inference than NVIDIA? Watch @learnwdaniel
's talk from Llamapalooza to learn about both the hardware and the software optimizations Cerebras is achieving to power the next generation of AI. Watch: https://
youtu.be/qLKp3mc26Gg?si
=Az8SEXK7y1u-hIeb
… -
Edge AI Revolutionizes Satellite Computing with Onboard Processing
By
–
From 8-bit CPUs to intelligent edge processing: Our VP @beach66 discusses how #edgeAI revolutionizes satellite computing, enabling onboard data analysis and continuous improvements through AI model updates. Read more from the latest @KratosDefense article.
-
Serving ChatGPT to 100M users with 1k H100s efficiently
By
–
Load balancing, caching, dynamic batching… with 10% DAU you probably don’t need much more than 1k H100s to serve ChatGPT to 100 million customers.