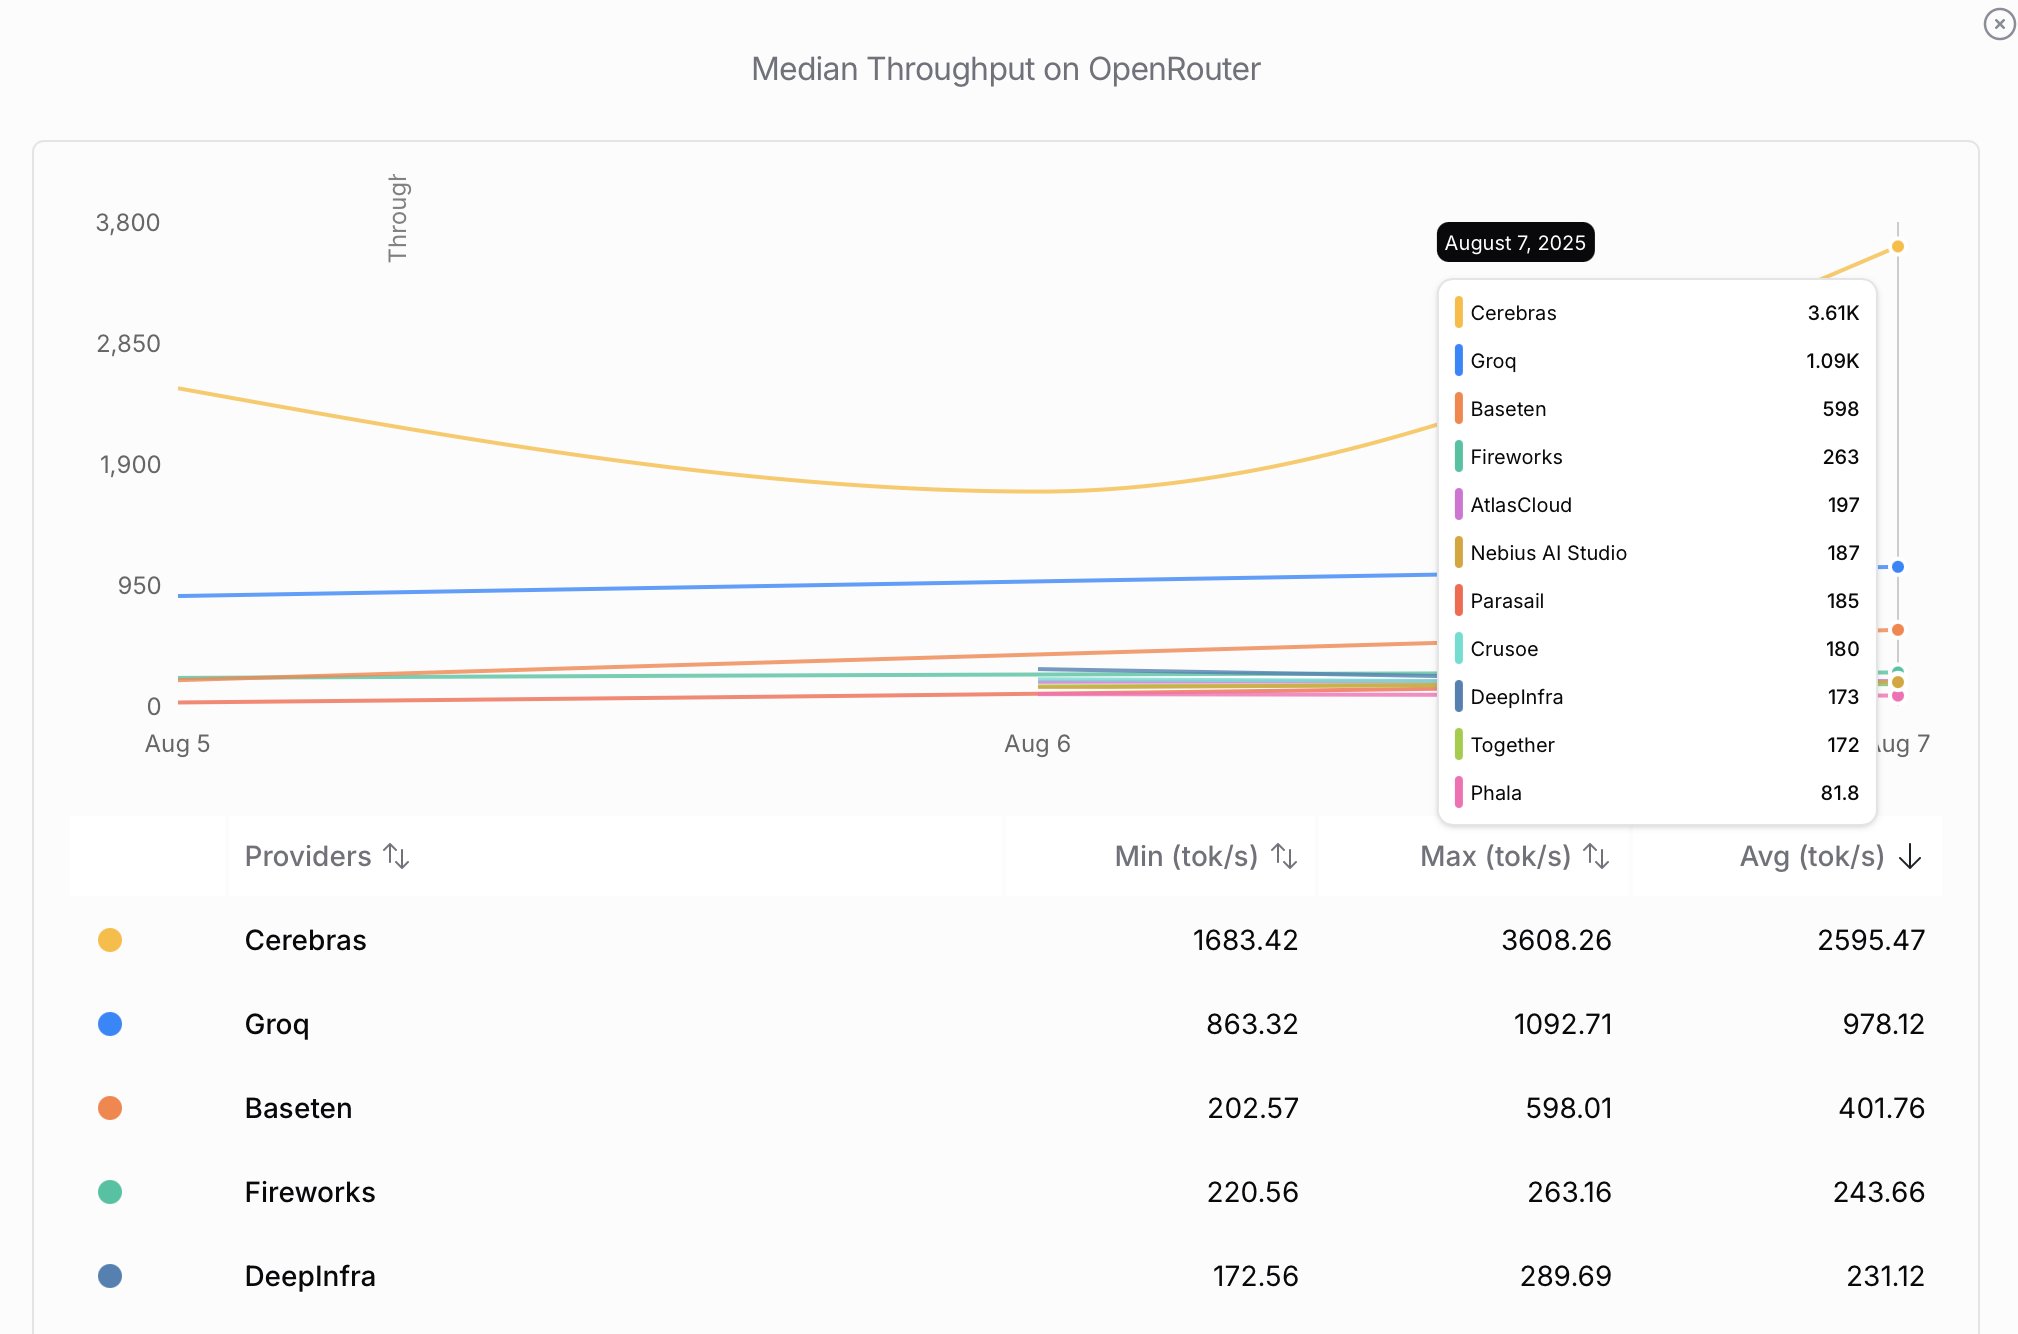
Deployed some more capacity and we are so back
HARDWARE
-

Cerebras outperforms Ferrari: 20x speed, comparable cost
By
–
Ferrari: 50% faster, 10x cost
Cerebras: 20x faster, same-ish cost. -
Hetzner Cloud reliability compared to bare metal hosting
By
–
I've used ~10 of them and they're all fine. Mainly Hetzner Cloud nowadays. More expensive than bare metal, but it's all they provide in the US, and they've always been solid.
-
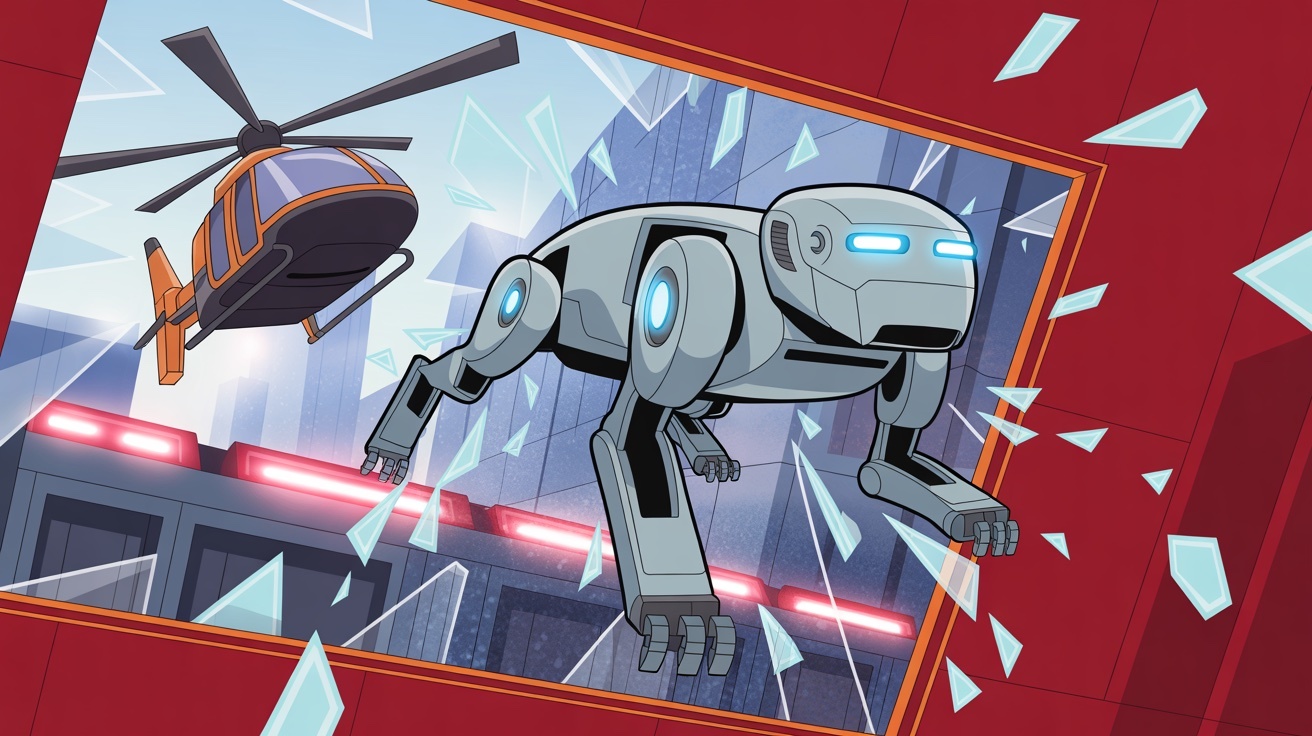
Top robotics breakthroughs: robodog stunts, android platform, hotel automation
By
–
Top stories in robotics today: – Unitree’s ultra-fast stunt robodog
– OpenMind’s ‘Android for robots’ – Japanese hotel run by robots – Robots rebuild homes after the LA fires
– Quick hits on other robotics news Read more: https://
robotnews.therundown.ai/p/unitrees-stu
nt-double-robodog
… -
Cutting-Edge AI and Robotics Innovations Shine at Goodwood Future Lab
By
–
The Incredible Tech That Stole The Show At Goodwood’s Future Lab Goodwood’s Future Lab at the Festival of Speed 2025 offered more than car reveals—it showcased cutting-edge innovations from space tech and quantum simulation to humanoid robots like Ameca, hinting at the future of
-
European AI Chip Startup Discusses Edge Computing GenAI Strategy
By
–
Excellent interview here in which @FabAroundEU (CEO at Axelera AI) talks to @VerveVentures about AI chips, European deep tech, and running GenAI at the edge with no cloud in sight.
Don't miss this! https://
eu1.hubs.ly/H0mdr-n0 -
Armed Amphibious Robot Dogs Signal Alarming AI Robotics Advance
By
–
La course vers Skynet continue : des chiens amphibies armés tout droit sortis de Black Mirror sont là. pic.twitter.com/XSkjEzgjsH
— VISION IA (@vision_ia) 7 août 2025La course vers Skynet continue : des chiens amphibies armés tout droit sortis de Black Mirror sont là.
-
GPT-OSS-120B: Efficient Open-Source Model on Single GPU
By
–
gpt-oss-120b is useless?
— Louis-François Bouchard 🎥🤖 (@Whats_AI) 7 août 2025
• 117 B-param MoE (5.1 B active), fits on a single 80 GB GPU
• Near-o4-mini parity on reasoning, coding, math & health tasks
• 128 k context, 3 “effort” levels, full CoT, tool use & code exec
• Trained on English STEM/code, multilingual capacity… pic.twitter.com/Guys37kCgFgpt-oss-120b is useless? • 117 B-param MoE (5.1 B active), fits on a single 80 GB GPU • Near-o4-mini parity on reasoning, coding, math & health tasks • 128 k context, 3 “effort” levels, full CoT, tool use & code exec • Trained on English STEM/code, multilingual capacity
-
Python FastAI Framework for GPU-Accelerated Machine Learning
By
–
Oh I just use python/fastai. This can help too: https://
fastgpu.fast.ai -
Groundbreaking AI Models Optimized for RTX PCs
By
–
Groundbreaking models are now available with optimizations for RTX AI PCs.