BIG DAY: GLM 5.1, DeepSeek v4, Minimax 2.7 is COMING
GENERATIVE AI
-
AI Expert Curates Comprehensive AI Lists on X Platform
By
–
I put you in my AI lists which are the most complete on X: https://
x.com/scobleizer/lis
ts
… -
LangSmith: Debugging and Optimizing AI Agents in Production
By
–
LangSmith 🤝Fix your agents
— Harrison Chase (@hwchase17) 7 avril 2026
You'll see our billboards around SF and NYC over the next few months.
The themes all point to the same problem: you don't know what your agents will do until you actually run them. What works in demos can break in the real world. Without tracing and… pic.twitter.com/IRKrj7J1y7LangSmith 🤝Fix your agents You'll see our billboards around SF and NYC over the next few months. The themes all point to the same problem: you don't know what your agents will do until you actually run them. What works in demos can break in the real world. Without tracing and evals, you're just guessing at why. Track what your agent actually does. Optimize and fix your agents. Then measure whether your fixes work. That loop is how agents get better, and LangSmith is built to power that workflow. If you spot one around, send it our way!
-
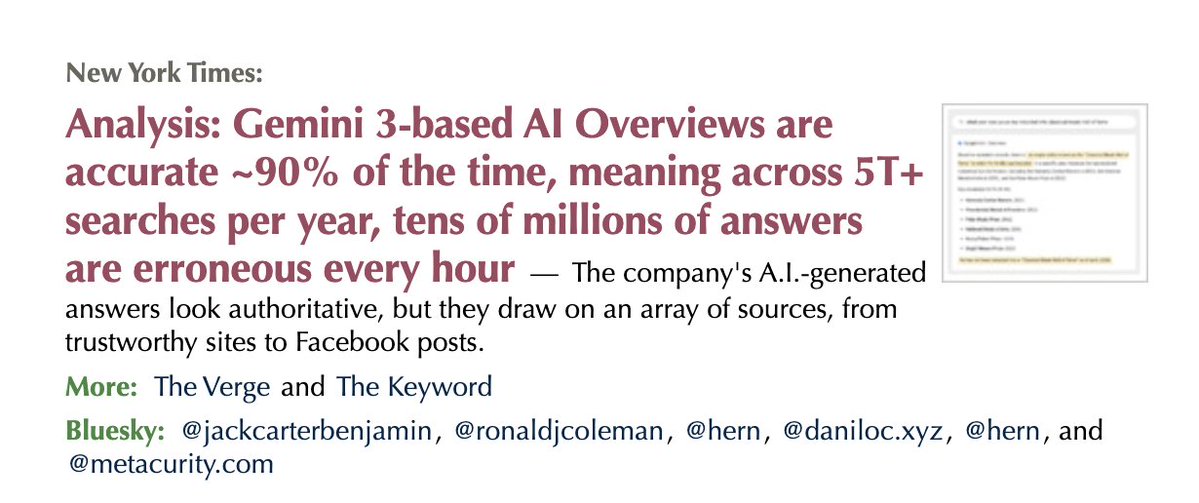
Google’s 10% Error Rate: Shift from Pre-ChatGPT Standards
By
–
10% error rate at any scale would never have been tolerated by Google pre-ChatGPT. The company has fundamentally changed rat king 🐀 (@MikeIsaac) glass half full: 90 percent accuracy is an impressive accuracy rate glass half empty: 10 percent error rate for a company that does more than 5 Trillion search queries per year is still a gigantic number nytimes.com/2026/04/07/techn… — https://nitter.net/MikeIsaac/status/2041535422623609174#m
→ View original post on X — @garymarcus, 2026-04-07 15:51 UTC
-

Salesforce Uses Slackbot to Solve SaaS Crisis
By
–
Salesforce is looking to Slackbot to help it solve the SaaSPocalypse puzzle go.theregister.com/feed/www.… [Translated from EN to English]
→ View original post on X — @craigbrownphd, 2026-04-07 15:49 UTC
-
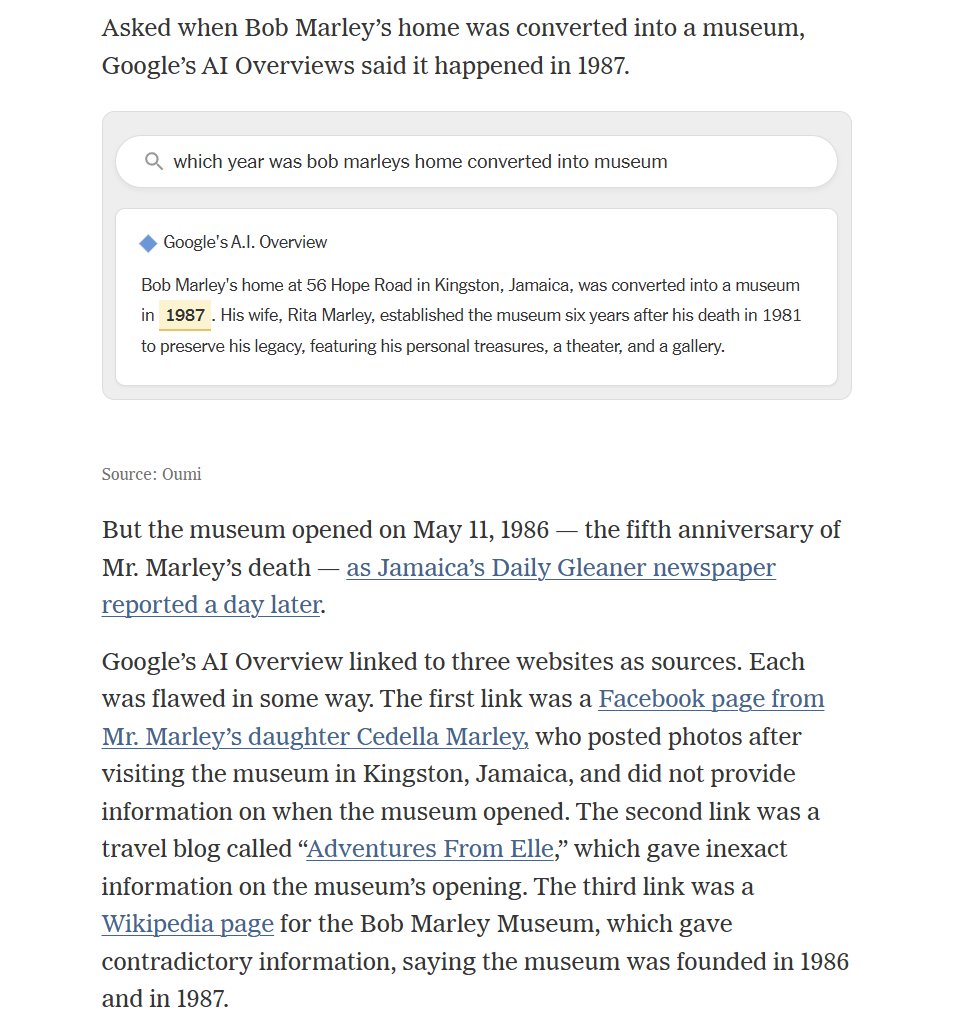
The challenges of measuring AI performance and reliability
By
–

This article is a case study of why measuring AI performance is so hard. AI Overviews make mistakes. But the same mistakes are in Wikipedia. But the sources are harder to find when using AI. But the AI answers may be better than most people would find. Unclear what it all means.
-
No AI involved in making this creative work
By
–
No AI involved in the making of this, can you believe it
-

Business Value of Agentic AI: Three Key Pillars for Scaling
By
–
What's The #Business Value Of #AgenticAI? Three Key Pillars For Scaling #AIAgents by Preetpal Singh @Forbes Learn more: buff.ly/d3CwrxT #LLM #GenerativeAI #ArtificialIntelligence #MachineLearning
→ View original post on X — @ronald_vanloon, 2026-04-07 15:23 UTC
-
AI’s Hybrid Strategy: Sharing Influence and Competitive Control
By
–
A new divide appears. For our free newsletter this week, we discuss how the AI industry is moving toward a new divide, open sourcing enough to spread influence while reserving their strongest models to preserve their strategic edge. @IrenaCronin and I write this newsletter every week. The AI industry is moving toward a hybrid strategy in which companies share enough of their models and tools to build adoption, developer loyalty, and ecosystem influence, while keeping their most advanced systems closed to protect competitive advantage, control risk, and capture more value. Instead of a simple open versus closed divide, AI is increasingly becoming a spectrum shaped by business strategy, safety concerns, and market competition. Read for free at unaligned.io and please subscribe! [Translated from EN to English]
→ View original post on X — @scobleizer, 2026-04-07 15:20 UTC
-

Anthropic Plans Always-On Claude Agent for Mobile
By
–

BREAKING : Anthropic is working on adding Claude Conway always-on agent to its mobile app. This means that we potentially may see a consumer version too! Soon?