Ever pondered how AI revolutionizes work and business in the new era? What if 300 million users becoming 20% more productive? @SAP
's CEO, Christian Klein, unveiled a groundbreaking revelation at #SAPSapphire last week—by year-end, #Joule, the AI assistant, will oversee 80% of
GENERATIVE AI
-

SAP Joule AI Assistant to Drive 20% Productivity Gains
By
–
-
Awesome LLM Apps with RAG GitHub Repository Showcase
By
–
Find all the awesome LLM Apps demo with RAG in the following Github Repo. P.S: Don't forget to star the repo to show your support
-
Local ChatGPT Memory Application Demo Using Streamlit
By
–
Working Application demo using Streamlit
— Shubham Saboo (@Saboo_Shubham_) 10 juin 2024
Paste the above code in vscode or pycharm and run the following command: 'streamlit run local_chatgpt_memory.py' pic.twitter.com/V8qsEyo3H1Working Application demo using Streamlit Paste the above code in vscode or pycharm and run the following command: 'streamlit run local_chatgpt_memory.py'
-
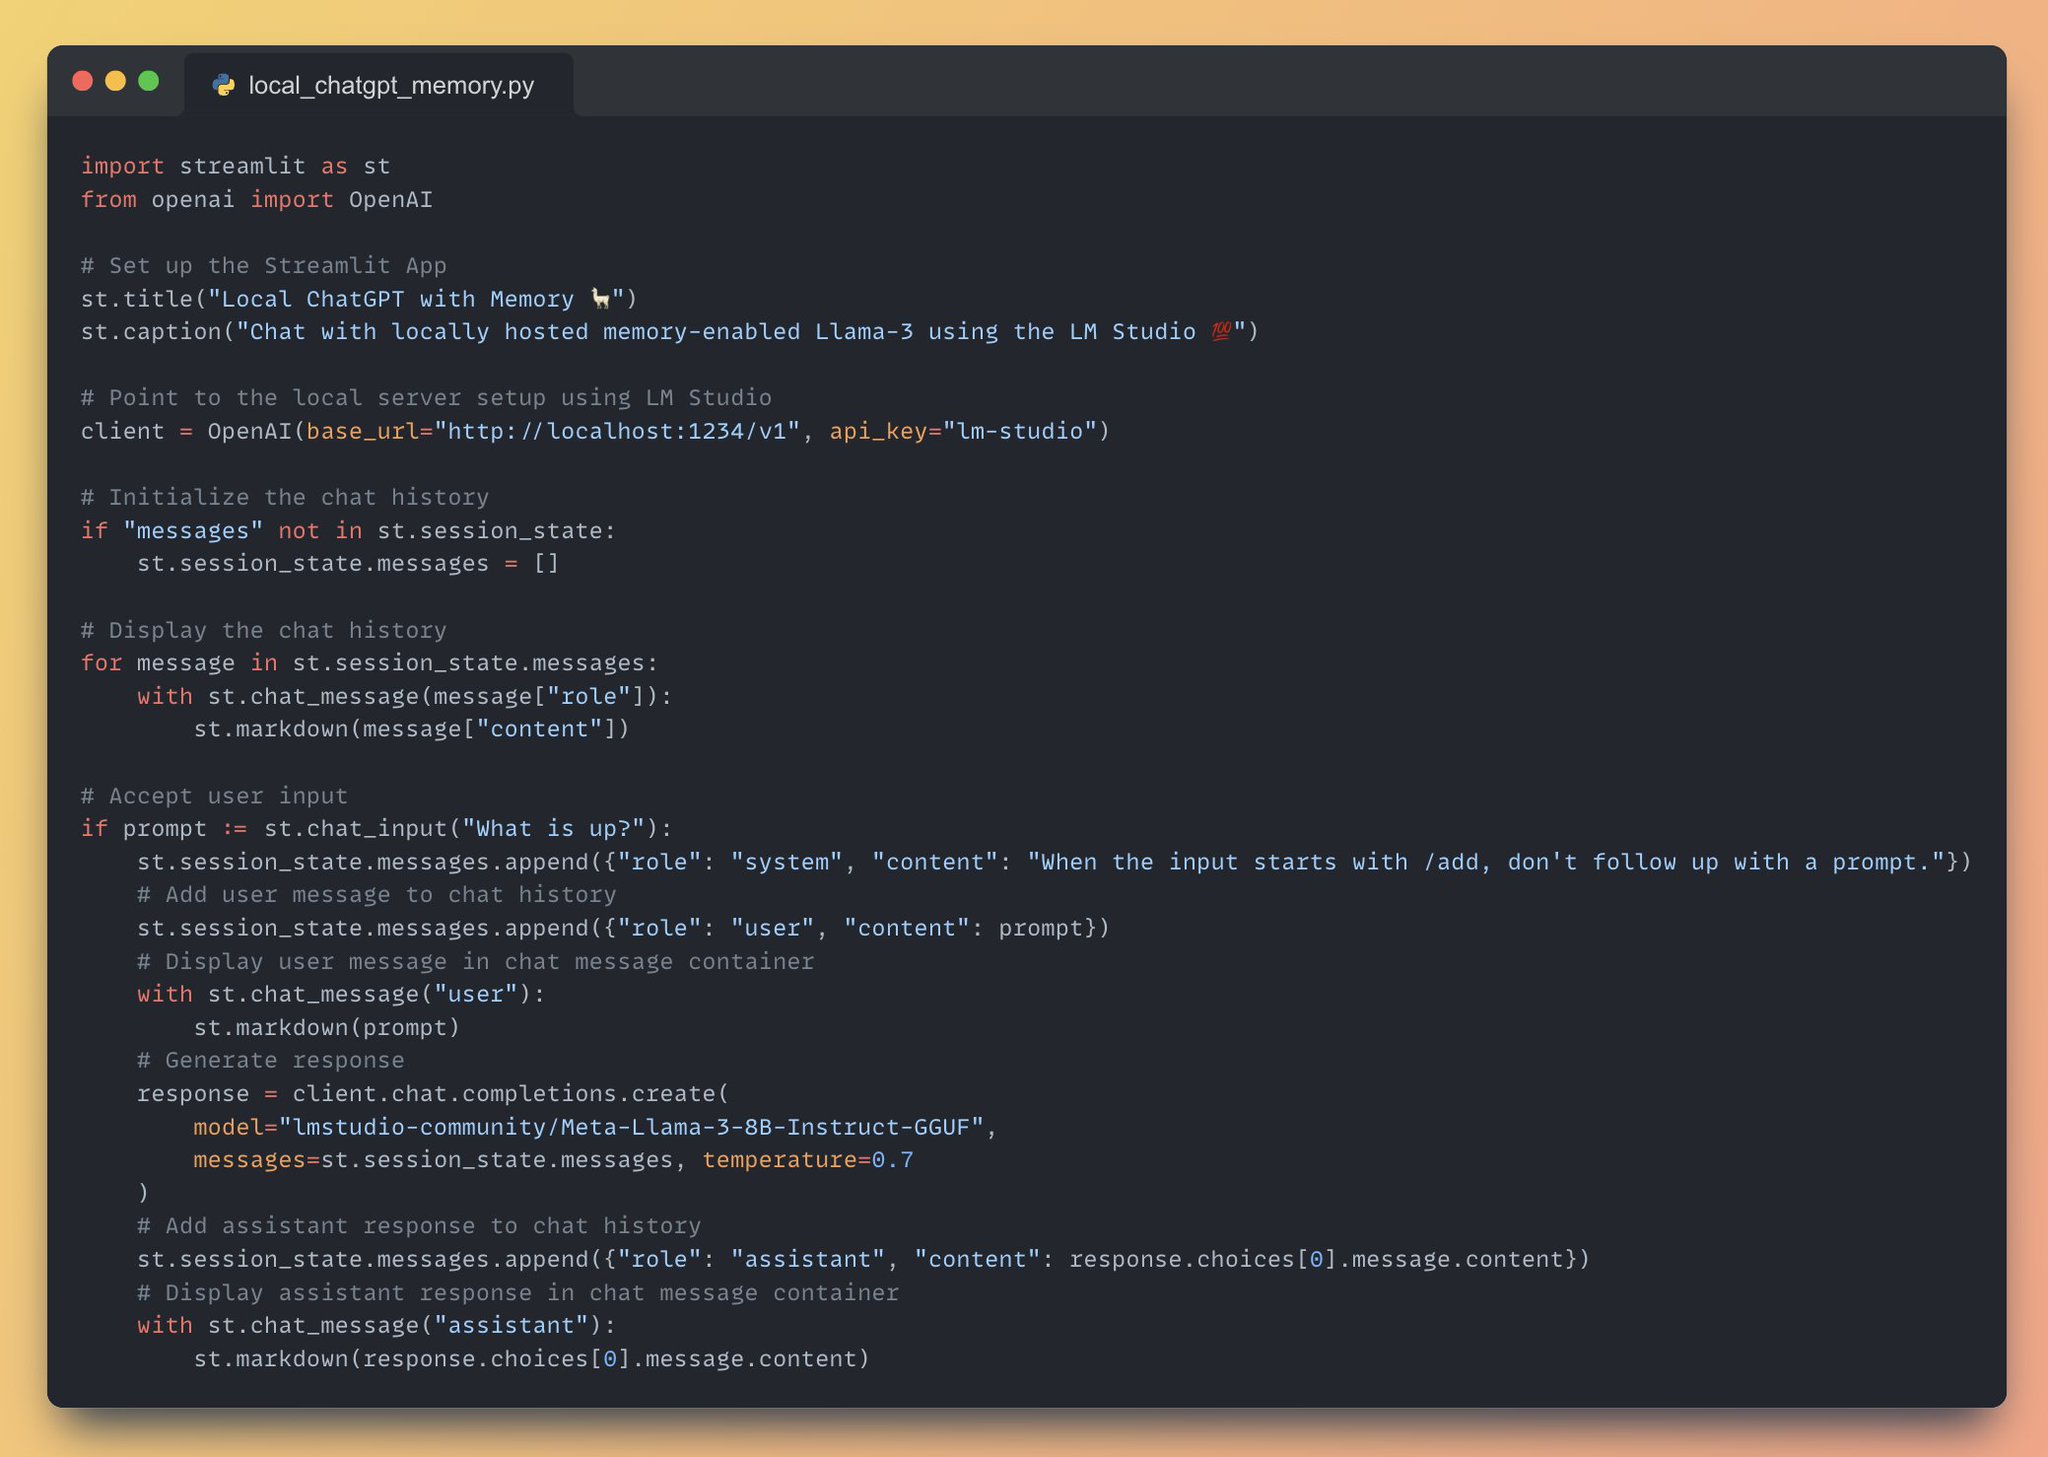
Full Application Code for Local ChatGPT with Memory
By
–
Full Application code for Local ChatGPT with memory
-
Building Web App with Llama-3 and Streamlit Integration
By
–
2. Import necessary libraries • Streamlit for building the web app
• OpenAI for accessing the Llama-3 model from a local server using the @LMStudioAI -
Build LLM App with Memory Using Llama-3 Locally
By
–
Build a LLM app with memory using Llama-3 running locally on your computer (100% free and without internet):
-
X Premium Users Monetize Neural Capacity via Grok Integration
By
–
Well it all started when X premium users with Neuralink could get paid to let Grok use excess neural capacity…
-
GPT-2 Speed Run: Building 124M Model from Scratch
By
–
"GPT-2 speed run" haha I love that.
From empty file to GPT-2 (124M) 😀 -

Reproducing GPT-2 124M: Comprehensive 4-Hour Video Lecture
By
–
📽️ New 4 hour (lol) video lecture on YouTube: "Let’s reproduce GPT-2 (124M)" piped.video/l8pRSuU81PU The video ended up so long because it is… comprehensive: we start with empty file and end up with a GPT-2 (124M) model: – first we build the GPT-2 network – then we optimize it to train very fast – then we set up the training run optimization and hyperparameters by referencing GPT-2 and GPT-3 papers – then we bring up model evaluation, and – then cross our fingers and go to sleep. In the morning we look through the results and enjoy amusing model generations. Our "overnight" run even gets very close to the GPT-3 (124M) model. This video builds on the Zero To Hero series and at times references previous videos. You could also see this video as building my nanoGPT repo, which by the end is about 90% similar. Github. The associated GitHub repo contains the full commit history so you can step through all of the code changes in the video, step by step. github.com/karpathy/build-na… Chapters. On a high level Section 1 is building up the network, a lot of this might be review. Section 2 is making the training fast. Section 3 is setting up the run. Section 4 is the results. In more detail: 00:00:00 intro: Let’s reproduce GPT-2 (124M) 00:03:39 exploring the GPT-2 (124M) OpenAI checkpoint 00:13:47 SECTION 1: implementing the GPT-2 nn.Module 00:28:08 loading the huggingface/GPT-2 parameters 00:31:00 implementing the forward pass to get logits 00:33:31 sampling init, prefix tokens, tokenization 00:37:02 sampling loop 00:41:47 sample, auto-detect the device 00:45:50 let’s train: data batches (B,T) → logits (B,T,C) 00:52:53 cross entropy loss 00:56:42 optimization loop: overfit a single batch 01:02:00 data loader lite 01:06:14 parameter sharing wte and lm_head 01:13:47 model initialization: std 0.02, residual init 01:22:18 SECTION 2: Let’s make it fast. GPUs, mixed precision, 1000ms 01:28:14 Tensor Cores, timing the code, TF32 precision, 333ms 01:39:38 float16, gradient scalers, bfloat16, 300ms 01:48:15 torch.compile, Python overhead, kernel fusion, 130ms 02:00:18 flash attention, 96ms 02:06:54 nice/ugly numbers. vocab size 50257 → 50304, 93ms 02:14:55 SECTION 3: hyperpamaters, AdamW, gradient clipping 02:21:06 learning rate scheduler: warmup + cosine decay 02:26:21 batch size schedule, weight decay, FusedAdamW, 90ms 02:34:09 gradient accumulation 02:46:52 distributed data parallel (DDP) 03:10:21 datasets used in GPT-2, GPT-3, FineWeb (EDU) 03:23:10 validation data split, validation loss, sampling revive 03:28:23 evaluation: HellaSwag, starting the run 03:43:05 SECTION 4: results in the morning! GPT-2, GPT-3 repro 03:56:21 shoutout to llm.c, equivalent but faster code in raw C/CUDA 03:59:39 summary, phew, build-nanogpt github repo
→ View original post on X — @sudalairajkumar, 2024-06-09 23:41 UTC
-
Data abundance and algorithmic advances beyond current scaling laws
By
–
7/ in the "data wall will slow AI" case, progress will depend on: – methods for data abundance (above)
– algorithmic advances that advance us beyond the current scaling law paradigm