6. Graphic designer Posting on social media is a hassle. This GPT make it easy for you. Try it out. Link: https://
chatgpt.com/g/g-lPeUc0axE-
graphic-designer
…
GENERATIVE AI
-

Graphic Designer GPT tool for social media content
By
–
-
Using Tutor Me GPT for personalized subject learning
By
–
4. Tutor me by Khan Academy
— God of Prompt (@godofprompt) 16 septembre 2024
Want to learn ANY subject with ChatGPT?
Use Tutor Me GPT.
Link: https://t.co/2HDFjNfn9l pic.twitter.com/cIRBZes4cj4. Tutor me by Khan Academy Want to learn ANY subject with ChatGPT? Use Tutor Me GPT. Link: https://
chatgpt.com/g/g-hRCqiqVlM-
tutor-me
… -
Mega Prompt Generator GPT for ChatGPT
By
–
1. Mega Prompt Generator
— God of Prompt (@godofprompt) 16 septembre 2024
To get exact and precise content from ChatGPT, give mega prompts to it.
This GPT can help you out.
Link: https://t.co/DdvLxY0DCg pic.twitter.com/7w6z4DDuNA1. Mega Prompt Generator To get exact and precise content from ChatGPT, give mega prompts to it. This GPT can help you out. Link: https://
chatgpt.com/g/g-1ObGhQpzP-
mega-prompt-generator
… -
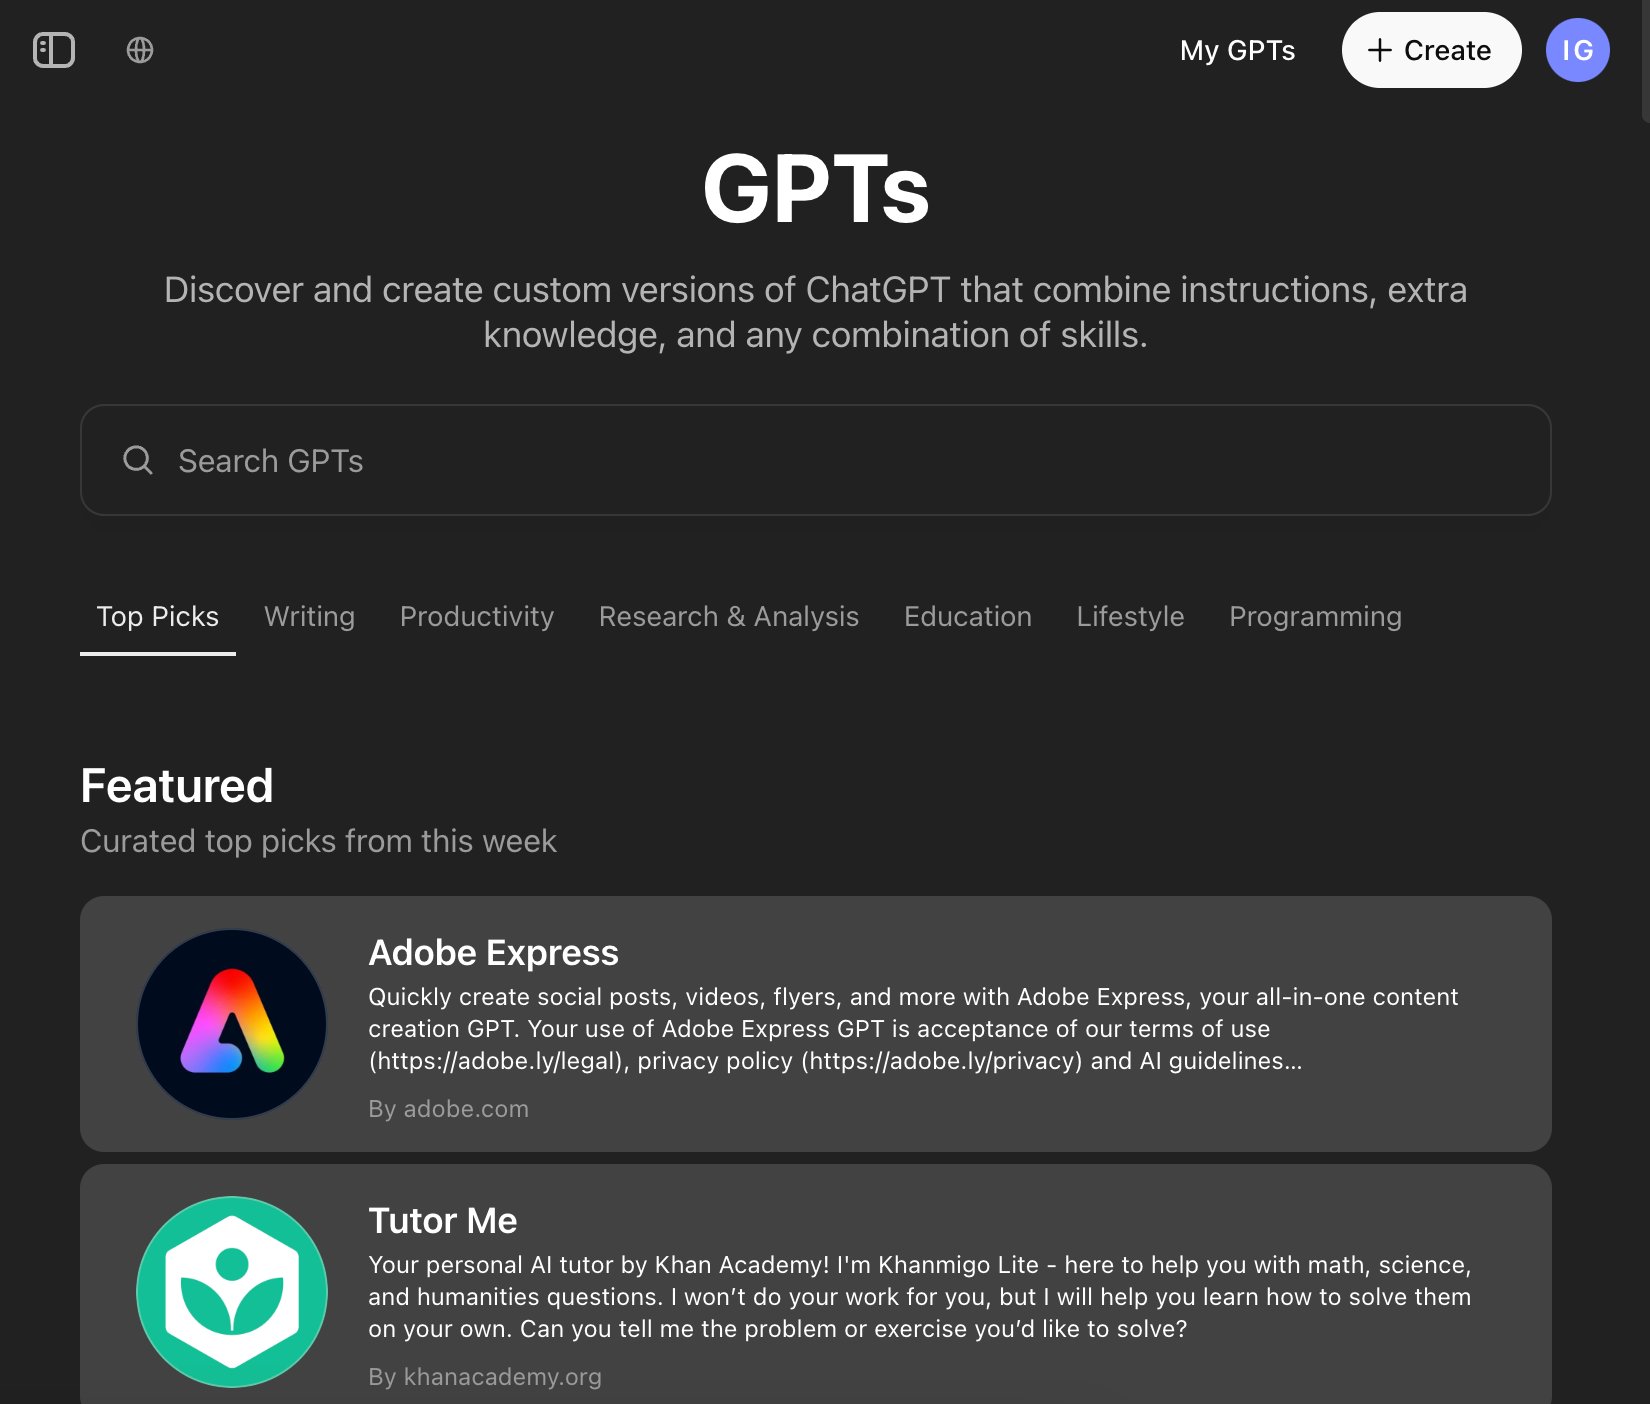
10 ChatGPT GPTs to Boost Productivity
By
–
I don't get it. People are ignoring the most powerful GPTs in ChatGPT. Here are 10 that will revolutionize your productivity:
-

Robust Dual Gaussian Splatting for Immersive Volumetric Videos
By
–
Robust Dual Gaussian Splatting for Immersive Human-centric Volumetric Videos
— AK (@_akhaliq) 16 septembre 2024
discuss: https://t.co/iwU9lvOFHM
Volumetric video represents a transformative advancement in visual media, enabling users to freely navigate immersive virtual experiences and narrowing the gap between… pic.twitter.com/7R3pP5W9y8Robust Dual Gaussian Splatting for Immersive Human-centric Volumetric Videos discuss: https://
huggingface.co/papers/2409.08
353
… Volumetric video represents a transformative advancement in visual media, enabling users to freely navigate immersive virtual experiences and narrowing the gap between -

OpenAI o1 Requires Advanced Evals for Progress Measurement
By
–
With OpenAI o1, it’s very clear we need more advanced and unsaturated evals to realistically measure progress going forward. Scale AI will have a big announcement later this week… stay tuned In the meantime, I’m back home in New Mexico, looking for eval inspiration
-

Direct Preference Optimization Authors Discuss DPO Impact
By
–
Thrilled to have the authors of Direct Preference Optimization answering questions on their paper! DPO offers a simple alternative to RLHF and has been hugely impactful, including being used to train Llama 3! Talk to the authors @archit_sharma97 and team directly to learn more!
-
Five Essential Papers on LLM Reasoning and RLHF Training
By
–
If you're curious about how large language models (LLMs) like @OpenAI
's O1 may enhance reasoning for complex tasks—not just through prompting, but via training and Reinforcement Learning from Human Feedback (RLHF)—here are 5 essential papers to explore: Quiet-STaR: Language -

Setting Up Gradio Demo on Hugging Face with o1-mini
By
–
setup a @Gradio demo for it on @huggingface, demo made by o1-mini https://t.co/VGjF6H4D53 pic.twitter.com/QiGp2oJxFo
— AK (@_akhaliq) 15 septembre 2024setup a @Gradio demo for it on @huggingface
, demo made by o1-mini