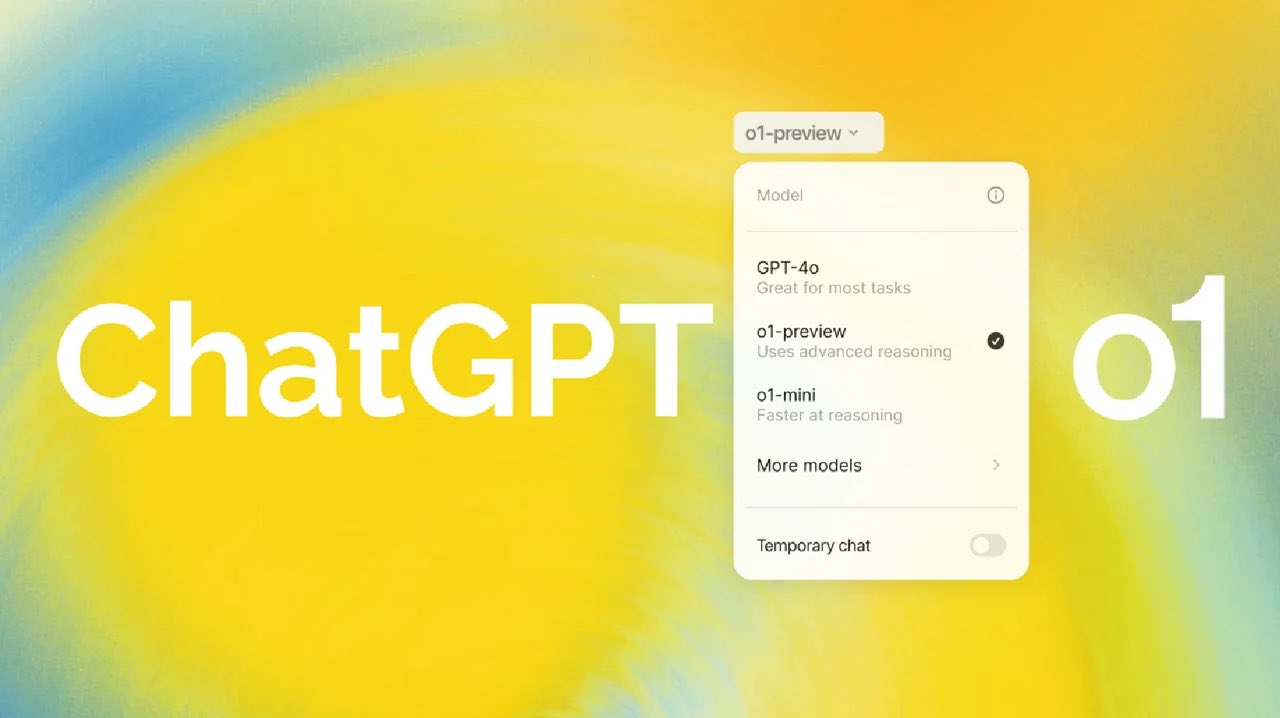
ChatGPT o1 model has shocked the AI world. Here’s how ChatGPT o1 evolved from previous GPT 4 version Follow the :
GENERATIVE AI
-
Hallucination in LLMs: Essential Feature for Exploration Discovery
By
–
It depends on what you do with LLMs. For new exploration and discovery, yes, hallucination is not just a feature. It's essential.
-

Anthropic Workbench Adds ‘Ideal Outputs’ Marking for Prompt Evaluation
By
–
ICYMI: Anthropic Workbench now allows marking "ideal outputs" in the prompt evaluator. Users can mark outputs which fit their expectations in order to improve their prompts further.
-
o1-mini vs o1-preview: choosing the right AI assistant
By
–
o1-mini is the smart friend that doesn't make you feel guilty asking for help o1-preview is smarter but you gotta choose your Qs, and respect their time
-

Code Pretraining Impact on Multilingual Language Models
By
–
Tune into the excellent discussion on our most actively discussed paper this week: To Code, or Not to Code! Here are the top 5 comments/questions! Thanks again @viraataryabumi and team! 1) How does pretraining on code data impact performance on non-English downstream tasks?
-
Prompt: Use ChatGPT for Zero-Based Thinking
By
–
6/ Zero-based thnking Prompt: "ChatGPT, guide me through a zero-based thinking process for [Decision/Strategy] to ensure it's still the right path."
-

Prompt to Outline a Competitive Moat Using ChatGPT
By
–
2/ Moat analysis Prompt: "ChatGPT, help me outline a moat for my [Product/Service] that will fend off competitors by focusing on [Unique Value Proposition]."
-
LLMs struggle counting tokens without Chain-of-Thought or tools
By
–
What I'm disputing is the specific, but I think common, misconception that of course any LLM could count *tokens* easily; it's just that tokenization makes letters unnecessarily hard. Without CoT or tools, LLMs are just bad at counting.