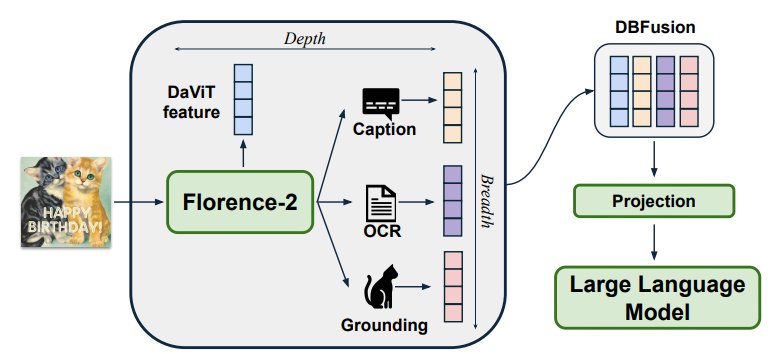
Florence-VL A multimodal large language model (MLLM) that integrates enriched visual representations from Florence-2 for improved vision-language alignment. Problem: Existing vision-language models (VL) are limited by less versatile visual representations and the need for
GENERATIVE AI
-
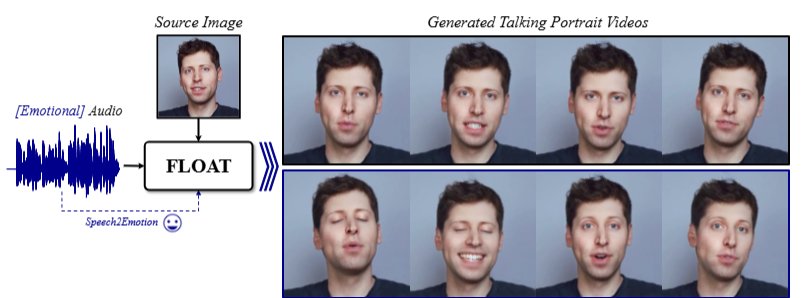
FLOAT: Expressive Talking Portrait Generation from Audio
By
–
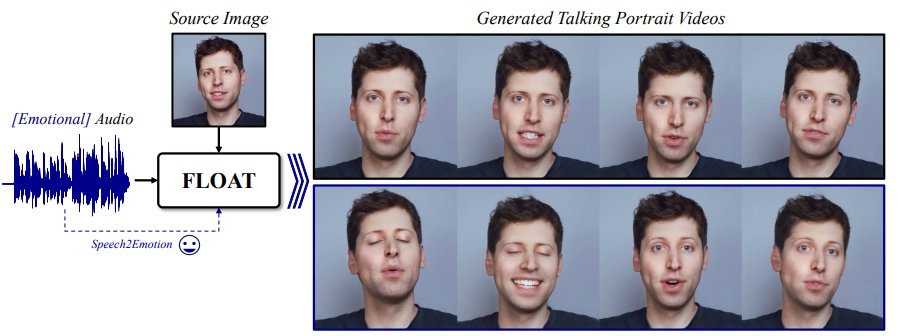
FLOAT A method for generating expressive, temporally consistent talking portrait videos from a single image and audio. Problem: Audio-driven talking portrait generation faces challenges in creating temporally consistent motion and efficient sampling while maintaining
-
Navigation World Models: Video Generation for Autonomous Agent Planning
By
–
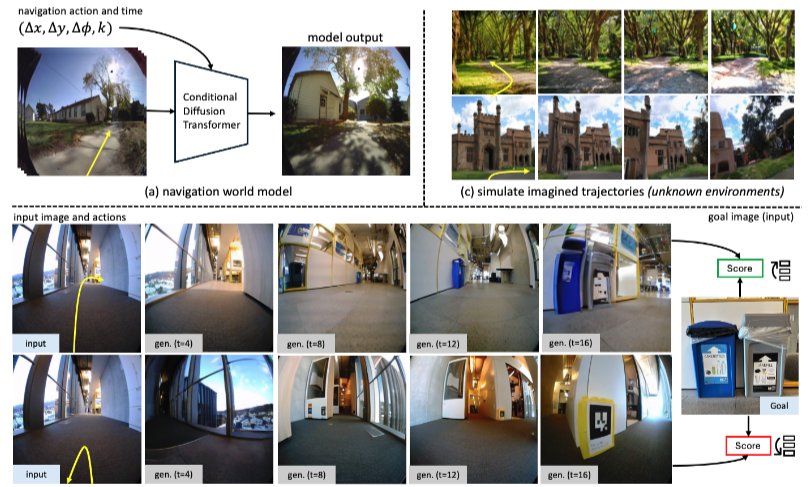
Navigation World Models A controllable video generation model that predicts future visual observations for navigation tasks based on past observations and actions. Problem: Visual-motor agents struggle with planning flexible navigation trajectories, especially in dynamic or
-
Open-Sora Plan: Open-Source High-Resolution Video Generation
By
–
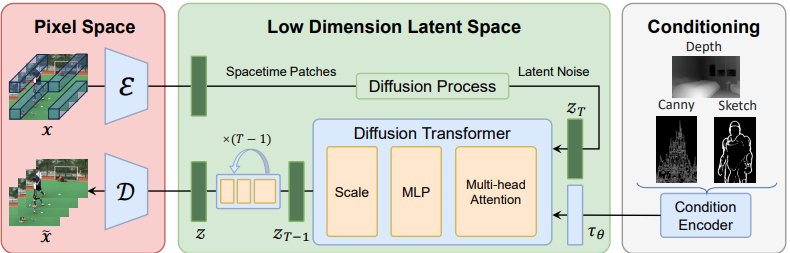
Open-Sora Plan: Open-Source Large Generation Model An open-source framework for generating high-resolution, long-duration videos from diverse user inputs. Problem: Existing video generation models struggle with high-resolution, long-duration video outputs due to high
-
Latest AI Papers: Navigation Models and Video Generation
By
–
Trending AI papers on alphaXiv this week, featuring an incredible week for the computer vision and multimodal communities – Navigation World Models (discussion with author @_amirbar
)
– Open-Sora Plan: Open-Source Large Generation Model (discussion with author -
Claude vs ChatGPT: Knowledge Cutoff Advantage Explained
By
–
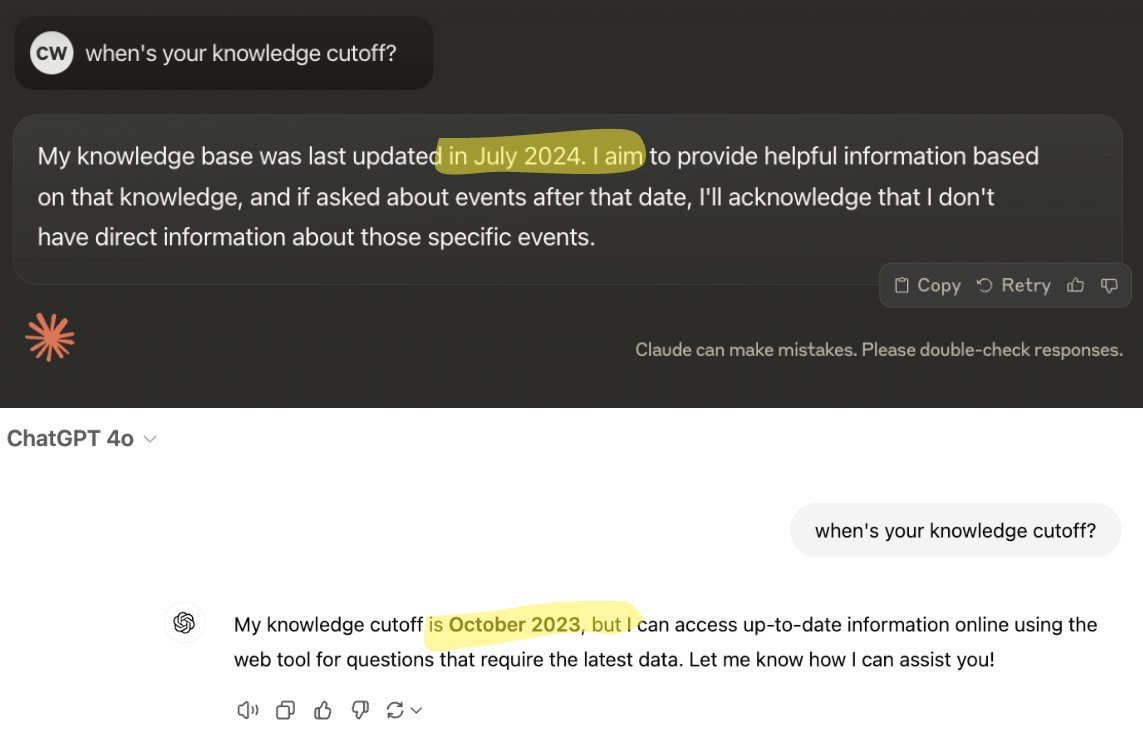
Why use #Claude over #ChatGPT? Claude’s got a knowledge cutoff that’s almost one year newer. In AI terms, that’s like a decade ahead, right?
-
Microsoft TRELLIS 3D Generation Model for Free Asset Creation
By
–
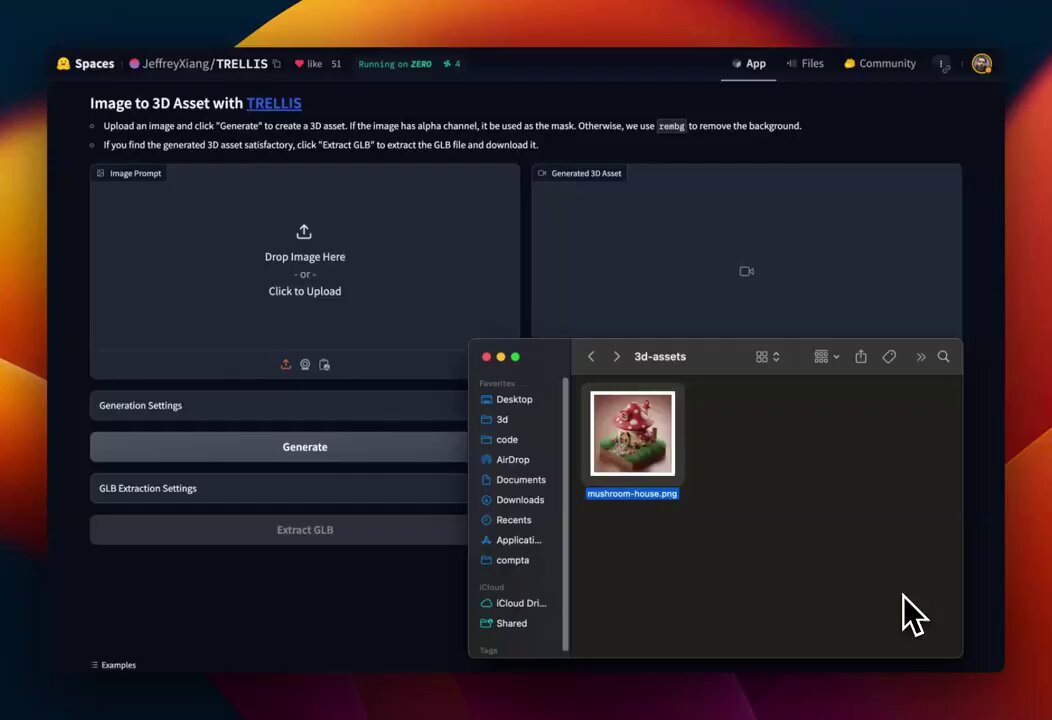
This is RICULOUSLY good, TRELLIS 3D Generation model by Microsoft! 🔥
— Vaibhav (VB) Srivastav (@reach_vb) 8 décembre 2024
Generate high-quality 3D assets from text or image prompts. Supports various formats like Radiance Fields, 3D Gaussians, and meshes
Available for FREE on Hugging Face! pic.twitter.com/V9VHdiAe8lThis is RICULOUSLY good, TRELLIS 3D Generation model by Microsoft! Generate high-quality 3D assets from text or image prompts. Supports various formats like Radiance Fields, 3D Gaussians, and meshes Available for FREE on Hugging Face!
-
Large Language Models Demonstrate Self-Improvement Capabilities
By
–
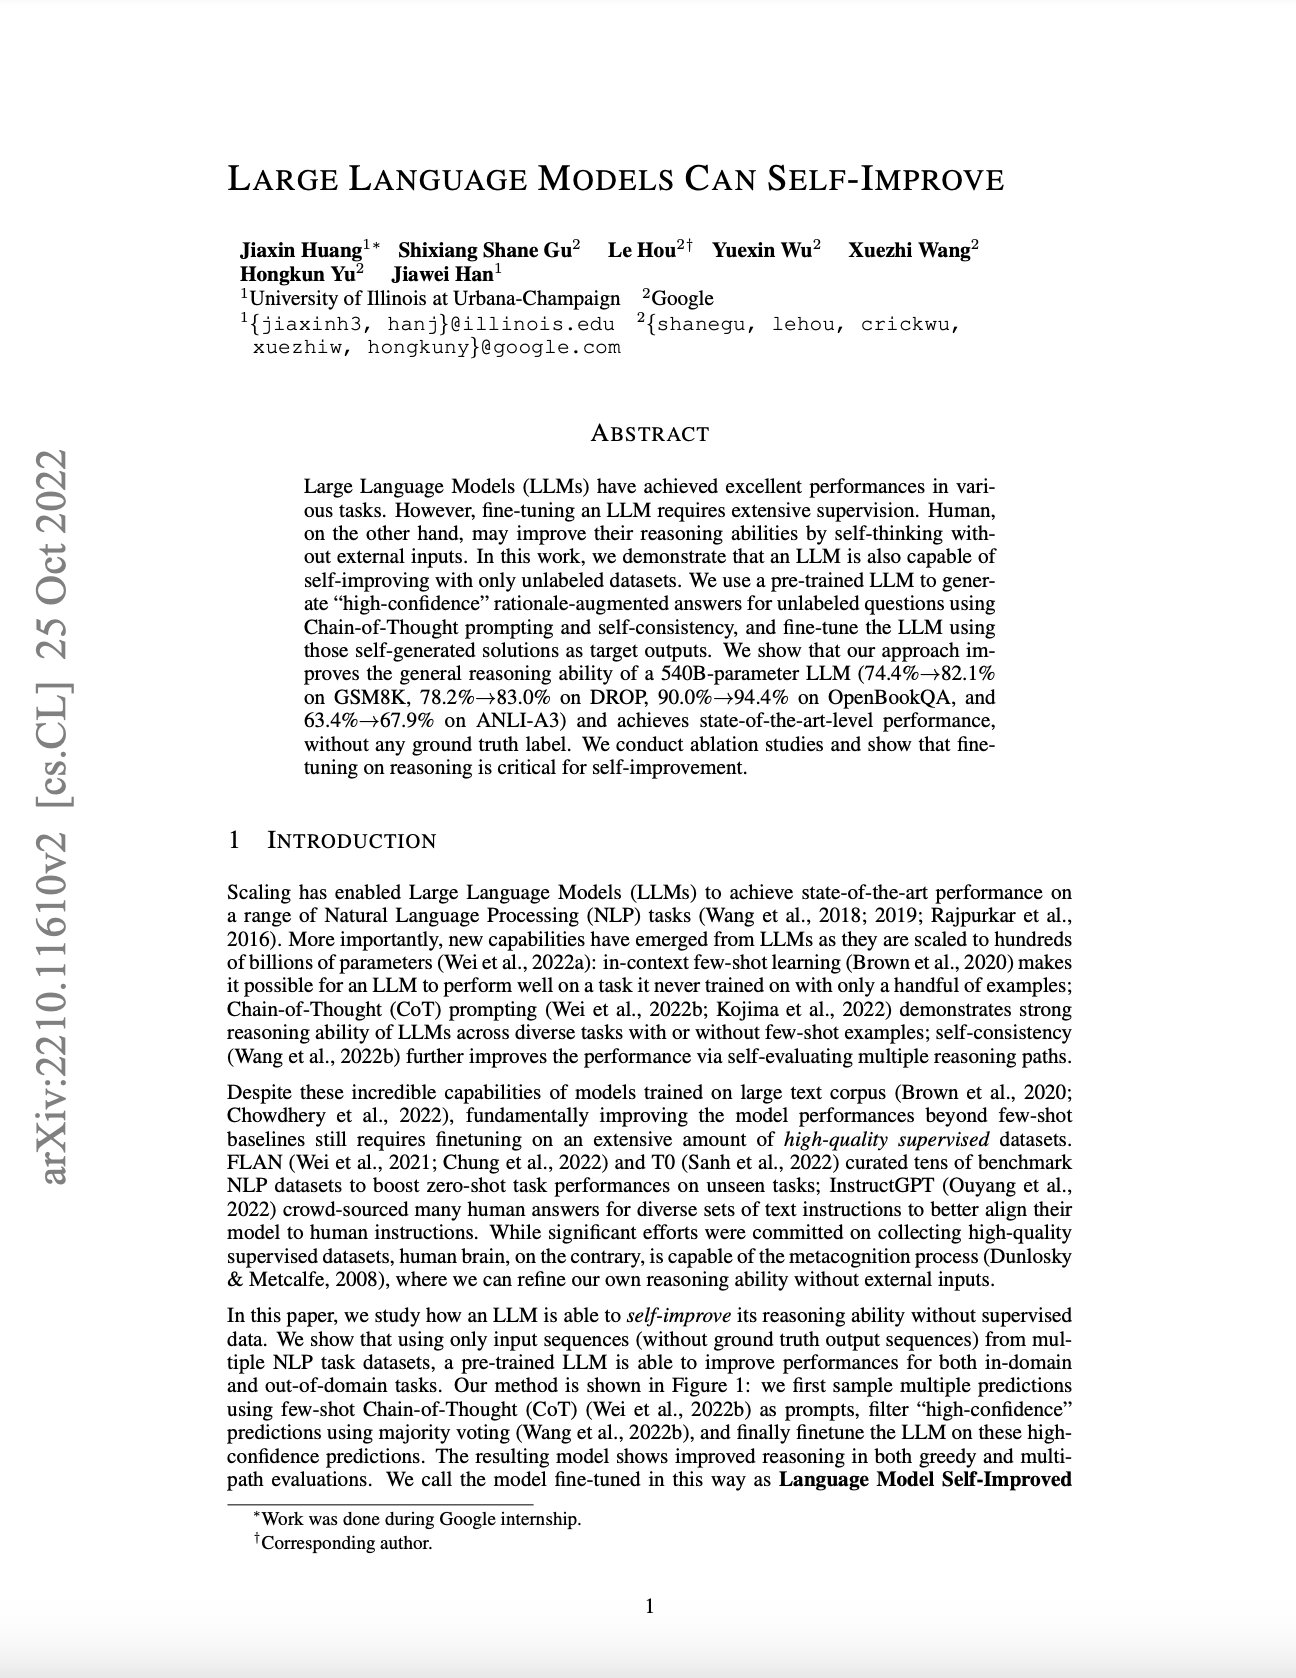
Large Language Models Can Self-Improve Huang et al.: https://
arxiv.org/abs/2210.11610 #ArtificialIntelligence #DeepLearning #MachineLearning -
24 Imperial AI Art Masterpieces Released on Blockchain
By
–
Ascend into the frontier of #CryptoAIArt ONLY 24 IMPERIAL MASTERPIECES REMAIN—each a sublime unity of code and transcendent vision, eternally etched into the blockchain. Verified Collection: http://
opensea.io/collection/mon
trealai
… Rare. Eternal. Unrivaled. #AIArt #MontrealAI #NFT -
Future LLMs as Justice Arbiters and Appeal Systems
By
–
Concretely, imagine that the next generation of LLMs gets good enough to render judgments about justice. Then people want to appeal to it as arbiter, etc.