The GAN is dead; long live the GAN! A Modern GAN Baseline https://
arxiv.org/abs/2501.05441 https://
github.com/brownvc/R3GAN HuggingFace:
GENERATIVE AI
-
Modern GAN Baseline: The GAN is Dead, Long Live the GAN
By
–
-
Train Your Own O1 Preview Model for Under $450
By
–
Sky-T1: Train your own O1 preview model within $450 https://
novasky-ai.github.io/posts/sky-t1/ -
Tesla and NVIDIA: Divergent Paths in AI Training Data Strategy
By
–
Why Tesla And NVIDIA Are Taking Different Paths To Train AI Systems The debate between #synthetic and #realworld #data is reshaping how companies approach #AI development, with industry giants like #NVIDIA and #Tesla taking opposing #strategies. Here, we explore the pros and
-

Enterprise AI/MLOps Platform for Executive Leaders and Data Teams
By
–
#AI / #CDO / #CTO / #CAIO execs! — You can use @AbacusAI
's state-of-the-art AI / #MLOps / #LLMOps Platform to run your own models at enterprise scale. Start here to learn more and accelerate your capabilities: http://
abacus.ai/mlops
——
#MachineLearning #DataScience #GenAI #LLMs -
Free Claude Mastery Guide from GodofPrompt
By
–
Want a FREE Claude Mastery Guide? Just click below: https://
godofprompt.ai/claude-mastery
-guide
… -
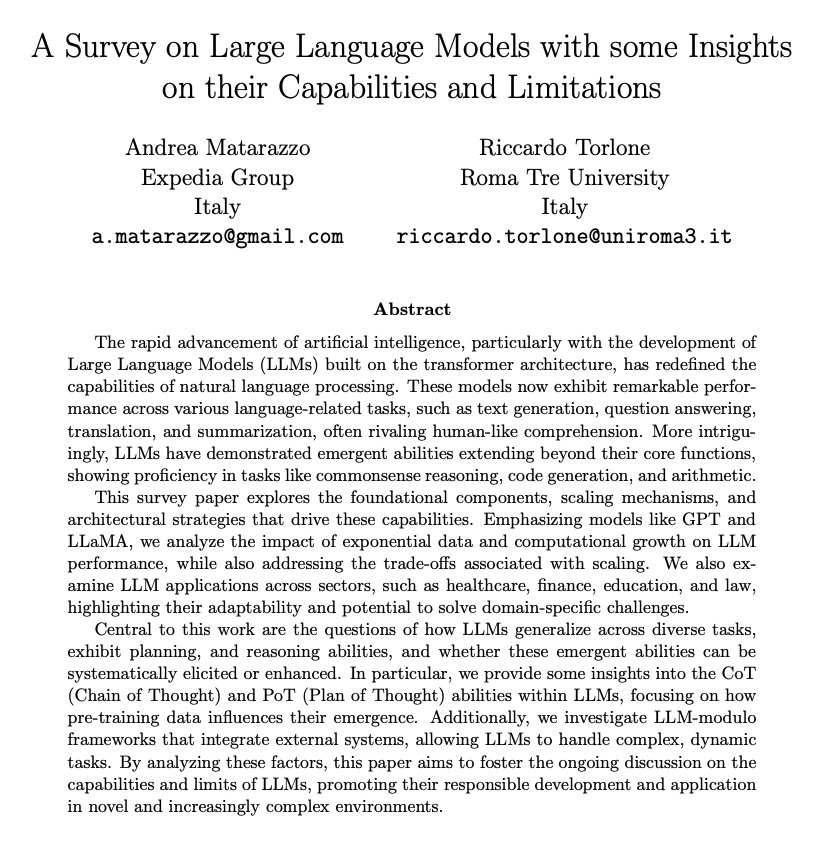
Survey on LLMs: Capabilities and Limitations Insights
By
–
10). A Survey on LLMs – a new survey on LLMs including some insights on capabilities and limitations.
-
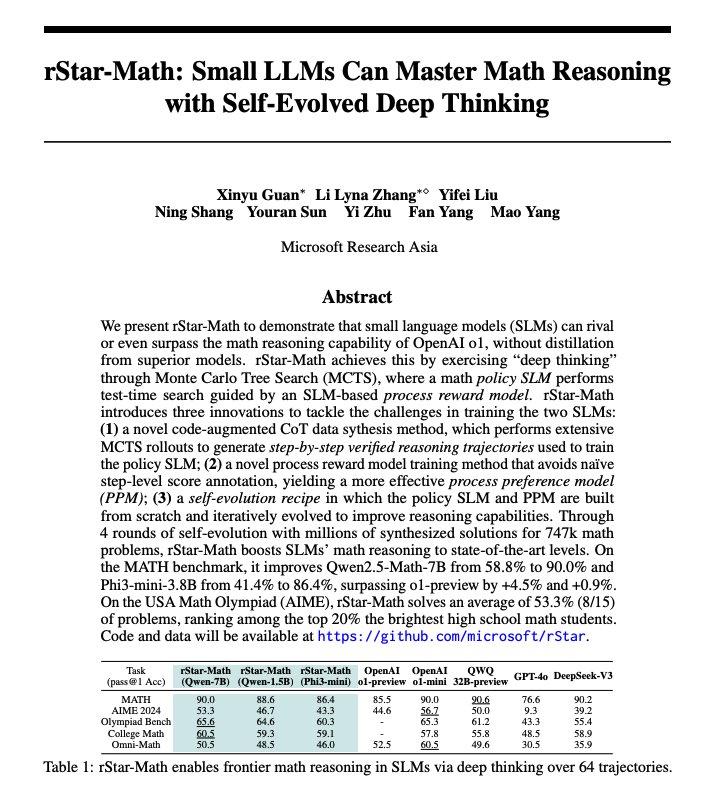
rStar-Math: Code-Augmented CoT for Enhanced Math Reasoning
By
–
6). rStar-Math – a new approach proposes three core components to enhance math reasoning: 1) a code-augmented CoT data synthesis method involving MCTS to generate step-by-step verified reasoning trajectories which are used to train the policy SLM…
-

Agent Laboratory: LLM Agents Advancing Research Process
By
–
2). Agent Laboratory – an approach that leverages LLM agents capable of completing the entire research process; the main findings are: 1) agents driven by o1-preview resulted in the best research outcomes…
-
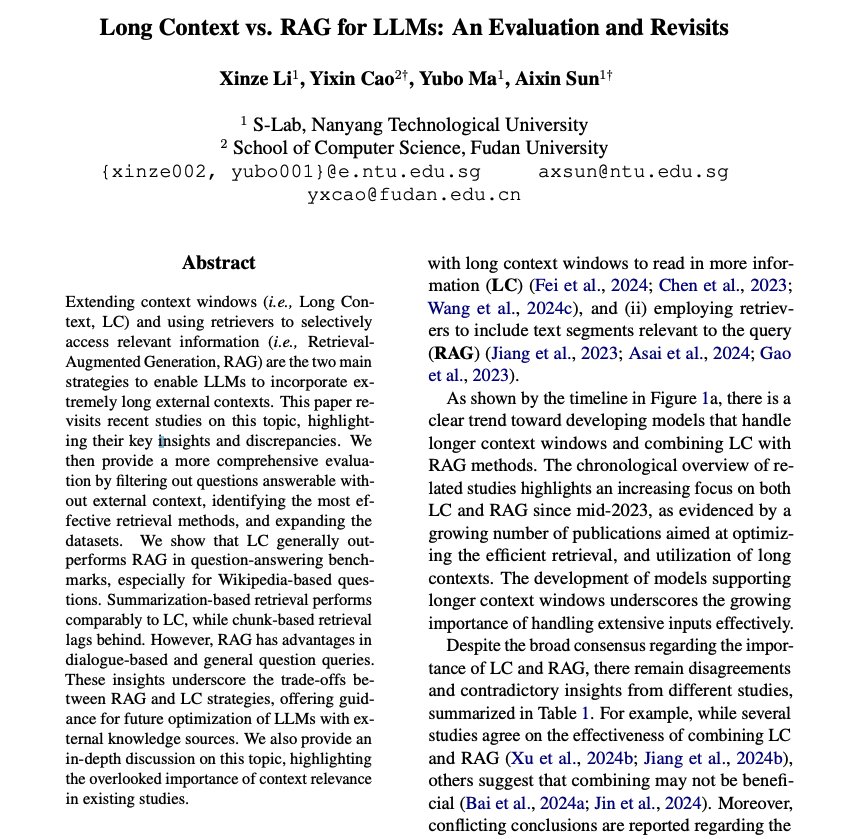
Long Context LLMs Outperform RAG in Question-Answering
By
–
3). Long Context vs. RAG for LLMs – performs a comprehensive evaluation of long context (LC) LLMs compared to RAG systems; the three main findings are: 1) LC generally outperforms RAG in question-answering benchmarks…
-

Search-o1 Framework Combines Reasoning Models with Agentic Search
By
–
4). Search-o1 – a framework that combines large reasoning models (LRMs) with agentic search and document refinement capabilities to tackle knowledge insufficiency…