That said, CAG has downsides:
• You need lots of memory as you fill the context window at every query.
• You cannot upload your whole million-rows dataset. It must be smaller than the current model's context window (e.g. 128k, 200k… tokens).
• You must host the model
GENERATIVE AI
-
Context-Augmented Generation: Memory and Scalability Limitations
By
–
-
CAG Approach Eliminates Retrieval Latency in AI Systems
By
–
Why is this CAG thing exciting:
• There's no retrieval latency. It just answers much faster.
• It's much simpler, with no complex retrieval pipelines or anything to build, really.
• Avoids retrieval-related mistakes (obviously, since there's no retrieval) -
CAG Preloads Knowledge into Long-Context Model Memory
By
–
On the other hand, CAG preloads all the necessary knowledge into a long-context model’s memory in its KV cache. A complicated way of saying the database here is pre-computed into the model's initial state.
-
RAG vs CAG: Understanding Two Augmented Generation Approaches
By
–
So you are wondering between these two options: Retrieval-Augmented Generation (RAG) Cache-Augmented Generation (CAG) What are those?
-
CAG vs RAG: New Approaches to Reduce AI Hallucinations
By
–
AI keeps evolving, and so do the ways we integrate knowledge into language models. CAG (Cache-Augmented Generation) is the new "hot sauce" for tackling hallucination and speeding up AI responses. But where does it fit alongside RAG (Retrieval-Augmented Generation)?
-
CAG versus RAG: Which AI approach do you need?
By
–
CAG, RAG, BAG, MAG, GAG… Okay, seriously, CAG or RAG? Which one do you need?
-
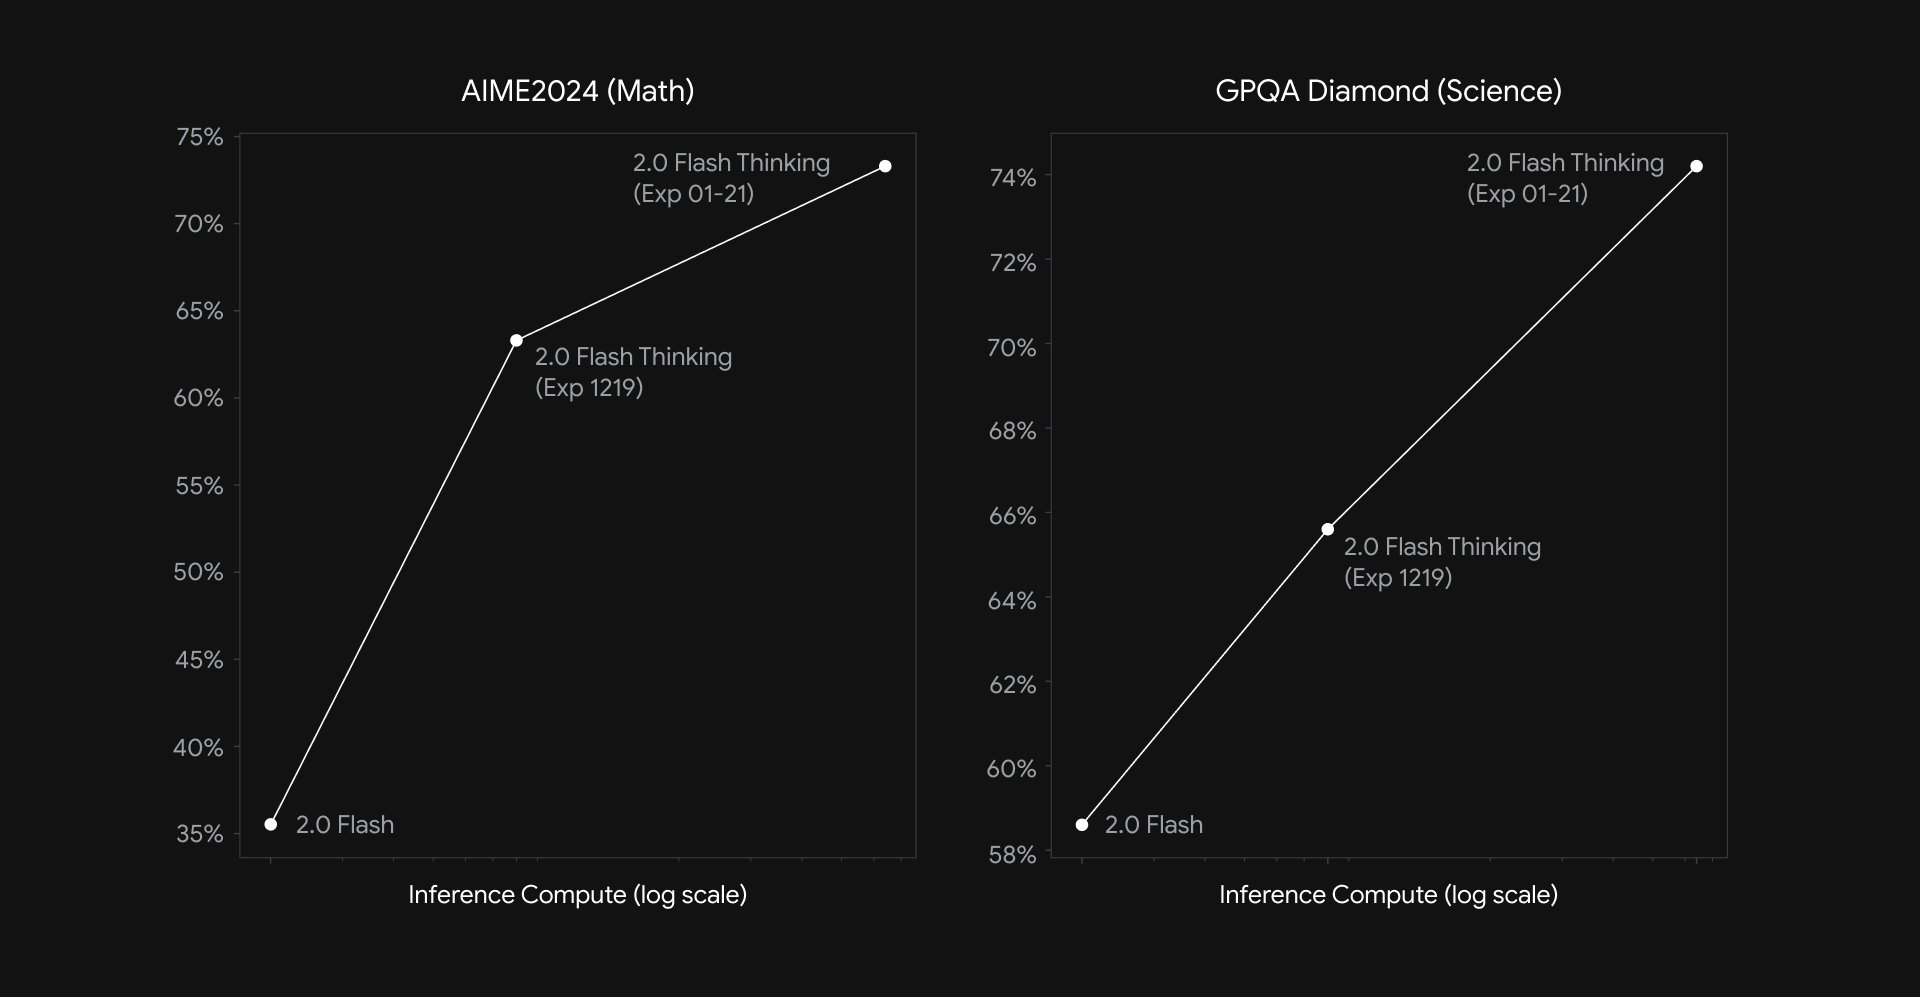
Gemini 2.0 Flash Thinking Achieves 73.3% AIME Math Score
By
–
Our latest update to our Gemini 2.0 Flash Thinking model (available here: https://
goo.gle/4jsCqZC) scores 73.3% on AIME (math) & 74.2% on GPQA Diamond (science) benchmarks. Thanks for all your feedback, this represents super fast progress from our first release just this past -
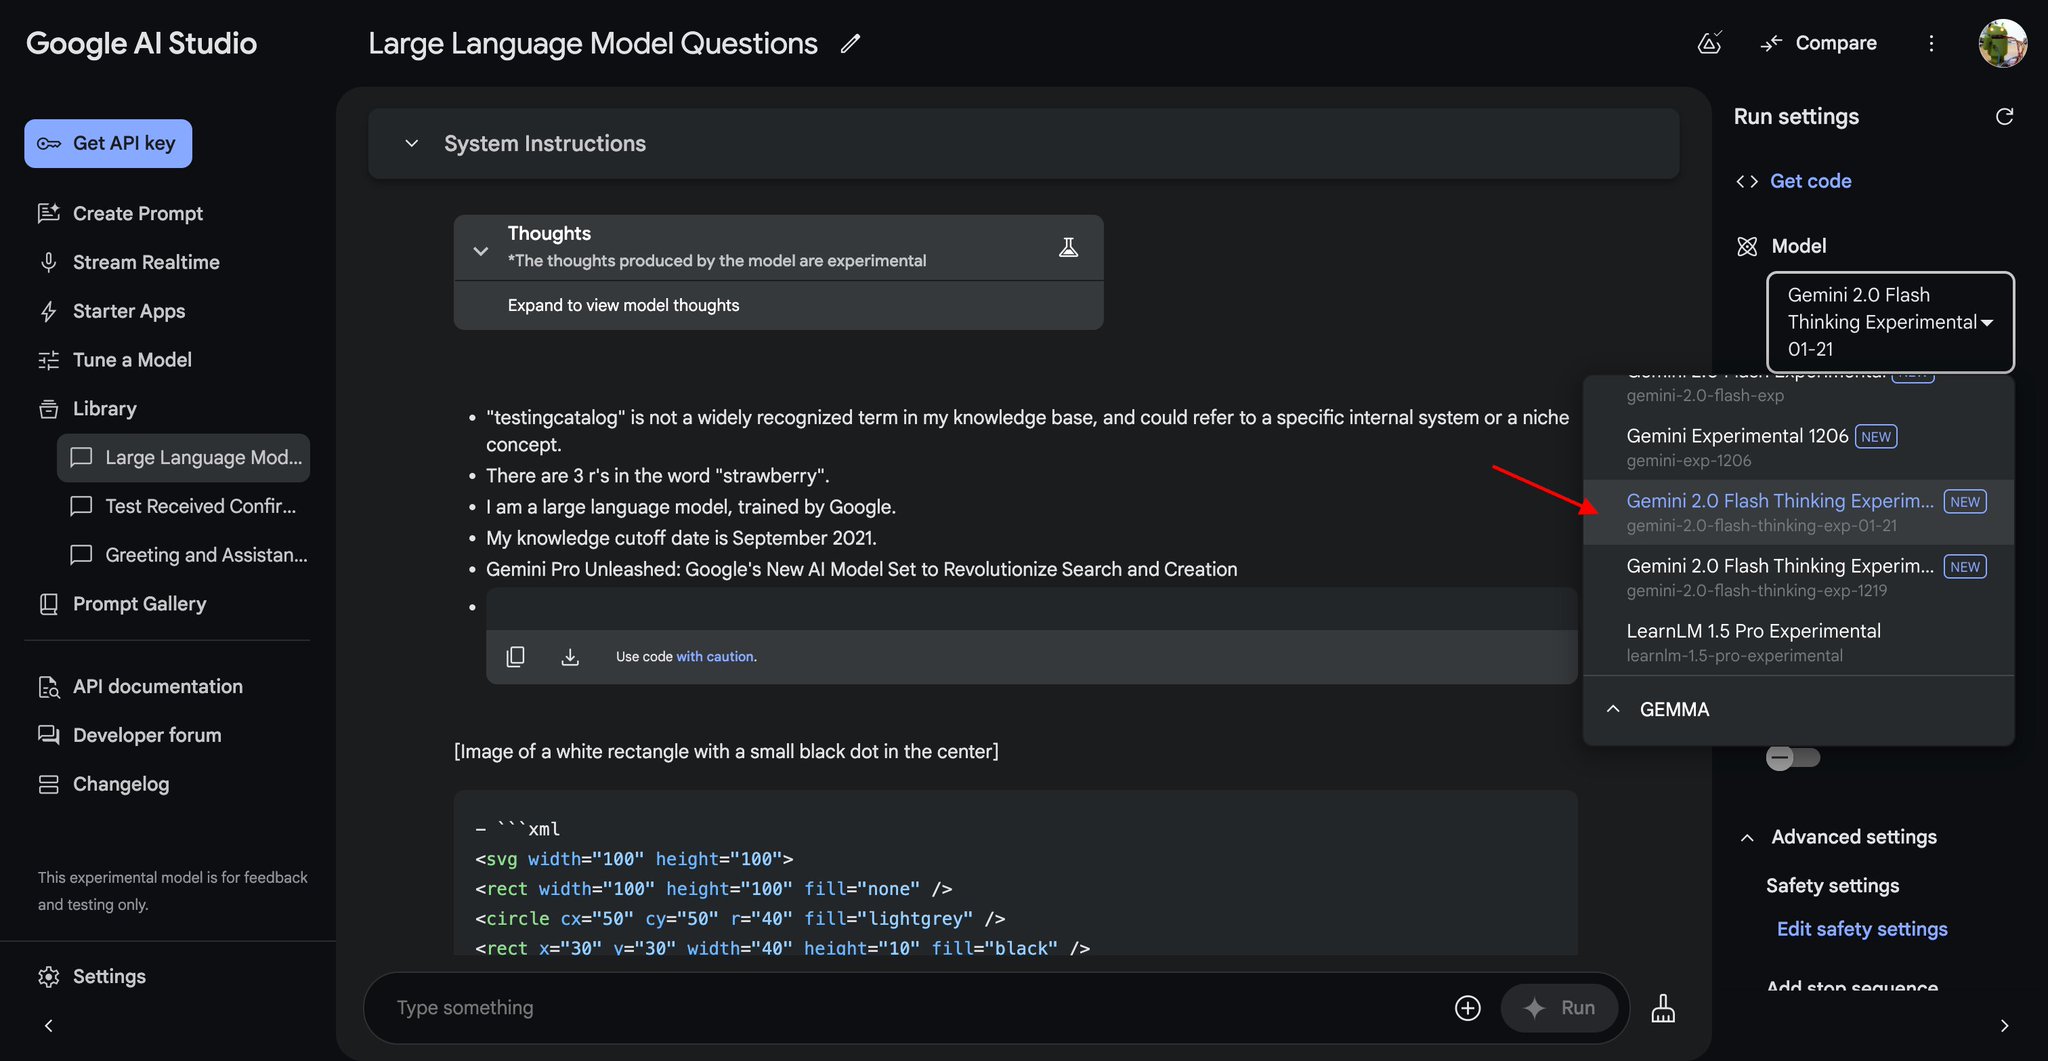
Google AI Studio launches Gemini 2.0 Flash
By
–
BREAKING : A new "Gemini 2.0 Flash Thinking Experience 0121" model is now available on Google AI Studio
-
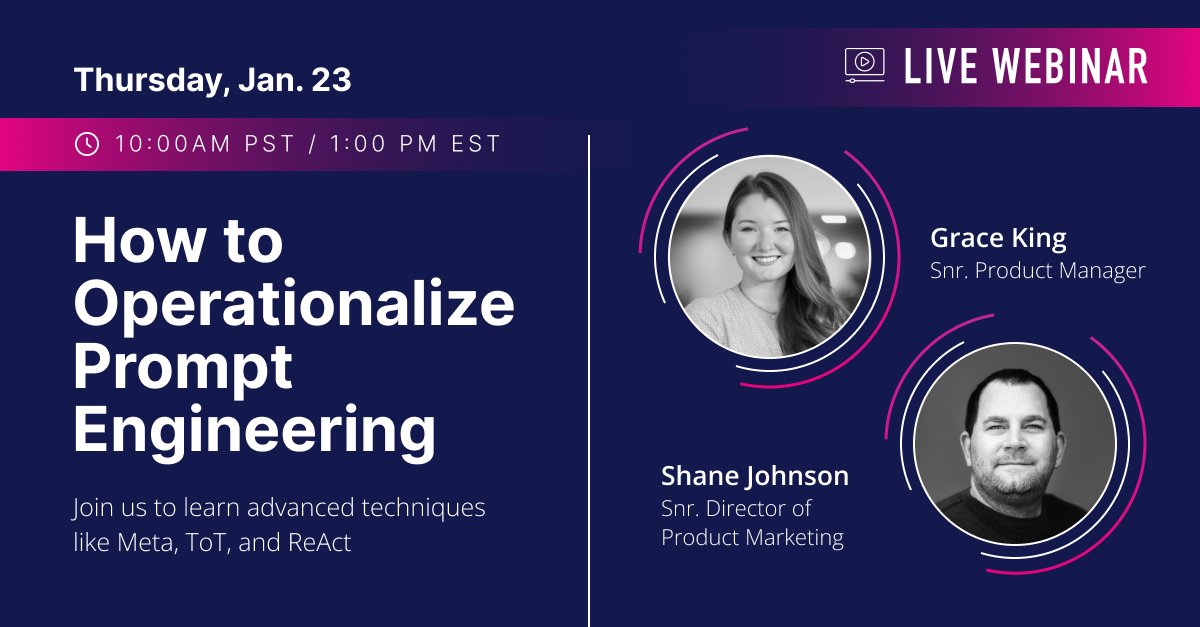
Unlock LLM Accuracy Through Prompt Engineering Operationalization
By
–
The lock : Needing to improve accuracy and quality of LLM responses.
The key : Operationalizing prompt engineering. Register for our upcoming webinar on how to unlock what you need with your #GenAI development process: https://
snkl.ai/promptengineer
ing
… #SnorkelAI #webinar -
Copilot Named Apple’s App of the Day
By
–
Honored to see Copilot selected as Apple's app of the day! If you haven't checked it out yet, maybe this is your sign