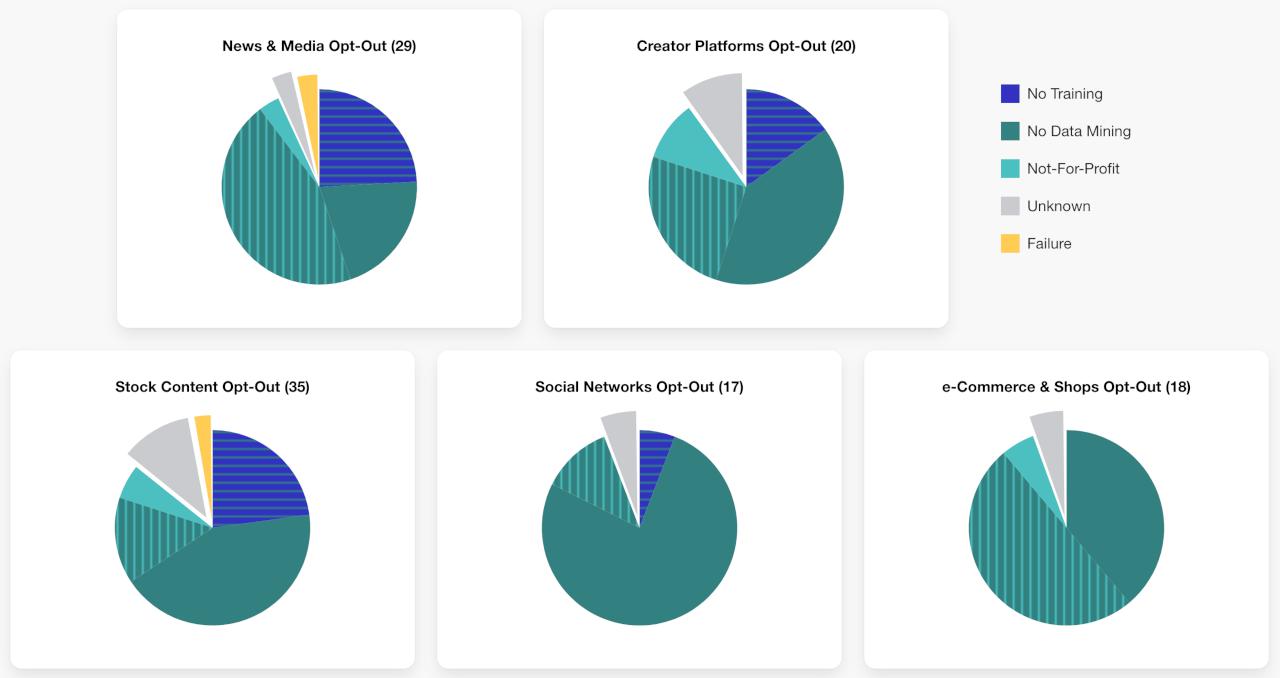
This has been a strange project to work on. Advocates and representatives on both sides of the debate don't really want to talk about © and opt-out, because the facts are inconvenient from both perspectives… What's necessary for this conversation to happen?
GENERATIVE AI
-
IBM Granite 3.1: New AI Features for Enterprise Workflows
By
–
New #AI Features Unveiled—Building Safer, Smarter Workflows@IBM Granite 3.1 is here, delivering powerful performance, long-context capabilities, and so much more. Discover how it’s redefining possibilities in enterprise AI.
— Ronald van Loon (@Ronald_vanLoon) 5 février 2025
Learn how it’s changing the game:… pic.twitter.com/J5GtlxVaX9New #AI Features Unveiled—Building Safer, Smarter Workflows @IBM Granite 3.1 is here, delivering powerful performance, long-context capabilities, and so much more. Discover how it’s redefining possibilities in enterprise AI. Learn how it’s changing the game:
-
GRPO: The Sputnik Moment for LLM Training Efficiency
By
–
The Sputnik Moment for AI?
GRPO could transform how LLMs are trained—making AI training more efficient, autonomous, and widely accessible. This is #AIforAll in action—bringing cutting-edge AI advancements to the global community. Do you think GRPO could change the future of -
DeepSeek Method Open-Source Implementation Market Impact
By
–
Disclaimer
This method was already detailed in the DeepSeek research paper—this is simply a well-executed open-source implementation. Any potential market impact on public companies should have already occurred or is currently in motion. #ArtificialIntelligence #LLMs -
Open Source Democratizes AI Innovation Across Researchers
By
–
The Power of Open Source
Billions of dollars in AI investments.
Thousands of research papers.
And now—condensed into just a few hundred lines of code. This is AI innovation at its finest—enabling researchers and developers worldwide to push AI forward faster than ever. -
GRPO Democratizes AI Training Without Human Reward Labels
By
–
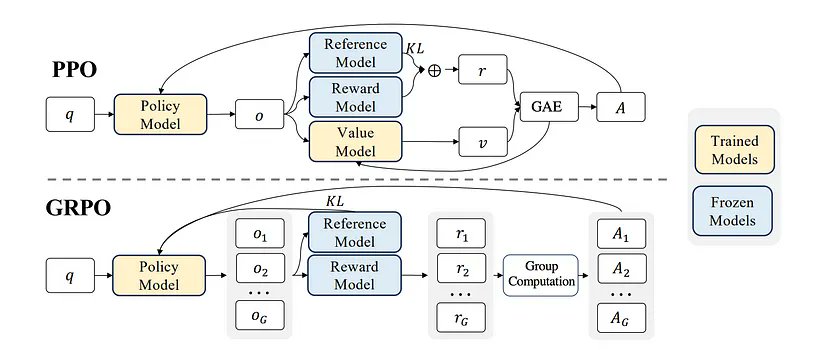
Why is this a game-changer? No human-labeled rewards → Fully autonomous learning Faster & more scalable RL → More efficient training Breakthrough in AI alignment → Smarter reward modeling
GRPO has the potential to democratize AI training—allowing for more -

GRPO: Grouped Reward Policy Optimization for RLHF Methods
By
–
What is GRPO (Grouped Reward Policy Optimization)? Most RLHF (Reinforcement Learning from Human Feedback) methods require: A separate reward model Labeled human preferences
GRPO removes these bottlenecks by dynamically estimating rewards directly from a group of -
DeepSeek R1 GRPO Open-Sourced: Revolutionary LLM Training
By
–
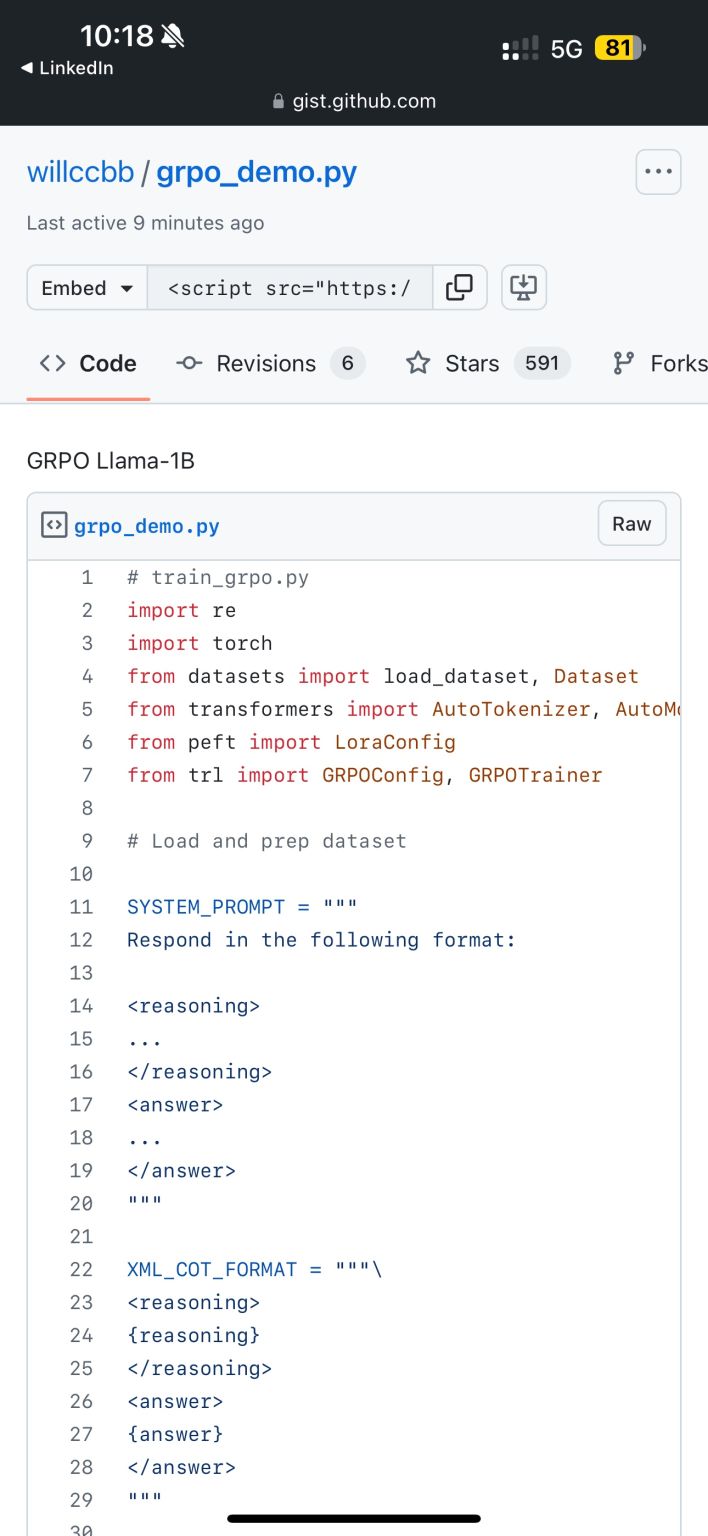
Day 8 – 25 Days of AI for ALL in 2025 DeepSeek R1’s GRPO is now fully open-source! A major breakthrough in LLM training—no separate reward models, no labeled data, just pure RL. More efficient, scalable & autonomous. Huge kudos to @deepseek_ai & thanks to
-
Baichuan-Omni-1.5 Surpasses GPT-4o Mini in Multimodal Processing
By
–
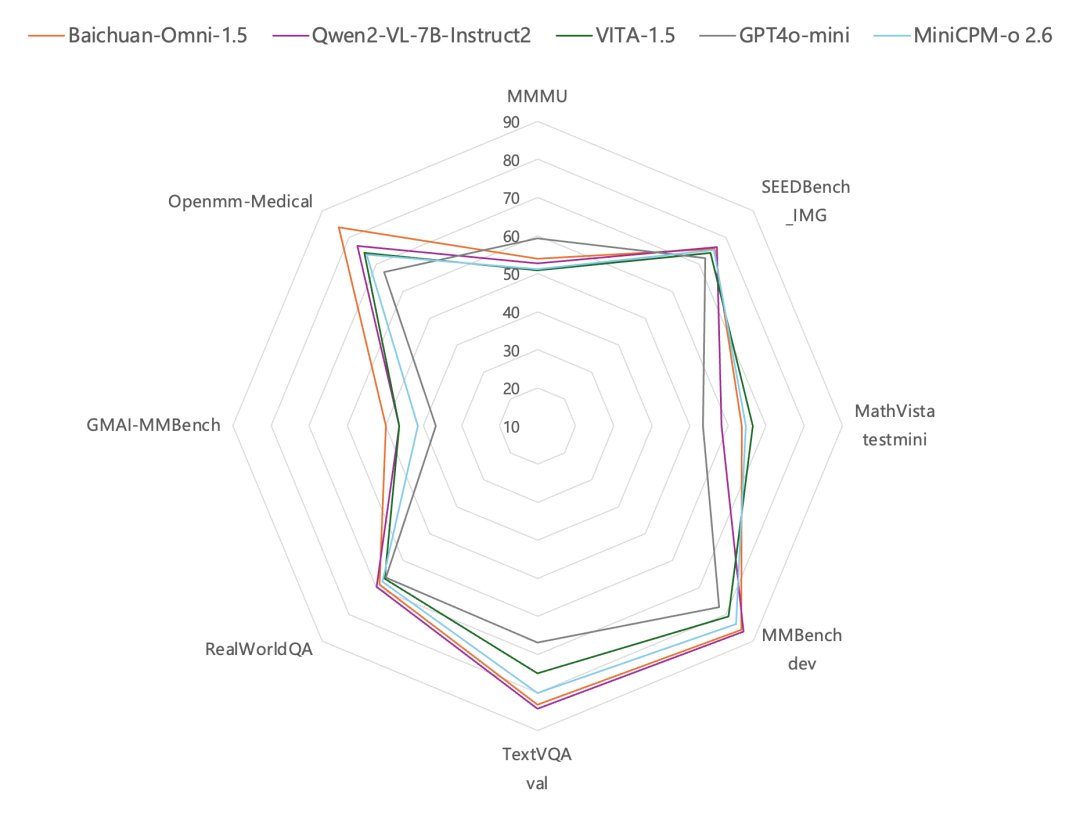
In terms of visual, speech, and multi-modal streaming processing, Baichuan-Omni-1.5 supasses GPT-4o mini, and its leading edge is even more pronounced in the field of multi-modal medical applications.
-
Baichuan Launches Omni-1.5 Multimodal Open-Source Model
By
–
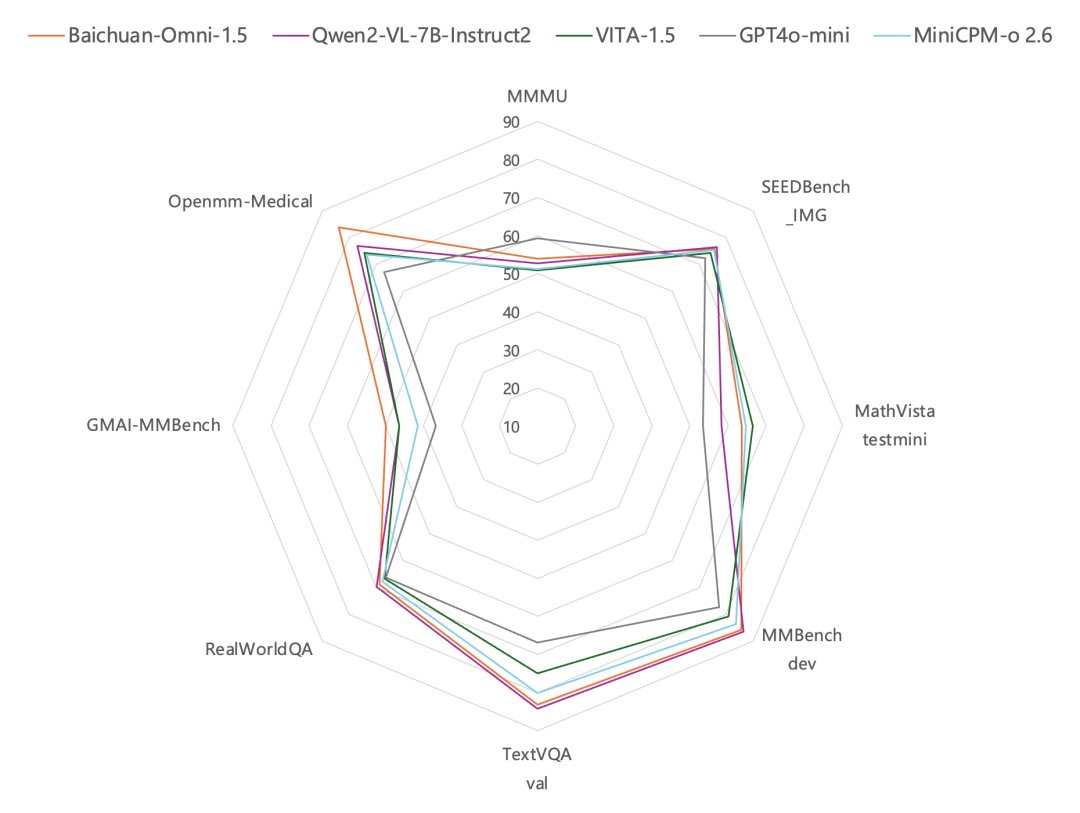
We launched Baichuan-Omni-1.5 open-source omni-modal large model. It not only supports omni-modal understanding of text, image, audio, and video, but also has dual modalities generation capabilities for both text and audio.