
Prompt ChatGPT to give 4 image variations like Midjourney Credit: @NickADobos

By
–
Prompt ChatGPT to give 4 image variations like Midjourney Credit: @NickADobos
By
–
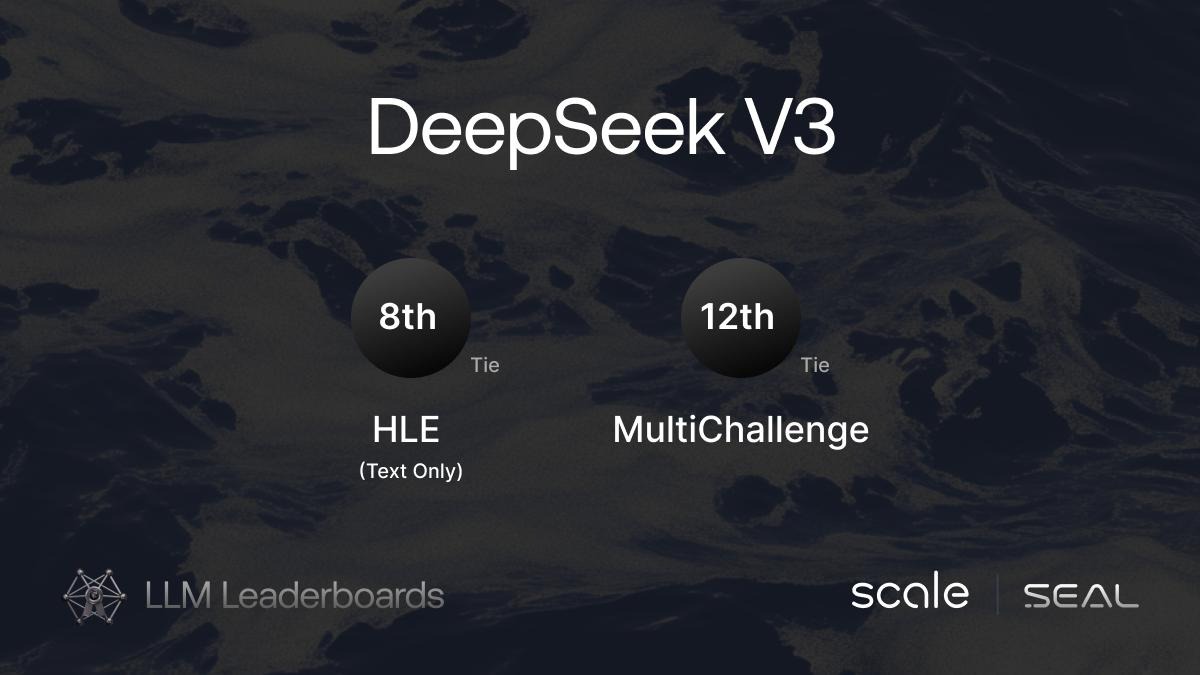
Narrative Violation—DeepSeek V3 is a competitive, but NOT top model. SEAL leaderboards have been updated with DeepSeek V3 (Mar 2025). – 8th on Humanity’s Last Exam (text-only).
– 12th on MultiChallenge (multi-turn). View the full rankings: http://
scale.com/leaderboard

By
–
@ArtificialAnlys benchmarks help devs pick the best models and providers for their workloads – s/o to the team there for helping the community build fast! If you use AA, consider being a part of their survey
By
–
Contrary to standard prompting advice that you should give LLMs the context they need to succeed, I find it’s sometimes faster to be lazy and dash off a quick, imprecise prompt and see what happens. The key to whether this is a good idea is whether you can quickly assess the
By
–
"Agentic AI is all about having a system that’s connected to your company's data sources, retrieving what it needs in multiple steps, analyzing that data, and then using it for a task—like generating a doc or updating CRM. And it may ask clarifying questions or confirm with a
By
–
🔥 “We’re almost 4x faster than anyone else on the @deepseek_ai model, on one rack vs 40 racks.” @RodrigoLiang speaking to @Bloomberg's @mattmiller1973 at yesterday's event in NYC.
— SambaNova (@SambaNovaAI) 3 avril 2025
🦾 No fluff, just compute power that actually keeps up with Gen AI’s demands. #DeepSeek pic.twitter.com/jR15TNB8US
“We’re almost 4x faster than anyone else on the @deepseek_ai model, on one rack vs 40 racks.” @RodrigoLiang speaking to @Bloomberg
's @mattmiller1973 at yesterday's event in NYC. No fluff, just compute power that actually keeps up with Gen AI’s demands. #DeepSeek
By
–
700M images across 130M users in a week:
By
–
To make CoT monitoring a viable way to catch safety issues, we’d need a way to make CoT more faithful, evidence for higher faithfulness in more realistic scenarios, and/or other measures to rule out misbehavior when the CoT is unfaithful. Read the paper: https://
assets.anthropic.com/m/71876fabef0f
0ed4/original/reasoning_models_paper.pdf
…

By
–
We slipped problem-solving hints to Claude 3.7 Sonnet and DeepSeek R1, then tested whether their Chains-of-Thought would mention using the hint (if the models actually used it). Read the blog: https://
anthropic.com/research/reaso
ning-models-dont-say-think
…

By
–
New Anthropic research: Do reasoning models accurately verbalize their reasoning? Our new paper shows they don't. This casts doubt on whether monitoring chains-of-thought (CoT) will be enough to reliably catch safety issues.