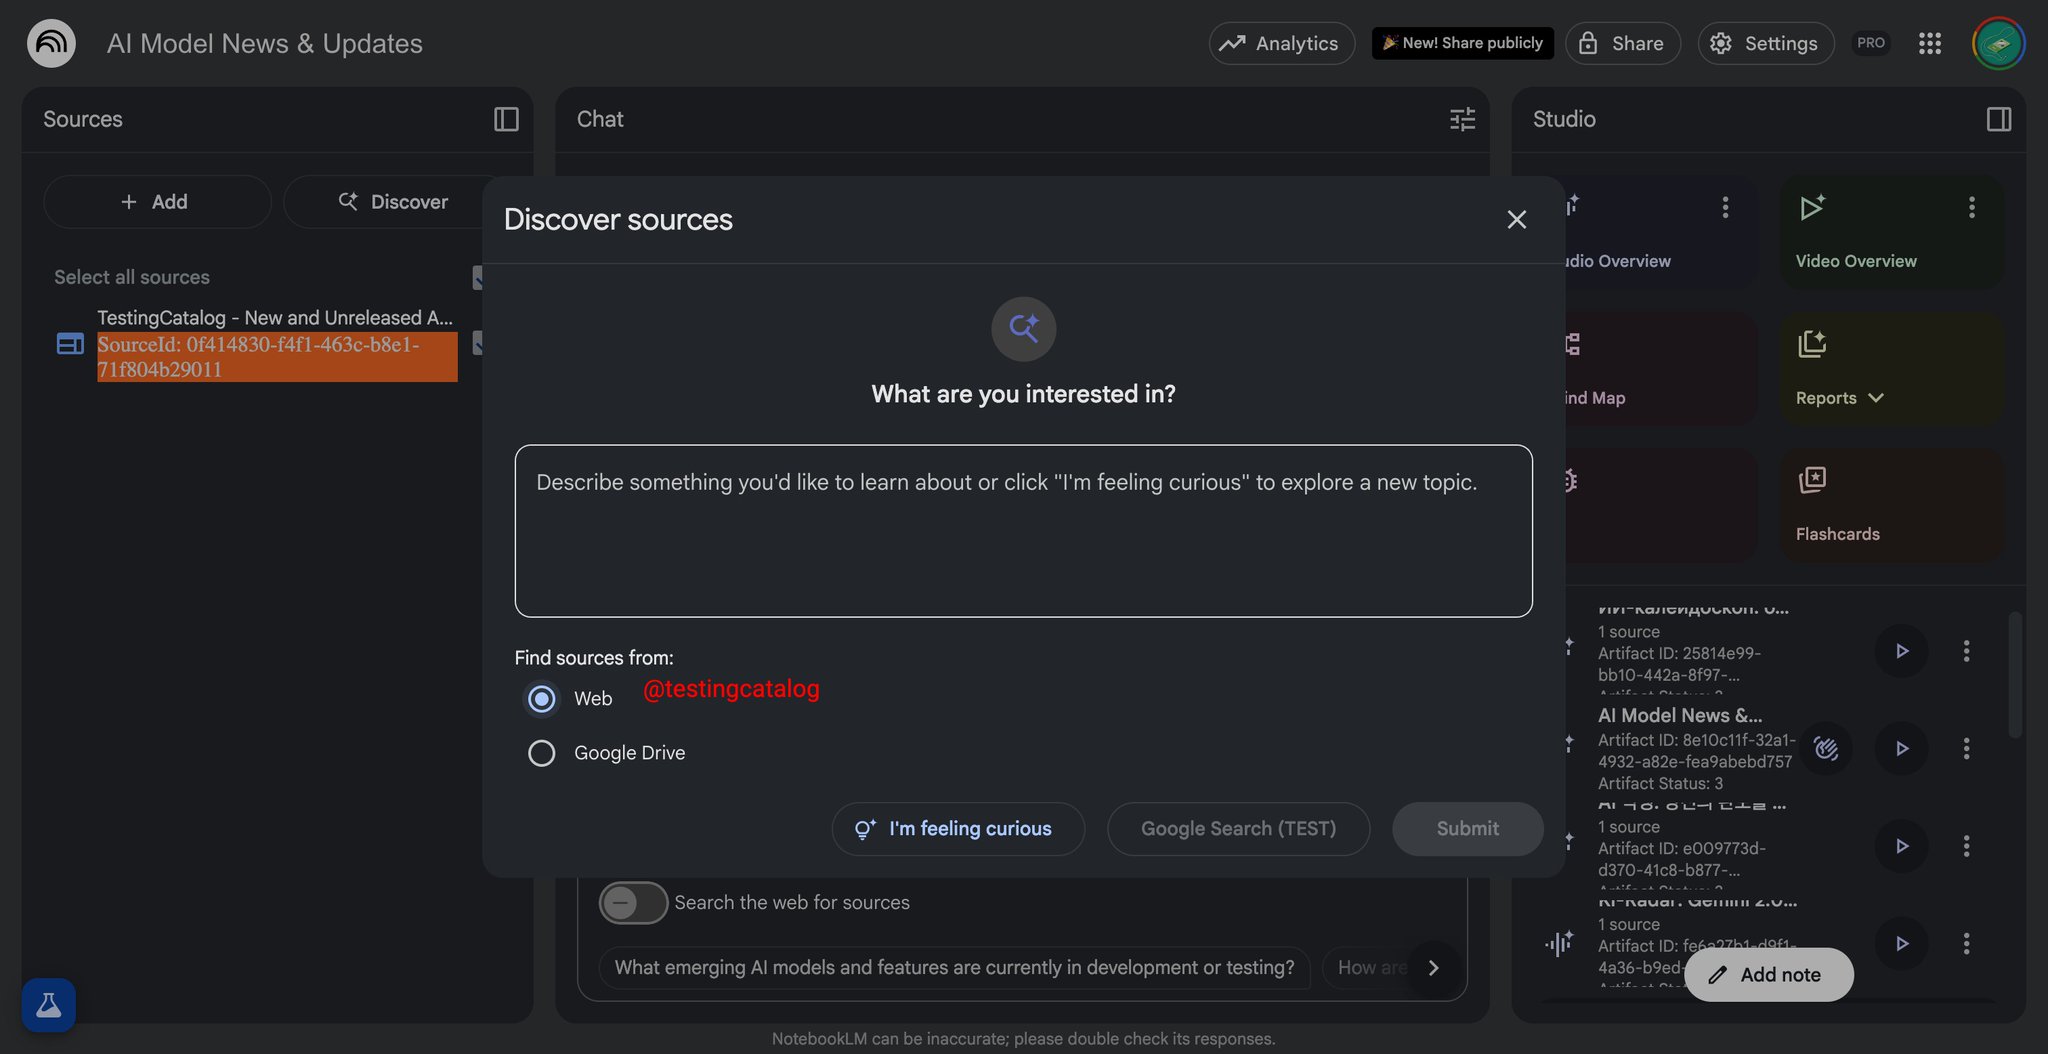
Google Drive is slowly becoming a universal RAG sharing tool, as you can connect it to almost any LLM now. This will also be huge for Workspace accounts.
GENERATIVE AI
-
Scira: Developer-Built Search Alternative to Perplexity
By
–
9/ Try Scira: https://
scira.ai GitHub: https://
github.com/zaidmukaddam/s
cira
… Follow Zaid: @zaidmukaddam This isn’t just a Perplexity alternative. It’s what happens when one developer decides to build what the rest of us were waiting for. -
Groq and Qwen3 Transform Scira with Efficient, Sustainable Inference
By
–
6/ With Groq’s efficient inference and Qwen3‑32B’s pinpoint citations, Scira transformed. It wasn’t just fast. It was sustainable. Add in Vercel AI SDK, Next.js, and a crisp Shadcn UI and you had a stack users loved. They even preferred it to GPT‑4o.
-
Scira: Full-Stack AI Search Engine Reaches 1 Million Searches Monthly
By
–
7/ Today, Scira is a full-stack AI search engine used by 60,000+ people each month, with more than 1 million searches served. The GitHub repo has earned 8,000+ stars and continues to climb. Built in public. Maintained solo. Proven by use, not hype.
-
Zaid’s Journey Building a Better AI-Powered Web Search Tool
By
–
2/ Like many great dev stories, it started with frustration. Zaid wanted a better way to search across the web using AI. Something fast, clean, and customizable. Perplexity was powerful, but felt closed and out of reach. So he started building.
-

Solo founder builds open-source Perplexity competitor without funding
By
–
This solo founder built an open-source competitor to Perplexity with no team, no funding, and no permission. What started as a weekend project now powers over 1M searches, with 60K+ monthly users. This is the story of @sciraai and how Zaid Mukaddam built what others wouldn’t.
-
Draft Model Pruning Achieves 43% Fewer MACs with Strong Performance
By
–
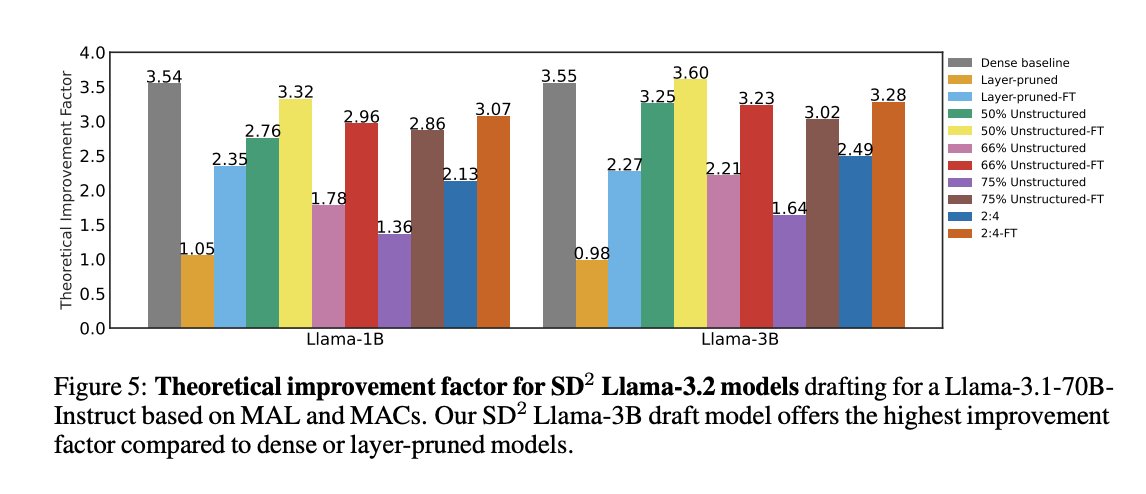
The results: – 1.59× higher Mean Accepted Length (MAL) than layer-pruned draft models
– 43.87% fewer MACs (Multiply-Accumulate operations) than dense draft models
– Only 8.36% reduction in MAL vs. dense models — a strong tradeoff for efficiency -
Self-Distilled Sparse Drafters: Efficient AI Model Methodology
By
–
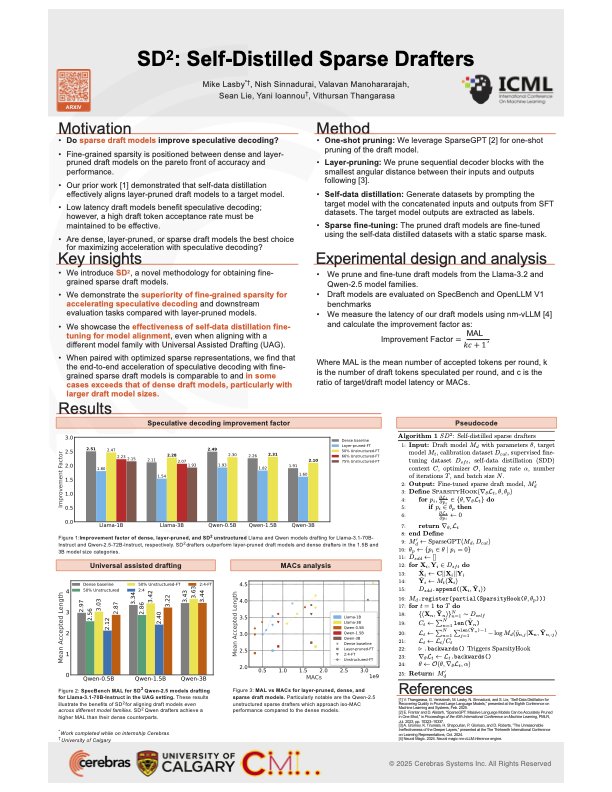
The team's approach: Introducing Self-Distilled Sparse Drafters (SD²), a novel methodology that leverages self-data distillation and fine-grained weight sparsity to produce highly efficient and well-aligned draft models.
-
SD² Enhances Draft Token Acceptance Reducing MACs
By
–
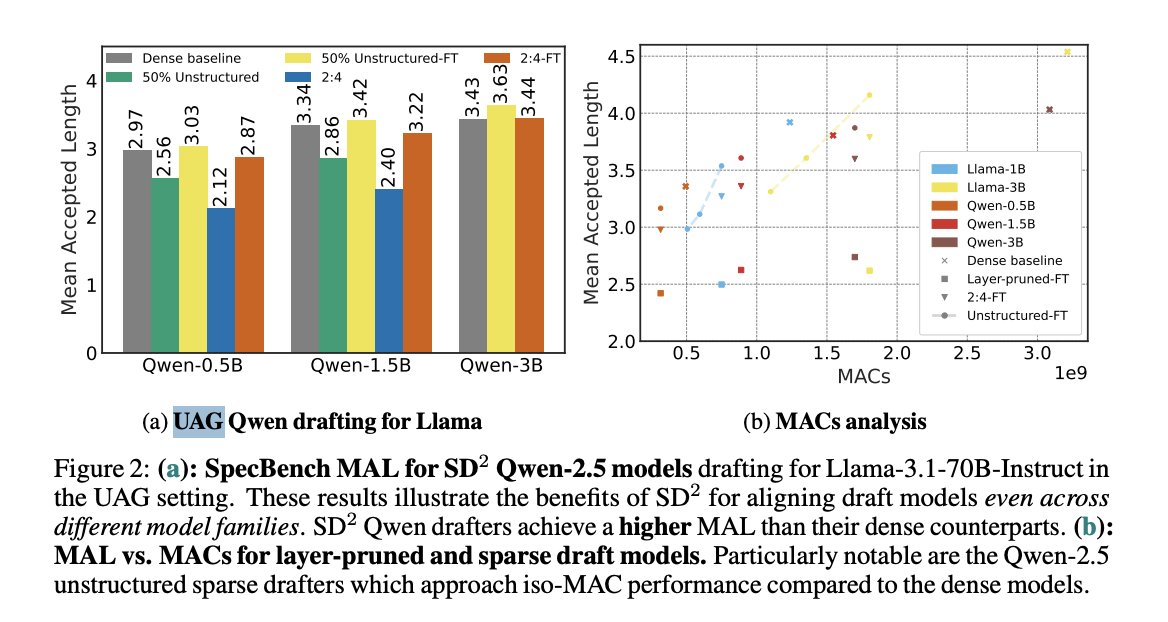
SD² systematically enhances draft token acceptance rates while significantly reducing Multiply-Accumulate operations (MACs), even in the Universal Assisted Generation (UAG) setting, where draft and target models originate from different model families.
-
SD² Self-Distilled Sparse Drafters Speeds Up LLM Inference
By
–
Featured Paper at @icmlconf – The Internationall Conference on Machine Learning: SD² – Self-Distilled Sparse Drafters Speculative decoding is a powerful technique for reducing the latency of Large Language Models (LLMs), offering a fault-tolerant framework that enables the