Top stories in AI today: – Anthropic's Skills teach Claude workflows
– Global AI concern outweighs excitement
– Generate presentations with Claude Skills
– OpenAI recruits black hole physicist
– 4 new AI tools, community workflows, and more Read more: https://
therundown.ai/p/claude-gains
-new-skills
…
GENERATIVE AI
-

Claude Skills, AI concerns, and new tools launched today
By
–
-

Mitigating LLM Repetition via Probabilistic Sampling
By
–
LLMs have a repetition problem. ask for a joke → same joke every time ask to roll dice → always returns 4 ask for creative ideas → predictable garbage Try this instead: Generate 5 responses with their corresponding probabilities, sampled at random from the tails of the
-
ScaleRL: Key Components Explained
By
–
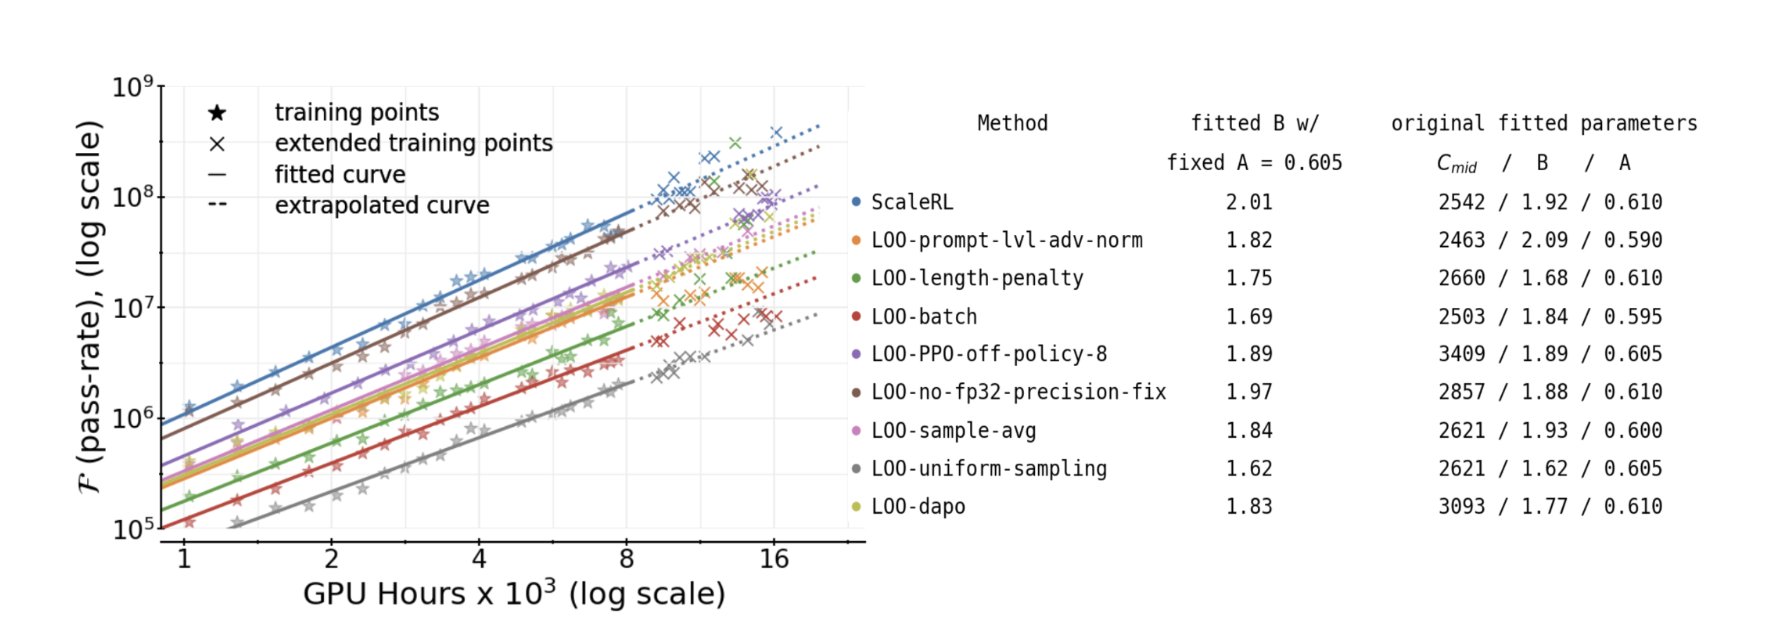
ScaleRL isn’t magic. It’s a recipe of small, proven ingredients: – Pipeline-RL async setup
– FP32 logits for stable gradients
– CISPO loss (clipped importance sampling)
– Prompt-level averaging
– Batch-level normalization
– No-Positive-Resampling (drop “too easy” prompts) -
ScaleRL outperforms in RL scaling tests
By
–
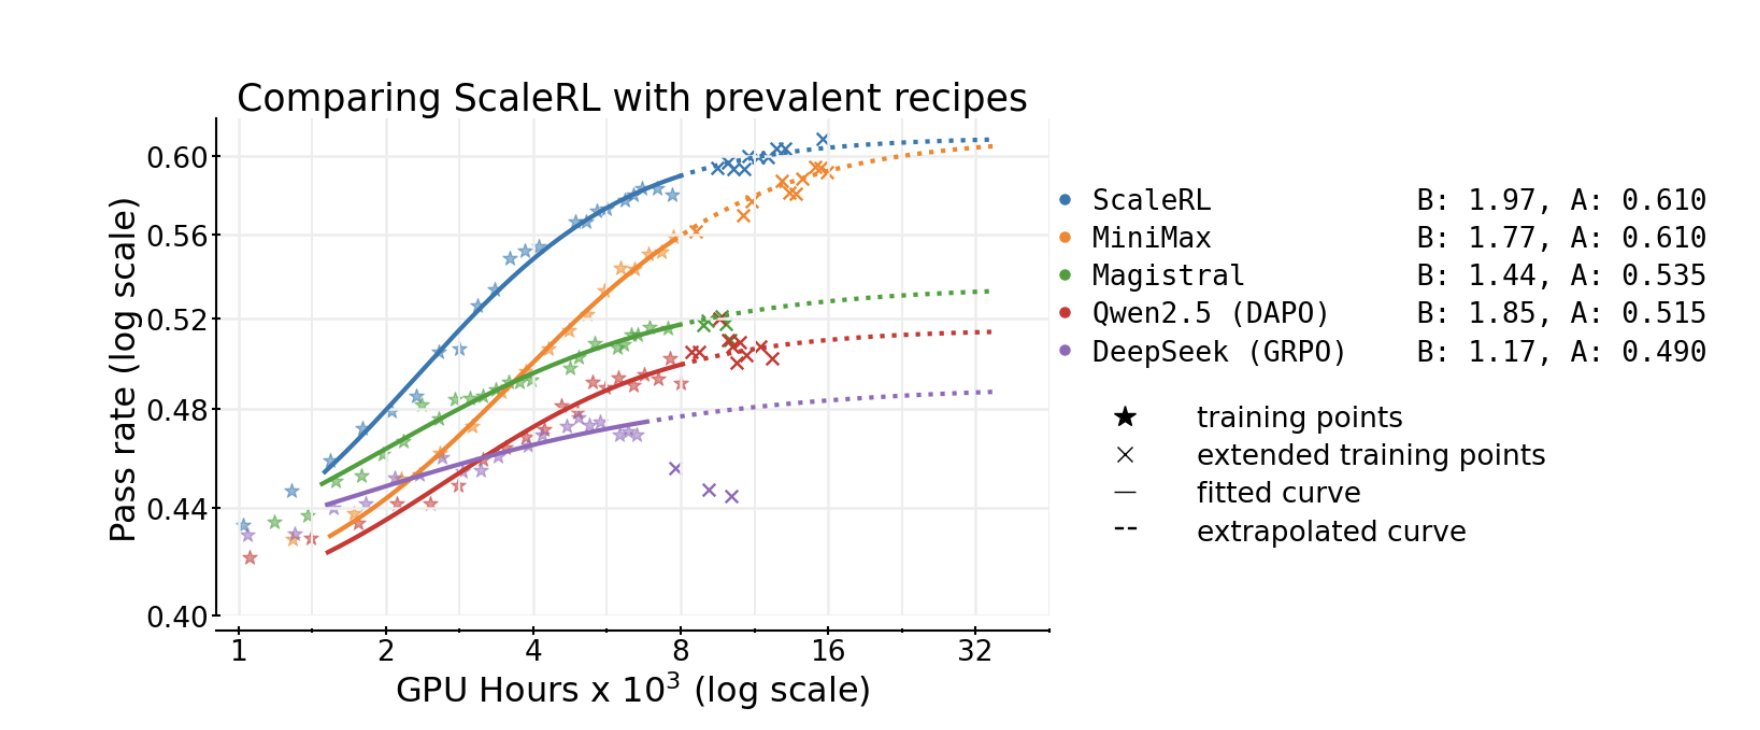
They tested this with 400,000 GPU hours across multiple RL recipes: DeepSeek (GRPO)
Qwen (DAPO)
Magistral
Minimax Result: only ScaleRL showed a stable, predictable trajectory. The others broke scaling laws entirely their curves collapsed. -
Meta’s ScaleRL reveals predictable RL scaling laws
By
–
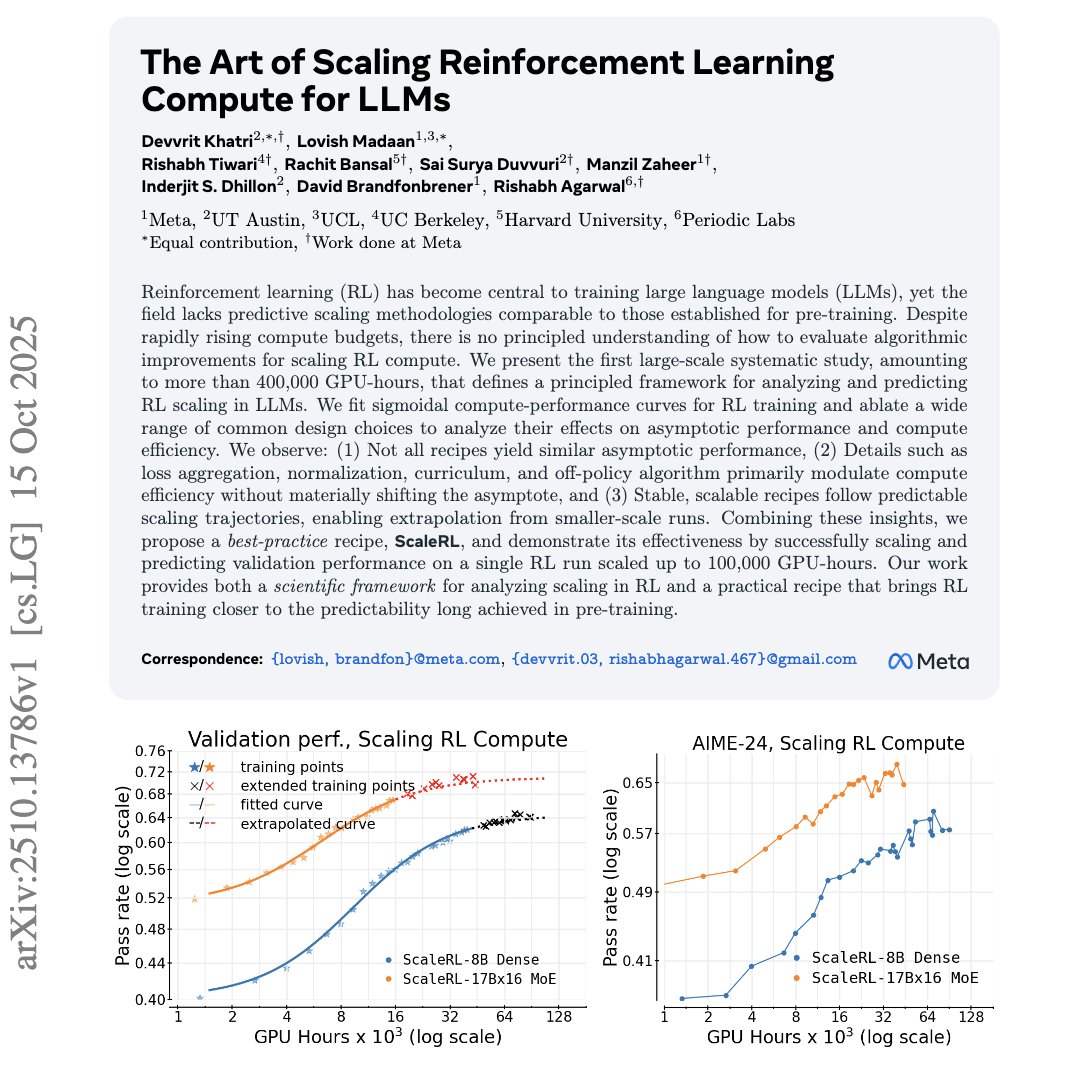
Holy shit… Meta just cracked the art of scaling RL for LLMs. For the first time ever, they showed that "reinforcement learning follows predictable scaling laws" just like pretraining. Their new framework, 'ScaleRL', fits a sigmoid compute-performance curve that can forecast
-

OpenAI Plans Aggressive Expansion With Advanced Future Models
By
–
@sama "We wouldn't be going this aggressive if all we had was today's model. We get to see it a year or two in advance"
— Peter Gostev (@petergostev) 17 octobre 2025
"We will partner with a lot of people: from electrons to the model distribution."
"You should expect much more from us in the coming months" https://t.co/zoncWJV13a pic.twitter.com/FxEYdoBog4@sama "We wouldn't be going this aggressive if all we had was today's model. We get to see it a year or two in advance" "We will partner with a lot of people: from electrons to the model distribution." "You should expect much more from us in the coming months"
-
MagicPathAI: Interactive AI Tool Remake and Recreation
By
–
This is so great! I had to remade it in @MagicPathAI
— Pietro Schirano (@skirano) 17 octobre 2025
Fully interactive. pic.twitter.com/k67chsbogCThis is so great! I had to remade it in @MagicPathAI Fully interactive.
-
AI Innovation Growth: Why Progress Isn’t Guaranteed
By
–
AI And The End Of Progress? Why Innovation May Be More Fragile Than We Think #ArtificialIntelligence could trigger a new wave of #growth or stall #innovation if managed poorly. Economist Carl Benedikt Frey explains why progress is never automatic and why the way we develop and
-

Risk-based Policy Optimization Improves LLM Reasoning Through Reward Risk-Taking
By
–
RL keeps evolving! Now you can teach LLMs to reason better by rewarding risk-taking. Risk-based Policy Optimization (RiskPO) is a new reinforcement learning framework for post-training LLMs. Instead of averaging rewards like GRPO, RiskPO uses a Mixed Value-at-Risk objective
-

AI and physician de-skilling: Lancet analysis of solutions
By
–
Will A.I. lead to de-skilling of physicians?
And if so what can be done to preempt it? @tberzin and I address this in a new @TheLancet piece https://
thelancet.com/journals/lance
t/article/PIIS0140-6736(25)02075-6/abstract
…