ICYMI: At a recent seminar, AI pioneers Lucy Suchman and Terry Winograd discussed AI's past and present, exploring the lessons generative frictions offer as we navigate the challenges and possibilities of AI. Watch the recording here: https://
hai.stanford.edu/events/generat
ive-frictions-a-conversation-on-ai
…
GENERATIVE AI
-

AI Pioneers Discuss Generative Frictions and AI’s Future
By
–
-

Veo 3.1 tops video generation leaderboards with major improvements
By
–
Awesome to see Veo 3.1 top the LMArena video leaderboards by a large distance with big improvements over Veo 3.0 for text-to-video (+30) and image-to-video (+70)! Huge congrats to the team! Try it for yourself in http://
flow.google and the @GeminiApp -
Scaling AI Without Purpose: A Critique of Growth
By
–
Scaling just for the sake of it even if it produces nothing useful? Heh.
-

Leveraging Custom GPTs for Business Performance
By
–
Custom GPT Outputs power my business AI
Essential for tailored and efficient performance
• Fine-tune models
• Engineer prompts
• Embed data Click below to read more: https://
godofprompt.ai/blog/custom-gp
t-outputs-best-practices-for-businesses
… -
Maintaining stylistic consistency in AI-generated ingredient images
By
–
When creating ingredient images, try to create stylistically consistent images. If you use input images that are too disparate, the output may lead to a cut scene. For example, when generating a reference image, try using a prompt like: “Create the next scene in this storyboard,… pic.twitter.com/JmK9j735ur
— Google AI (@GoogleAI) 20 octobre 2025When creating ingredient images, try to create stylistically consistent images. If you use input images that are too disparate, the output may lead to a cut scene. For example, when generating a reference image, try using a prompt like: “Create the next scene in this storyboard,
-
Optimizing First and Last Frame AI Video Generation Techniques
By
–
Here are some really tactical ways to optimize the First and last frame capability:
— Google AI (@GoogleAI) 20 octobre 2025
— Make sure your prompt includes precise camera motion descriptions for smooth and creative transitions between the first and last frames.
— Or, you can simply include the word “transform” in… pic.twitter.com/pGGtgZMjWzHere are some really tactical ways to optimize the First and last frame capability: — Make sure your prompt includes precise camera motion descriptions for smooth and creative transitions between the first and last frames.
— Or, you can simply include the word “transform” in -
Scene Extension in Generative Video AI: Chaining Frames
By
–
Scene extension works by chaining: the last frame of the first video acts as the visual starting point for the next. This means that if your first video ends in music or background noise, the second video will maintain that audio consistency throughout.
— Google AI (@GoogleAI) 20 octobre 2025
Also, you can extend… pic.twitter.com/q7n2FXNfB0Scene extension works by chaining: the last frame of the first video acts as the visual starting point for the next. This means that if your first video ends in music or background noise, the second video will maintain that audio consistency throughout. Also, you can extend
-
Veo 3.1 Video Generation Model New Creative Control Features
By
–
Last week, we announced Veo 3.1 and a series of new features that give you more creative control over your video generations. Here are a few additional tips to make sure you’re using this new model to the fullest. After reading this thread, you can put your Veo skills to the
-

Deepfakes Threat: Technology, Entertainment, and Ethical Implications
By
–
The Growing Threat of Deepfakes: Entertainment vs. Truth 🤔🔍 In an age where misinformation spreads faster than ever, #deepfakes have become a major concern, especially on social media. The #technology is advancing so rapidly that it’s getting harder to distinguish between what’s real and what’s fabricated. But here's the most alarming part: we enjoy these fakes. 🎙️ In this episode of Human X Machine, @TamaraMcCleary joins Christopher Lomas to discuss the dangers of deepfakes and the ethical implications they bring. They explore: 🔹 How deepfakes thrive on social platforms, going viral despite their deception 🔹 The challenge of detecting deepfakes as they become increasingly sophisticated 🔹 The willingness of people to overlook the truth for the sake of entertainment and sensationalism 🎧 Listen to the full conversation here: Apple: podcasts.apple.com/gb/podcas… Spotify: open.spotify.com/episode/6ZW… #AIEthics #TechForGood #SocialMediaRisks #DigitalDeception
→ View original post on X — @tamaramccleary, 2025-10-20 14:07 UTC
-
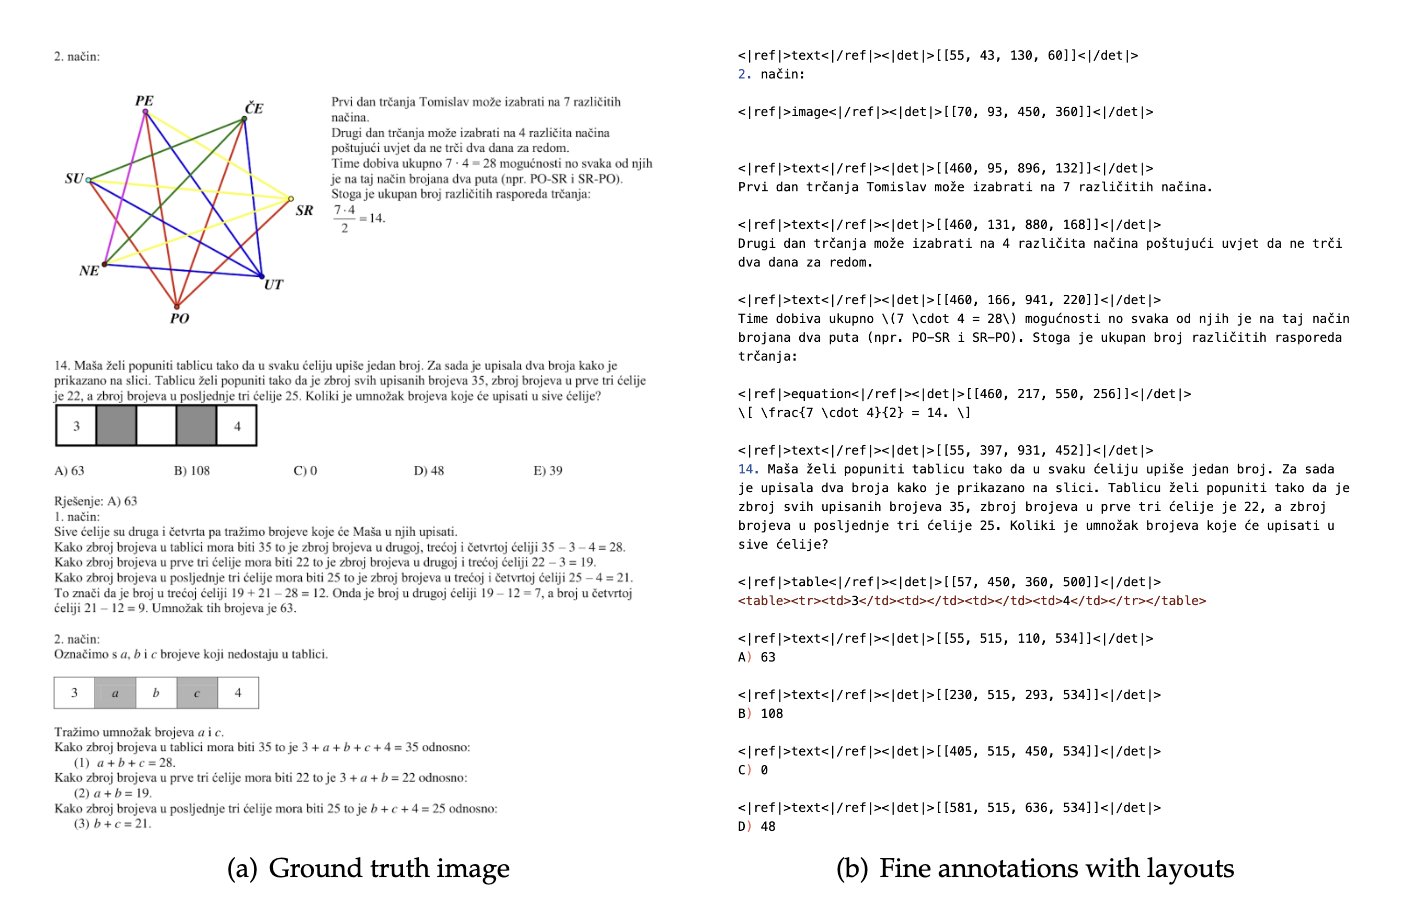
Using Visual Context Compression to Improve LLM Memory and Reasoning
By
–
5. This isn’t “just another OCR.” It’s a proof of concept for context compression. If text can be represented visually with 10× fewer tokens LLMs could use the same idea for long-term memory and efficient reasoning. Imagine GPT-5 processing a 1M-token document as a 100K-token