LangSmith Agent Builder uses memory to improve with feedback. Three practical ways to get the most out of memory: → Tell your agent to remember what works
→ Use skills to give it specialized context when needed
→ Edit its instructions directly when that's faster Full
GENERATIVE AI
-
Three Ways to Optimize LangSmith Agent Memory and Performance
By
–
-
Fine-tune AI Models Without GPU Using Claude Code and Unsloth
By
–
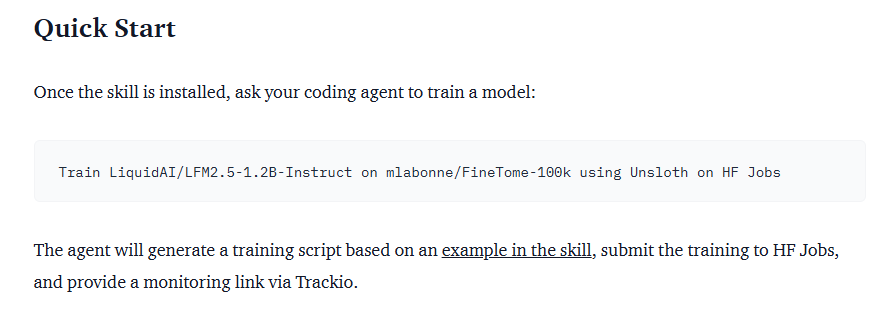
Great application of skills: post-train models directly from Claude Code or Codex. No code, no GPU required. We fine-tuned LFM2.5-1.2B-Instruct with just a prompt 👀 Ben Burtenshaw (@ben_burtenshaw) You can finetune AI models with Unsloth + Hugging Face, and right now it’s free! We're giving away GPU credits on HF Jobs + Unsloth. Train a 1.2B model like @liquidai LFM2.5-1.2B with one command. Ship it to your phone, laptop, or API. No infra. No setup. Just prompt your coding agent and go. — https://nitter.net/ben_burtenshaw/status/2024552060558229858#m
→ View original post on X — @maximelabonne, 2026-02-19 18:47 UTC
-
AI imagines Snoop Dogg born in different countries
By
–
What if Snoop Dogg was born in Other Countries? 🤔
— Linus ✦ Ekenstam (@LinusEkenstam) 19 février 2026
AI Imagines how he would look like pic.twitter.com/nPKAB2Cw8JWhat if Snoop Dogg was born in Other Countries? AI Imagines how he would look like
-

Automated PowerPoint Generation Tool Never Manual Again
By
–
Never make a powerpoint manually again.
-
LangSmith for Startups: Free Tools for Early-Stage Teams
By
–
🚀 Introducing: LangSmith for Startups
— LangChain (@LangChain) 19 février 2026
We are launching LangSmith for Startups to give early-stage teams the tooling and community they need to iterate faster and win bigger.
Observe, evaluate, and deploy your agents — now with free credits to help you get started. 💸
Our… pic.twitter.com/WizxZ2iBa9Introducing: LangSmith for Startups We are launching LangSmith for Startups to give early-stage teams the tooling and community they need to iterate faster and win bigger. Observe, evaluate, and deploy your agents — now with free credits to help you get started. Our
-

Comparison of Gemini 3.1 Pro and Codex 5.3 Performance
By
–
Gemini 3.1 Pro is here. Benchmarks look impressive, and definitely a qualitative improvement over 3.0. However, it also looks like OAI really cooked with Codex 5.3 for coding.
-
Custom AI Benchmark Created Without User Data
By
–
No user data was used in the making of the custom benchmark, to be clear!
-
Google Releases Gemini 3.1 Pro with Doubled Reasoning Performance
By
–
Today, we’re continuing to push the boundaries of AI with our release of Gemini 3.1 Pro.
— Jeff Dean (@JeffDean) 19 février 2026
This updated model scores 77.1% on ARC-AGI-2, more than double the reasoning performance of its predecessor, Gemini 3 Pro.
Check out the visible improvement in this side-by-side comparison,… pic.twitter.com/8fbHFLeyL8Today, we’re continuing to push the boundaries of AI with our release of Gemini 3.1 Pro. This updated model scores 77.1% on ARC-AGI-2, more than double the reasoning performance of its predecessor, Gemini 3 Pro. Check out the visible improvement in this side-by-side comparison, showing Gemini 3.1 Pro’s crisp animation built with pure code. Read more about today’s 3.1 Pro update: blog.google/innovation-and-a…
-

Gemini 3.1 Pro Launches: Deep Reasoning Model on Poe
By
–
Gemini 3.1 Pro is live on Poe — Google’s newest Gemini model built to solve your hardest challenges: deep reasoning, synthesis, and complex problem solving. We got early access to a private snapshot and co-developed a custom benchmark to help shape this model with our partners at
-

Gemini 3.1 Pro Launch: Major Reasoning Improvements Announced
By
–
Excited to launch Gemini 3.1 Pro! Major improvements across the board including in core reasoning and problem solving. For example scoring 77.1% on the ARC-AGI-2 benchmark – more than 2x the performance of 3 Pro. Rolling out today in @GeminiApp
, @antigravity and more – enjoy!