Oh I so love this demo using @theworldlabs ' Marble API!
GENERATIVE AI
-
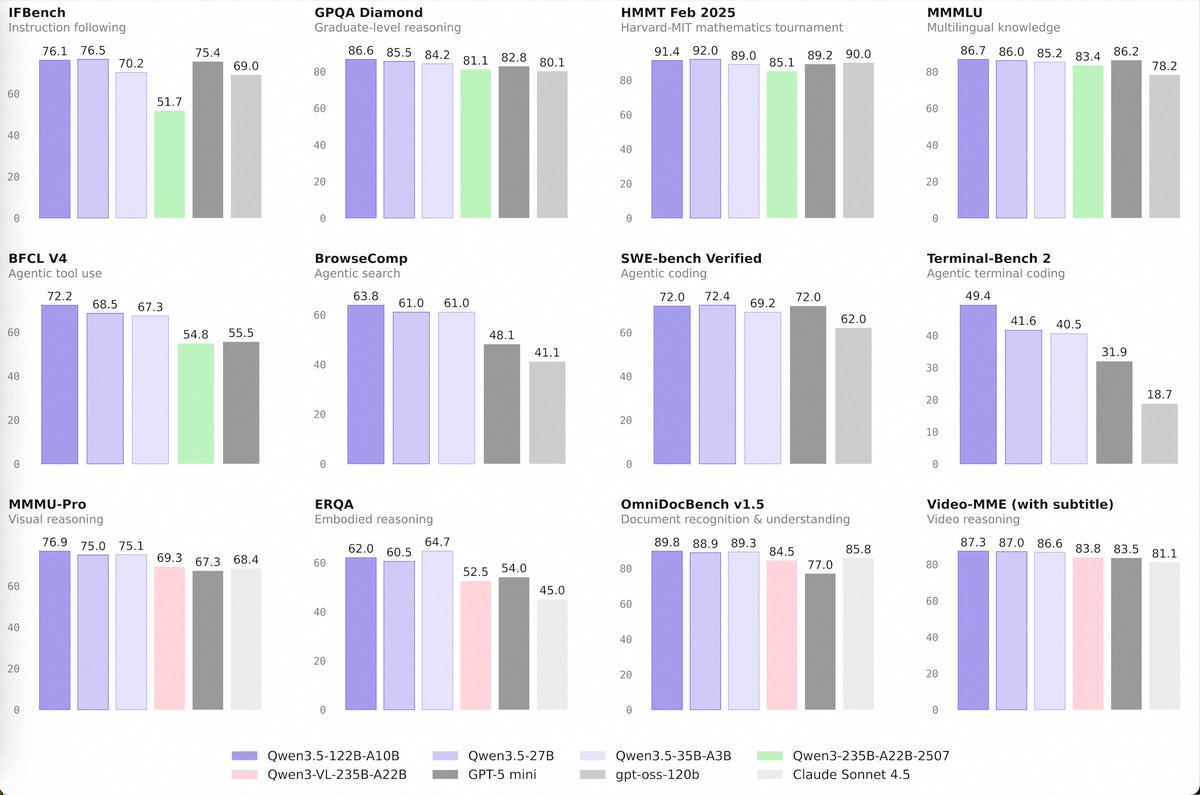
Unfortunate timing: 24B-A2B release coincides with Qwen3.5 launch
By
–
Releasing a 24B-A2B model on the same day as Qwen3.5-35B-A3B is NOT great timing 🥲 Qwen (@Alibaba_Qwen) 🚀 Introducing the Qwen 3.5 Medium Model Series Qwen3.5-Flash · Qwen3.5-35B-A3B · Qwen3.5-122B-A10B · Qwen3.5-27B ✨ More intelligence, less compute. • Qwen3.5-35B-A3B now surpasses Qwen3-235B-A22B-2507 and Qwen3-VL-235B-A22B — a reminder that better architecture, data quality, and RL can move intelligence forward, not just bigger parameter counts. • Qwen3.5-122B-A10B and 27B continue narrowing the gap between medium-sized and frontier models — especially in more complex agent scenarios. • Qwen3.5-Flash is the hosted production version aligned with 35B-A3B, featuring: – 1M context length by default – Official built-in tools 🔗 Hugging Face: huggingface.co/collections/Q… 🔗 ModelScope: modelscope.cn/collections/Qw… 🔗 Qwen3.5-Flash API: modelstudio.console.alibabac… Try in Qwen Chat 👇 Flash: chat.qwen.ai/?models=qwen3.5… 27B: chat.qwen.ai/?models=qwen3.5… 35B-A3B: chat.qwen.ai/?models=qwen3.5… 122B-A10B: chat.qwen.ai/?models=qwen3.5… Would love to hear what you build with it. — https://nitter.net/Alibaba_Qwen/status/2026339351530188939#m
→ View original post on X — @maximelabonne, 2026-02-24 17:01 UTC
-
Preparation of Gemini 3.1 Flash Image Preview
By
–
PREVIEW : Google is preparing Gemini 3.1 Flash Image Preview for the upcoming release. Nano Banana 2 (Flash) model was tested in December based on the Gemini 3 Flash, but it was postponed. Soon?
-
LFM2-24B-A2B: Liquid AI’s Fastest 24B MoE Model Released
By
–
Meet LFM2-24B-A2B, @liquidai's largest model. 24B MoE, 2B active. Blazing fast even on CPU. Available now in LM Studio 👾💧 lmstudio.ai/models/lfm2-24b-…
→ View original post on X — @maximelabonne, 2026-02-24 15:44 UTC
-
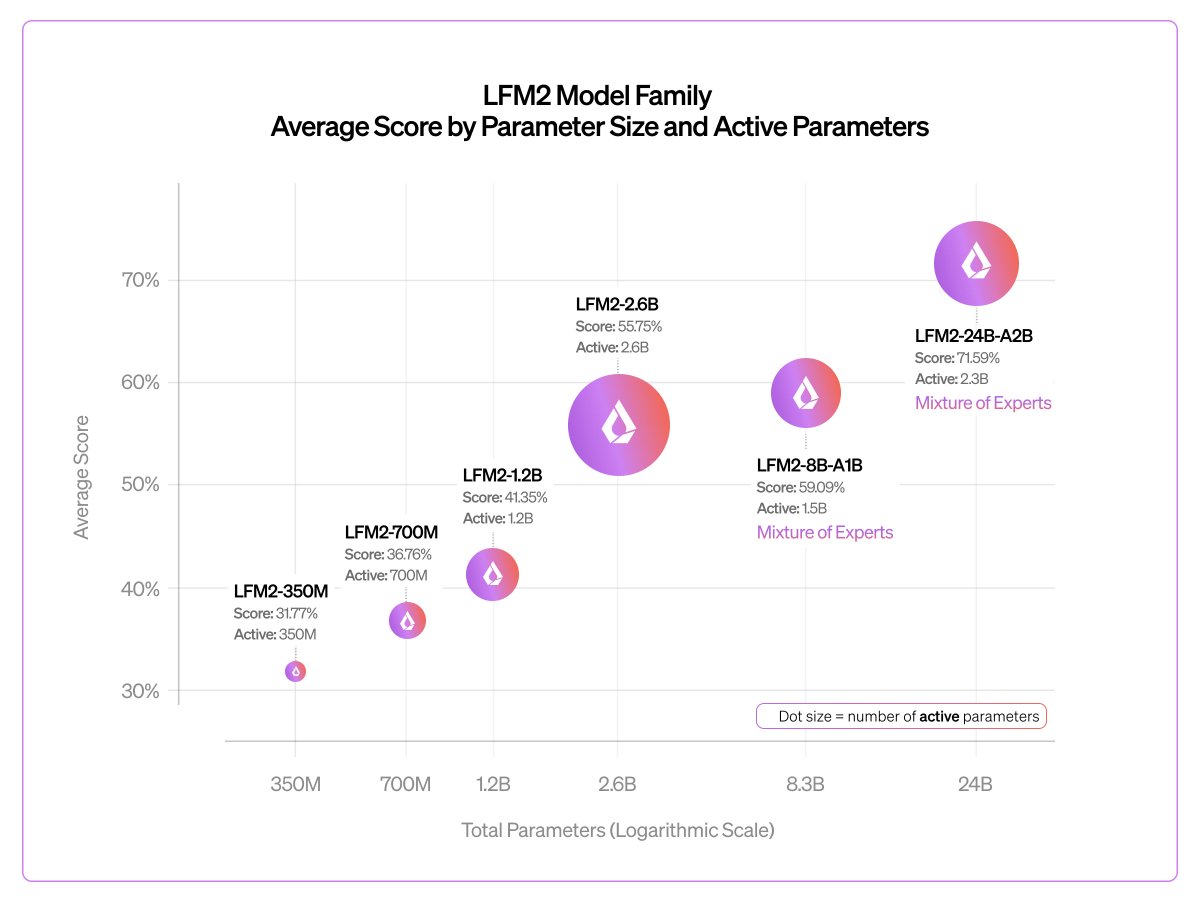
Liquid AI releases LFM2-24B-A2B model for on-device inference
By
–
ollama run lfm2:24b-a2b .@liquidai's latest on-device model is here! It's the largest LFM2 model yet, and is designed to run fast on device, and fits on devices with 32GB of unified memory. Liquid AI (@liquidai) Today, we release our largest LFM2 model: LFM2-24B-A2B 🐘 > 24B total parameters > 2.3B active per token > Built on our hybrid, hardware-aware LFM2 architecture It combines LFM2’s fast, memory-efficient design with a Mixture of Experts setup, so only 2.3B parameters activate each run. The result: best-in-class efficiency, fast edge inference, and predictable log-linear scaling all in a 32GB, 2B-active MoE footprint. 🧵 — https://nitter.net/liquidai/status/2026301771539202269#m
→ View original post on X — @maximelabonne, 2026-02-24 14:36 UTC
-
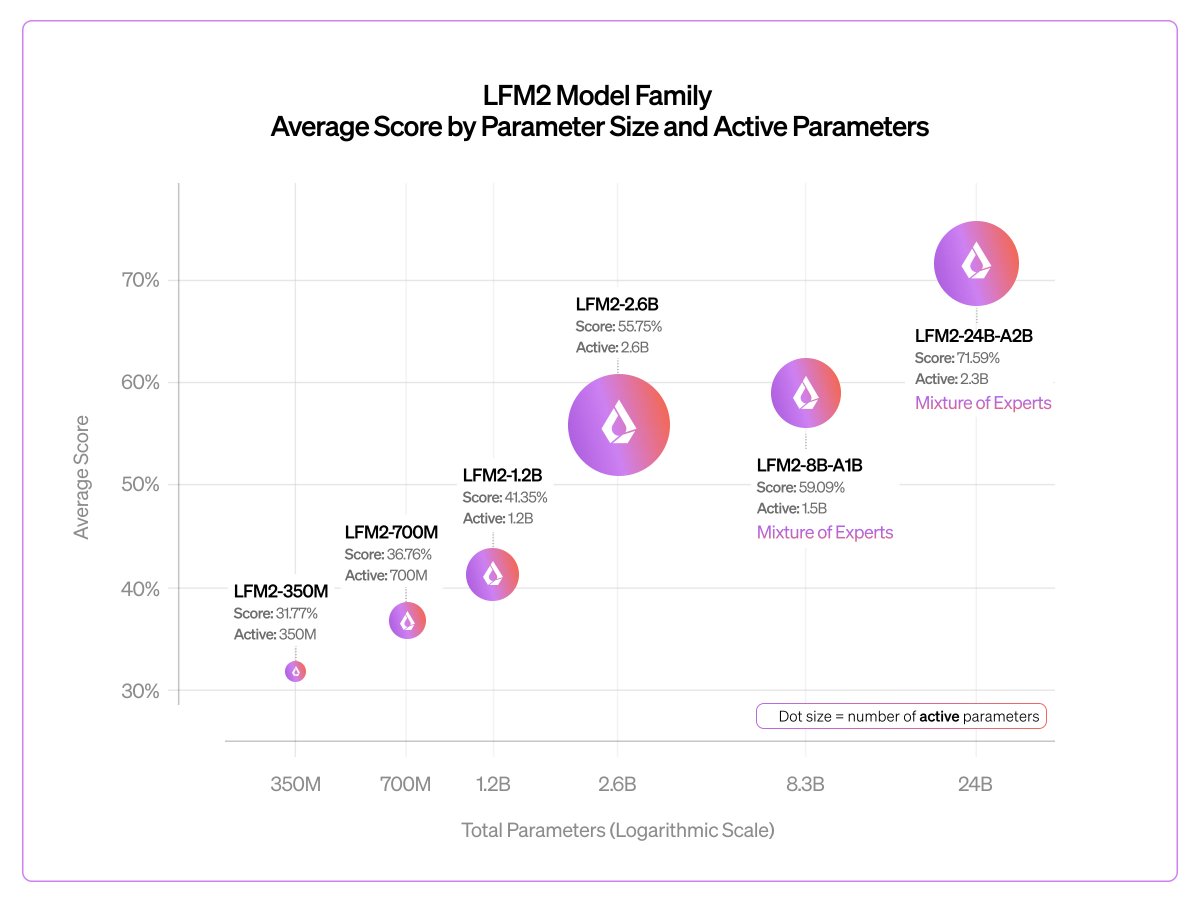
Liquid AI Releases Largest LFM2-24B-A2B Model with Fast Inference
By
–
Early checkpoint of our biggest LFM2 model to date 🎉 It shows good scaling and extremely fast inference vs. gpt-oss-20b and Qwen3-30B-A3B We'll release an LFM2.5 version with more pre-training and RL in a few months Liquid AI (@liquidai) Today, we release our largest LFM2 model: LFM2-24B-A2B 🐘 > 24B total parameters > 2.3B active per token > Built on our hybrid, hardware-aware LFM2 architecture It combines LFM2’s fast, memory-efficient design with a Mixture of Experts setup, so only 2.3B parameters activate each run. The result: best-in-class efficiency, fast edge inference, and predictable log-linear scaling all in a 32GB, 2B-active MoE footprint. 🧵 — https://nitter.net/liquidai/status/2026301771539202269#m
→ View original post on X — @maximelabonne, 2026-02-24 14:31 UTC
-

Claude AI Now Available Inside PowerPoint for Pro Users
By
–
Claude is now inside PowerPoint. It builds slides from your template.
Edits decks without breaking formatting.
Creates native charts and diagrams you can actually edit.
This is how AI should work — inside your workflow. Available to Pro, Max, Team and Enterprise plan -
Three Common Mistakes When Using Claude AI
By
–
LES 3 ERREURS QUI VOUS TRAHISSENT Erreur 1 : Utiliser Claude sans personnalisation
Prompt générique → Résultat générique Erreur 2 : Accepter la première version
Claude améliore souvent trop. Demandez-lui de se retenir. Erreur 3 : Ne pas relire après correction
Même avec les -
Using Prompt Engineering to Match Personal Writing Style in Claude
By
–
7/ Le prompt "Style Personnel" Pour que Claude écrive vraiment comme TOI :
"Tu vas adopter mon style d'écriture personnel. Analyse d'abord ces 3 exemples de mes textes précédents : [Exemple 1] [Exemple 2] [Exemple 3] Identifie : → Longueur moyenne de mes phrases → Mots et -
Invisible Corrector Prompt for LLMs
By
–
4/ Le prompt "Correcteur Invisible" Quand tu veux juste corriger sans changer le style : "Tu es un correcteur fantôme qui répare les fautes sans laisser de traces de son passage.
Règles strictes : Corrige UNIQUEMENT les fautes objectives (orthographe, grammaire, conjugaison)