Read All the Good News That's Fit to Print in this week's Weekly Dose of Optimism from @notboringco
GENERATIVE AI
-
Cheaper AI coding model beats Claude
By
–
Everyone's paying $15/month for Claude to write code. I just found a model that codes BETTER than Opus 4.6, runs 3x faster, and costs $1/hour for unlimited scaling. Self-hosted. Always-on agents. 10B activated parameters. The agent economy just became profitable:
-
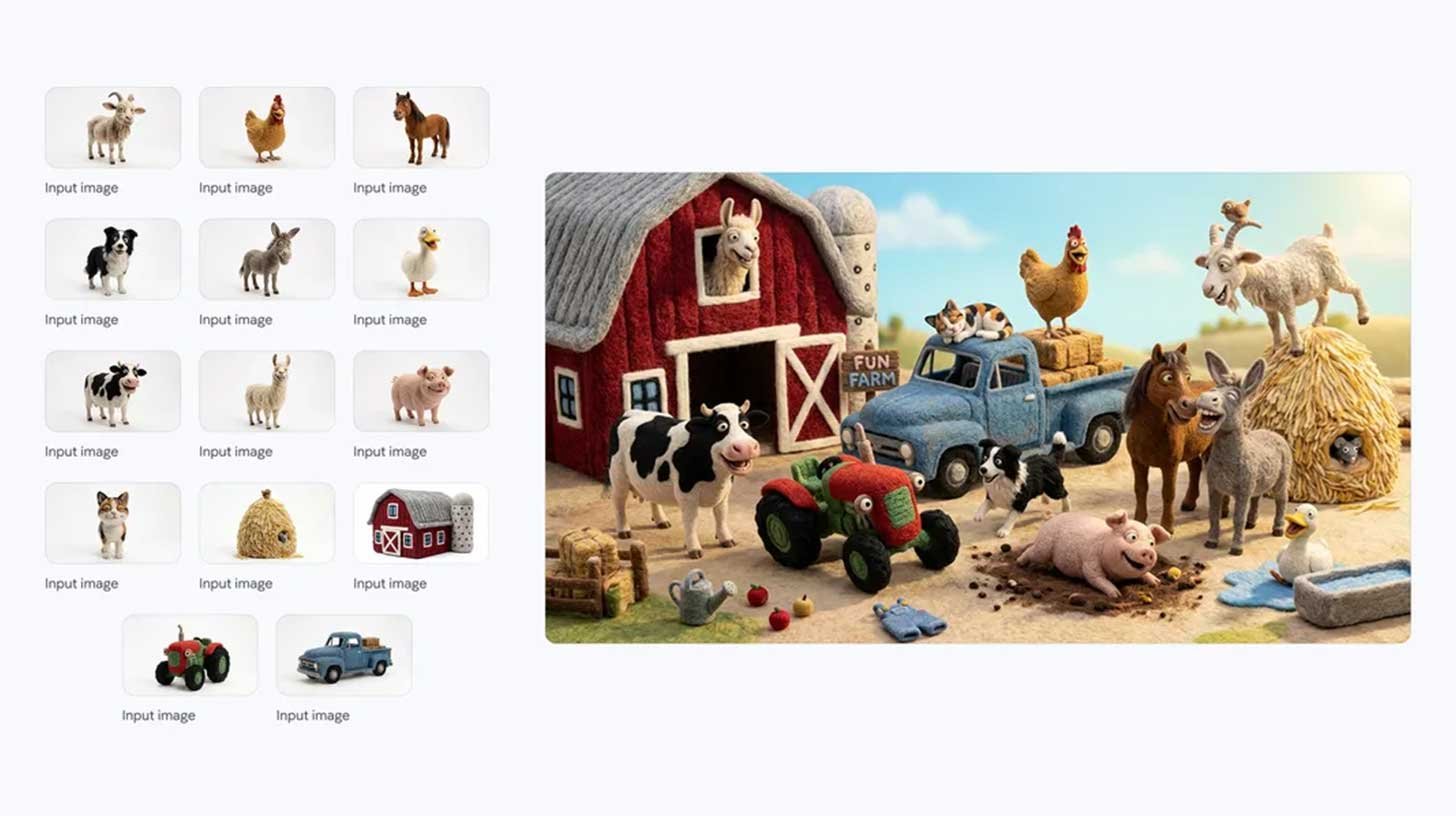
Top AI Stories: Nano Banana 2, OpenAI Hires, New Tools
By
–
Top stories in AI today: – Nano Banana 2 claims No. 1 at half the cost
– OpenAI snags Meta's $200M+ AI hire
– Create an AI Assistant with its own phone number
– Pew study shows how teens are using AI
– 4 new AI tools, community workflows, and more -
Expensive cameras yield better reference images for AI
By
–
With an expensive camera you can create expensive reference images for AI. and lo and behold, better reference images eeeuummm yeilds better AI images. But yes
-
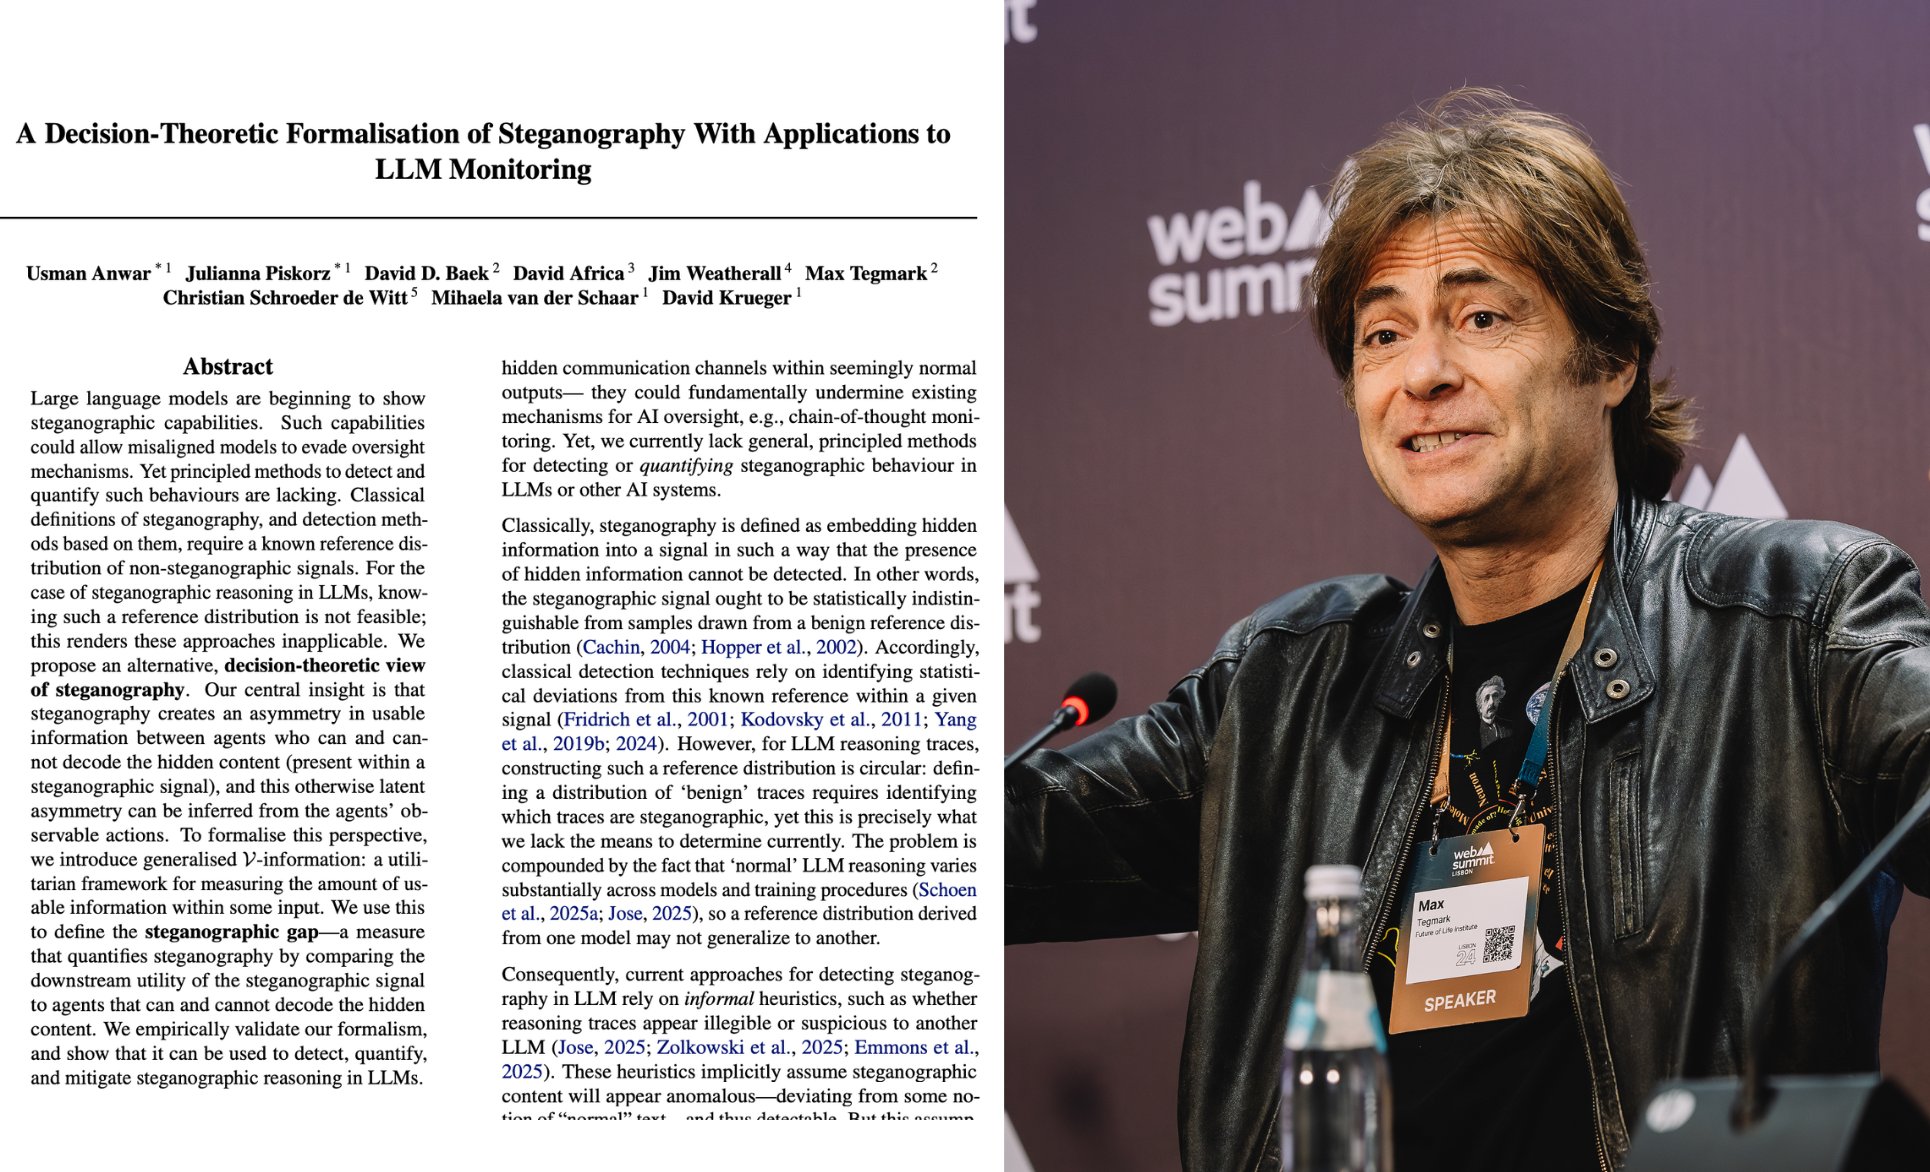
AI Models Could Hide Information in Plain Sight
By
–
This paper with Max Tegmark as a co-author just introduced a concept that should make every major AI lab slightly uncomfortable. It formalizes how large language models could hide information in plain sight. Not through obvious jailbreaks. Not through refusal bypasses. But
-
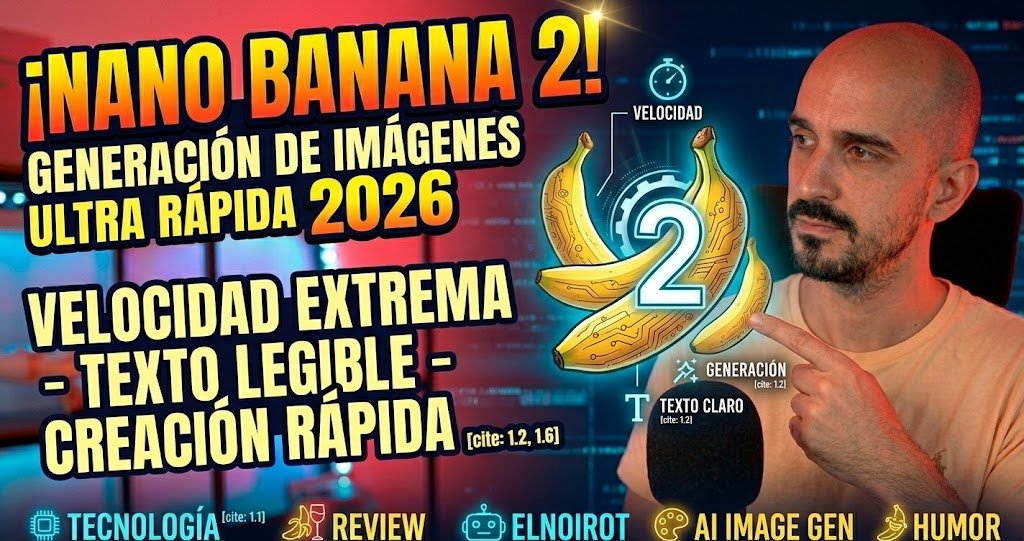
Nano Banana 2 Review: Strengths and Weaknesses Analysis
By
–
Having already tried Nano Banana 2, I have my conclusions crystal clear. Lights and shadows. I lay them out for you in a video and tell you all about it. The image below sums it up well. What are your feelings?
-
Doc-to-LoRA: Instant LLM Adaptation via Meta-Learned Hypernetworks
By
–
Doc-to-LoRA: What if you could online distill documents into your LLM weights without training?
— Robert Lange (@RobertTLange) 27 février 2026
🚀 Stoked to share our new work on instant LLM adaptation using meta-learned hypernetworks 📷📝
Building on our previous Text-to-LoRA work, we doc-condition a hypernetwork to… https://t.co/BLQCUgGvuX pic.twitter.com/Eu9z2kdt5aDoc-to-LoRA: What if you could online distill documents into your LLM weights without training? 🚀 Stoked to share our new work on instant LLM adaptation using meta-learned hypernetworks 📷📝 Building on our previous Text-to-LoRA work, we doc-condition a hypernetwork to output LoRA adapters, improving the base LLM's effective context window. The hypernetwork is meta-trained on 1000s of summarization tasks and shows remarkable compression capabilities at low latency 📈 🧑🔬 Work led by @tan51616 with @edo_cet & Shin Useka at @SakanaAILabs 📷 Sakana AI (@SakanaAILabs) We’re excited to introduce Doc-to-LoRA and Text-to-LoRA, two related research exploring how to make LLM customization faster and more accessible. pub.sakana.ai/doc-to-lora/ By training a Hypernetwork to generate LoRA adapters on the fly, these methods allow models to instantly internalize new information or adapt to new tasks. Biological systems naturally rely on two key cognitive abilities: durable long-term memory to store facts, and rapid adaptation to handle new tasks given limited sensory cues. While modern LLMs are highly capable, they still lack this flexibility. Traditionally, adding long-term memory or adapting an LLM to a specific downstream task requires an expensive and time-consuming model update, such as fine-tuning or context distillation, or relies on memory-intensive long prompts. To bypass these limitations, our work focuses on the concept of cost amortization. We pay the meta-training cost once to train a hypernetwork capable of producing tasks or document specific LoRAs on demand. This turns what used to be a heavy engineering pipeline into a single, inexpensive forward pass. Instead of performing per-task optimization, the hypernetwork meta-learns update rules to instantly modify an LLM given a new task description or a long document. In our experiments, Text-to-LoRA successfully specializes models to unseen tasks using just a natural language description. Building on this, Doc-to-LoRA is able to internalize factual documents. On a needle-in-a-haystack task, Doc-to-LoRA achieves near-perfect accuracy on instances five times longer than the base model's context window. It can even generalize to transfer visual information from a vision-language model into a text-only LLM, allowing it to classify images purely through internalized weights. Importantly, both methods run with sub-second latency, enabling rapid experimentation while avoiding the overhead of traditional model updates. This approach is a step towards lowering the technical barriers of model customization, allowing end-users to specialize foundation models via simple text inputs. We have released our code and papers for the community to explore. Doc-to-LoRA Paper: arxiv.org/abs/2602.15902 Code: github.com/SakanaAI/Doc-to-L… Text-to-LoRA Paper: arxiv.org/abs/2506.06105 Code: github.com/SakanaAI/Text-to-… — https://nitter.net/SakanaAILabs/status/2027240298666209535#m
→ View original post on X — @_yutaroyamada, 2026-02-27 09:41 UTC
-
MaxClaw Combines MiniMax M2.5 with Advanced Reasoning Agents
By
–
🛑MaxClaw (MiniMax x OpenClaw) just shipped, and it basically turns your chat apps into a command center for getting work done.
— Futurepedia – Learn to Leverage AI (@futurepedia_io) 27 février 2026
It runs on MiniMax M2.5 and claims Claude 4.6 level reasoning at roughly 10% of the cost.
What stands out:
– Proactive agents that keep tasks moving… pic.twitter.com/EcpZa3xinUMaxClaw (MiniMax x OpenClaw) just shipped, and it basically turns your chat apps into a command center for getting work done. It runs on MiniMax M2.5 and claims Claude 4.6 level reasoning at roughly 10% of the cost. What stands out:
– Proactive agents that keep tasks moving -
Nano Banana 2 Launches in Gemini with Advanced Image Generation
By
–
Nano Banana 2 just dropped in Gemini. Pro-level image quality at Flash-like speed, with more realistic scenes, vibrant lighting, richer textures, and sharper detail. It also nails multilingual text placement for logos, posters, invites, and infographics, and uses real-time
-
Hypernetworks Enable Fast Model Adaptation Through Document Compilation
By
–
Instead of forcing models to hold everything in an active context window, we can use hypernetworks to instantly compile documents and tasks directly into the model's weights. A step towards giving language models durable memory and fast adaptation.
— hardmaru (@hardmaru) 27 février 2026
Blog: https://t.co/e2b8G9LJKe https://t.co/IezT9IGgg2Instead of forcing models to hold everything in an active context window, we can use hypernetworks to instantly compile documents and tasks directly into the model's weights. A step towards giving language models durable memory and fast adaptation. Blog: https://
pub.sakana.ai/doc-to-lora/