Qwen3.5 is ranked at an impressive 7th place on pinchbench atm. It's really impressive for such a relatively small open-weight model.
I think that's a perfect use case for local LLMs.
Curious to see where Nemotron 3 Super will rank.
GENERATIVE AI
-

Qwen3.5 Ranks 7th on Pinchbench as Impressive Small Open-Weight Model
By
–
-
Sarvam-105B: Indian AI model outperforms DeepSeek-R1
By
–
Sarvam-105B trained in India, on Indian data, on Indian infrastructure. Scored 96.7 on AIME 2025. Outperformed DeepSeek-R1 on certain benchmarks. A model worth BILLIONS — built for ₹246 crore. (6/8) @AshwiniVaishnaw @jitinprasada @PIB_India @SecretaryMEITY @abhish18 @kavitabha
-
Indian AI Companies Develop 105B LLM and Multimodal Models
By
–
What's running on these GPUs? #SarvamAI building a 105B parameter model. #BharatGen training multimodal LLMs. http://
Gnani.AI building voice models for 12 Indian languages. All Made in India. (5/8) @AshwiniVaishnaw @jitinprasada @PIB_India @SecretaryMEITY @abhish18 -
Thanks for the writing rework by Claude
By
–
Oh wow wait, that's not bad adding a writing rework by Claude! Thanks!
-

Nvidia Nemotron 3 Super 120B: High Performance Open-Weight LLM
By
–
Another week, another noteworthy open-weight LLM release. Nvidia’s Nemotron 3 Super 120B-A12B looks pretty good. Benchmarks are on par with Qwen3.5 122B and GPT-OSS 120B, but the throughput is great! Below is a short, visual architecture rundown.
-
Using AI to format a daily newsletter
By
–
Well, obviously to put out a daily newsletter I'm not going to spend 2 hours writing it. I do the draft, I choose the news, the sentences roughly, and then the AI formats it.
-
LLM2Vec-Gen: Frozen LLMs Generate Better Embeddings Through Reasoning
By
–
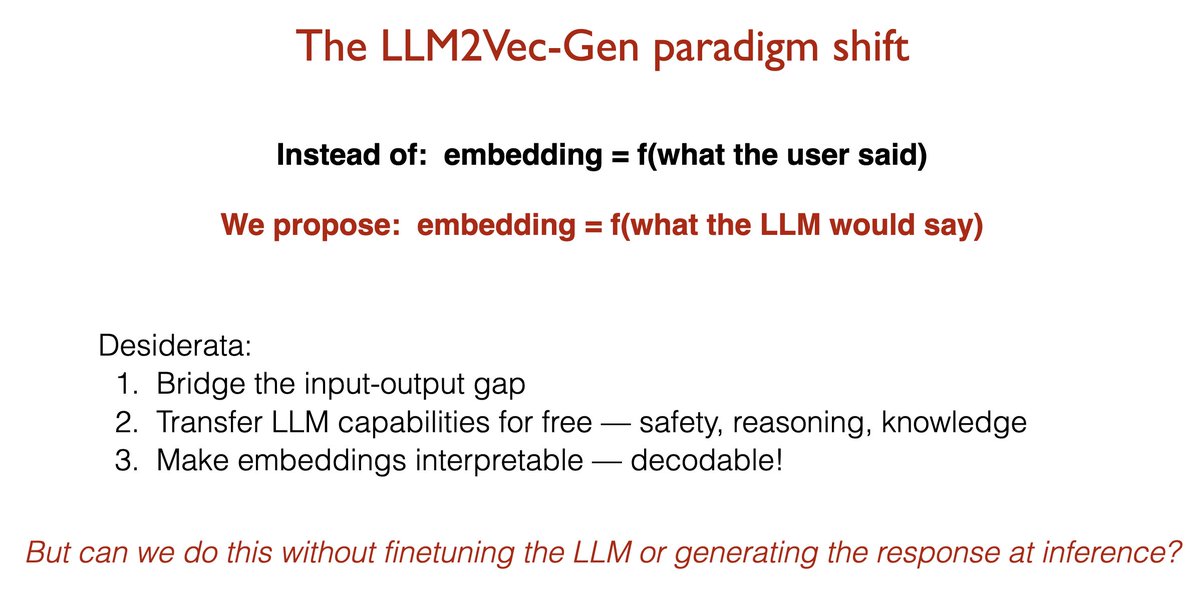
LLM2Vec-Gen represents a major paradigm shift for embeddings/retrieval. Why encode the query when the LLM already knows what to look for and can directly produce an embedding for it? Best part: it’s self-supervised, and it does all of this while the LLM remains completely frozen. Think about it: "solve x² + 3x − 4 = 0" has zero reasoning in it. But the LLM's response does. By encoding the response, the embedding captures the reasoning — and the better the LLM reasons, the better the embedding. This is why our results scale with model size. As LLMs get smarter, our embeddings automatically get better. LLM2Vec-Gen is also the first demonstration of the promise of @ylecun's JEPA for text embeddings. The alignment loss is JEPA — predict in representation space, not token space. The reconstruction loss goes beyond — it keeps embeddings decodable. This paradigm shift opens new frontiers: 🔬 Can we build a full JEPA for language where the teacher and student are the same LLM? ⚡ Can LLMs reason in compressed space without ever generating text? 🤖 Can agents reason in compression tokens and carry that directly into retrieval? 💬 Can agents talk to each other in compression tokens instead of text — dense, fast, and still human-readable? LLM2Vec-Gen is a first step toward all four. Vaibhav Adlakha (@vaibhav_adlakha) Your LLM already knows the answer. Why is your embedding model still encoding the question? 🚨Introducing LLM2Vec-Gen: your frozen LLM generates the answer's embedding in a single forward pass — without ever generating the answer. Not only that, the frozen LLM can decode the embedding back into text. 🏆 SOTA self-supervised embeddings 🛡️ Free transfer of instruction-following, safety, and reasoning — https://nitter.net/vaibhav_adlakha/status/2032065008603951187#m
→ View original post on X — @hugo_larochelle, 2026-03-12 12:37 UTC
-

India AI Impact Summit 2026: Global Leaders Democratize AI
By
–
The India AI Impact Summit 2026 brought together global leaders to discuss the next frontier in the AI growth story. The summit also highlighted how a nation like India, with its scale and diversity, has a unique opportunity to democratise AI for the world. Mr. Sam Altman, CEO of
-

New Open-Source LuxTTS Model Enables Efficient Local Voice Cloning
By
–
Wild. There is an incredible new open-source TTS model in town. It achieves SOTA voice cloning on par with models 10x larger. 150x real-time generation. 1GB VRAM. 48kHz quality. Meet LuxTTS: The new open-source standard for local voice cloning. If you are still paying
-
AI Actors in Film: Inevitable, Efficient, and Permanent
By
–
https://t.co/xGrdD77DCc https://t.co/c7nMbVAjt6
— Jouhatsu | AI Influence Operator (@Jouhatsu_ai) 12 mars 2026Engager cet acteur coûterait $100 000 et deux semaines à Hollywood. Soul Cast de Higgsfield l'a fait en trois minutes.
ET vous êtes propriétaire du personnage pour toujours. 80 % des films utiliseront des acteurs IA d'ici 2026. Voici pourquoi c'est inévitable : @higgsfield