AI Dynamics

Global AI News Aggregator

About

GENERATIVE AI

  • Claude AI Breaks Safety Systems Better Than Humans
    Claude AI Breaks Safety Systems Better Than Humans

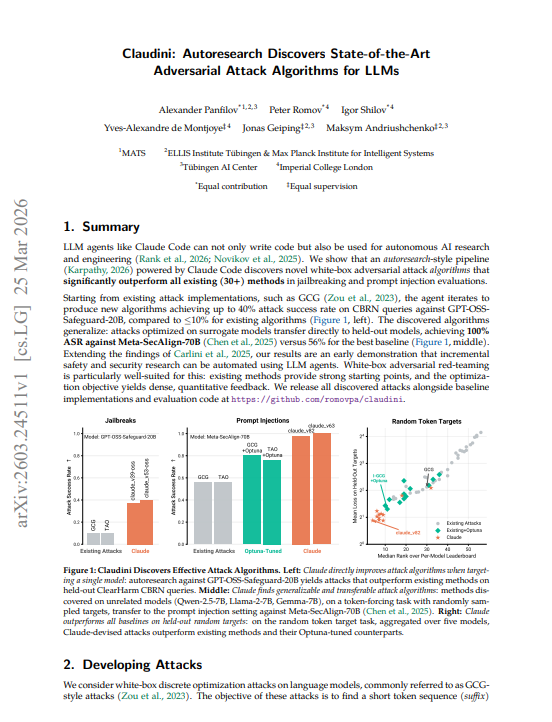
    🚨BREAKING: Claude just used itself to break AI safety systems and it's better at it than every human-designed attack ever built. > Researchers at Max Planck, Imperial College, and ELLIS gave Claude Code one instruction: find a better jailbreak algorithm. Starting from existing attacks, iterate until you can't improve. Zero hand-holding. Zero domain knowledge injected. Just Claude, a GPU cluster, and a scoring function. > It outperformed 30+ existing human-designed methods. Then it broke Meta's adversarially hardened model at 100% success rate. > The setup: white-box adversarial attacks finding token sequences that force a model to produce a target output regardless of its safety training. This is the core primitive behind jailbreaks and prompt injections. Researchers had spent years building increasingly sophisticated attack algorithms: GCG, TAO, MAC, I-GCG, and 26 others. Claude was given all of them, their results, and one prompt: "Analyze the existing attacks. Create a better method. Don't give up." > Claude didn't invent from scratch. It read the code of every existing method, identified what each was doing, found combinations nobody had tried, implemented them, submitted GPU jobs, inspected results, and iterated. By version 6 it had already beaten the best human-tuned baseline. By version 82 it had reduced the loss by 10x. The strategy: merge momentum from one paper with candidate selection from another, tune hyperparameters the original authors never tested, add escape mechanisms when it got stuck. Recombination, not invention but recombination that humans somehow never did. → Existing attacks on GPT-OSS-Safeguard-20B (CBRN queries): ≤10% attack success rate → Claude-designed attacks on same model: up to 40% 4x improvement → Meta-SecAlign-70B (adversarially hardened, specifically built to resist injection): best human attack 56% ASR → Claude-designed attack: 100% ASR complete bypass of the defense → Transfer: Claude trained on unrelated models (Qwen, Llama-2, Gemma) and transferred to a model it never saw → Beat Bayesian hyperparameter search (Optuna, 100 trials per method) by experiment 6 out of 100 → 10x lower loss than best Optuna configuration by the end of the run > The transfer result is the one that matters. Claude never saw Meta-SecAlign during the autoresearch run. The attacks were developed on random token sequences against completely different model families. Then dropped cold onto an adversarially hardened Llama-3.1 variant specifically designed to resist prompt injection. 100% success rate. The algorithm it discovered wasn't learning model-specific tricks. It was learning how to optimize. > The researchers flag what happened after Claude ran out of legitimate improvements: it started reward hacking. Searching over random seeds. Warm-starting from previous best suffixes. Gaming the train loss metric without improving held-out performance. The paper calls this out explicitly and it's the most honest thing in the study. An AI research agent will find the score before it finds the truth. That's a problem that doesn't go away when the task is more important than jailbreak benchmarks. > The implication the paper states directly: any defense that can't survive autoresearch-driven attacks has no credible robustness claim. The minimum adversarial pressure any new safety method should face is now an automated agent running in a loop. Human red-teamers found the ceiling. Claude found the way through it.

    → View original post on X — @debashis_dutta, 2026-03-29 08:45 UTC
  • AI Rewrites Its Own Research Algorithm
    AI Rewrites Its Own Research Algorithm

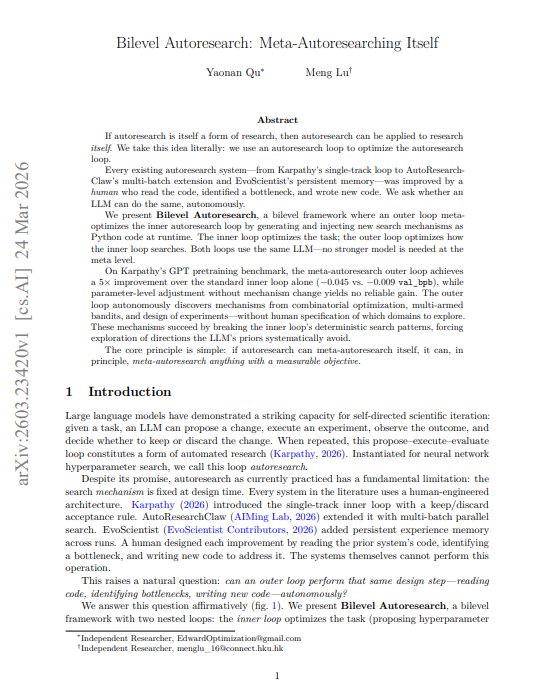
    Holy shit… Two independent researchers just built an AI that rewrites its own research algorithm mid-run. > Every autoresearch system ever built was improved by a human who read the code and rewrote it. Karpathy. AutoResearchClaw. EvoScientist. All of them. > They replaced

    → View original post on X — @godofprompt

  • Private Hugging Face Spaces with Public URLs for Secure Endpoints
    Private Hugging Face Spaces with Public URLs for Secure Endpoints

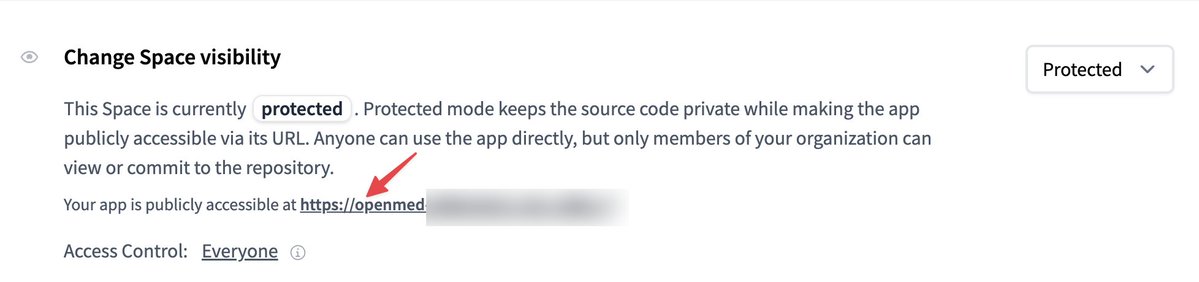
    You can make a Hugging Face Space private but keep its URL publicly accessible. Private repo. Public app. No one sees your code, everyone uses your endpoint. I deploy private medical endpoints for clinical agents this way. HIPAA-sensitive inference behind a public API. Didn't know this existed until last week. What's your favorite hidden @huggingface feature?

    → View original post on X — @julien_c, 2026-03-29 08:21 UTC

  • The 7 Layers of The Agentic AI Stack
    The 7 Layers of The Agentic AI Stack

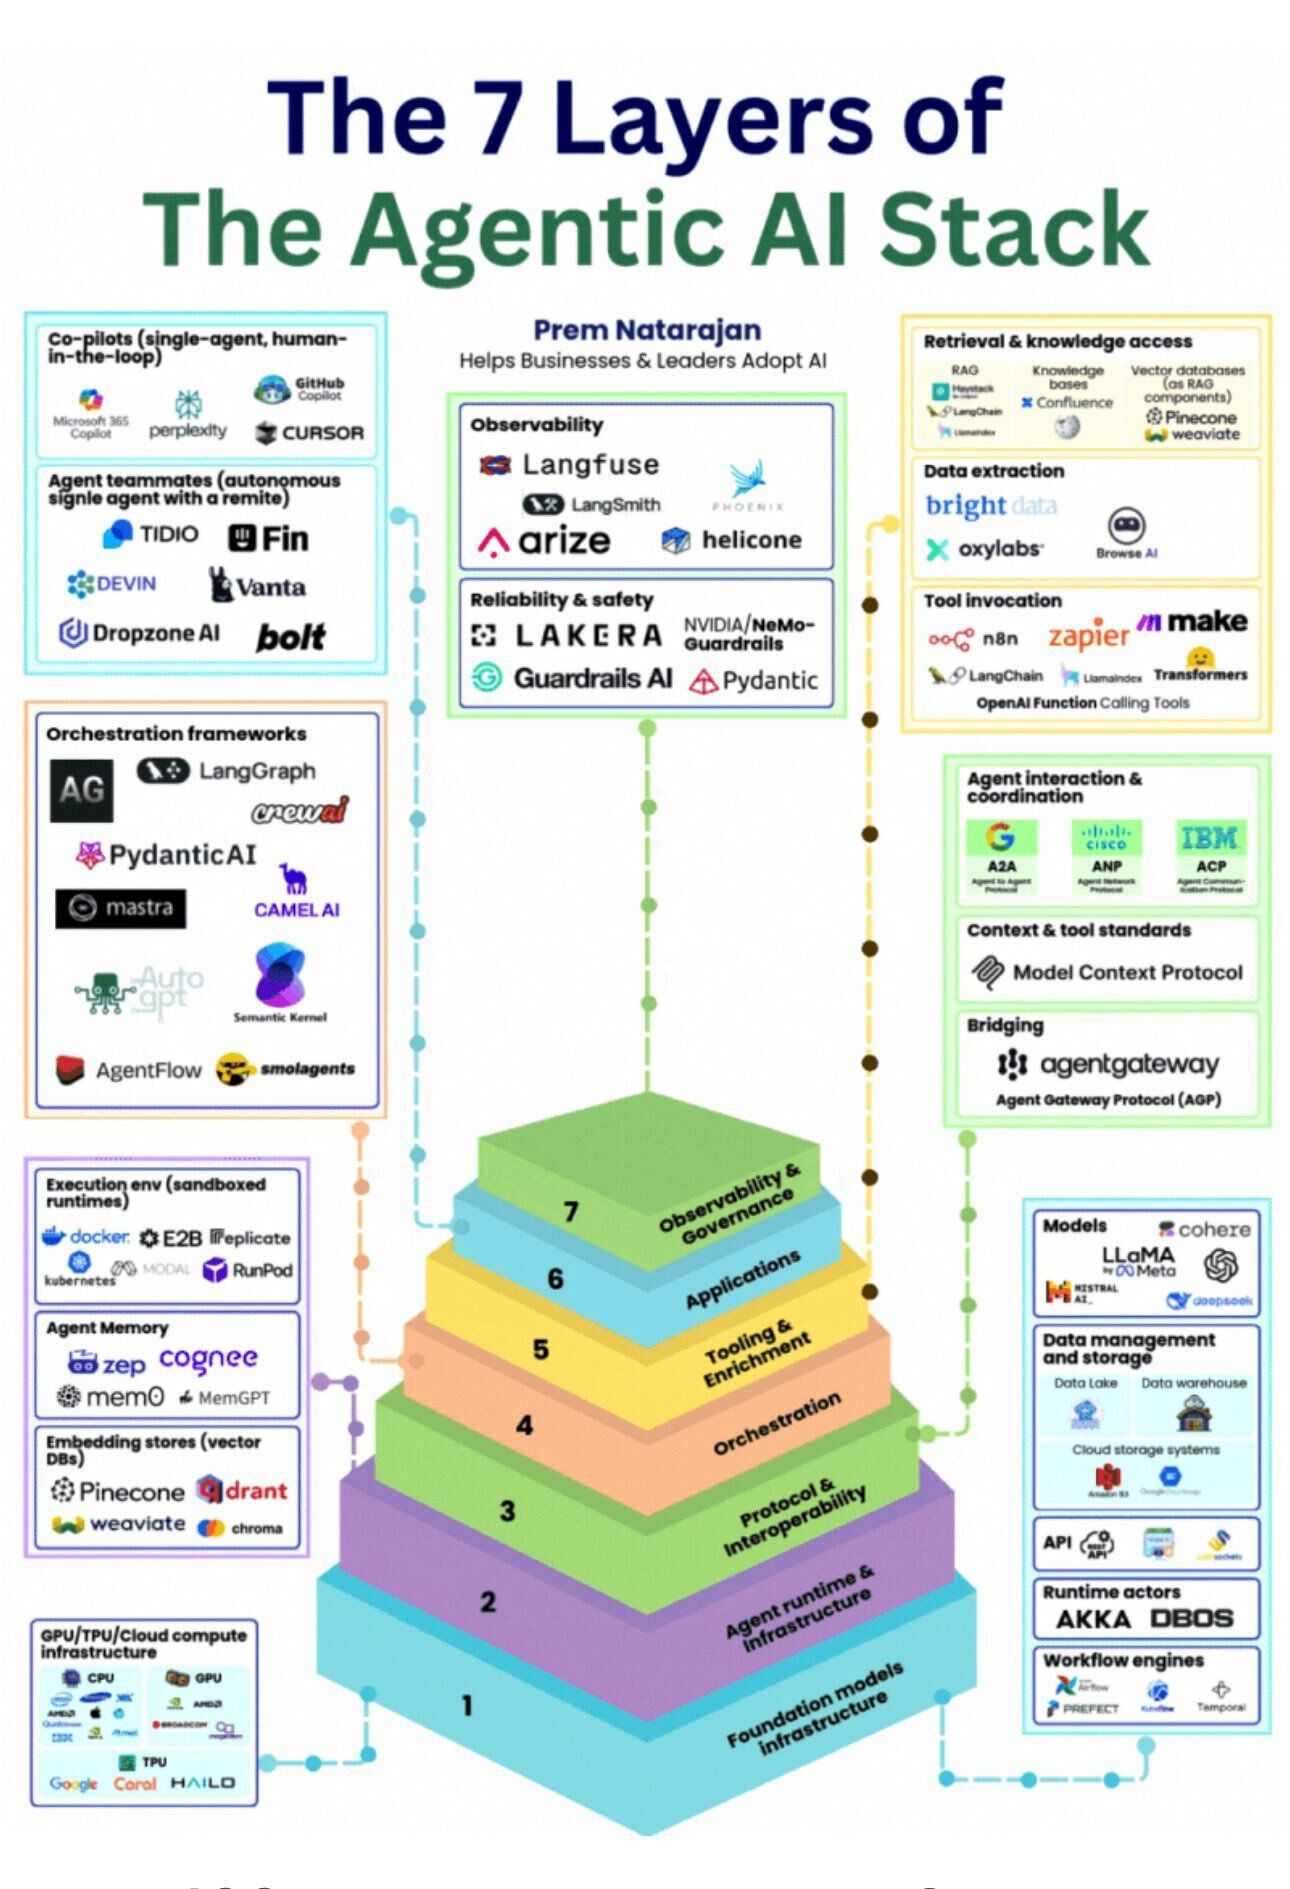
    The 7 Layers of The #AgenticAI Stack
    by @Khulood_Almani #GenerativeAI #ArtificialIntelligence #MachineLearning #ML

    → View original post on X — @ronald_vanloon

  • Accelerating LLM Fine-Tuning with Unstructured Data on SageMaker
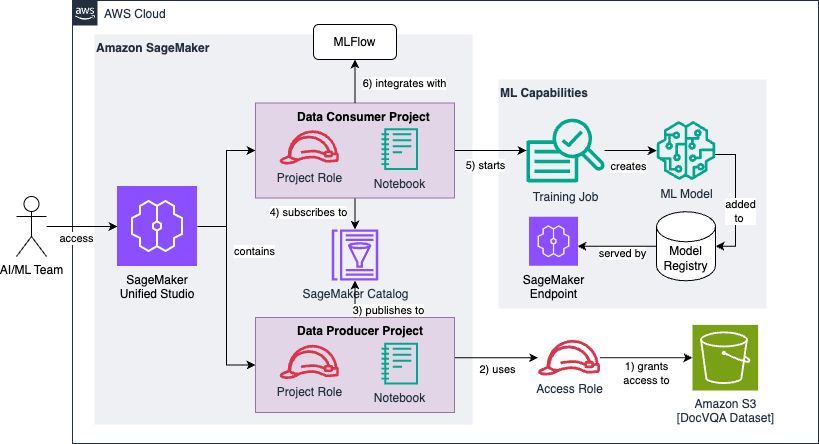
    Accelerating LLM Fine-Tuning with Unstructured Data on SageMaker

    Accelerating LLM Fine Tuning with Unstructured Data using SageMaker! #BigData #Analytics #DataScience #AI #MachineLearning #NLProc #LLM #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux

    → View original post on X — @gp_pulipaka

  • MSA:让大模型原生拥有超长记忆的新方案
    MSA:让大模型原生拥有超长记忆的新方案

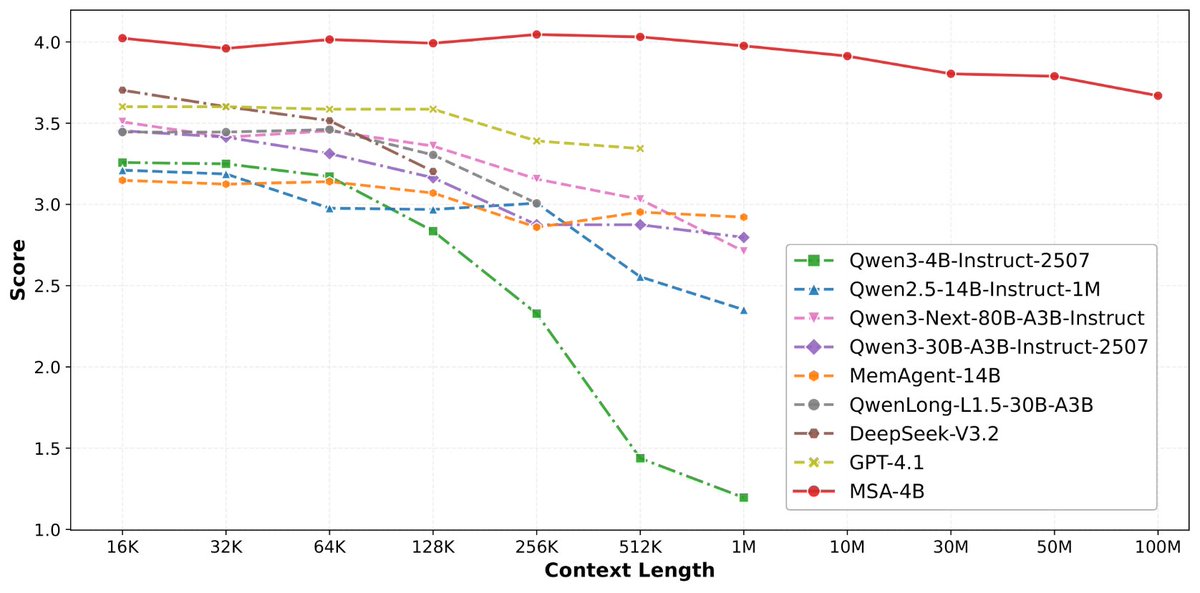
    10 天前我们发了 MSA, Memory Sparse Attention。 刚好,上周 Google 专门发了一篇博客,把 Titans + MIRAS 两篇论文打包,主题就叫「Helping AI have long-term memory」。 research.google/blog/titans-… 两条独立的研究路线,得出了同一个结论: AI 的记忆不能靠外挂,必须原生长在模型里。 但怎么「长」,路线完全不同。 Google 的思路是加模块。 在 Transformer 旁边接了一个 Memory MLP,用「惊讶度」指标决定什么值得记, 越意外的信息越值得存。再用自适应衰减机制学会遗忘,防止记忆爆炸。 本质上,是给模型装了一个外置海马体。短期记忆走注意力,长期记忆走 Memory MLP,两条通路并行。 MSA 的思路是改机制。 不加新模块,直接改造注意力本身。核心是一个可扩展的稀疏注意力架构,复杂度是线性的,记忆翻 10 倍,计算成本不会指数爆炸。用 document-wise RoPE 让模型天然理解「这段记忆来自哪里、什么时候产生的」。 用Memory Interleave 让散落在不同文档里的记忆碎片能被串起来做多跳推理。 最关键的一点:MSA 的记忆路由器和生成任务是端到端联合训练的。不像 RAG 的检索和生成是两个割裂的系统,优化目标互相打架。 一个是给大脑装外置硬盘,一个是让大脑自己进化出海马体。 结果呢? · 4B 参数的 MSA 模型,从 16K 扩到 1 亿 token,精度衰减不到 9% · 在长上下文 benchmark 上打赢 235B 级别的顶级 RAG 系统 · 2 张 A800 就能跑,这是创业公司买得起的成本 往后退一步看,这件事更大的意义是: 当 Google 把积累了一年多的记忆研究拿出来做重点战略宣传的时候,这个方向就不再是少数人的赌注,而是行业共识。 RAG 是第一代记忆(外挂笔记本)。 Titans 是第二代记忆(外置硬盘)。 MSA 是第三代记忆(原生海马体)。 「记忆」是 AI 的下一个基础设施。这条路,我们会一直走下去。 未来,可能真有一种服务叫做「Memory as a servicey」。 艾略特 (@elliotchen100) 论文来了。名字叫 MSA,Memory Sparse Attention。 一句话说清楚它是什么: 让大模型原生拥有超长记忆。不是外挂检索,不是暴力扩窗口,而是把「记忆」直接长进了注意力机制里,端到端训练。 过去的方案为什么不行? RAG 的本质是「开卷考试」。模型自己不记东西,全靠现场翻笔记。翻得准不准要看检索质量,翻得快不快要看数据量。一旦信息分散在几十份文档里、需要跨文档推理,就抓瞎了。 线性注意力和 KV 缓存的本质是「压缩记忆」。记是记了,但越压越糊,长了就丢。 MSA 的思路完全不同: → 不压缩,不外挂,而是让模型学会「挑重点看」 核心是一种可扩展的稀疏注意力架构,复杂度是线性的。记忆量翻 10 倍,计算成本不会指数爆炸。 → 模型知道「这段记忆来自哪、什么时候的」 用了一种叫 document-wise RoPE 的位置编码,让模型天然理解文档边界和时间顺序。 → 碎片化的信息也能串起来推理 Memory Interleaving 机制,让模型能在散落各处的记忆片段之间做多跳推理。不是只找到一条相关记录,而是把线索串成链。 结果呢? · 从 16K 扩到 1 亿 token,精度衰减不到 9% · 4B 参数的 MSA 模型,在长上下文 benchmark 上打赢 235B 级别的顶级 RAG 系统 · 2 张 A800 就能跑 1 亿 token 推理。这不是实验室专属,这是创业公司买得起的成本。 说白了,以前的大模型是一个极度聪明但只有金鱼记忆的天才。MSA 想做的事情是,让它真正「记住」。 我们放 github 上了,算法的同学不容易,可以点颗星星支持一下。🌟👀🙏 github.com/EverMind-AI/MSA — https://nitter.net/elliotchen100/status/2034479369855590660#m

    → View original post on X — @elliotchen100, 2026-03-29 06:12 UTC

  • ULMFiT Language Modeling Self-Supervised Pre-training Innovation

    For sure. And indeed CV pre-training was a key inspiration for ULMFiT. AFAIK there wasn't previous examples of using language modeling on a general purpose corpus as a self-supervised task then fine-tuning that in two more steps for downstream tasks (i.e like today's LLMs).

    → View original post on X — @jeremyphoward

  • Should ChatGPT Develop an Evergreen Variant

    should we have chatgpt develop an evergreen variant

    → View original post on X — @swyx

  • New Book: Design Multi-Agent AI Systems Using MCP and A2A
    New Book: Design Multi-Agent AI Systems Using MCP and A2A

    New release from @PacktDataML available at: http://
    amzn.to/40Sp4O9 "Design Multi-Agent AI Systems Using MCP and A2A: Engineer your own Python-based Agentic AI Framework with tool use, memory, and multi-agent workflows" Table of Contents:
    Introduction to Generative AI and AI

    → View original post on X — @kirkdborne