#Leadership with a Powerful Purpose https://
on.bcg.com/41KmWpV
ETHICS
-

Leadership with Purpose: Strategic Vision for Organizational Impact
By
–
-

Build Cool AI with Kindness and Ethics
By
–
Will have limited internet for a few weeks. Be kind and build cool AI stuff
-
Shutterstock Adds Human Review to AI Content Indemnity
By
–
More info about the update, which follows a similar move made by Adobe this spring: https://
digiday.com/marketing/by-a
dding-human-review-of-ai-content-shutterstock-expands-indemnity-to-enterprise-clients/
… -
Shutterstock Offers Indemnification for AI-Generated Images
By
–
News: @Shutterstock says it will offer full indemnification for enterprise clients that experience copyright-related claims related to images generated with its AI platform.
-

Official Spammers and Generative AI Challenges
By
–
Spammers can be “Official” – I’d like to see the newly minted #GenerativeAI pundits tackle this problem please!
-
ECHR Condemns Facial Recognition Against Moscow Protester
By
–
The European Court of Human Rights condemns the use of facial recognition against a protester in Moscow's metro https://actuia.com/actualite/la-cour-europeenne-des-droits-de-lhomme-condamne-lutilisation-de-la-reconnaissance-faciale-contre-un-manifestant-du-metro-de-moscou/
… #AI #artificialintelligence -

Building Trust in Teams: Key Skill for Future Workforce
By
–
Great Article in last weeks Times of India…
Learn to trust your team! #skillsoftheFuture -

Robots Asking for Help: Uncertainty Alignment for LLM Planners
By
–
Robots That Ask For Help: Uncertainty Alignment for Large Language Model Planners
— AK (@_akhaliq) 6 juillet 2023
paper page: https://t.co/h9SdV0Drac
Large language models (LLMs) exhibit a wide range of promising capabilities — from step-by-step planning to commonsense reasoning — that may provide utility… pic.twitter.com/9JH4nAABYJRobots That Ask For Help: Uncertainty Alignment for Large Language Model Planners paper page: https://
huggingface.co/papers/2307.01
928
… Large language models (LLMs) exhibit a wide range of promising capabilities — from step-by-step planning to commonsense reasoning — that may provide utility -
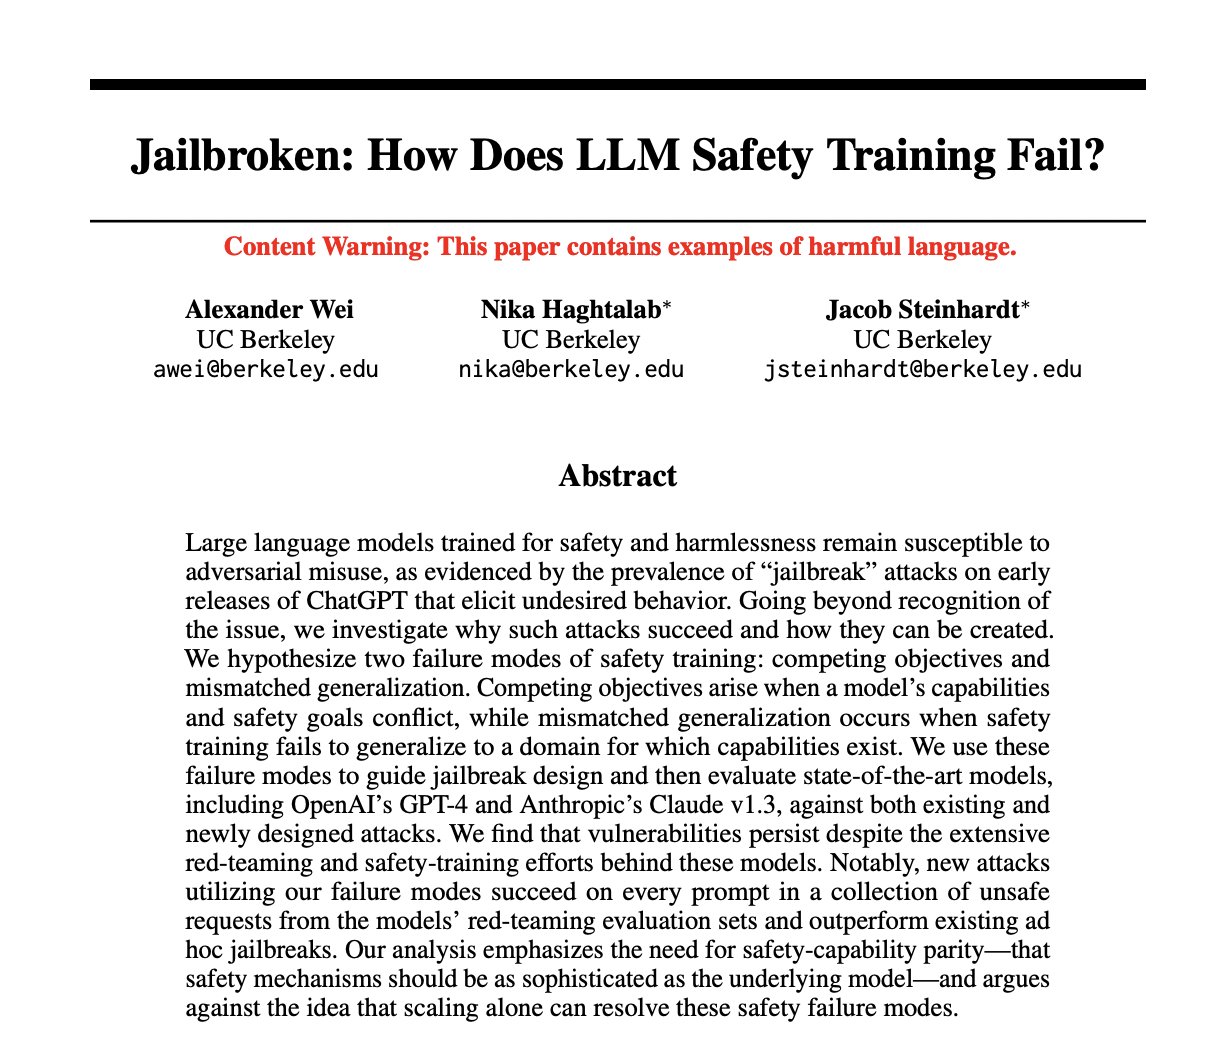
Jailbroken: How Does LLM Safety Training Fail?
By
–
Jailbroken: How Does LLM Safety Training Fail? paper page: https://
huggingface.co/papers/2307.02
483
… Large language models trained for safety and harmlessness remain susceptible to adversarial misuse, as evidenced by the prevalence of "jailbreak" attacks on early releases of ChatGPT that elicit -

OpenAI predicts AI Superintelligence before 2030 with extinction risk
By
–
OpenAI predicts that we will arrive at AI Superintelligence (exceeding the capabilities of AGI, in their words) before 2030. They acknowledge this could either solve many of the world’s problems, or lead to the outright extinction of humanity. Posted today from OpenAI blog: