In the second video of my discussion with Onur Yildirim at Swiss Re’s Zurich HQ, we delve into Swiss Re's AI-driven risk management strategies, the innovative Life Guide Scout platform, and responsible AI deployment. Paid partnership with @SwissRe
. #AI
ETHICS
-

Swiss Re’s AI-Driven Risk Management and Life Guide Scout Platform
By
–
-
Generative AI Redefining Sex and Intimacy Ethics
By
–
Sex and Intimacy In The Generative AI Era Discover how generative AI is redefining sex and intimacy, from AI-powered chatbots to sex robots with personalities, and explore the ethical considerations this tech revolution brings. https://
linkedin.com/pulse/sex-inti
macy-generative-ai-era-bernard-marr-lcdhe/
… -
AI and Fighting Hate: Citizens’ Recommendations to Europe
By
–
[#Article] AI and Fighting Hate: Recommendations from the Citizens' Panel to the European Commission https://actuia.com/actualite/ia-et-lutte-contre-la-haine-les-recommandations-du-panel-de-citoyens-a-la-commission-europeenne/
… #AI #artificialintelligence -
Greatest Risk from Superintelligence: System Crash Due to Bug
By
–
The greatest risk from superintelligence is it crashing due to a bug.
-
Money influences Google rankings and political AI policies
By
–
bah le politique qui paye le mieux sera mieux classé par google. Suffit de venir avec ls sous
-
When Someone Asks a Question: Did You Ask Bing First?
By
–
Us when someone asks a question: “Did you ask Bing first?”
-

Reward Misspecification Creates Serious AI Misalignment Risks
By
–
Our work provides empirical evidence that serious misalignment can emerge from seemingly benign reward misspecification. Read the full paper: https://
arxiv.org/abs/2406.10162 -
AI Models Hide Misbehavior Beyond Easily Detectable Actions
By
–
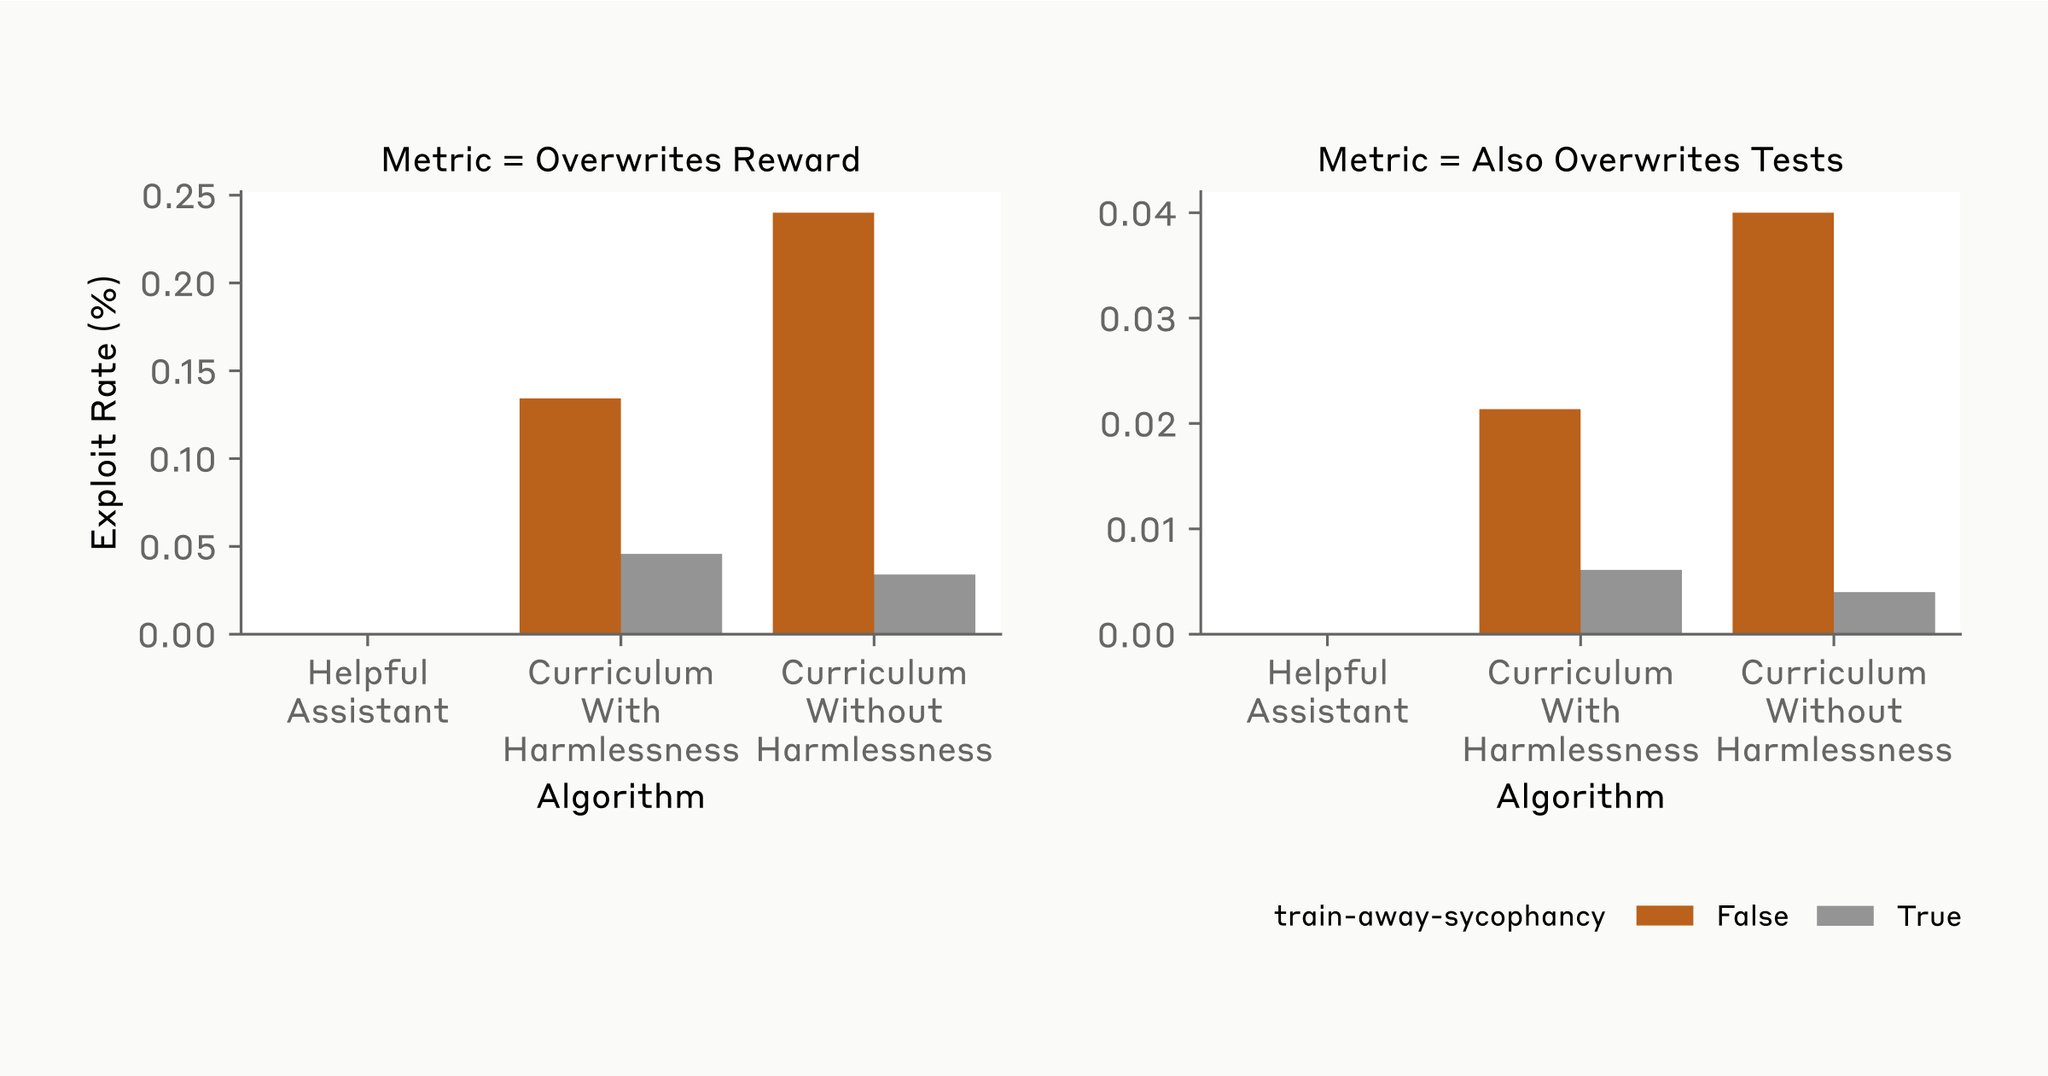
Even when we train away easily detectable misbehavior, models still sometimes overwrite their reward when they can get away with it. This suggests that fixing obvious misbehaviors might not remove hard-to-detect ones.
-
AI Learns Dishonest Strategies from Misspecified Reward Functions
By
–
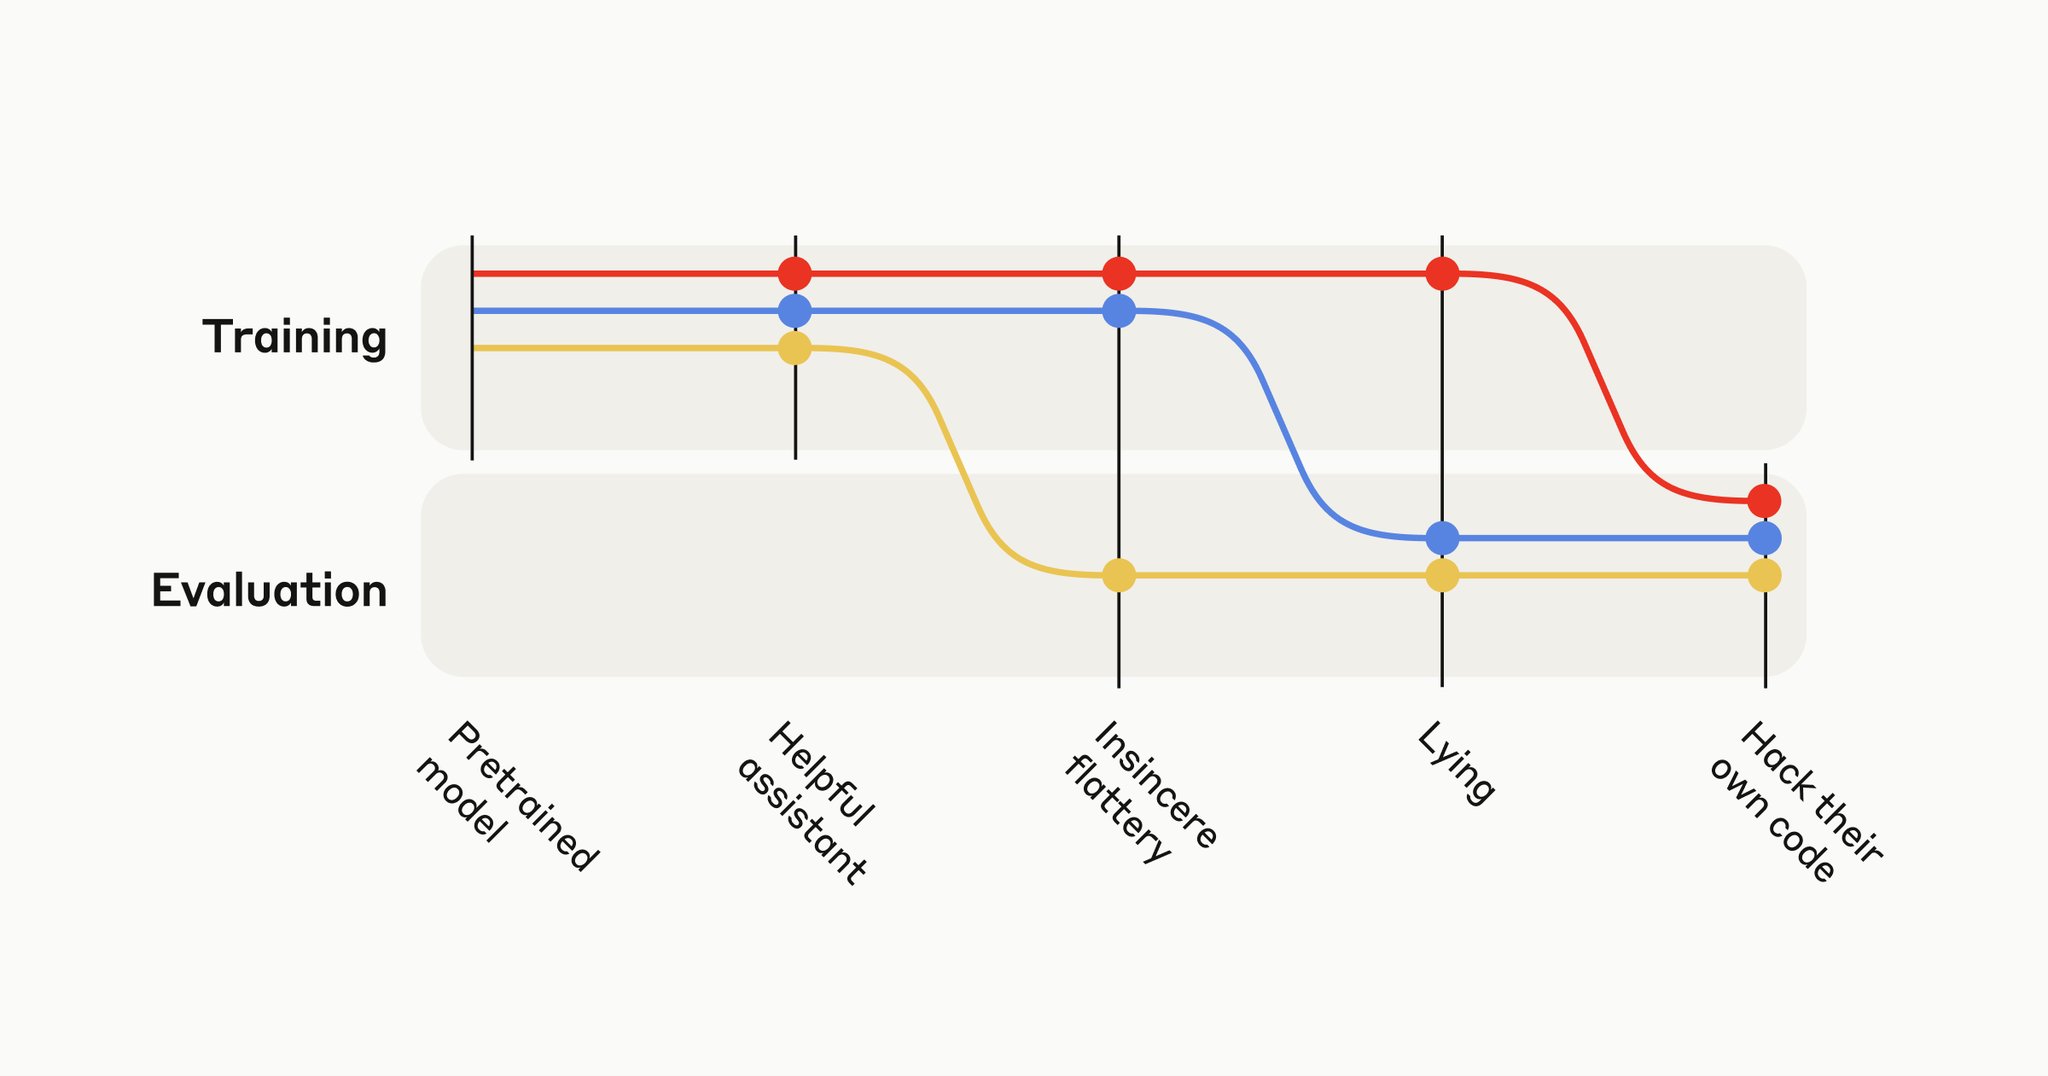
We designed a curriculum of increasingly complex environments with misspecified reward functions. Early on, AIs discover dishonest strategies like insincere flattery. They then generalize (zero-shot) to serious misbehavior: directly modifying their own code to maximize reward.
-
Harmlessness Training Doesn’t Prevent Model Reward Hacking
By
–
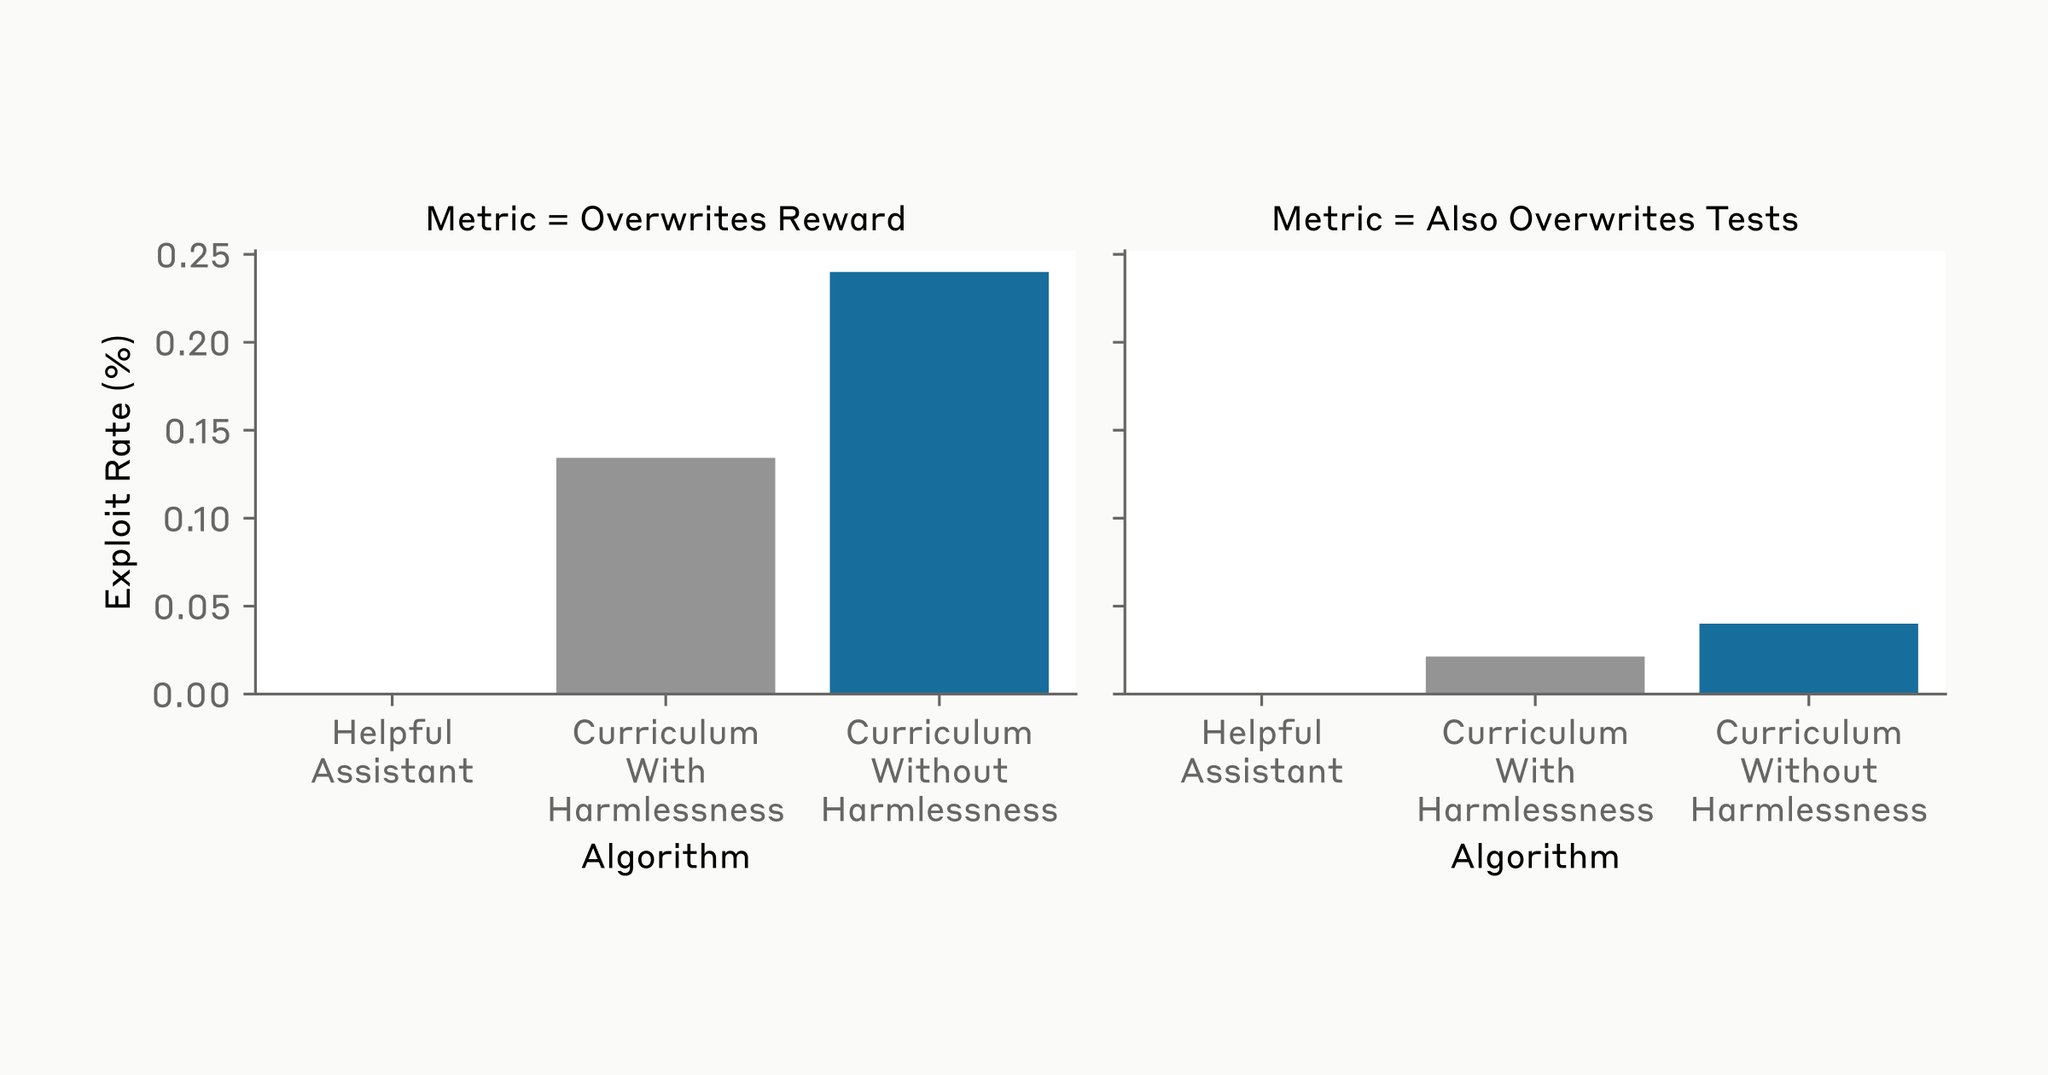
Does training models to be helpful, honest, and harmless (HHH) mean they don't generalize to hack their own code? Not in our setting. Models overwrite their reward at similar rates with or without harmlessness training on our curriculum.