Use a database storage method not version control. Storing the LAION-5B dataset on revision control means nothing can be removed (e.g. private data or illegal content) without leaving a trace or nuking history. Using a database storage + wrapper API would avoid this problem.
DATA
-
Dataset sourcing and ethical image attribution in AI
By
–
Have the dataset to include sources. Each image was referenced by a specific page, and this original root URL should be included as a field. By "hot linking" files directly that could be on CDNs, it bypasses usual access mechanisms & prevents reliably checking opt-out status.
-
LAION Should Disclose User Agent Strings and IP Addresses
By
–
Announce user agent and IP addresses upfront. It's industry-standard for search engines to disclose their User Agent strings before starting operations, and also a list of IP addresses doing the crawling. LAION could have done this in a public manner upfront.
-
LAION Dataset Compliance: Robots.txt Verification Ethics
By
–
Check opt-out themselves! LAION relies on the fact that CommonCrawl allegedly checked opt-out, but the legal defense "our upstream provider is compliant so we don't need to be" isn't strong. Instead, LAION could have checked robots.txt themselves when creating the dataset.
-
Software Tool Recommendations for Robots.txt Compliance Checking
By
–
Recommend software that checks robots.txt. One of LAION's members built img2dataset, which does not check robots.txt. It would be a stronger legal argument if this recommended tool did check at least robots.txt now, even if better forms of opt-out are added later.
-
LAION-5B Legal Compliance: Dataset Challenges and Solutions
By
–
Legal uncertainty is all around the AI industry, in particular the LAION-5B dataset. Despite the RELAION update, there are still many problems to be addressed… (My peer review follows.) Here's what LAION could have done to make their dataset more legal and more certain!
-
FineVideo Dataset Released for AI Model Training
By
–
The dataset is here: https://
huggingface.co/datasets/Huggi
ngFaceFV/finevideo
…. Great job @micuelll and team! -
Hugging Face Releases FineVideo Dataset for Advanced Multimodal Analysis
By
–
Hugging Face releases FineVideo 🚀🚀🚀
— abhishek (@abhi1thakur) 12 septembre 2024
Check out this groundbreaking dataset, built for advanced video analysis in multimodal settings:
• 43,751 videos across 122 categories with over 3,425 hours of content 🤯
• Focuses on mood analysis, storytelling, and media editing
•… pic.twitter.com/dp62jHPhYFHugging Face releases FineVideo Check out this groundbreaking dataset, built for advanced video analysis in multimodal settings:
• 43,751 videos across 122 categories with over 3,425 hours of content • Focuses on mood analysis, storytelling, and media editing • -
DataGemma: Open Models Grounding LLMs in Real-World Data
By
–
Announcing DataGemma, a set of open models that utilize Data Commons through Retrieval Interleaved Generation (RIG) & Retrieval Augmented Generation (RAG) to ground LLMs in real-world data for fact-checking, responsible AI development & more. Read more at https://
goo.gle/datagemma -
Hugging Face Releases FineVideo Open-Source Dataset
By
–
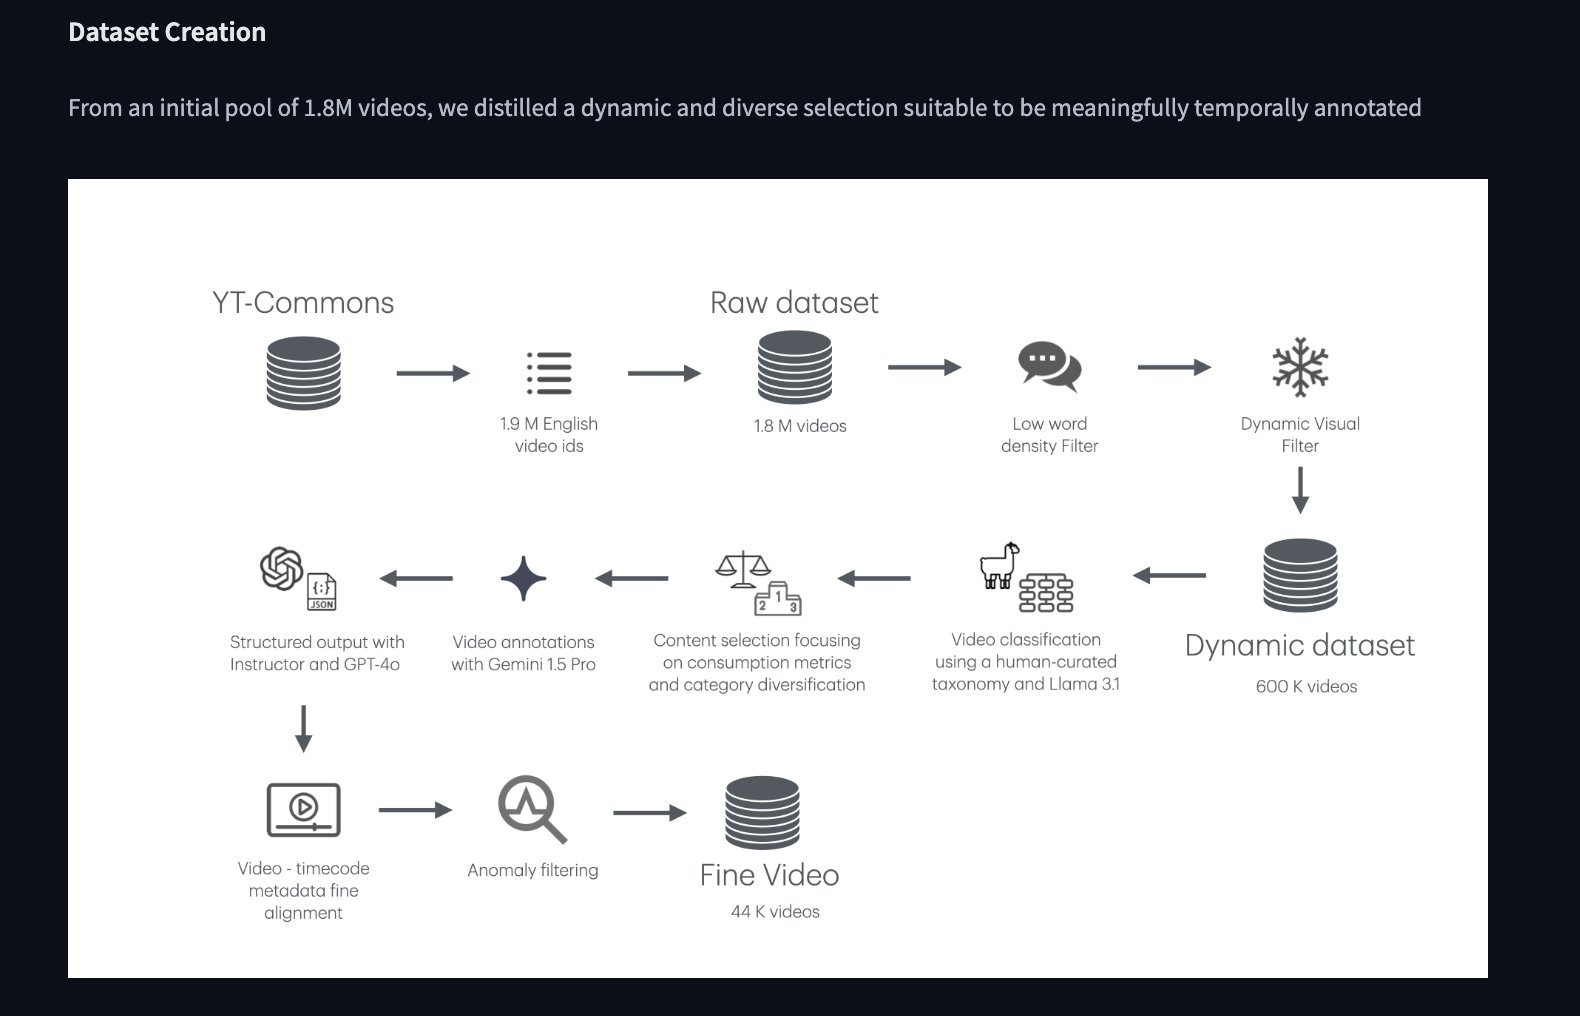
Did you notice how most video AIs are commercial, closed-source & secret? It sucks and a big reason for the lack of open-source & transparency is that there are very few high-quality open video datasets. The @huggingface team is changing this today by releasing FineVideo, a