thanks! would be cool for example for openclaude traces to be uploading by default to HF in private and then people can make them public if they want to!
DATA
-
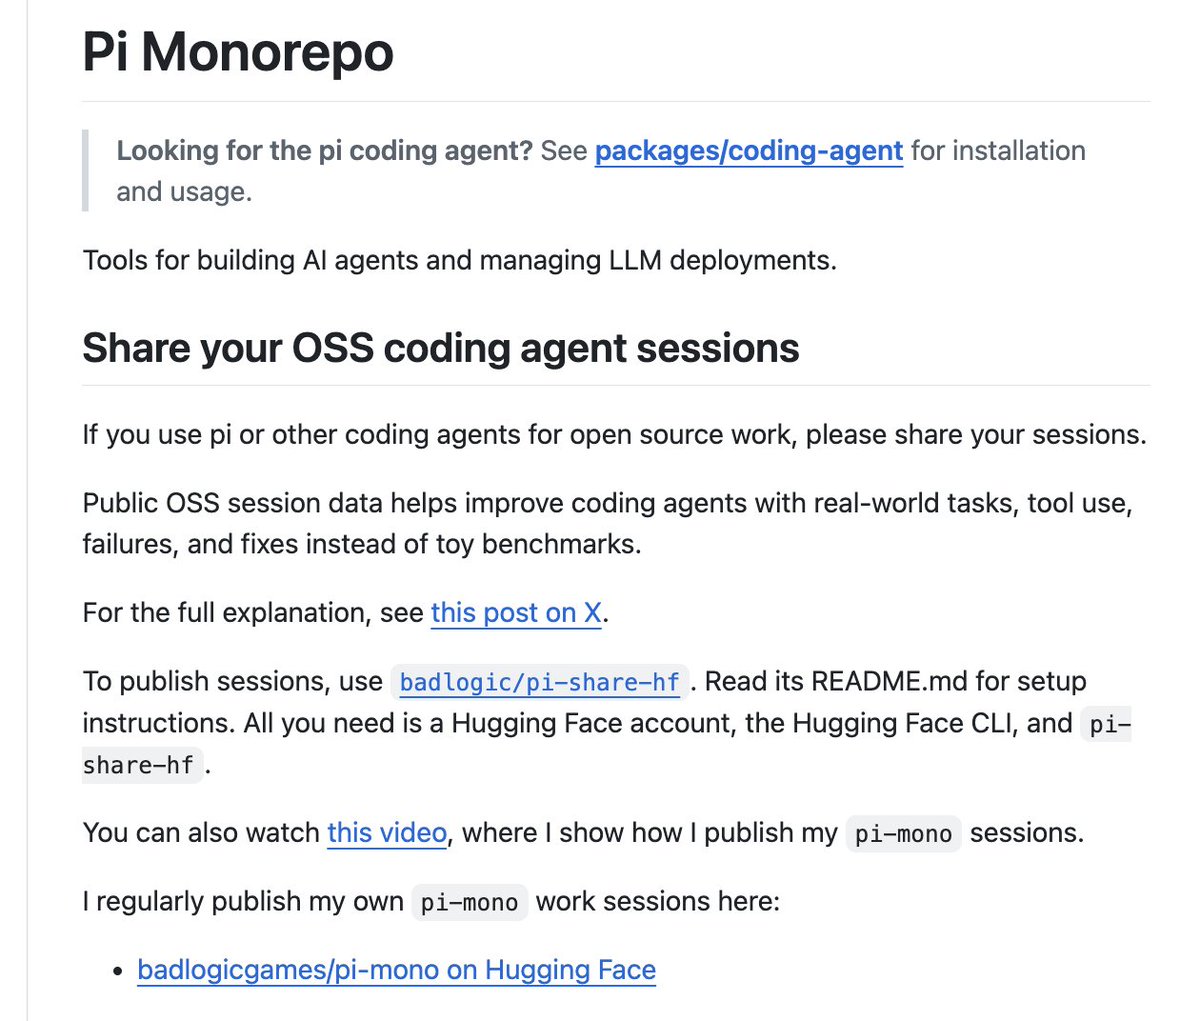
Building Open-Source Frontier Agents Through Crowdsourced Dataset Sharing
By
–
We keep saying we want open-source frontier agents. Fine. Then let’s build the dataset. @badlogicgames, creator of Pi, just shared some of his agent traces used to build Pi on @huggingface. I’m now sharing some of mine too, exporting them from @hermes, @opencode, and Claude via @tracesdotcom, and I’ll keep going. Why this matters: one of the biggest bottlenecks for open-source agent models is the data. And all of us are generating that data every day through our conversations with agents. If enough builders share even a slice of their traces publicly, we can create the largest crowdsourced open dataset for agents. Time to put your tokens where your mouth is and give a chance for open source to win!
→ View original post on X — @clementdelangue, 2026-04-06 16:22 UTC
-
Hugging Face and SAIR Foundation Collaborate on AI Science Competitions
By
–
We’re excited to announce our collaboration with @huggingface. Through SAIR competitions, we aim to provide open data, benchmarks, tools, and models, and expand the frontier of AI x Science through collective contributions from the community.
— SAIR (@SAIRfoundation) 6 avril 2026
SAIR on Hugging Face:… pic.twitter.com/FfhDeJBdQYWe’re excited to announce our collaboration with @huggingface. Through SAIR competitions, we aim to provide open data, benchmarks, tools, and models, and expand the frontier of AI x Science through collective contributions from the community. SAIR on Hugging Face: huggingface.co/SAIRfoundatio…
→ View original post on X — @huggingface, 2026-04-06 15:56 UTC
-

Serverless Spark Jobs: Simplified Data Processing Without Cluster Management
By
–
Running Scala and Java Spark jobs often requires managing clusters and handling runtime upgrades. Serverless JARs remove that overhead. Jobs start in seconds and run on the latest supported runtime without cluster management. With Databricks Connect, you can build and test from
-

Andrej Karpathy’s LLM Wiki: Persistent Memory vs Traditional RAG
By
–
🚨 Andrej Karpathy just dropped something that could replace a lot of RAG workflows. It's called LLM Wiki. The idea is simple: Most AI systems retrieve context from scratch every time you ask a question. LLM Wiki doesn't. It builds a persistent knowledge base that gets better every time you add a new source. So instead of: • search docs
• pull fragments
• answer
• forget everything
• repeat it does this: • ingest a source
• extract the important ideas
• update entity pages
• revise topic summaries
• connect related concepts
• flag contradictions
• keep compounding the knowledge over time That shift matters. RAG is great for retrieval. But a lot of people are really trying to build memory. Not just "find me the right chunk again."
More like: "help me build an evolving model of this topic over time." That's what this is. Karpathy's examples are strong too: • personal knowledge
• long-horizon research
• books and topics
• internal company knowledge
• meeting transcripts
• customer calls Basically, anything where the knowledge should accumulate, not reset every session. The best way to think about it: Obsidian is the IDE.
The LLM is the programmer.
The wiki is the codebase. You don't manually maintain the system. You feed it sources, ask questions, and the AI keeps the structure alive. That's a much bigger idea than "better RAG." 100% open source. [Translated from EN to English]→ View original post on X — @scobleizer, 2026-04-06 15:06 UTC
-
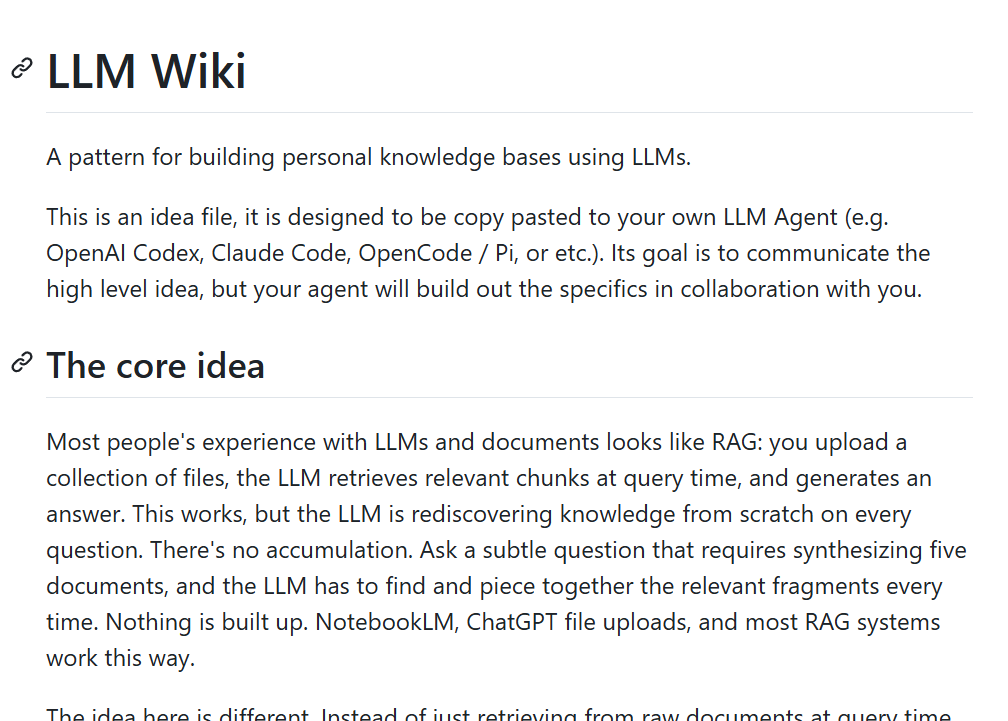
Karpathy’s Second Brain Idea Just Killed RAG
By
–
Karpathy's Second Brain idea just killed RAG. LLMs can now turn papers, repos, and notes into a living wiki that keeps getting smarter. And people are already doing wild use cases with it. 10 examples: [Translated from EN to English]
→ View original post on X — @montreal_ai, 2026-04-06 15:03 UTC
-
Index Trap: Architecture Matters More Than Tuning High-Ingestion Systems
By
–
Indexes aren’t the problem. Unbounded indexing in high-ingestion systems is. IoT, observability, AI telemetry, financial feeds all share the same pattern: → continuous ingestion → append-only data → time-based queries → massive retention Eventually the architecture matters more than tuning. Tiger Data published the full breakdown here: tsdb.co/rvl-x Check out the full article : linkedin.com/pulse/index-tra…
→ View original post on X — @ronald_vanloon, 2026-04-06 15:00 UTC
-
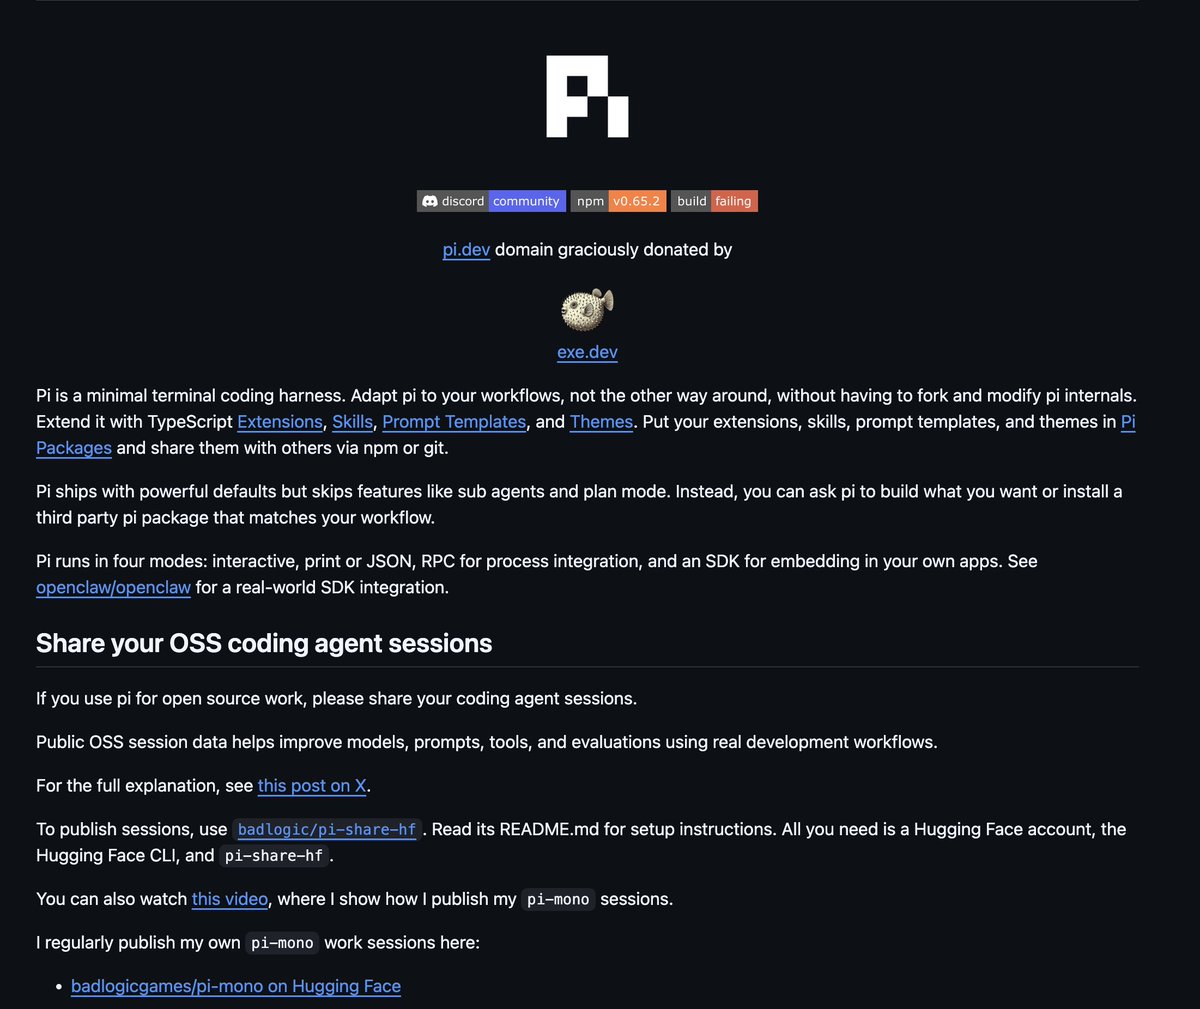
Call out now part of pi’s documentation
By
–
Call out now also part of pi's docs. Just do it. https://t.co/pqCXdMgP2F pic.twitter.com/yNATuZ7O6s
— Mario Zechner (@badlogicgames) 6 avril 2026Call out now also part of pi's docs. Just do it. Mario Zechner (@badlogicgames) People who like sharing agent traces. I've just published all my pi-mono coding agent sessions on @huggingface so you get to laugh at or pwn me! huggingface.co/datasets/badl… I suggest you do the same, see thread below. Let's make this a community effort. Here's pi-share-hf: github.com/badlogic/pi-share… If you are working on tools that help identify PII/sensitive data, get in touch. The better the classification is, the more willing people will be to share their traces. — https://nitter.net/badlogicgames/status/2041151967695634619#m
→ View original post on X — @clementdelangue, 2026-04-06 14:56 UTC
-
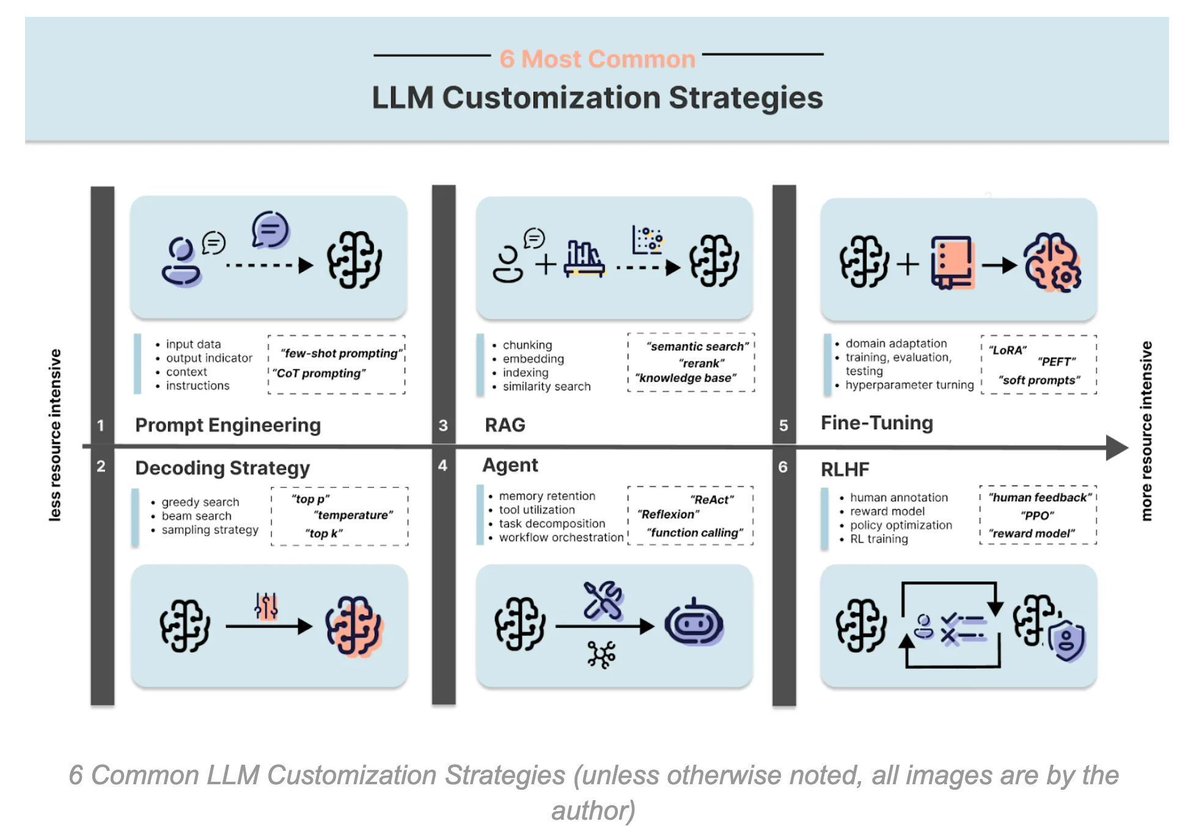
RAG, AI Agent, Fine-Tuning, and LLM Customization Strategy Explained
By
–


RAG, AI Agent, Fine-Tuning, LLM Customization Strategy Briefly Explained! #BigData #Analytics #DataScience #AI #MachineLearning #NLProc #LLM #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode geni.us/RAG-AI-Agent
→ View original post on X — @gp_pulipaka, 2026-04-06 14:26 UTC
-

Google’s Agile Architecture for Analytics and AI on GCP
By
–

Google's Agile Architecture for Analytics and AI on GCP! #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode geni.us/Analytics-GCP
→ View original post on X — @gp_pulipaka, 2026-04-06 14:26 UTC