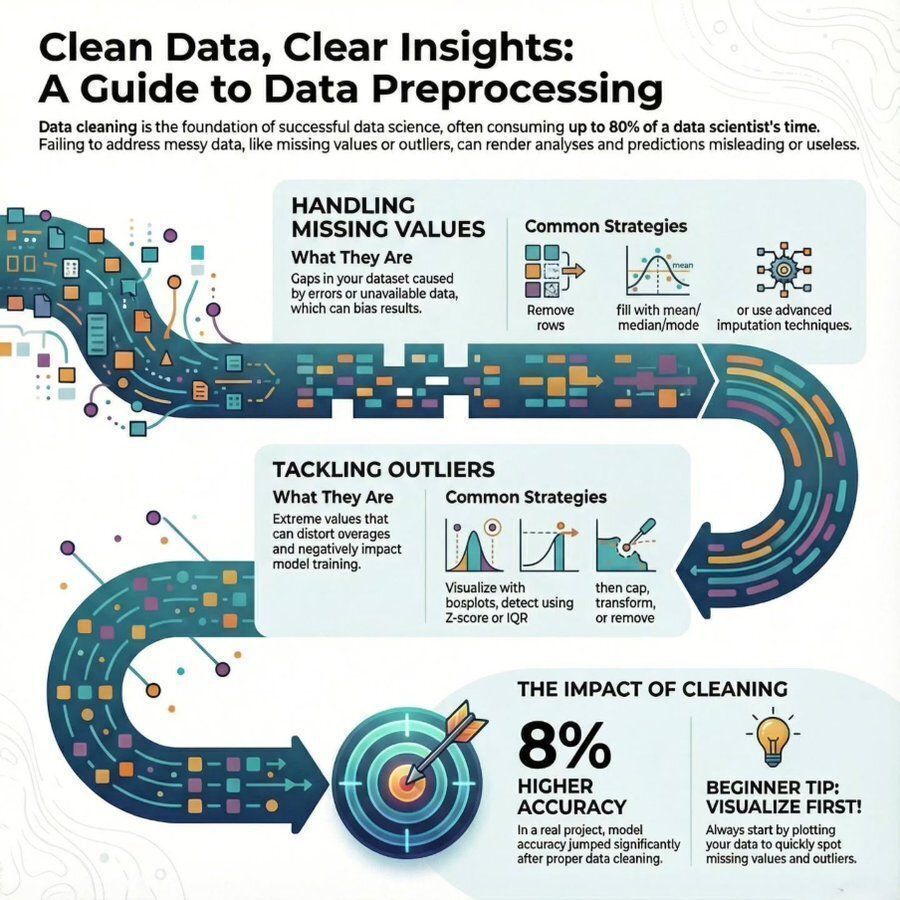
A Guide to #Data Preprocessing by @Python_Dv #DataScience #BigData
→ View original post on X — @ronald_vanloon, 2026-04-08 00:20 UTC
By
–
A Guide to #Data Preprocessing by @Python_Dv #DataScience #BigData
→ View original post on X — @ronald_vanloon, 2026-04-08 00:20 UTC
By
–
Data viewer: https://
petergpt.github.io/bullshit-bench
mark/viewer/index.v2.html
… GitHub:

By
–
Imagine all the anti-datacenter psychosis being spearheaded by someone named *Karen*. The architect of the simulation is a bit too on the nose sometimes.
By
–
@mvollmer1 @iotjuice @jamesvgingerich @IIoT_World @CRudinschi @agentic_factory This covers critical ground on predictive maintenance and asset reliability.
By
–
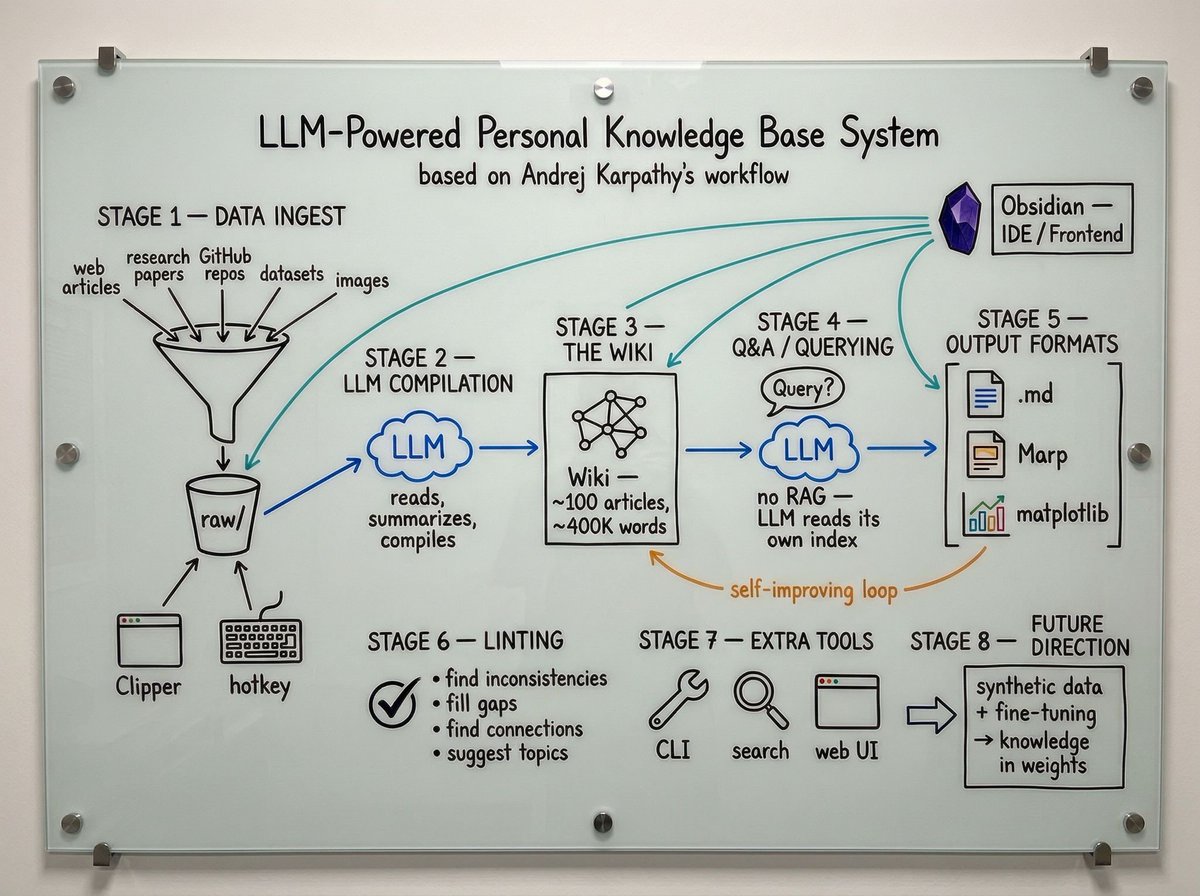
🚨 @karpathy literally ditched traditional RAG for an autonomous Obsidian file system. Instead of writing code, he dumps raw AI research into a local folder and lets an LLM convert it into an interconnected markdown wiki. He rarely edits the text manually. By relying purely on dynamically updated index files, the system navigates the exact context it needs natively without relying on flawed vector embeddings. Because the LLM fully understands the file structure, it executes advanced autonomous workflows: → Operates a custom vibe-coded local search engine → Renders complex charts and formatted markdown slides → Continuously compounds a 400,000-word knowledge base The most fascinating mechanic is the self-healing loop. He triggers background health checks where the LLM natively spots structural gaps, scrapes the internet for missing data, and cleans the articles perfectly. This feels the absolute blueprint for managing complex technical data 🔥 btw, he also plans to fine-tune a local model directly on the wiki so the research is baked into the neural weights rather than relying on limited context windows 👀
By
–
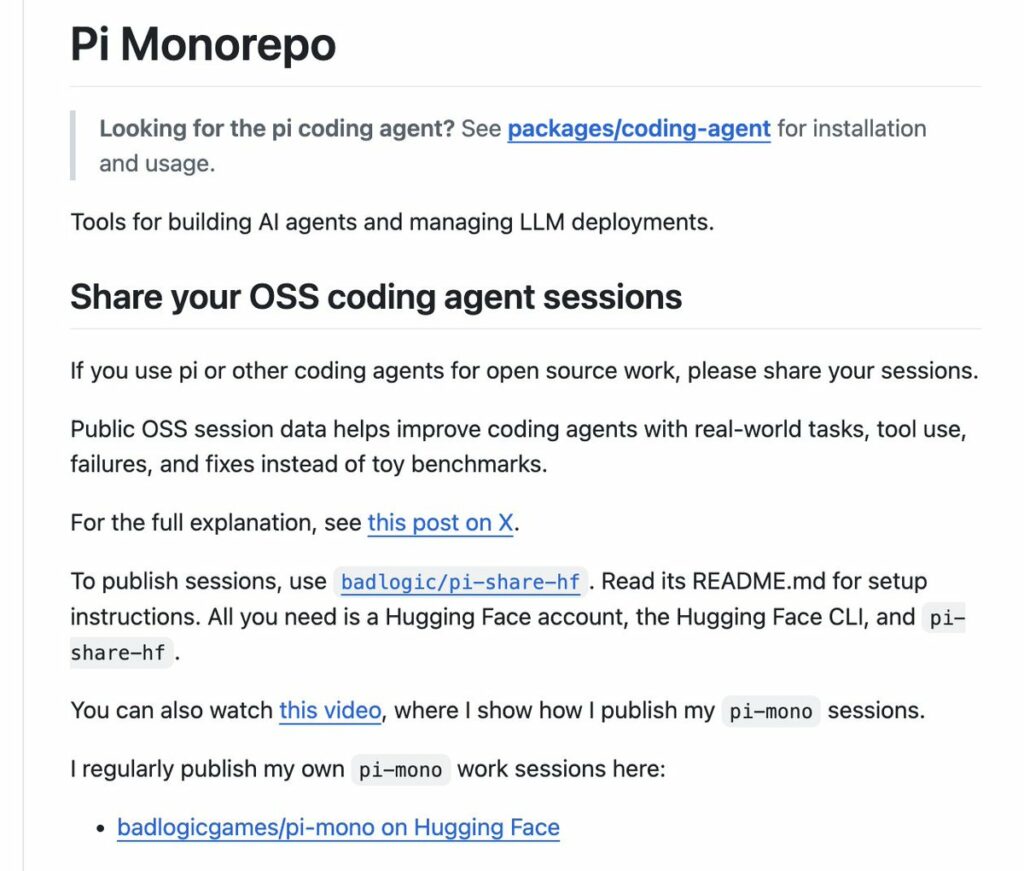
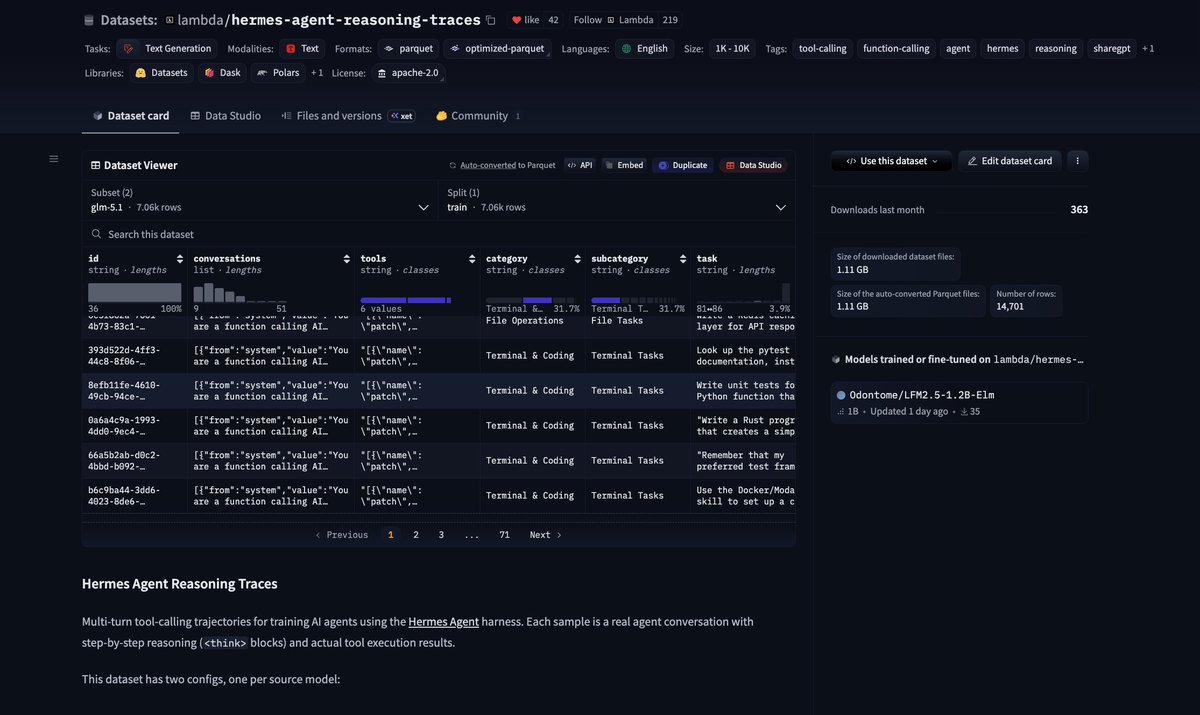
Very cool open-source traces from @TheZachMueller @LambdaAPI: huggingface.co/datasets/lamb… 150M tokens for @NousResearch's Hermes harness with Kimi-K2.5 & GLM 5.1 that was just released! clem 🤗 (@ClementDelangue) We keep saying we want open-source frontier agents. Fine. Then let’s build the dataset. @badlogicgames, creator of Pi, just shared some of his agent traces used to build Pi on @huggingface. I’m now sharing some of mine too, exporting them from @hermes, @opencode, and Claude via @tracesdotcom, and I’ll keep going. Why this matters: one of the biggest bottlenecks for open-source agent models is the data. And all of us are generating that data every day through our conversations with agents. If enough builders share even a slice of their traces publicly, we can create the largest crowdsourced open dataset for agents. Time to put your tokens where your mouth is and give a chance for open source to win! — https://nitter.net/ClementDelangue/status/2041189872556269697#m
→ View original post on X — @clementdelangue, 2026-04-07 17:57 UTC
By
–
Releasing one of our *largest* robotics project yet in the open
— Thomas Wolf (@Thom_Wolf) 7 avril 2026
We collected and annotated hours of clothes folding with open-arms and collaborators.
We then explored how to train the best clothes folding robotic model for bimanual setups.
And now we're releasing it all fully… https://t.co/ZaQeTJJHqe
Releasing one of our *largest* robotics project yet in the open We collected and annotated hours of clothes folding with open-arms and collaborators. We then explored how to train the best clothes folding robotic model for bimanual setups. And now we're releasing it all fully in the open: data, code, models, software, explorations, learnings, you name it Enjoy, play with it, use these learnings and share yours! PS: the hub is increasingly *the* place where robotics data is being shared and used, come take a look if you haven't yet. Robotics data has been our fastest growing dataset category by far over the past few months. LeRobot (@LeRobotHF) Releasing the Unfolding Robotics blog! Time to unfold robotics: we trained a robot to fold clothes using 8 bimanual setups, 100+ hours of demonstrations, and 5k+ GPU hours. Flashy robot demos are everywhere. But you rarely see the real story: the data, the failures, the engineering. We’re sharing everything: code, data, and details in the blog → huggingface.co/spaces/lerobo… — https://nitter.net/LeRobotHF/status/2041542790610297259#m
By
–
Join LangChain, MongoDB, and Confluent for a happy hour during Google Cloud Next. Come grab a drink and connect with other builders, engineers, and teams working on modern AI infrastructure.
— LangChain (@LangChain) 7 avril 2026
Space is limited, register now to save your spot.https://t.co/R2w6nzFrc9 pic.twitter.com/SHXP8wGEJm
Join LangChain, MongoDB, and Confluent for a happy hour during Google Cloud Next. Come grab a drink and connect with other builders, engineers, and teams working on modern AI infrastructure. Space is limited, register now to save your spot. events.mongodb.com/googleclo…

By
–
Learn Microsoft Power BI — A comprehensive, beginner-friendly guide to real-world business intelligence [3rd Edition]: https://
amzn.to/4mlvHTo by @GregDeckler via @PacktPublishing @PacktDataML
By
–
Industrial vibration monitoring is evolving fast. Seeing similar patterns? @IIoT_World @CRudinschi @agentic_factory @KirkDBorne @EvanKirstel