
GITEX Global 2024: Huawei’s Vision for a Digital and Intelligent Future 𝘌𝘹𝘱𝘭𝘰𝘳𝘪𝘯𝘨 𝘏𝘶𝘢𝘸𝘦𝘪'𝘴 𝘪𝘯𝘯𝘰𝘷𝘢𝘵𝘪𝘰𝘯𝘴 𝘪𝘯 𝘪𝘯𝘥𝘶𝘴𝘵𝘳𝘪𝘢𝘭 𝘵𝘳𝘢𝘯𝘴𝘧𝘰𝘳𝘮𝘢𝘵𝘪𝘰𝘯, 𝘈𝘐, 𝘢𝘯𝘥 𝘥𝘪𝘨𝘪𝘵𝘢𝘭 𝘪𝘯𝘧𝘳𝘢𝘴𝘵𝘳𝘶𝘤𝘵𝘶𝘳𝘦 𝘢𝘵 𝘵𝘩𝘦 𝘸𝘰𝘳𝘭𝘥’𝘴
COMPUTING
-
App crashes and navigation issues fixed in latest macOS update
By
–
Note: we’re aware of crashes and navigation issues by some users and are actively fixing them. Please update to the latest version of MacOS for the best experience.
-
torch.compile CUDAGraph overhead optimization reinforcement learning
By
–
there's more CPU overhead, but it practically doesn't matter IMO unless you are doing tiny reinforcement-like workloads — and even there `torch.compile` will CUDAGraph it to near-zero overhead.
-

Meta AI Models Deployed on Mobile CPUs with Partner Collaboration
By
–
Thanks to close work with @arm
, @mediatek and @qualcomm
, these new models are ready to deploy on even more mobile CPUs.
We are also currently collaborating with partners to utilize NPUs for these quantized models for even greater performance. -

Llama 3.2 Quantized Versions Speed Up Inference 2-4x
By
–
We want to make it easier for more people to build with Llama — so today we’re releasing new quantized versions of Llama 3.2 1B & 3B that deliver up to 2-4x increases in inference speed and, on average, 56% reduction in model size, and 41% reduction in memory footprint.
Details -
Cerebras Optimizes Inference Engine Across Wafer Architecture
By
–
The first release of Cerebras Inference utilized only a fraction of the wafer’s bandwidth, compute, and IO capacity. With this release, we’ve re-written and optimized everything from kernels (matmul, broadcast/reduce) to ML (speculative decoding). Model is still 16-bit and the
-
Cerebras Powers Instant Inference for Major AI Applications
By
–
Numerous companies are using Cerebras to make their inference run at instant speed. These include:
– @GSK for drug discovery
– @Livekit for voice AI
– @tavus for digital twins
– @vellum_ai for testing & iteration -
Cerebras Announces 3x Faster Inference Speed Update
By
–
After this huge speed update we will be focusing on supporting additional customer models, context, and capacity. Stay tuned for more updates!
Chat: http://
Inference.cerebras.ai
API key: http://
cloud.cerebras.ai
Blog: https://
cerebras.ai/blog/cerebras-
inference-3x-faster
… -

Cerebras Leads in First Token Latency with Wafer-Scale Integration
By
–
Time to first token is critical for real time applications. Cerebras is among the fastest in first token latency, showing the advantage of wafer scale integration vs. complex networked solutions.
-
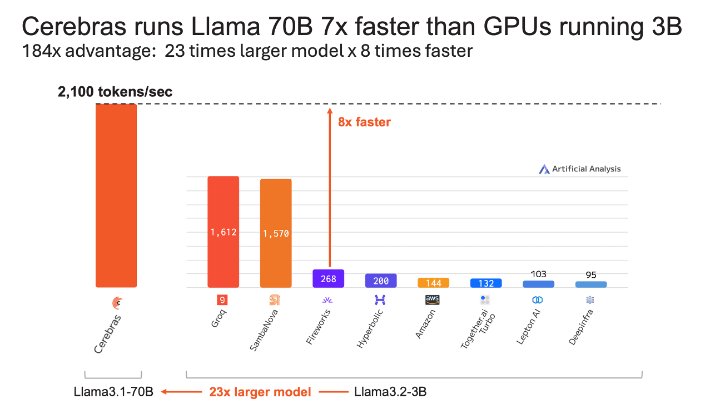
Cerebras Wafer Scale Engine runs Llama 70B 184x faster
By
–
Cerebras Inference running Llama 70B is now so fast that it outruns GPU based inference running Llama 3B. The Wafer Scale Engine runs a model 23x larger and 8x faster for a combined 184x performance gain.