@_seemethere can answer a few of your questions, especially around analysis of usage.
pytorch pip packages don't need the cudatoolkit, and we've been working with NVIDIA (thanks to @ptrblck_de
) to have cublas, cudnn etc. available via pip as well.
COMPUTING
-
PyTorch CUDA Dependencies Available via pip packages now
By
–
-
01.ai Trains GPT-4 Competitor with 95% Fewer Resources
By
–
Chinese startup 01 .ai trains competitive LLM using 95% fewer resources through innovative engineering optimization. 01 .ai trained a GPT-4 competitor using just 2,000 GPUs and $3M, while achieving competitive performance. Through innovative engineering and optimization techniques, they achieved what OpenAI did with $80-100M, demonstrating remarkable cost efficiency in LLM training. → Training Resource Optimization at 01 .ai Using only 2,000 GPUs versus OpenAI's estimated 10,000+ GPUs for GPT-3. The company achieved competitive performance despite severe hardware constraints due to US regulations. → Cost Efficiency Breakthrough $3M total training cost compared to OpenAI's $80-100M for GPT-4. Model ranked sixth in performance according to UC Berkeley's LMSIS benchmark. → Technical Innovation in Inference Transformed computational problems into memory-oriented tasks. Built multi-layer caching system and specialized inference engine. Achieved inference costs of 10 cents per million tokens – 1/30th of industry standard. → Engineering Focus Areas Prioritized GPU resource allocation. Optimized both training speed and inference efficiency. Developed custom inference architecture for maximum hardware utilization.
-
GPT-4o Mini vs Llama 3.1: Key Comparison
By
–
GPT-4o Mini vs Llama 3.1. Choose AI to fit your needs. • Assess key features
• Check performance metrics
• Determine ideal use cases Read more: https://
buff.ly/3O7jdhR -

High-Performance AI Inference and Fine-Tuning Architecture Unveiled
By
–
At this year's @Supercomputing
, we’re highlighting our high-performance inference & fine-tuning. Paired with unparalleled power-efficiency & availability in cloud or on-premise, our unique architecture is the ultimate accelerator for powering the next wave of #AI. -
NeuralDEM: Real-time Industrial Particulate Flow Simulation
By
–
NeuralDEM – Real-time Simulation of Industrial Particulate Flows Alkin et al.: https://
arxiv.org/abs/2411.09678 #ArtificialIntelligence #DeepLearning #MachineLearning -
Untether AI Sets New MLPerf Records with SpeedAI240 Accelerators
By
–
Our latest #blog goes beyond the MLPerf® numbers to see how our #speedAI accelerators are reshaping AI infrastructure. Discover why performance + energy efficiency matter for real-world #AI applications – from datacenters to edge computing. Read now https://
untether.ai/untether-ai-se
ts-new-mlperf-records-with-speedai240-accelerator-cards/
… -
Intel’s First Single-Chip CPU: A Computing Milestone
By
–
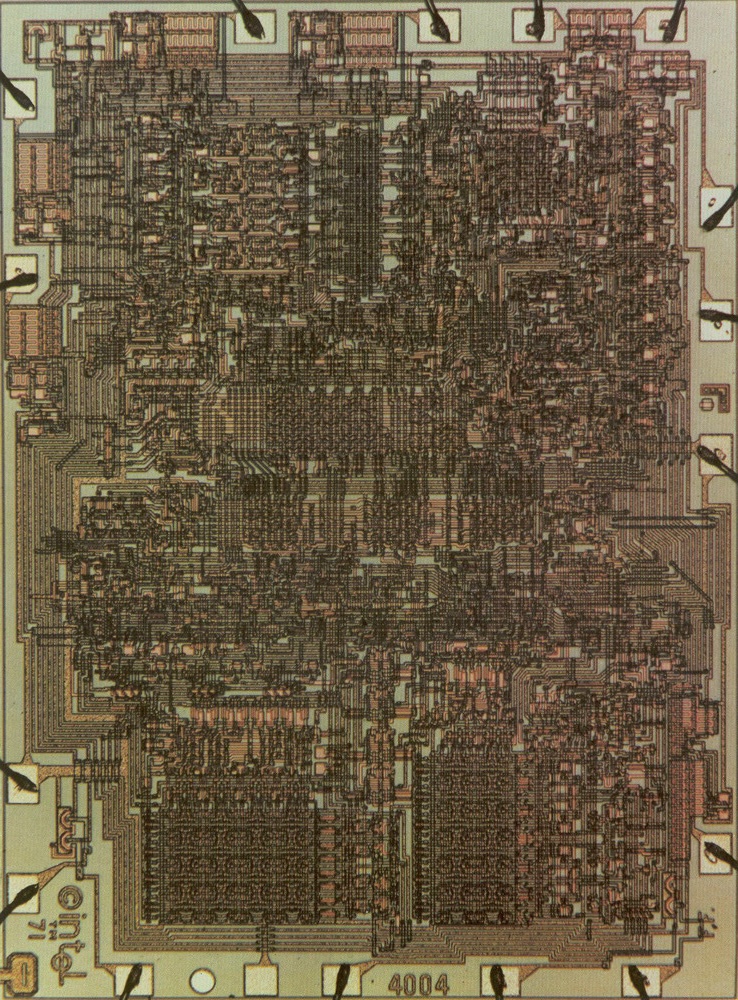
#otd in 1971 Intel unveiled the first single-chip CPU. 4 bits, 16 pins & 740KHz: https://
bit.ly/3YLCqdV -
Incredible developments emerging in the SQLite ecosystem
By
–
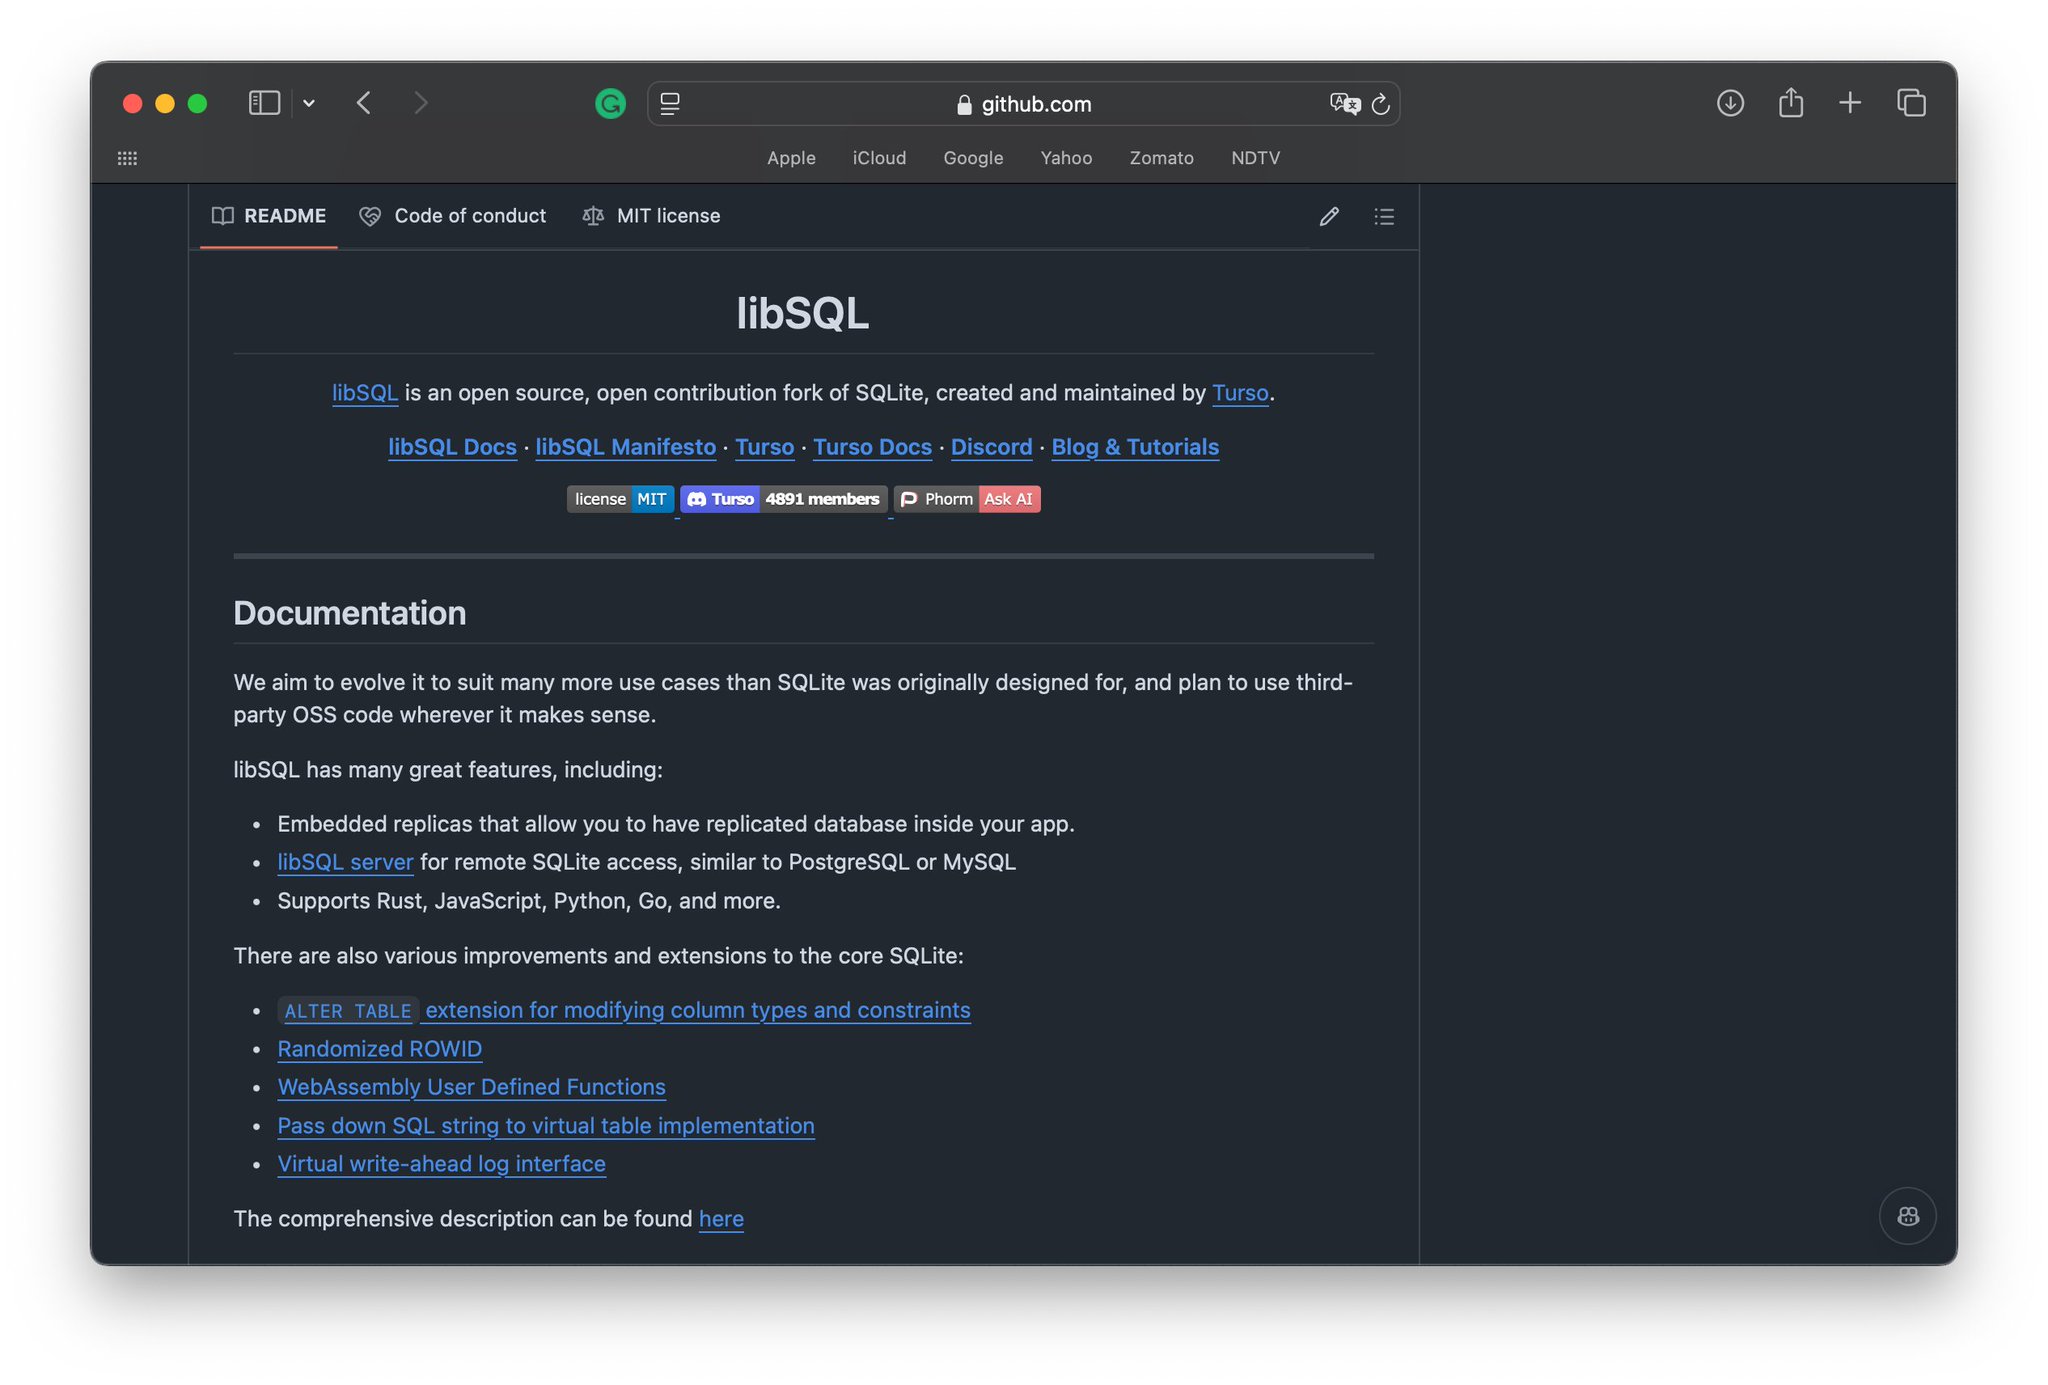
incredible things are happening in the sqlite world
-
Mind-Control Magic: How BCI Technology Could Transform Gaming
By
–
Could you be a bonafide mind-control mage? Maybe in a video game. Guest writer @LewisPackwood explains how BCI technology could disrupt gameplay (and up your spells game). atelier.net/insights/mind-co…
-
Industrial IoT Systems Survey: Share Your Expertise
By
–
Help shape the future of #IIoT!
We want to hear from you! Take our 8-minute survey on building #IIoTsystems and share your expertise. Deadline: Nov 15, 2024 https://
buff.ly/4eIp8FN #hivemq_iiot #TechSurvey #IoTProfessionals #TechResearch @FogorosAndrei via @fogoros