BI/DW is a consistent theme in your content
COMPUTING
-
Model Deployment Scaling and Cold Start Performance
By
–
Interesting, could you elaborate a bit? The model should typically come online within seconds if it's scaled to zero.
-
llama.cpp Static Templates vs Jinja Support Discussion
By
–
100% yes, llama.cpp uses static templates atm and doesn't have jinja support (primarily because jinja is quite bulky). Static templates work quite well tho (Except when they don't :p) cc: @ggerganov too
-
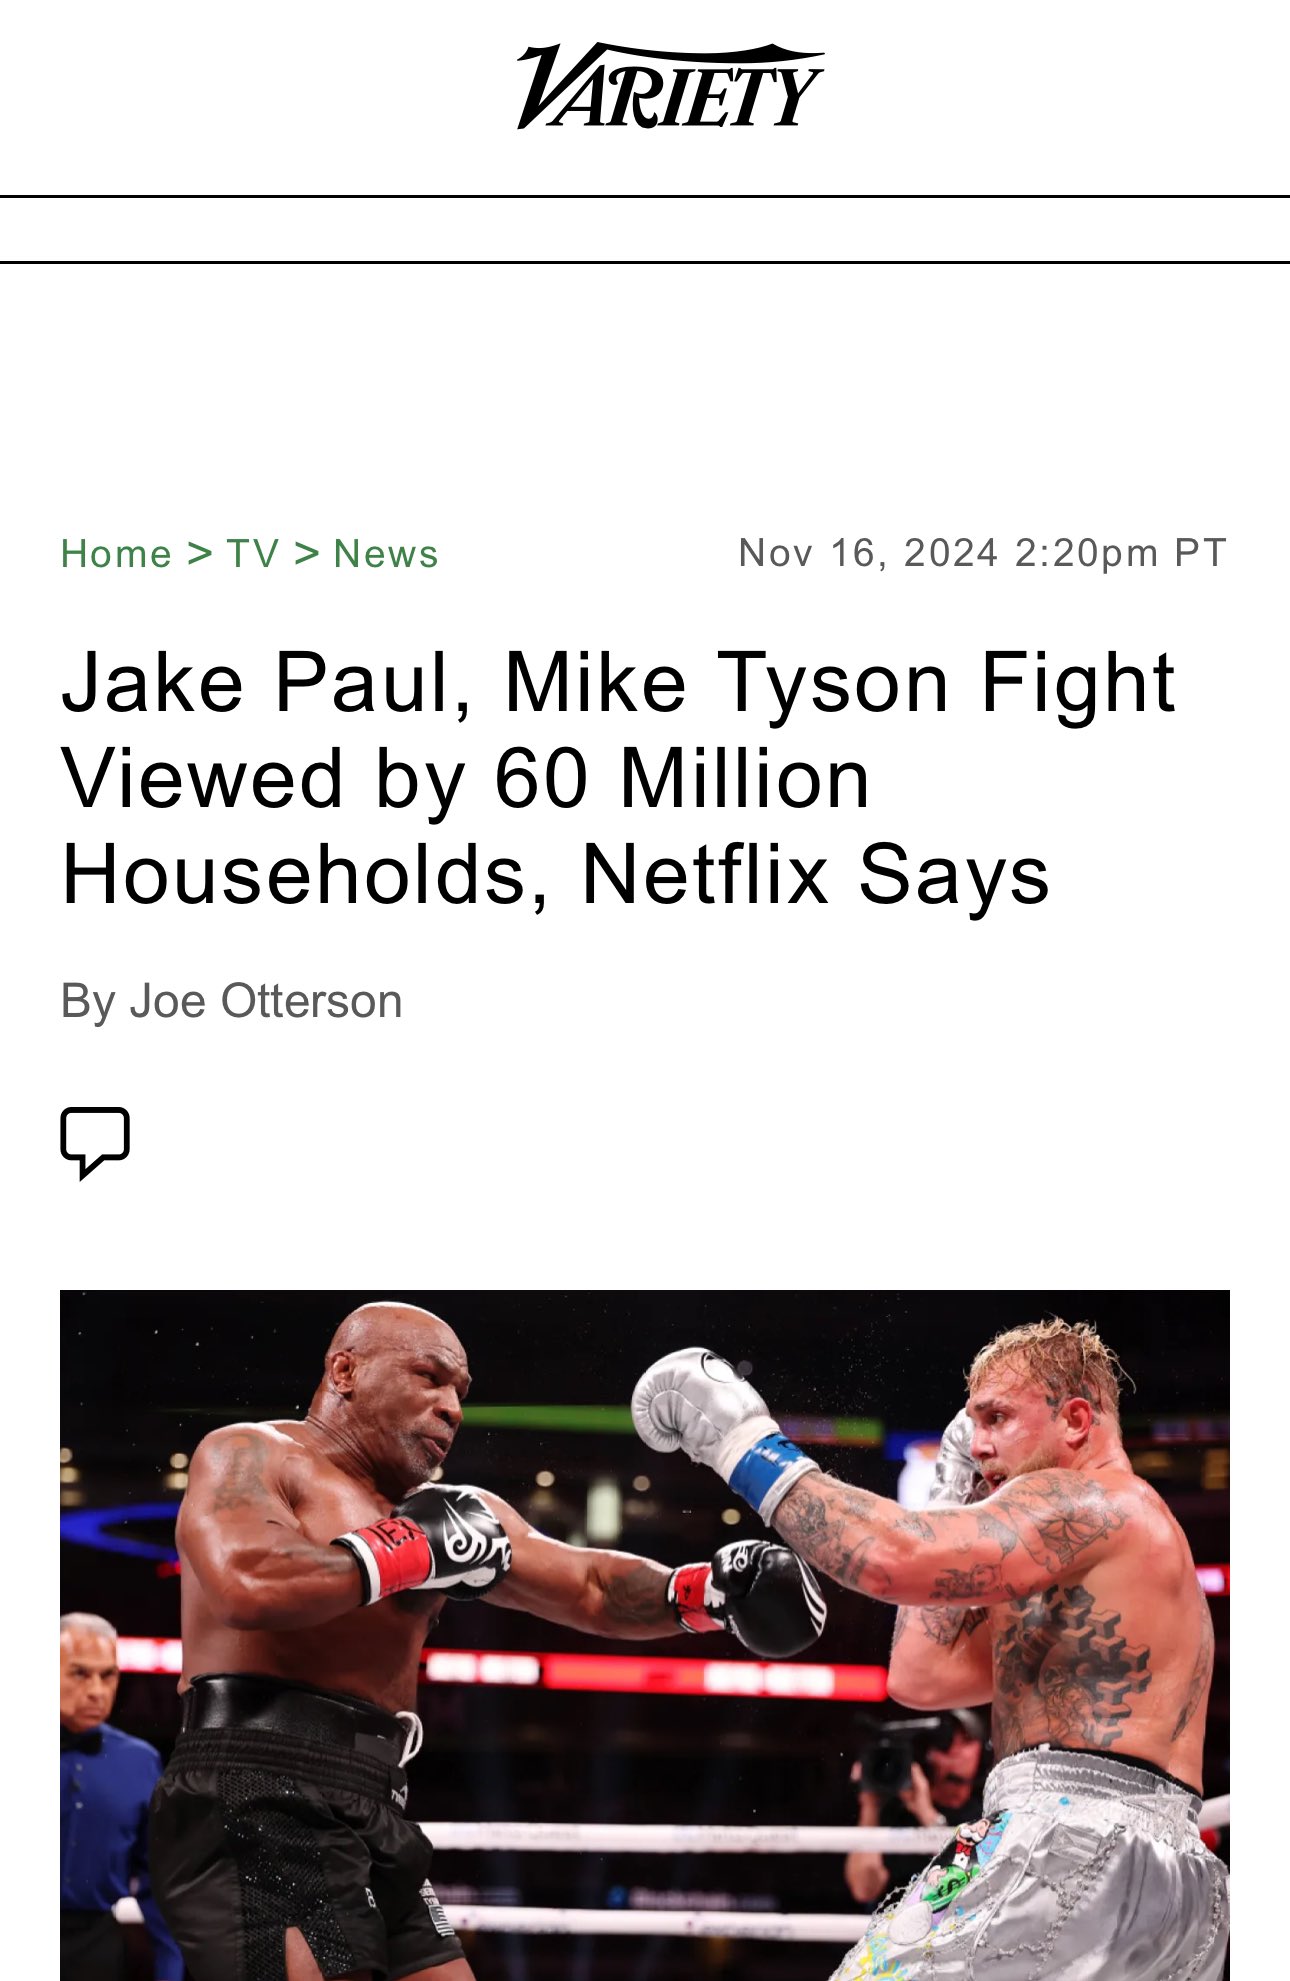
Platform Achieves 65 Million Peak Concurrent Viewers
By
–
They did share some numbers yesterday — 65M peak concurrent viewers
-
Cloning and Running AI Spaces Locally or on ZeroGPU
By
–
Not sure if I follow, you can just clone the space and run locally right? Alternatively you can run it on ZeroGPU
-
Mixture of Transformers: Sparse Multimodal Architecture for Efficiency
By
–
9). Mixture of Transformers – introduce Mixture-of-Transformers (MoT), a new sparse multi-modal transformer architecture that matches the performance of traditional models while using only about half the computational resources for text and image processing.
-
Precision-Aware Scaling Laws for Large Language Models
By
–
2). Scaling Laws for Precision – introduces "precision-aware" scaling laws that predict how model performance is affected by both training and inference precision in LLMs.
-
Diversity of AI Hardware Accelerators and Software Stacks
By
–
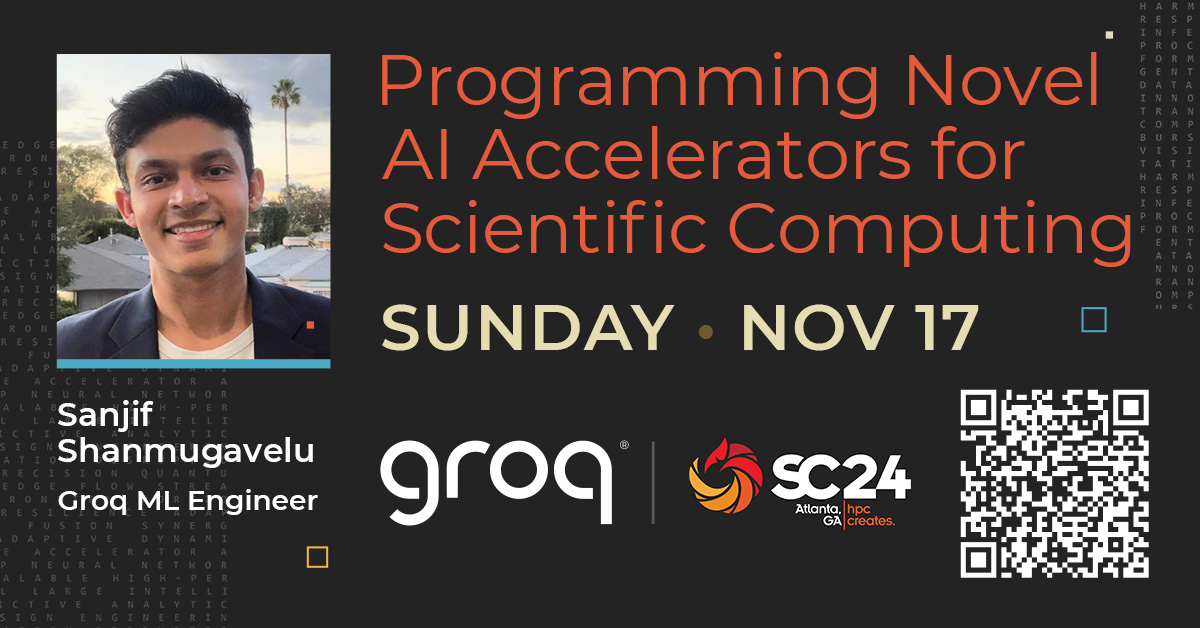
There is a wide diversity of specialized HW accelerators and SW stacks designed and built to run AI applications efficiently, so it is challenging to understand their differences, capabilities, programming approaches, and how they perform, particularly for scientific
-

MATLAB EXPO 2024 Highlights: Innovation and Success Stories
By
–
A big thank you to everyone who participated in MATLAB EXPO 2024! From inspiring talks to success stories, your presence made it unforgettable. Catch up on the highlights https://
spr.ly/6017sVSMx #MATLABEXPO