8 GB of video RAM for LLM, then 2 GB for ASR, and 2 GB for the game. Total requirement is 12 GB. I know it's quite high but we need to start somewhere.
COMPUTING
-
Running AI NPCs Locally: Feasibility and Implementation
By
–
Yes, you can run local LLMs. But can you run AI NPCs locally?
-

Comprehensive llama.cpp Guide: Building and Performance Benchmarking
By
–
Cool guide to llama.cpp from building to perf benchmarking llama.cpp's documentation is notoriously difficult to work with. There's some more advanced stuff I didn't know about, it's great stuff from @steel_ph0enix https://
steelph0enix.github.io/posts/llama-cp
p-guide/
… -
AI People Local LLM Update Eliminates Cloud Dependency
By
–
Next week, we’re releasing a major update for AI People: Local LLM. Our AI NPCs will be able to run entirely on your PC, eliminating the need for cloud-based LLMs. To my knowledge, this makes us the first game in the history of the universe to achieve this!
-
India launches Airawat AI supercomputer for advanced computing
By
–
For more information, tap here: https://
airawat.cdac.in @GoI_MeitY @abhish18 @_DigitalIndia #PowerofAirawat #AISupercomputing #IndiaAI #DigitalIndia #FutureOfAI #AIForGood #InnovationImpact #IndiaTechPride #gpu #supercomputing -
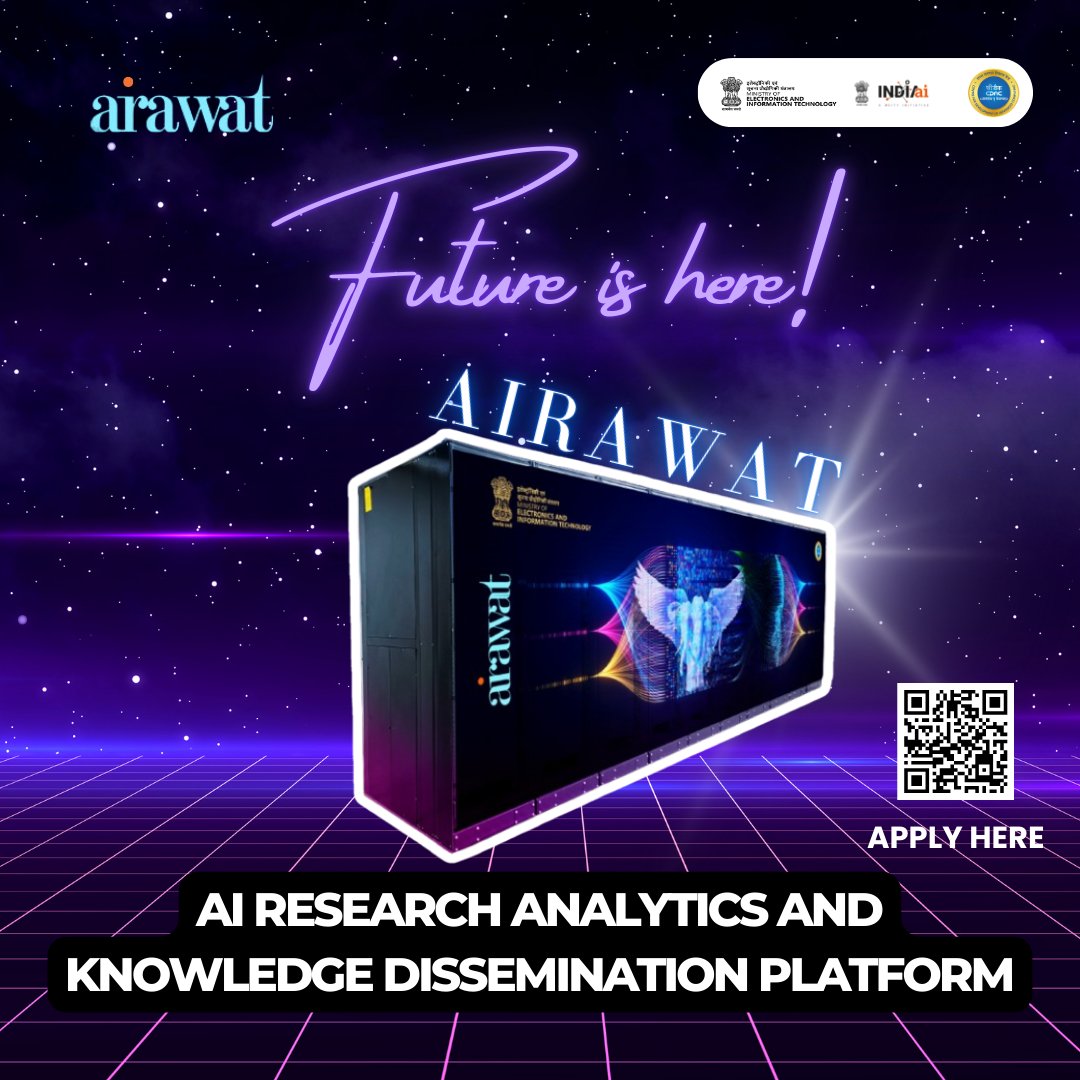
India Launches AIRAWAT: AI and Supercomputing Initiative
By
–
The future is here, and it’s powered by AIRAWAT! Join us in celebrating India’s leap into AI and supercomputing. The journey has just begun! For more information, tap here: https://
airawat.cdac.in -
Top 10 Tech Trends Reshaping Enterprise Business
By
–
Top 10 Tech Trends Reshaping the Enterprise: AI & ML – Smarter decisions, automation
Generative AI – Instant content, enhanced service
5G – Faster, smarter connectivity
Quantum Computing – Solving the unsolvable
IoT – Data-driven insights, efficiency
AR/VR – Immersive business -
GPU Resource Allocation: Balancing Optimization with Debugging Flexibility
By
–
A fully optimized system might wind up with persistent kernels running continuously on all GPUs, but I want the ability to debug a single process using all GPUs, as well as launch parallel experiments directly from one host without needing a cluster layer.
-
Grace GPU cluster kernel launch and multi-GPU operation capabilities
By
–
Can you comment on my original question — can a process on one grace CPU launch kernels and operate on all 72 GPUs, or do you need to treat it as 18 separate hosts that just happen to have great NCCL connectivity?
-
X Feed Quality Improves: Space, ML, Chips, and EV Updates
By
–
Lately, my feed on X has been a bliss. From ISRO's latest rocket and space station updates to ML papers and cutting edge chip prod startups to new EVs and much more… It was a disaster just few weeks ago. What happened suddenly?