Just trying out how it goes. will go with gpus in next model training
COMPUTING
-
GPU-less Model Training Progress and Performance Challenges
By
–
One of my latest model training is in progress without gpu it is time-consuming and slowish. #MachineLearning #LLMs
-
Engineering Innovation Podcast: Greentown Labs Sustainable Tech Breakthroughs
By
–
Explore the intersection of engineering and innovation in our limited-series podcast! In episode one, hear how Greentown Labs’ startups use MATLAB and Simulink to build breakthrough sustainable technologies. Listen here: https://
spr.ly/6012tLW02 -
Mobile Subscribers Growth: From NTT 1980 to 5G 2025
By
–
Rise of #Mobile Subscribers 3K → 1980 NTT 340K → 1985 Vodafone 11M → 1990 AMPS goes 90M → 1995 GSM SMS 738M → 2000 3G boosts 2.2B → 2005 Razr V3 5.3B → 2010 Smartphones
7.4B → 2015 4G ignites 8.3B → 2020 Covid Zoom 9.5B → 2025 5G enables -
2D Convolution Stride Optimization for Compute Efficiency
By
–
This analysis suggests that a 2D convolution filter of stride=2 would be the most compute-efficient for this particular workload… Also, ideally batch up all the grey data and do the calculation all at once.
-
Moore’s Law: Computing Cost Plummets 1M to Near Zero
By
–
Cost of 1 #MIPS (Million Instructions Per Second) 1975: ~$1M 1980: ~$180K 1985: ~$2.5K 1990: ~$100 1995: ~$1 2000: ~$0.10 2005: ~$0.02 2010: ~$0.04 2015: ~$0.005 2020: ~$0.002 2025: ~$0.0015 $1M to ~Zero in 45 years #AI #MooresLaw #Computing
-
GitHub Code Vault Setup for Long-term Code Preservation
By
–
I wonder if a GitHub Code Vault like setup would work, ofc wouldn’t require a lot of back and forth: https://
archiveprogram.github.com/arctic-vault/ -
SambaNova Cloud Delivers Fastest AI Inference for Llama Models
By
–
Being fast wasn't enough. We wanted to be the fastest 🚀
— SambaNova (@SambaNovaAI) 2 décembre 2024
Experience the world's fastest #AI inference with SambaNova Cloud!
Supercharge your AI-powered applications across Llama 3.1 8B, 70B, & 405B models – for free.
✅ 70B at 461 tokens/s
✅ 405B at 200 tokens/s #DevsBeing fast wasn't enough. We wanted to be the fastest Experience the world's fastest #AI inference with SambaNova Cloud! Supercharge your AI-powered applications across Llama 3.1 8B, 70B, & 405B models – for free. 70B at 461 tokens/s 405B at 200 tokens/s #Devs
-
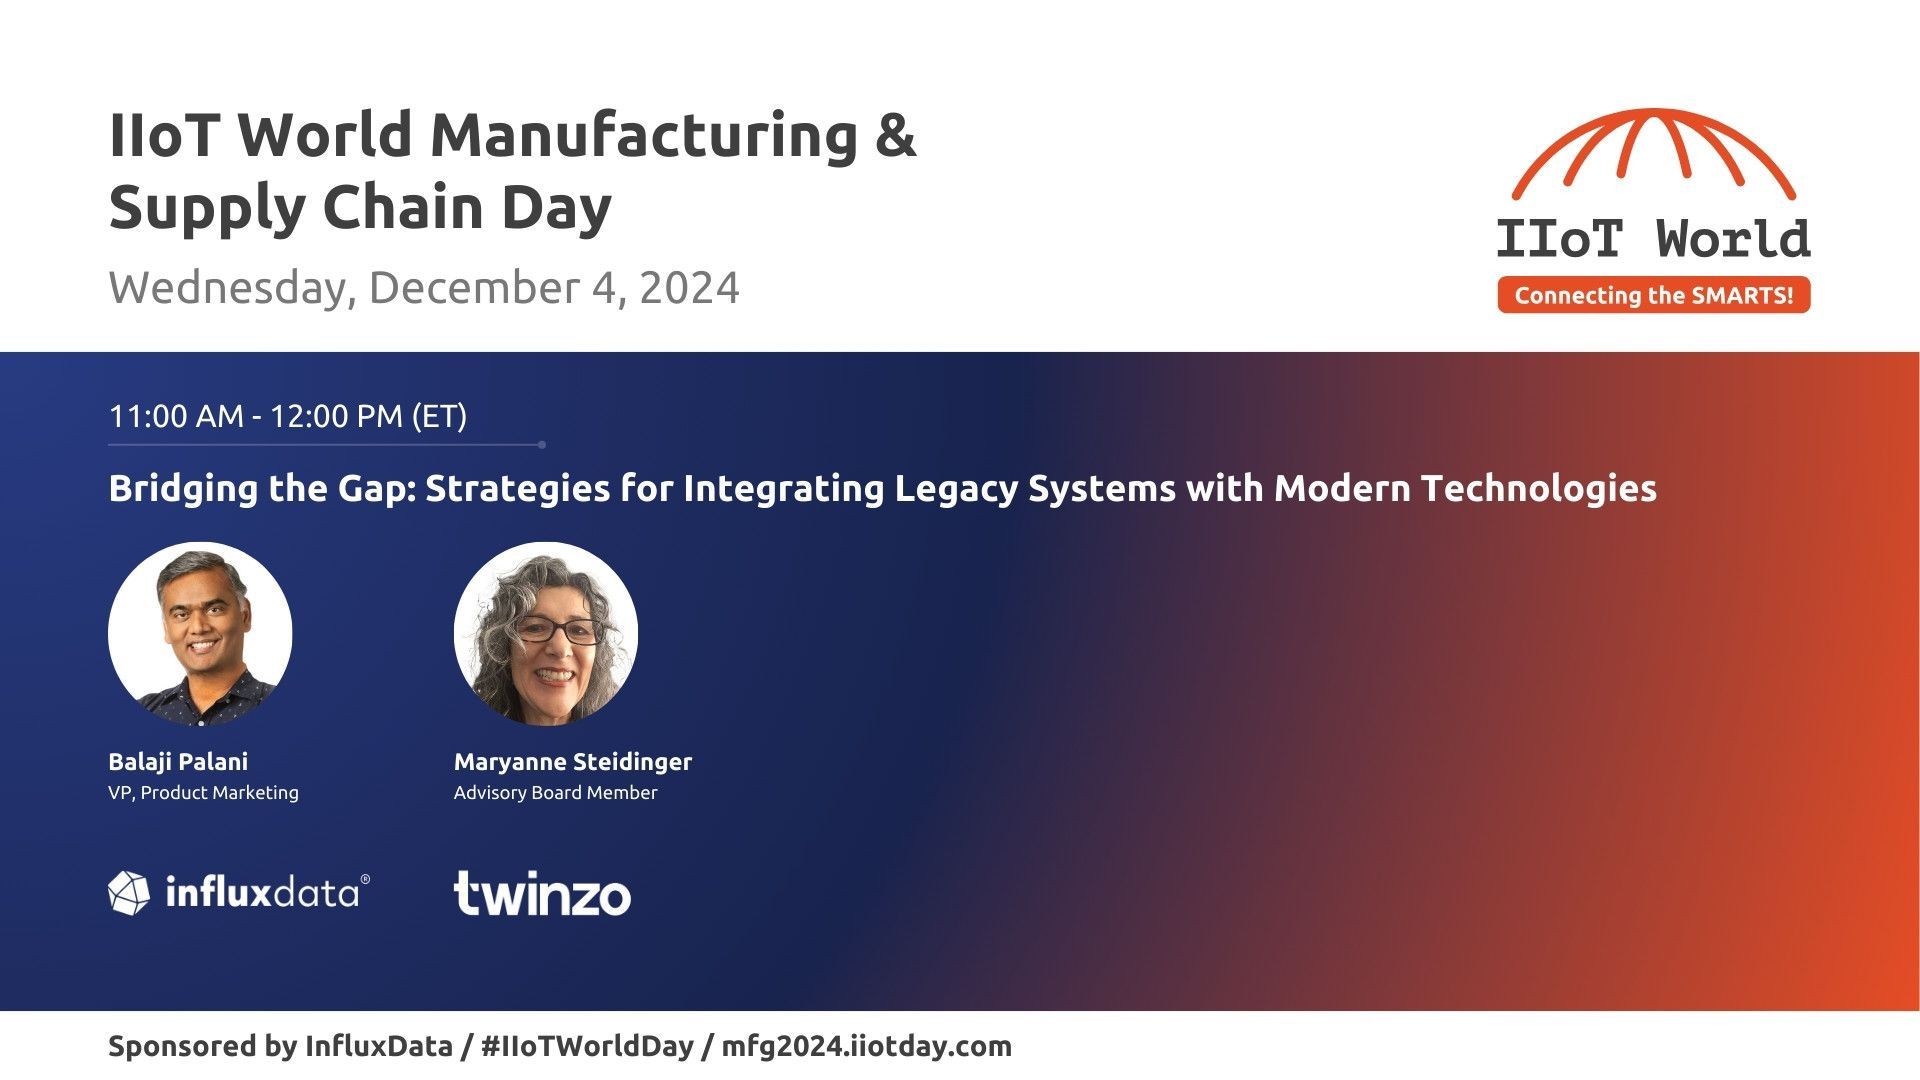
InfluxDB TSDB Solutions Transform Industrial Data Scaling
By
–
Don’t miss the session on transforming industrial data with modern TSDB solutions! Dec 4 at 11:00 am EST. Discover strategies for scaling data with #InfluxDB! https://
buff.ly/4hri8P4 #sponsored #influxdata_iiot #Innovation #DataTransformation #SmartManufacturing @YvesMulkers -
Cerebras Wafer-Scale Engine Powers Neocortex AI Supercomputer
By
–
How does the Cerebras Wafer-Scale Engine power the Neocortex AI supercomputer? Find out on December 6th. Register below!