1000s of toks/sec across a dozen parallel requests if not more
COMPUTING
-

Neer Jain on Model Ensembling for Improved Prediction Performance
By
–


Neer Jain Explains Model Ensembling Strategies Used to Improve Prediction Performance in The Competition! #BigData #Analytics #AI #MachineLearning #DataScience #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux
-

AI Enters the Kill Chain: Unity in Principle, Variation in Practice
By
–
Unity In Principle, Variation In Practice: When AI Enters the Kill Chain! #BigData #Analytics #AI #MachineLearning #DataScience #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode
-

Matrix Factorization Explained for Recommendation Systems
By
–


What's Matrix Factorization! #RecSy #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #ReactJS #CloudComputing #Serverless #Linux #Mathematics #Programming #Coding #100DaysofCode https://
geni.us/Matrix-RecSys -
NVIDIA Research Introduces LongLive-2.0 for Long Video Generation
By
–
Long video generation is a systems problem.
— NVIDIA AI (@NVIDIAAI) 22 mai 2026
Introducing LongLive-2.0 from NVIDIA Research: an end-to-end NVFP4 training and inference system for long video generation.
Low-precision deployment often relies on post-training quantization, creating a gap between how models are… pic.twitter.com/rRg35QNOVGLong video generation is a systems problem. Introducing LongLive-2.0 from NVIDIA Research: an end-to-end NVFP4 training and inference system for long video generation. Low-precision deployment often relies on post-training quantization, creating a gap between how models are
-
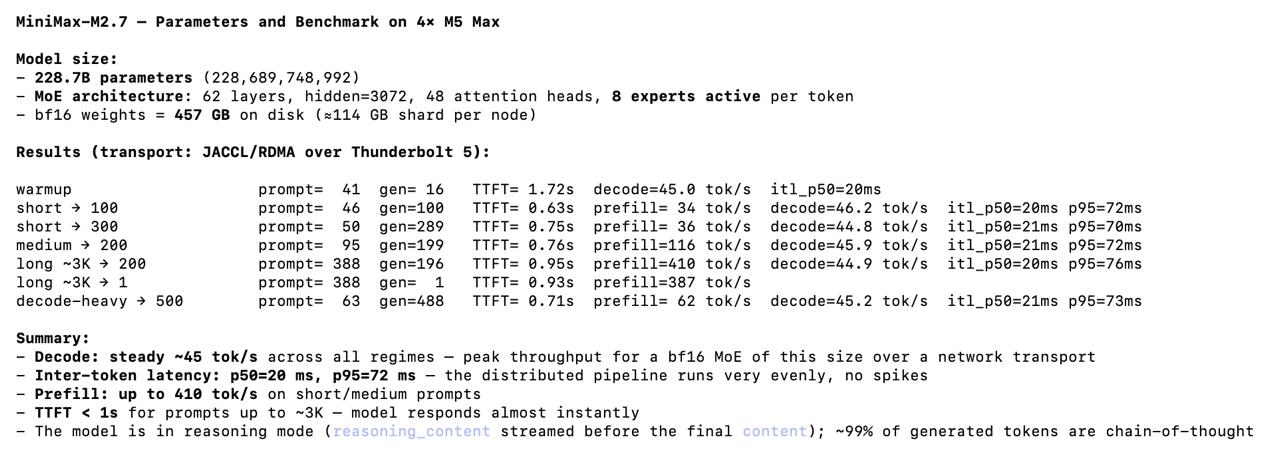
Expensive MacBooks run MiniMax with low performance and limited context
By
–
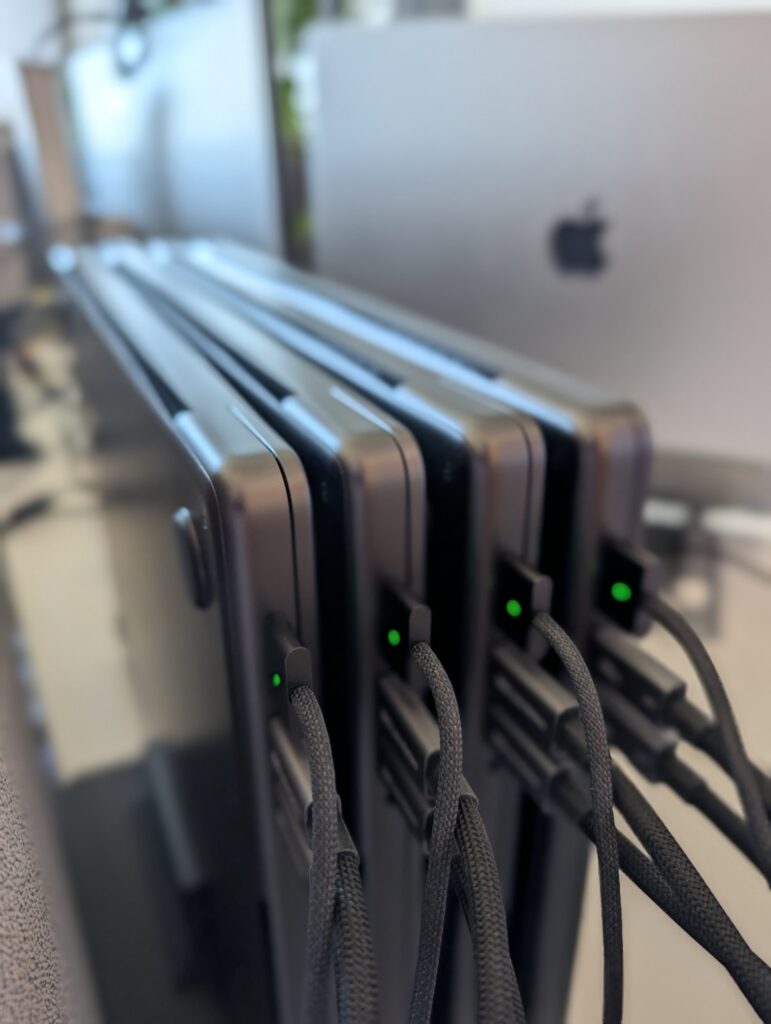
Good example of Performative Inference / Local AI grifting MiniMax-M2.7 on 4x M5 Max MacBooks (~$22,000 USD) – Longest prompt: 338 (???) – Max context: ~3k (???) – 45 tok/s (lol) – Single prompt, no parallel requests Some of the funniest & stupidest shit I've ever seen
-
Anthropic AI’s Project Glasswing finds thousands of critical software vulnerabilities
By
–
Last month we launched Project Glasswing, our collaborative AI cybersecurity initiative. Since then, we and our partners have found more than ten thousand high- or critical-severity vulnerabilities in essential software.
-

Gemini 3.5 Flash Outperforms 3.1 Pro in Vision Use Cases
By
–
Gemini 3.5 Flash outperforms 3.1 Pro on many vision use cases (like the below Roboflow eval) while being ~6x faster on average Gemini multimodal understanding for the win.
-
Qwen 3.5 27B: Buy RTX 3090s or Stay Underclass
By
–
If you saw Qwen 3.5 27B and didn’t see that as a chance to ensure the permanent underclass semi-joke never happens to you (by simply purchasing a couple of RTX 3090s) I am sorry to say but you ngmi
-
DeepSeek v4 Pro 75% Discount, Only 27% Compute and 10% Cache
By
–
Let that sink in for a moment. DeepSeek v4 pro 75% discount. Permanent! In: $0.43
Out: $0.87 If you read the DeepSeek v4 tech paper you know that this model is insanely good when it comes to efficiency. Only 27% compute and only 10% cache compares to v3.2. SemiAnalysis wrote